StreamSpeech
StreamSpeech is an “All in One” seamless model for offline and simultaneous speech recognition, speech translation and speech synthesis.
- 1.3k
- Python
- MIT
- 17 mo ago
StreamSpeech is an “All in One” seamless model for offline and simultaneous speech recognition, speech translation and speech synthesis.
A fast speech-to-speech & speech-to-text translation model that supports simultaneous decoding and offers 28× speedup.
Free, private, real-time translation for any audio on your Mac. Runs on-device with TranslateGemma and reads translations aloud. No account, no API key.
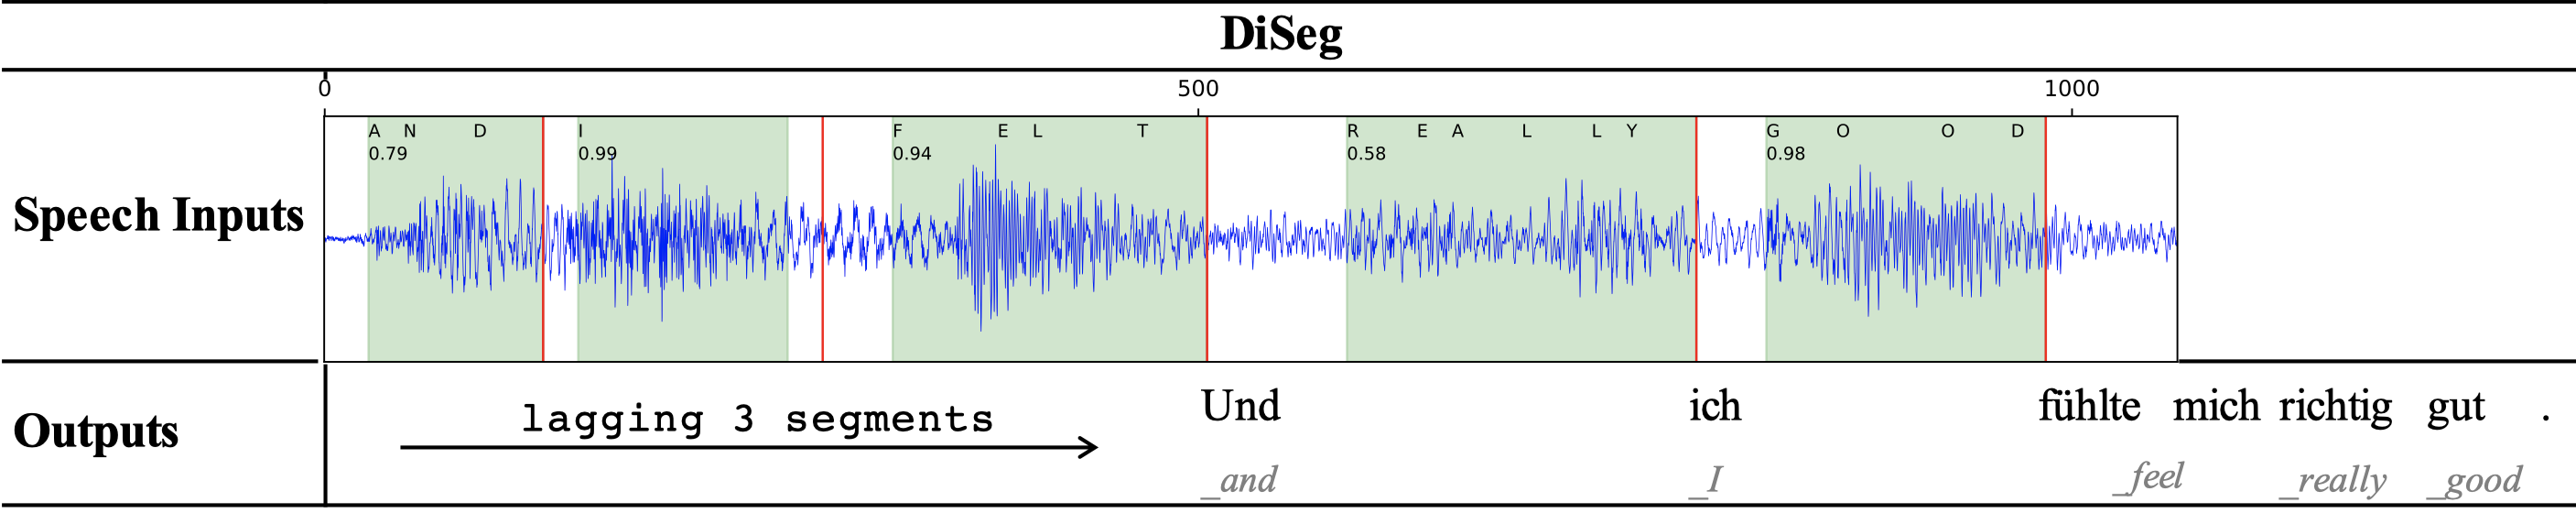
Source code for ACL 2023 paper "End-to-End Simultaneous Speech Translation with Differentiable Segmentation"
StreamUni is a framework that efficiently enables unified Large Speech-Language Models to accomplish streaming speech translation in a cohesive manner.
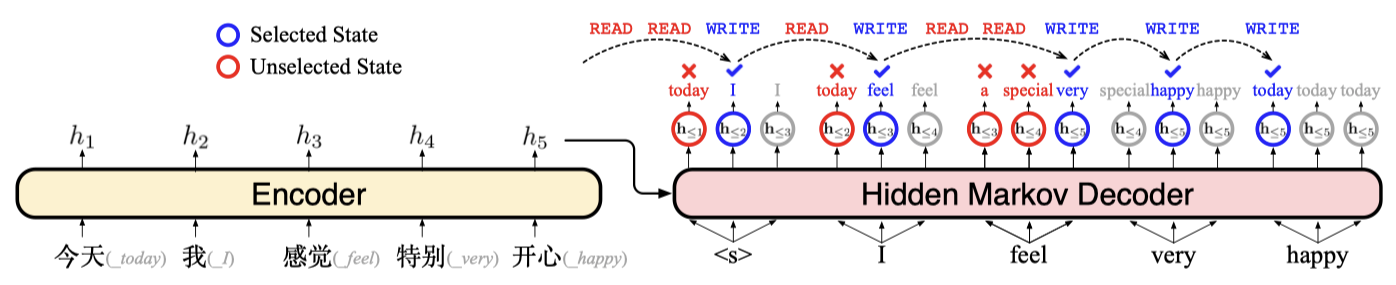
Source code for ICLR 2023 spotlight paper "Hidden Markov Transformer for Simultaneous Machine Translation"
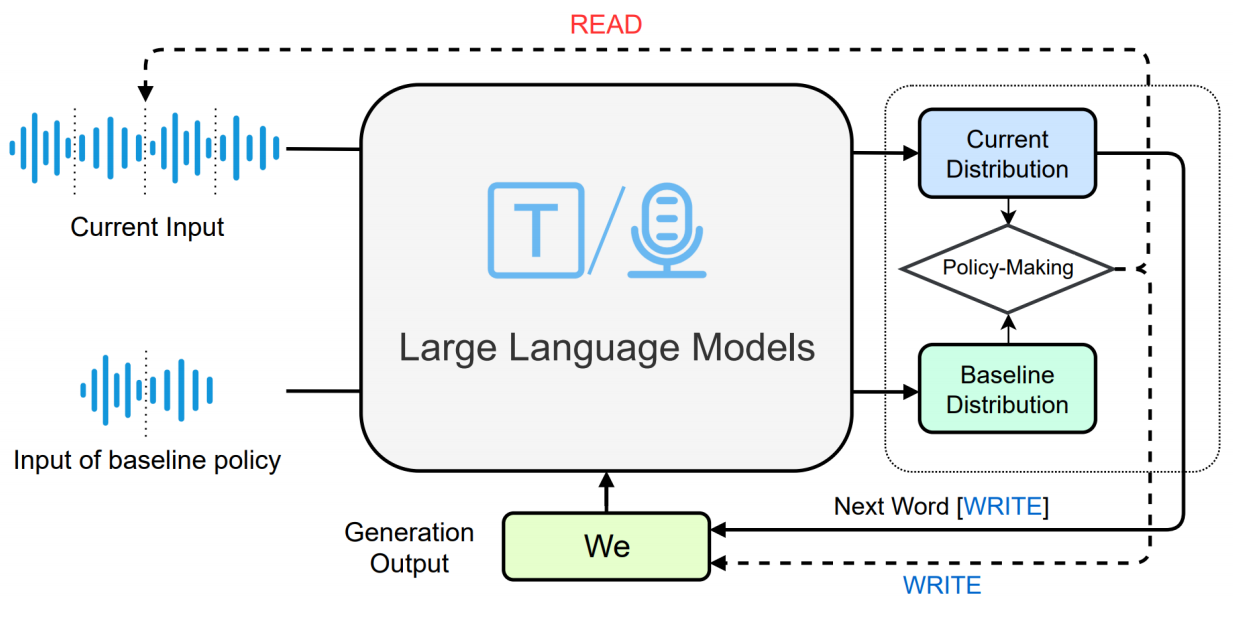
The code for AAAI 2025 “Large Language Models Are Read/Write Policy-Makers for Simultaneous Generation”
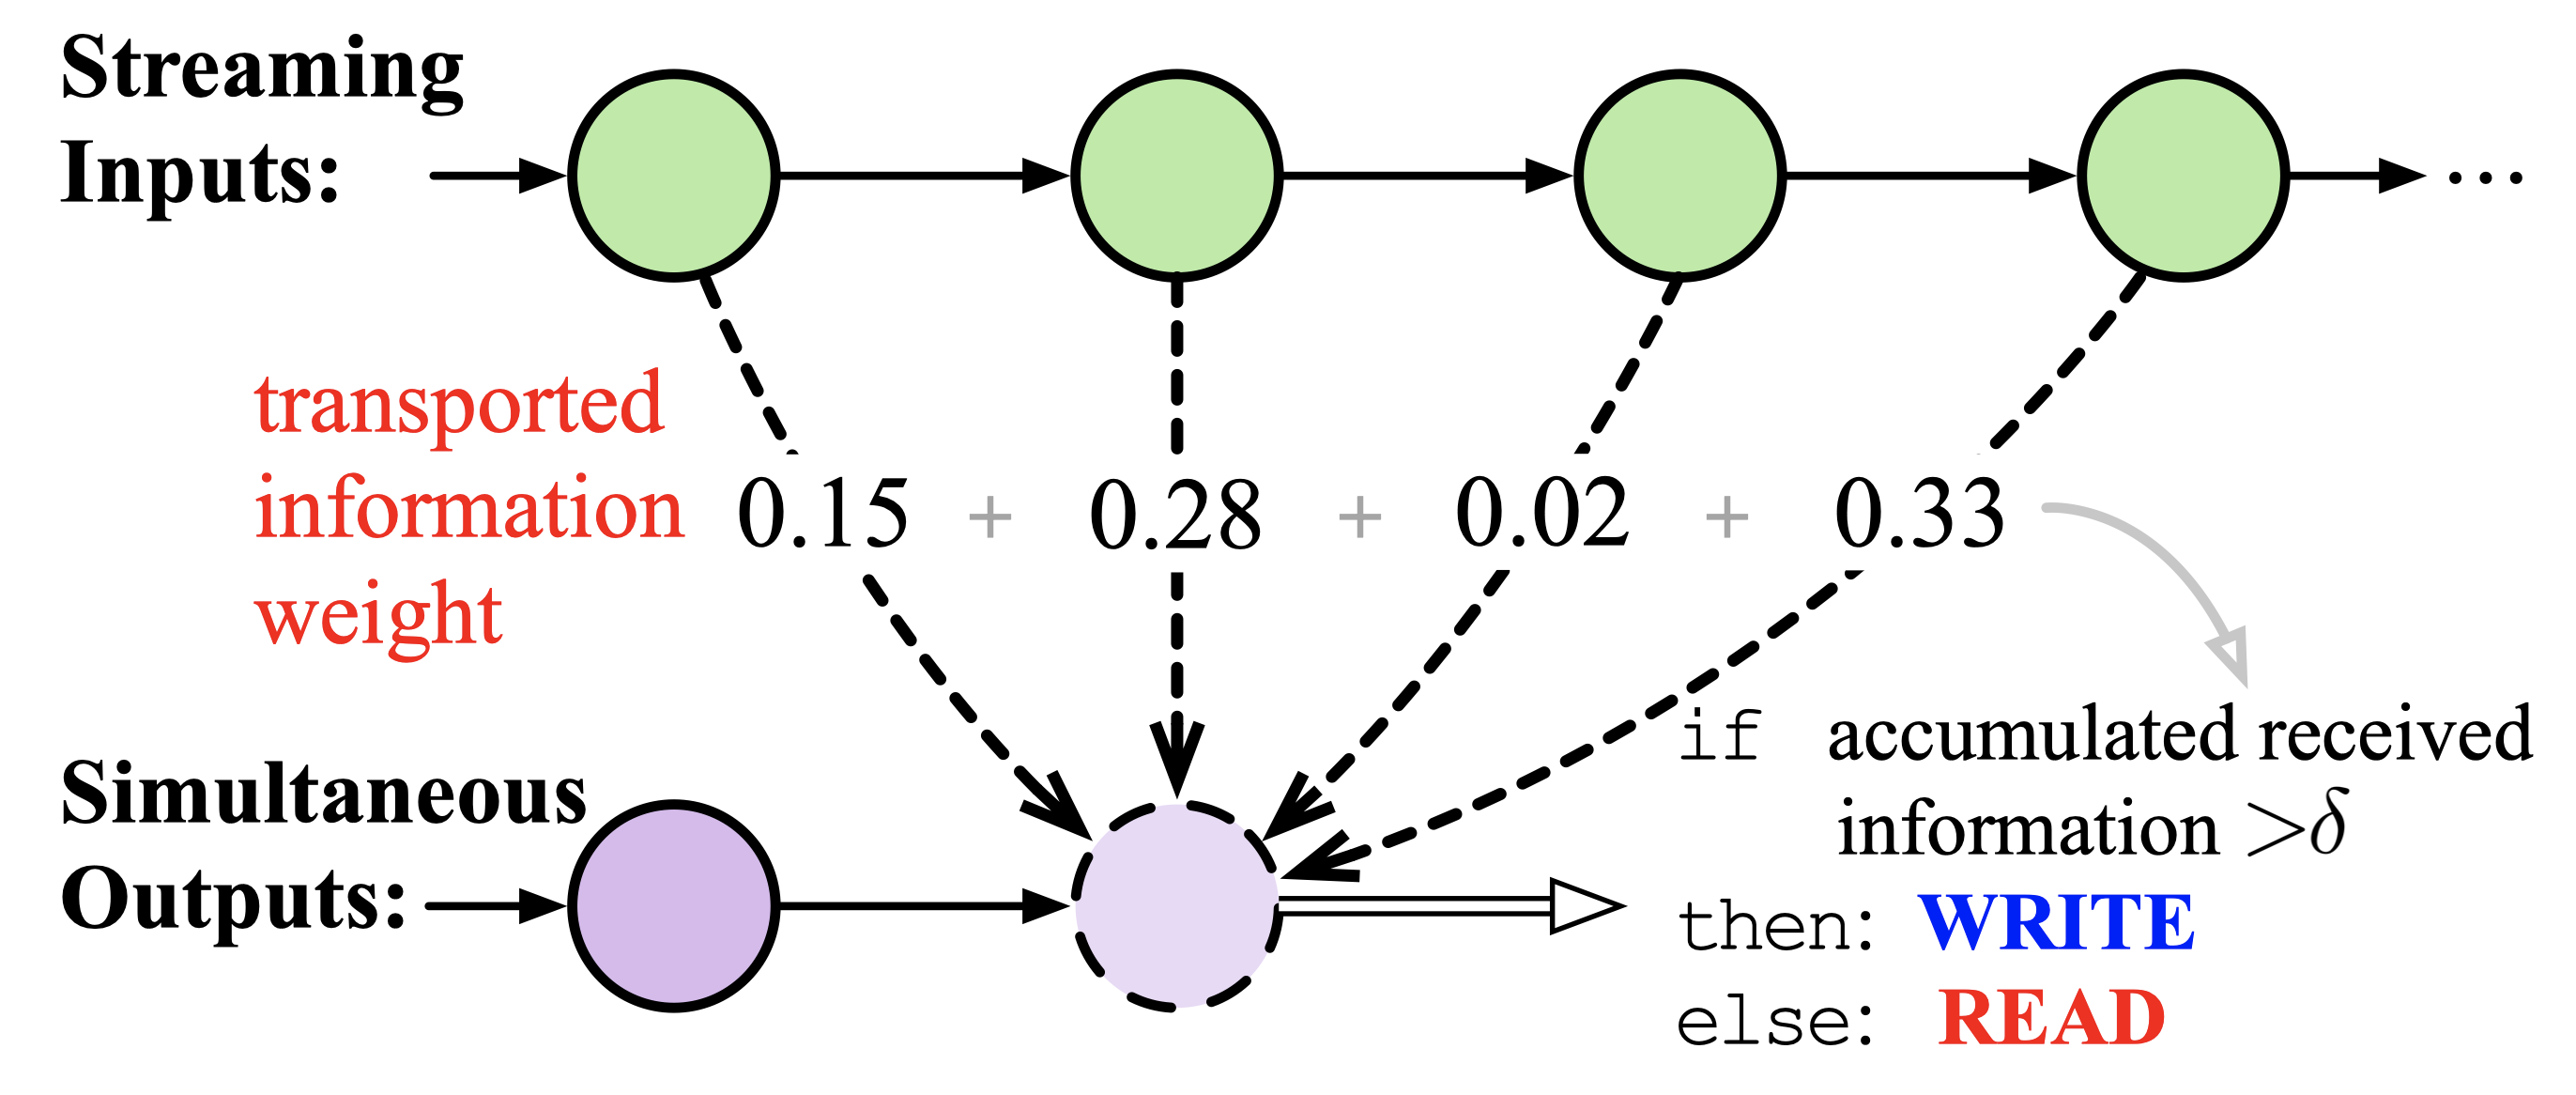
Code for EMNLP 2022 main conference paper "Information-Transport-based Policy for Simultaneous Translation"
Official implementation for EMNLP 2023 paper "Non-autoregressive Streaming Transformer for Simultaneous Translation"
Code for ACL 2022 main conference paper "Modeling Dual Read/Write Paths for Simultaneous Machine Translation"
Code for ICML25 Paper "Overcoming Non-monotonicity in Transducer-based Streaming Generation"
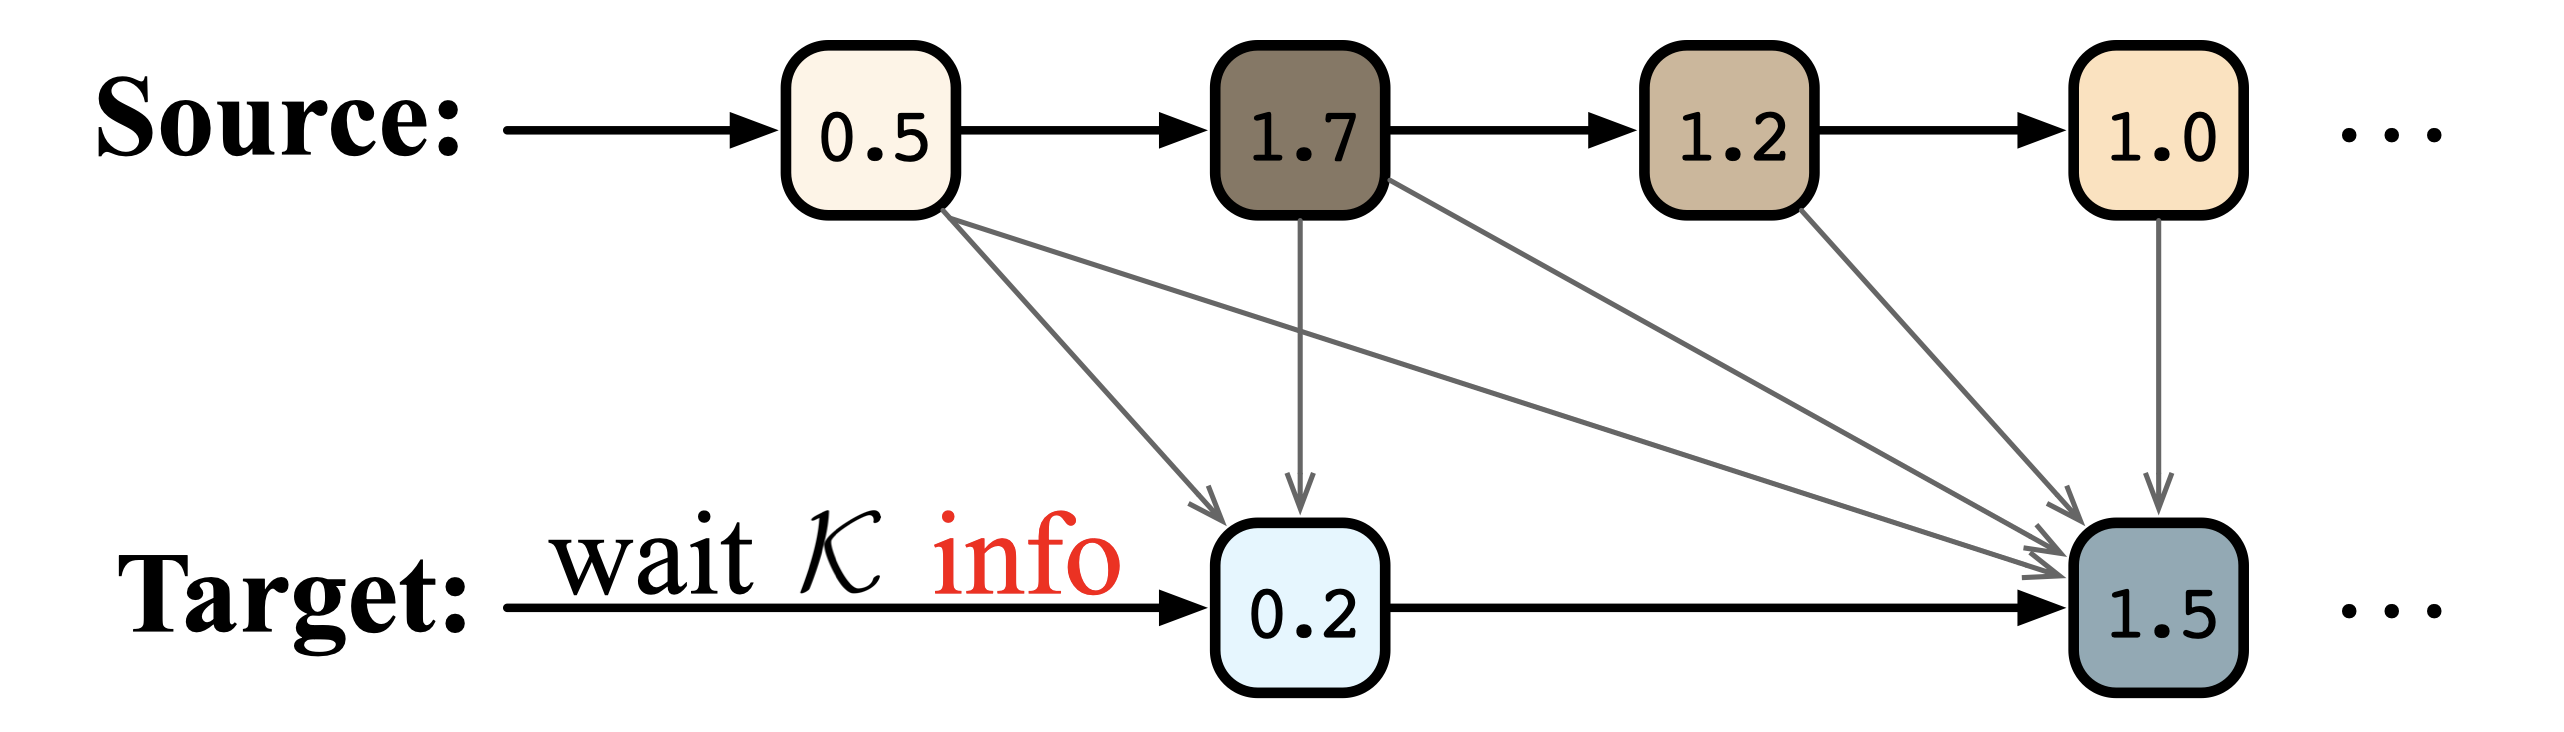
Source code for our EMNLP 2022 paper "Wait-info Policy: Balancing Source and Target at Information Level for Simultaneous Machine Translation"
Code for ACL 2022 findings paper "Gaussian Multi-head Attention for Simultaneous Machine Translation"
Code for EMNLP 2021 oral paper "Universal Simultaneous Machine Translation with Mixture-of-Experts Wait-k Policy"