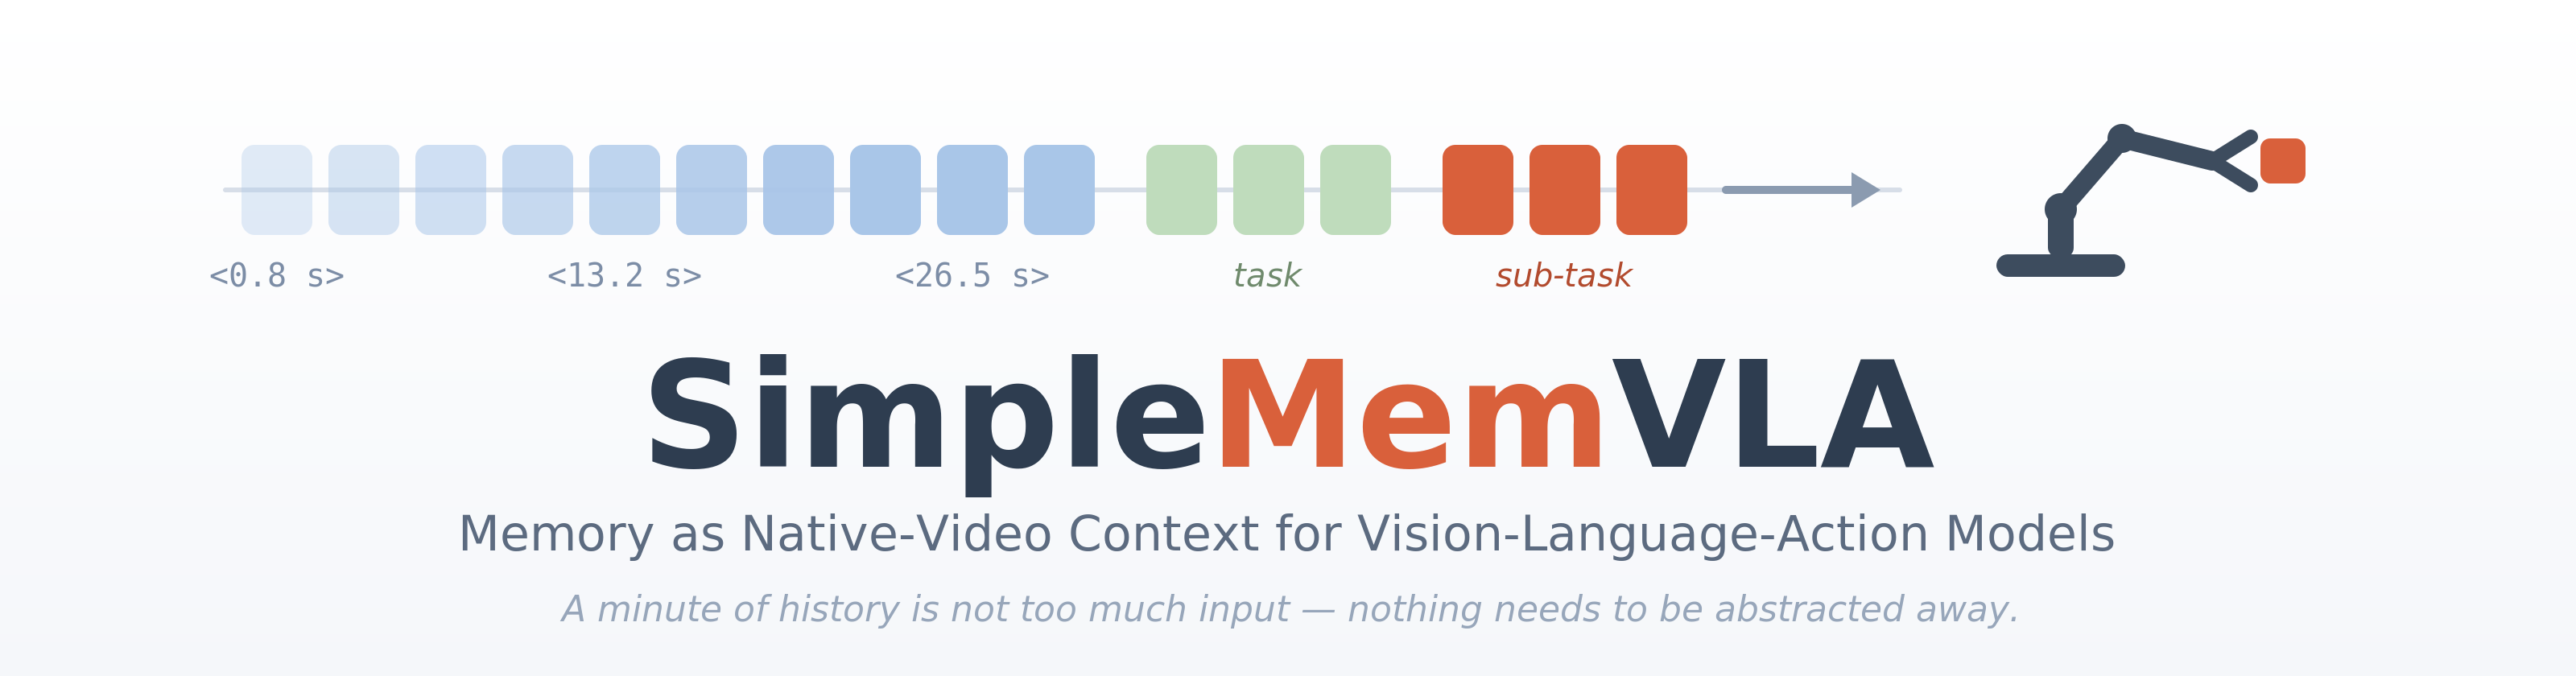
SimpleMemVLA
Native-video memory for vision-language-action models, using timestamped visual history and exact streaming inference for long-horizon robot manipulation.
- 115
- Python
- MIT
- 3 wk ago
Native-video memory for vision-language-action models, using timestamped visual history and exact streaming inference for long-horizon robot manipulation.
Streamable Text-to-Speech model using a language modeling approach, without vector quantization
Pure PyTorch + 🤗 Transformers reimplementation of Megalodon (CEMA + chunked attention) - readable, hackable, no CUDA kernels required


