tensorrt-llm

Awesome-LLM-Inference
📚A curated list of Awesome LLM/VLM Inference Papers with Codes: Flash-Attention, Paged-Attention, WINT8/4, Parallelism, etc.🎉
- 5.6k
- Python
- GPL-3.0
- 4 wk ago


InferenceX
Open Source AI Accelerator Research Platform Standard / 开源推理研究平台
- 2.1k
- Python
- Apache-2.0
- 4 h ago

WhisperS2T
An Optimized Speech-to-Text Pipeline for the Whisper Model Supporting Multiple Inference Engine
- 582
- Jupyter Notebook
- MIT
- 2 y ago

awesome-cuda-and-hpc
🚀🚀🚀 This repository lists some awesome public CUDA, cuda-python, cuBLAS, cuDNN, CUTLASS, TensorRT, TensorRT-LLM, Triton, TVM, MLIR, PTX and High Performance Computing (HPC) projects.
- 525
- 16 mo ago

optimum-benchmark
🏋️ A unified multi-backend utility for benchmarking Transformers, Timm, PEFT, Diffusers and Sentence-Transformers with full support of Optimum's hardware optimizations & quantization schemes.
- 342
- Python
- Apache-2.0
- 10 d ago



grps
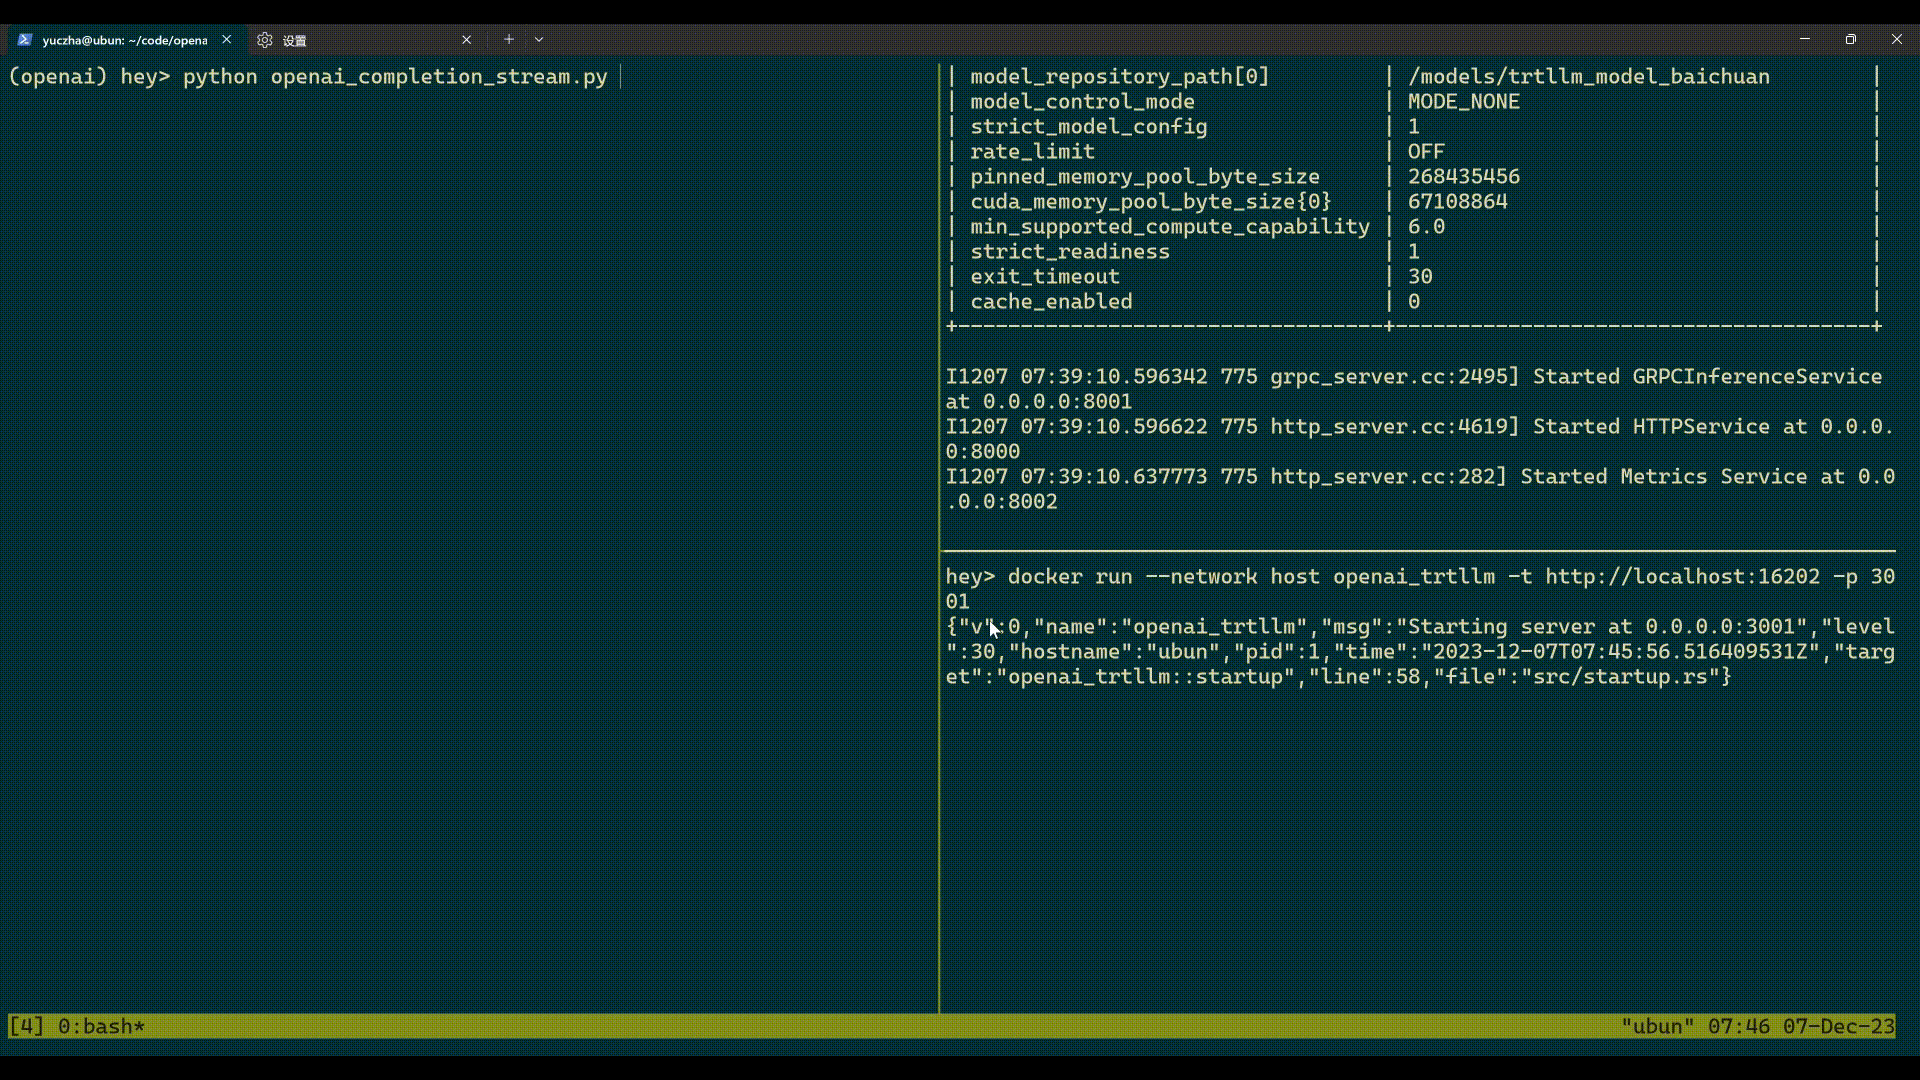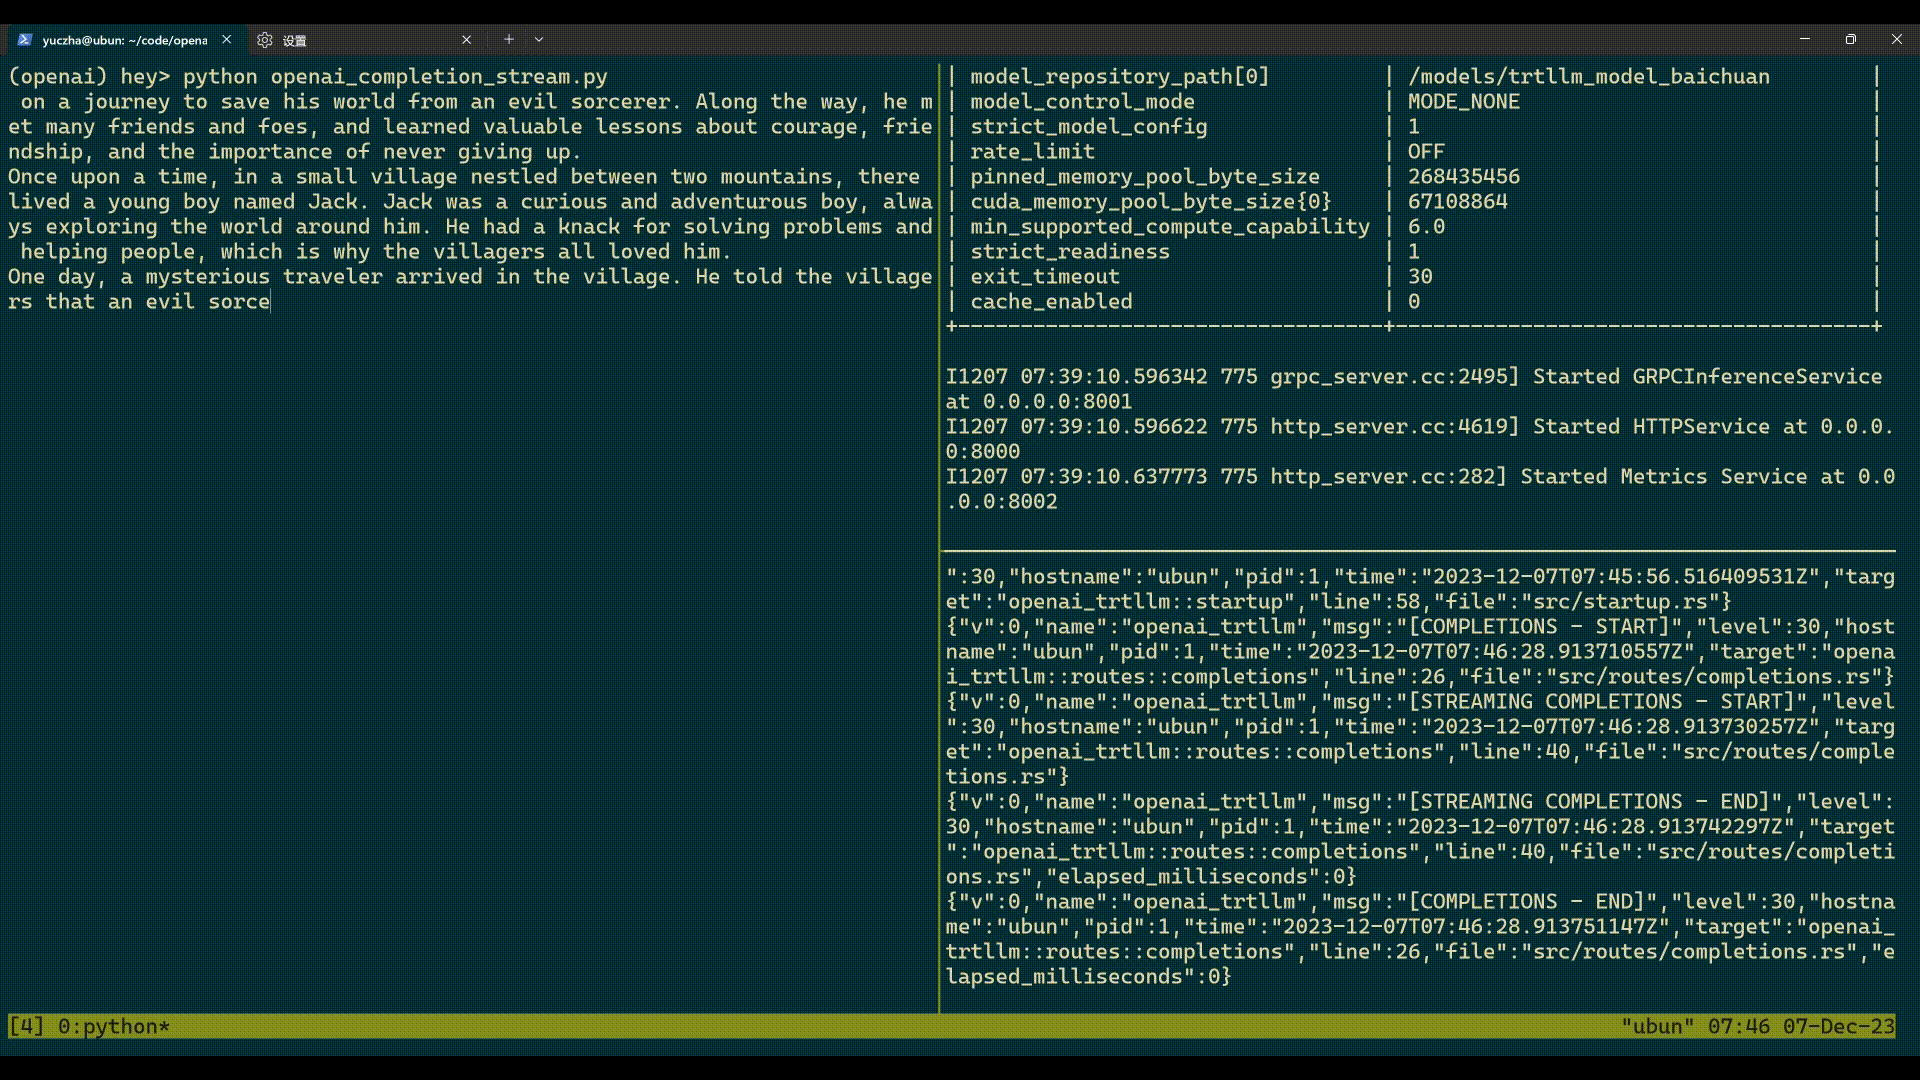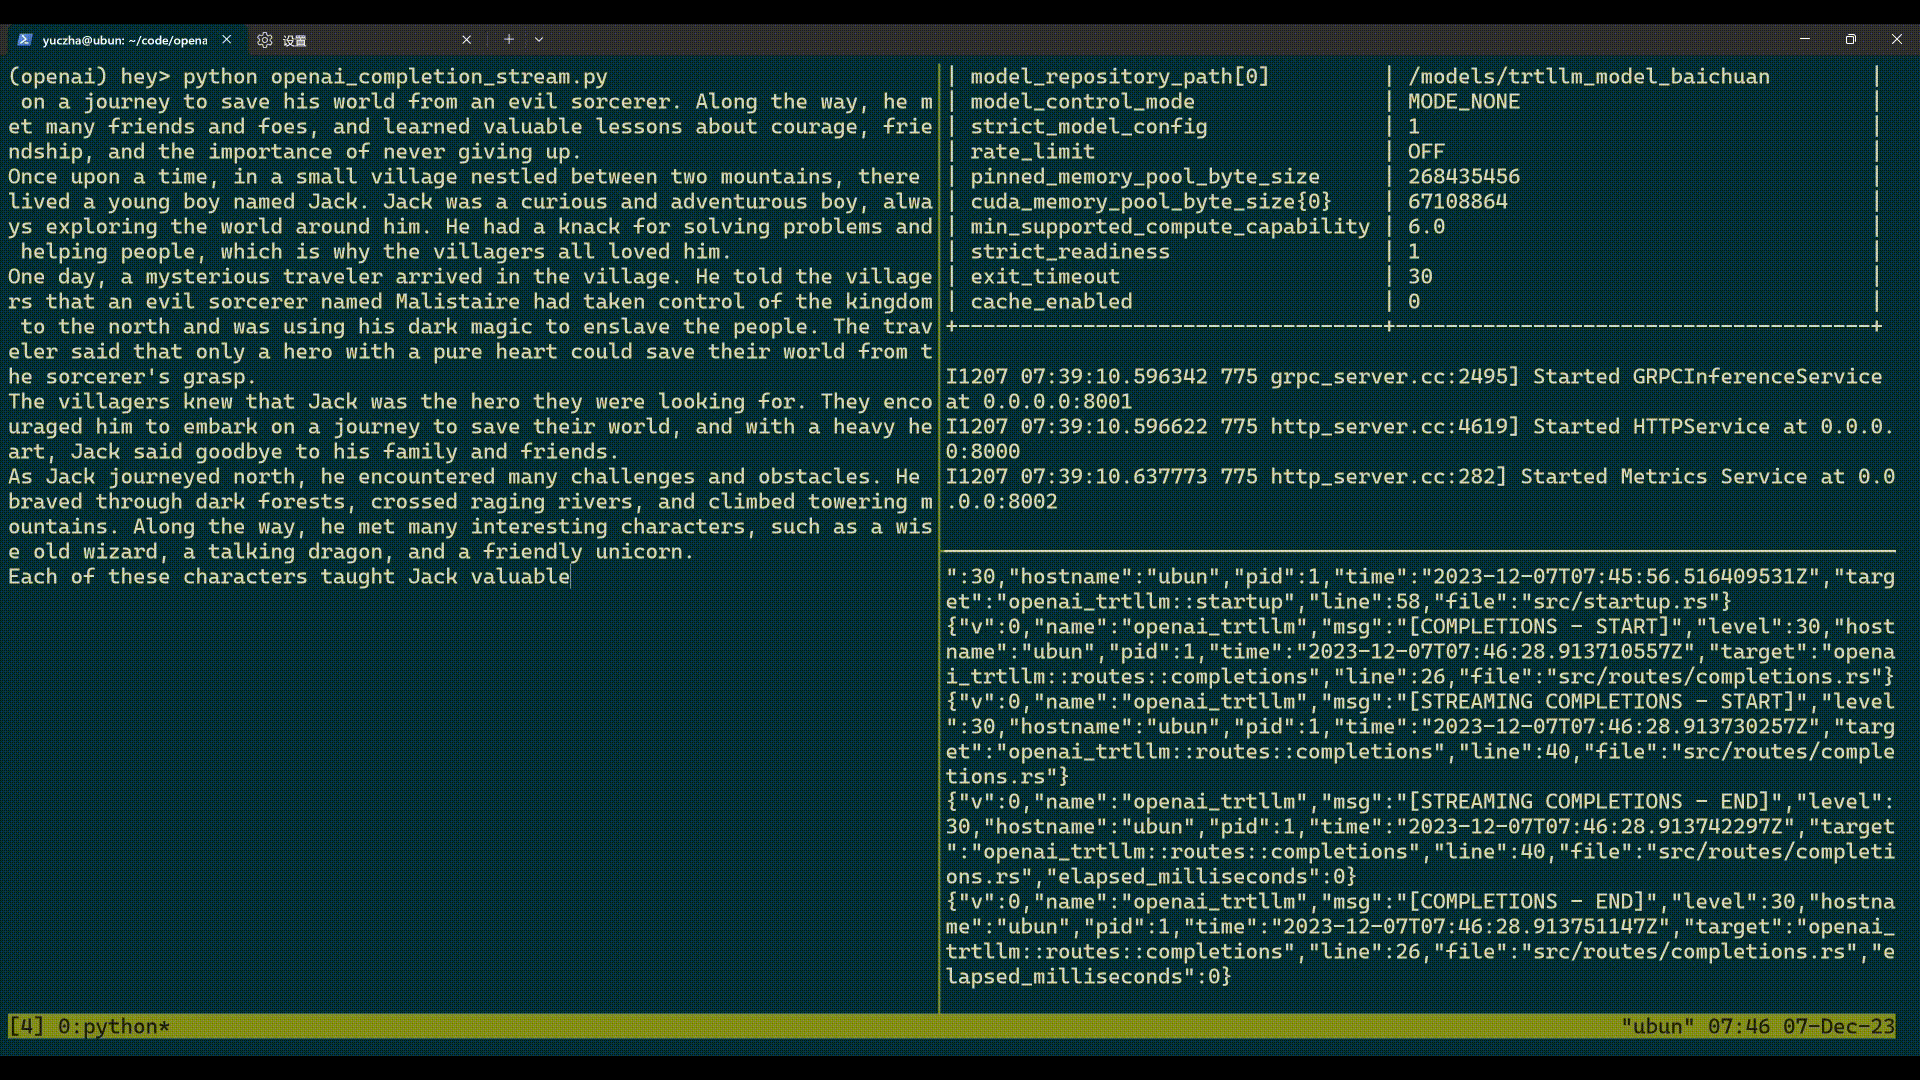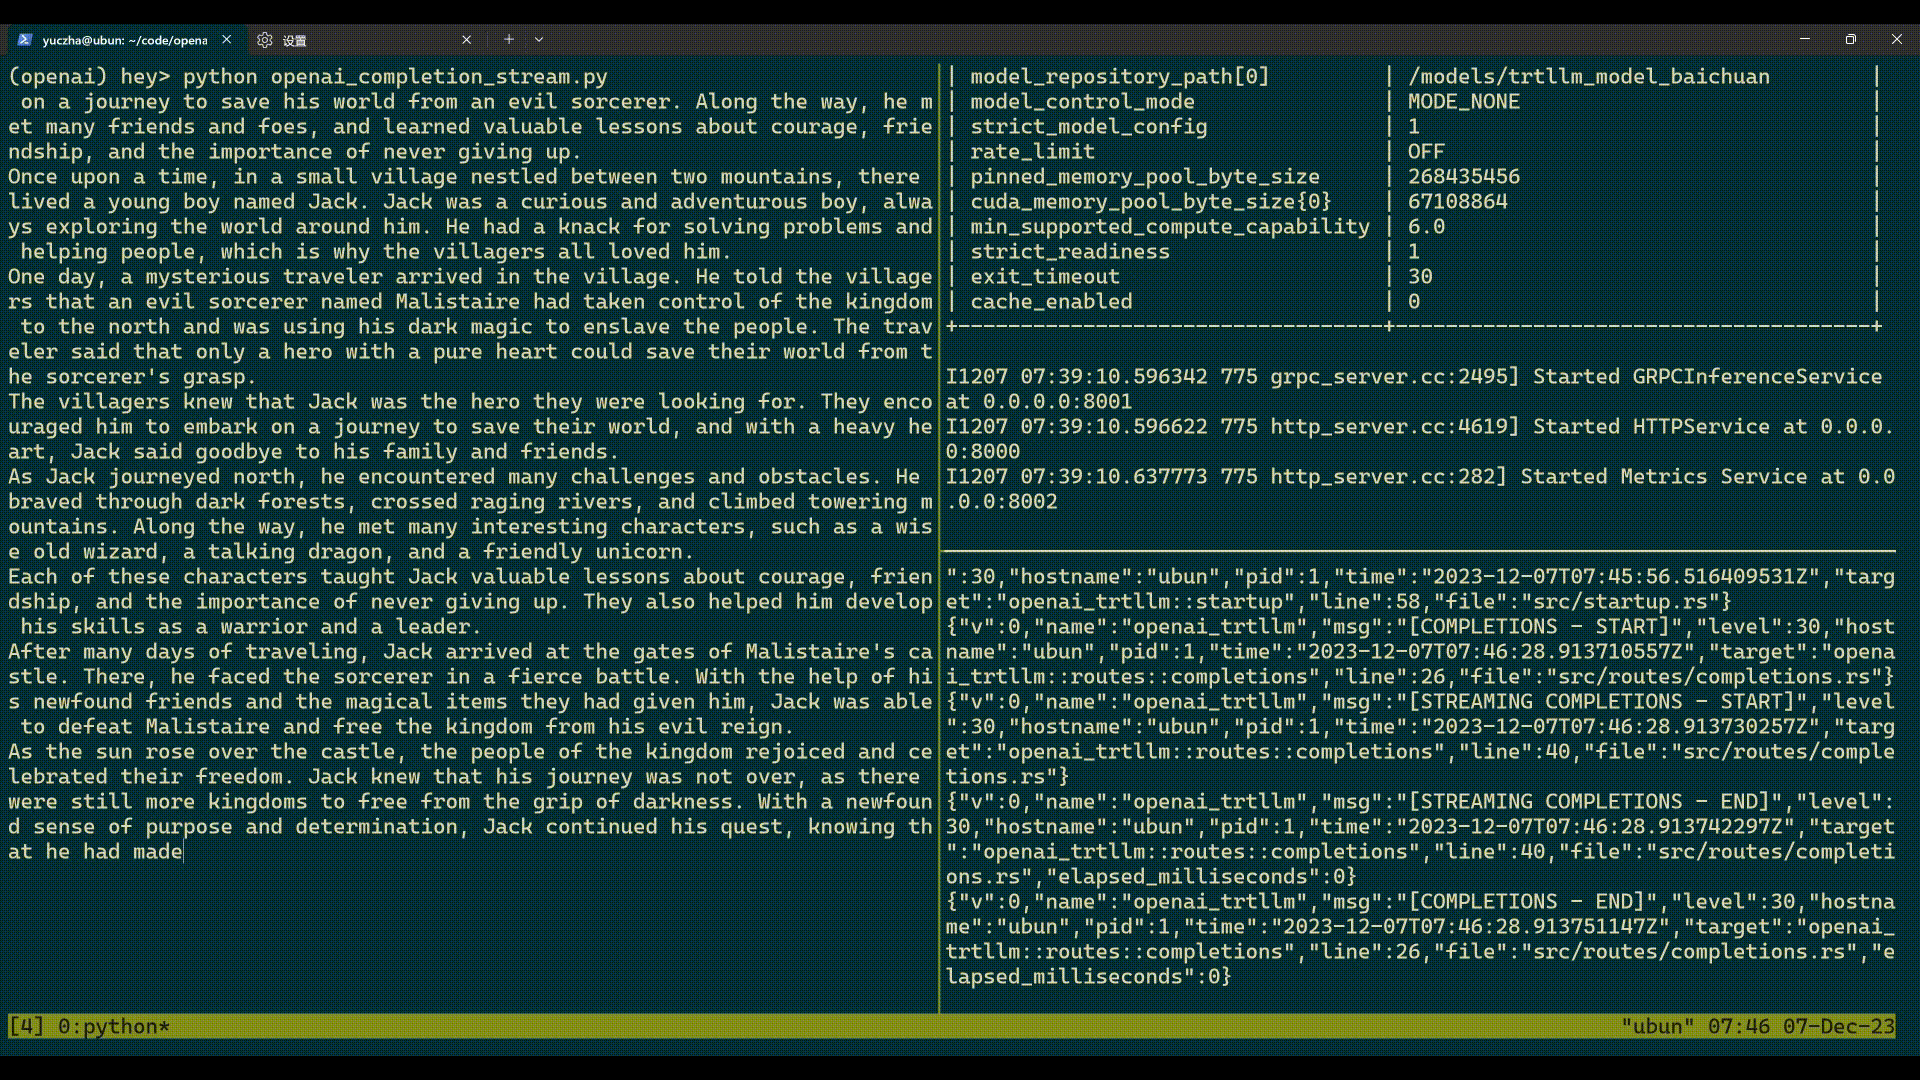
Deep Learning Deployment Framework: Supports tf/torch/trt/trtllm/vllm and other NN frameworks. Support dynamic batching, and streaming modes. It is dual-language compatible with Python and C++, offering scalability, extensibility, and high performance. It helps users quickly deploy models and provide services through HTTP/RPC interfaces.
- 172
- C++
- Apache-2.0
- 19 mo ago

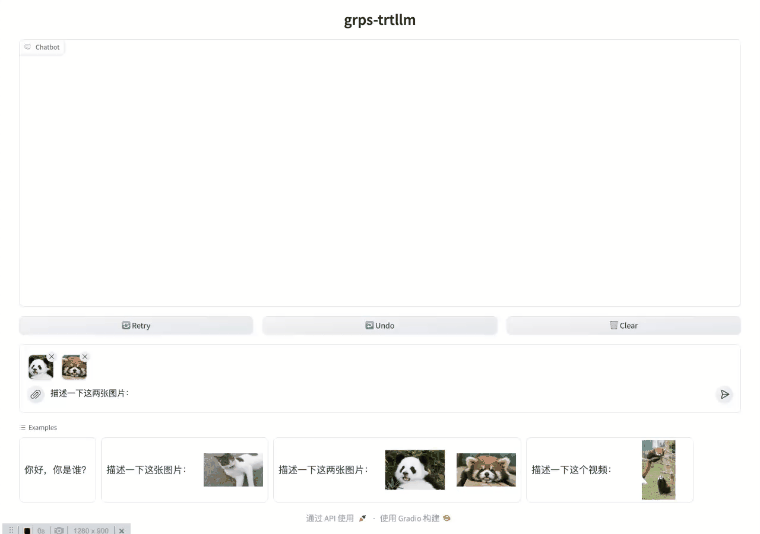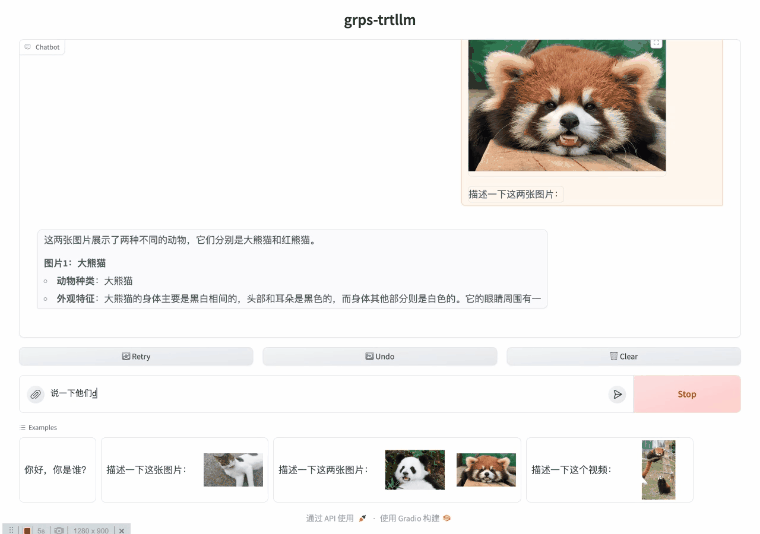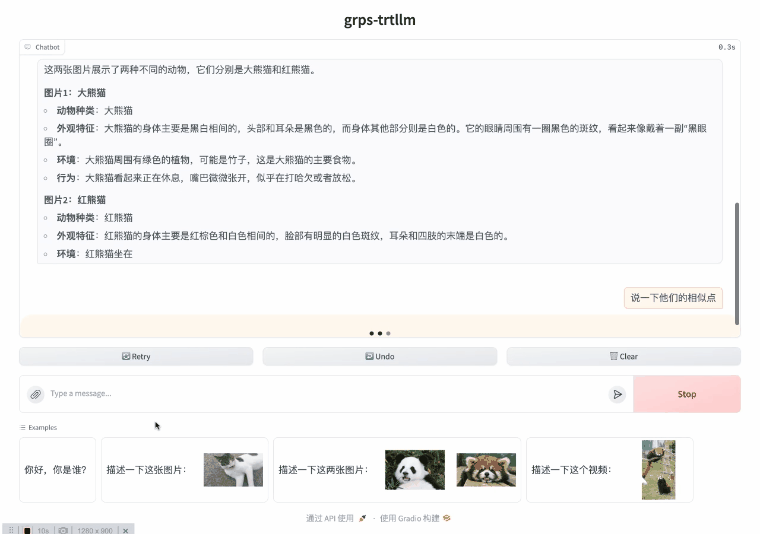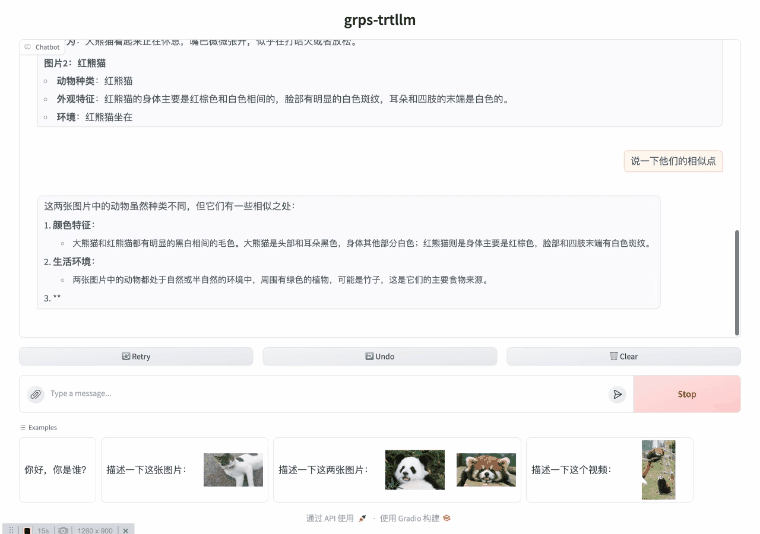
grps_trtllm
Higher performance OpenAI LLM service than vLLM serve: A pure C++ high-performance OpenAI LLM service implemented with GPRS+TensorRT-LLM+Tokenizers.cpp, supporting chat and function call, AI agents, distributed multi-GPU inference, multimodal capabilities, and a Gradio chat interface.
- 160
- Python
- Apache-2.0
- 12 mo ago
GPU-Perf-Playground
GPU 性能与 AI Infra 学习项目:CUDA/Triton 算子、NCU/NSYS、vLLM/SGLang/TRT-LLM/ms-swift、PyTorch/DeepSpeed/ms-swift 训练、并行架构
- 126
- Python
- Apache-2.0
- 2 mo ago


LLM-Tutorial
LLM tutorial materials include but not limited to NVIDIA NeMo, TensorRT-LLM, Triton Inference Server, and NeMo Guardrails.
- 17
- Python
- Apache-2.0
- 17 mo ago

linux-kernel-inference-fastpath
Linux kernel and systems fast path for LLM inference: eBPF tracing, runtime hints, cgroups, NUMA/GPU locality, KV-cache memory policies, TTFT boost, and experimental kernel primitives.
- 3
- 5 mo ago

NIM Inference TCO Lab
Compare managed API, NVIDIA NIM, and raw OSS inference TCO
Runs in the browser on Hugging Face
- 0
- mit
- 3 wk ago
Qwen3-1.7B-TensorRT-LLM-Checkpoint-FP8
Text generation model, used with tensorrt-llm.
- 0
- 22
- apache-2.0
- 8 mo ago
Qwen2.5-1.5B-Instruct-TensorRT-LLM-Checkpoint-FP8
Text generation model, used with tensorrt-llm.
- 0
- 22
- apache-2.0
- 8 mo ago
Qwen2.5-1.5B-Instruct-TensorRT-LLM-Checkpoint-NVFP4
Text generation model, used with tensorrt-llm.
- 0
- 17
- apache-2.0
- 8 mo ago
Qwen3-4B-TensorRT-LLM-Checkpoint-FP8
Text generation model, used with tensorrt-llm.
- 0
- 16
- apache-2.0
- 8 mo ago
Qwen3-0.6B-TensorRT-LLM-Checkpoint-FP8
Text generation model, used with tensorrt-llm.
- 0
- 16
- apache-2.0
- 8 mo ago
Phi-4-mini-instruct-TensorRT-LLM-Checkpoint-NVFP4
Text generation model, used with tensorrt-llm.
- 0
- 16
- mit
- 8 mo ago
Qwen2.5-1.5B-Instruct-TensorRT-LLM-Checkpoint-FP16
Text generation model, used with tensorrt-llm.
- 0
- 16
- apache-2.0
- 8 mo ago
Phi-4-mini-instruct-TensorRT-LLM-Checkpoint-FP8
Text generation model, used with tensorrt-llm.
- 0
- 13
- mit
- 8 mo ago