tesseract


OCRmyPDF
OCRmyPDF adds an OCR text layer to scanned PDF files, allowing them to be searched
- 35k
- Python
- MPL-2.0
- 7 d ago

PyMuPDF
Layout-aware document engine for AI and a feature-rich Python toolkit for extracting, rendering and editing PDFs and other documents. Since version 2.0, its ML-based layout analysis turns PDFs and Office files into high-quality Markdown for RAG and agents, running fast on CPU and grounding every result to its source page.
- 11k
- Python
- AGPL-3.0
- 1 d ago

xberg
The fast, precise document-intelligence engine for every language: text, tables and metadata from 100+ formats, with OCR, transcription and code intelligence.
- 9.6k
- Rust
- MIT
- 59 min ago

tessdata
Trained models with fast variant of the "best" LSTM models + legacy models
- 7.7k
- Apache-2.0
- 3 y ago




llm_aided_ocr
Enhances Tesseract OCR output using LLMs (local or API) for error correction, smart chunking, and markdown formatting of scanned PDFs
- 3k
- Python
- 3 wk ago


Tesseract4Android
Fork of tess-two rewritten from scratch to support latest version of Tesseract OCR.
- 951
- C
- Apache-2.0
- 10 mo ago


scribeocr
Web interface for recognizing text, proofreading OCR, and creating fully-digitized documents.
- 811
- JavaScript
- AGPL-3.0
- 4 wk ago


BetterOCR
🔍 Better text detection by combining multiple OCR engines (EasyOCR, Tesseract, and Pororo) with 🧠 LLM.
- 644
- Python
- MIT
- 18 mo ago

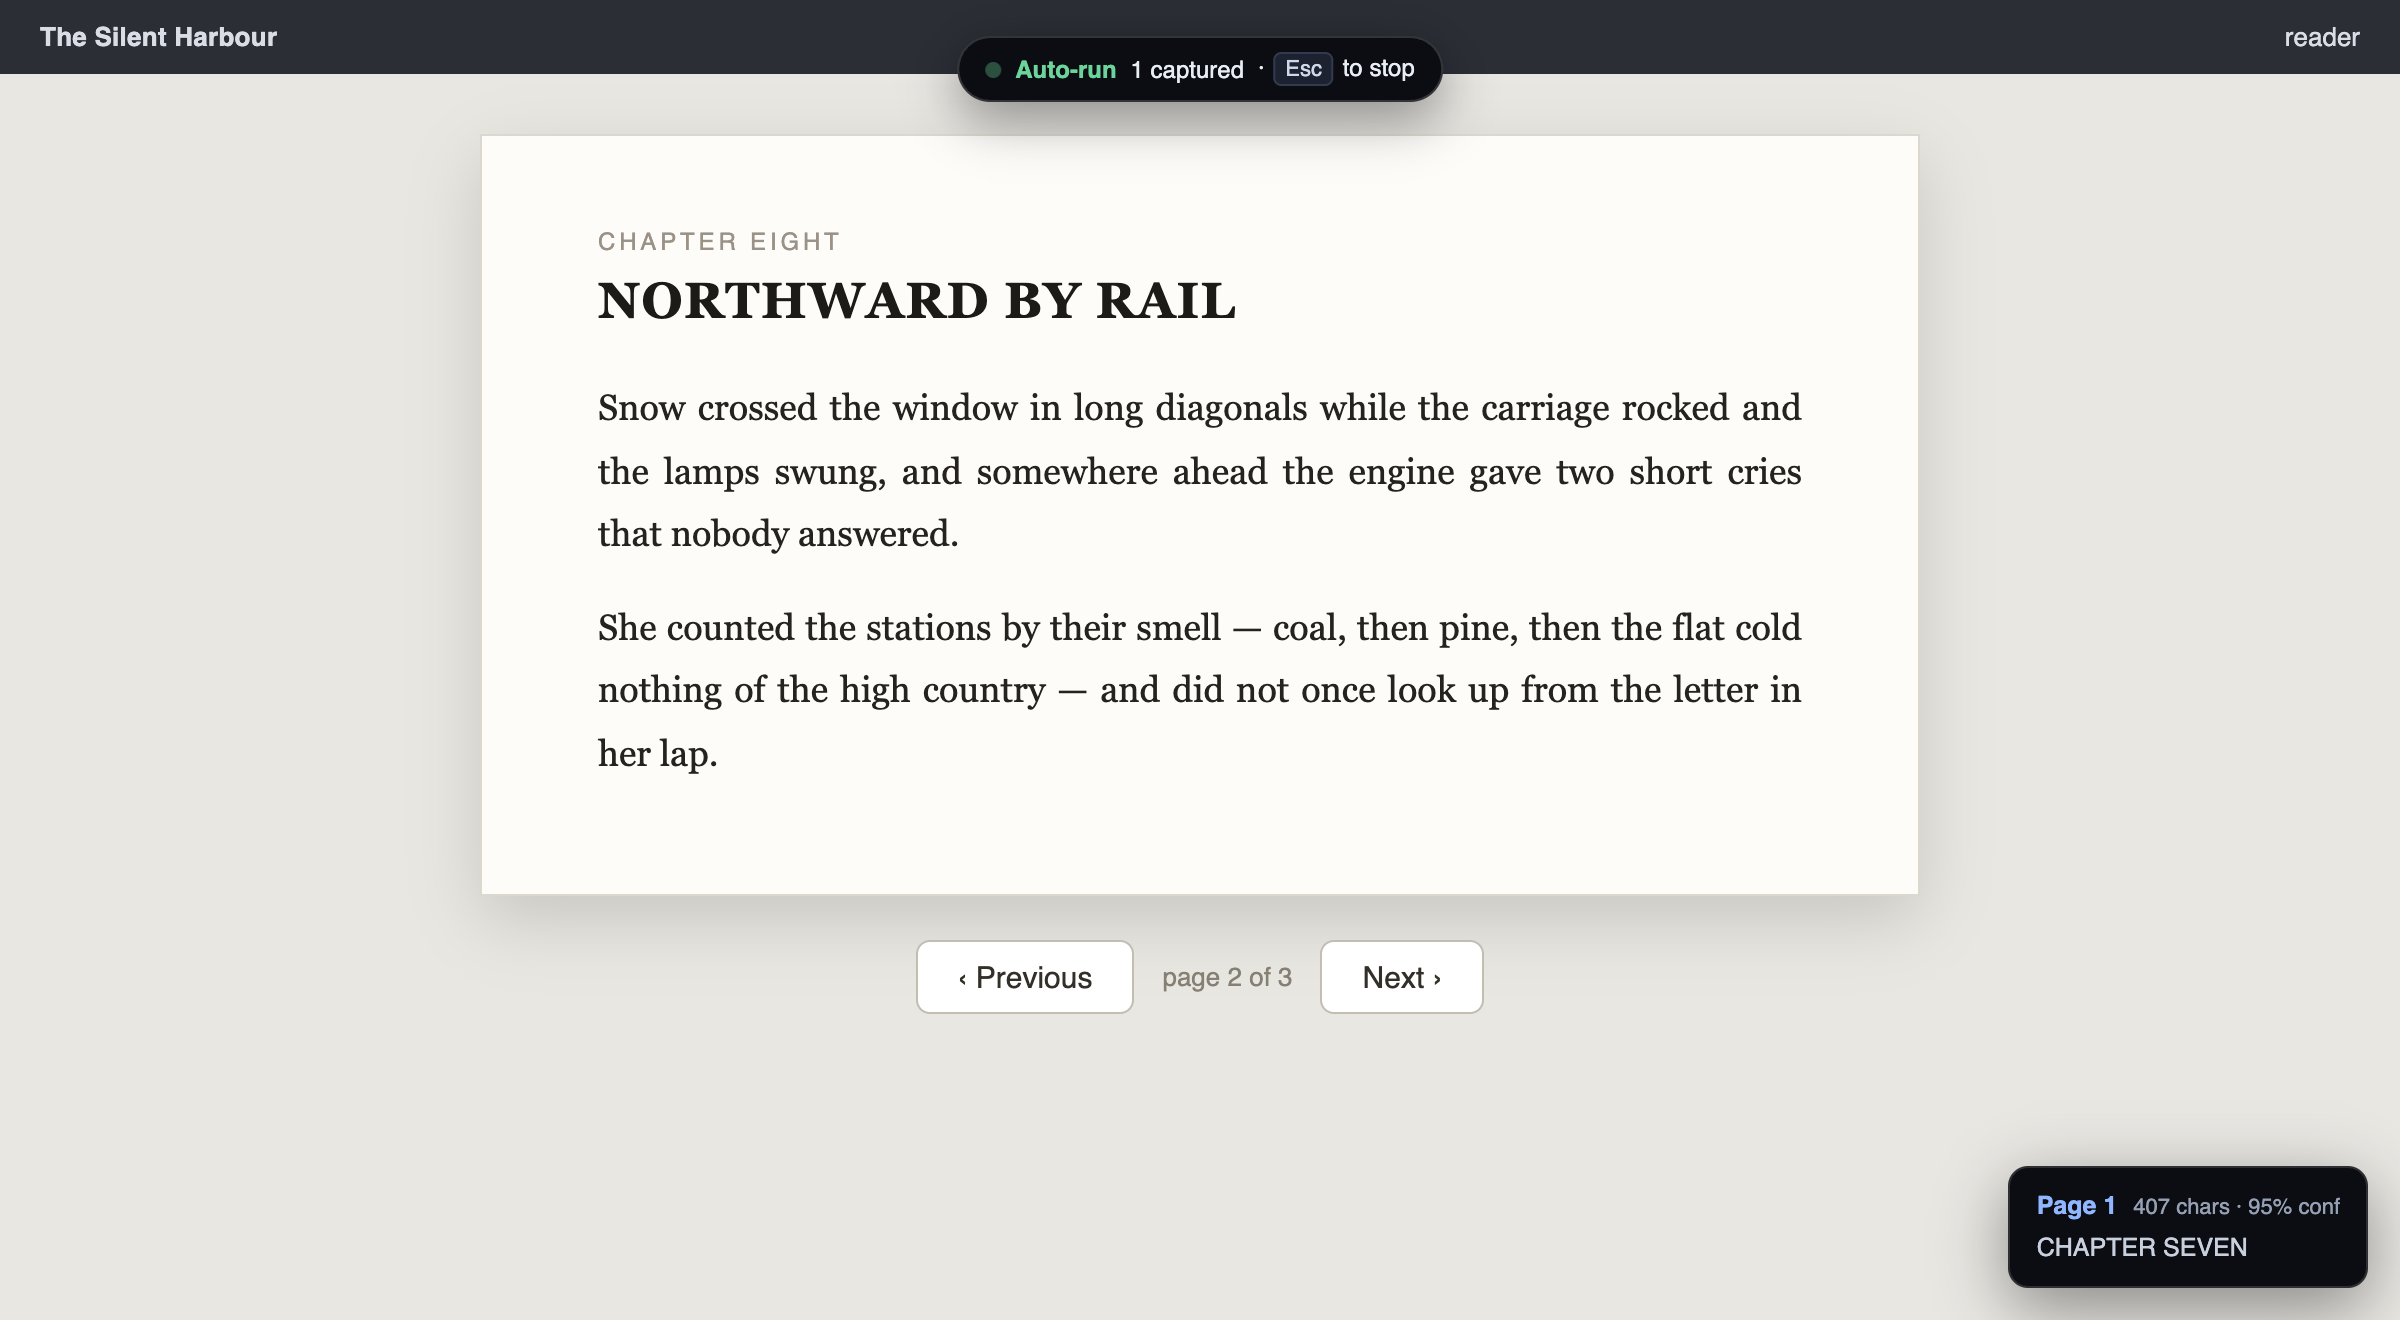
ocr-it
Chrome extension: pin a screen region once, then hotkey your way through a paginated document. OCR runs 100% offline via bundled Tesseract.
- 431
- JavaScript
- MIT
- 3 mo ago


image2text
:clipboard: Python wrapper to grab text from images and save as text files using Tesseract Engine
- 423
- Python
- 16 mo ago

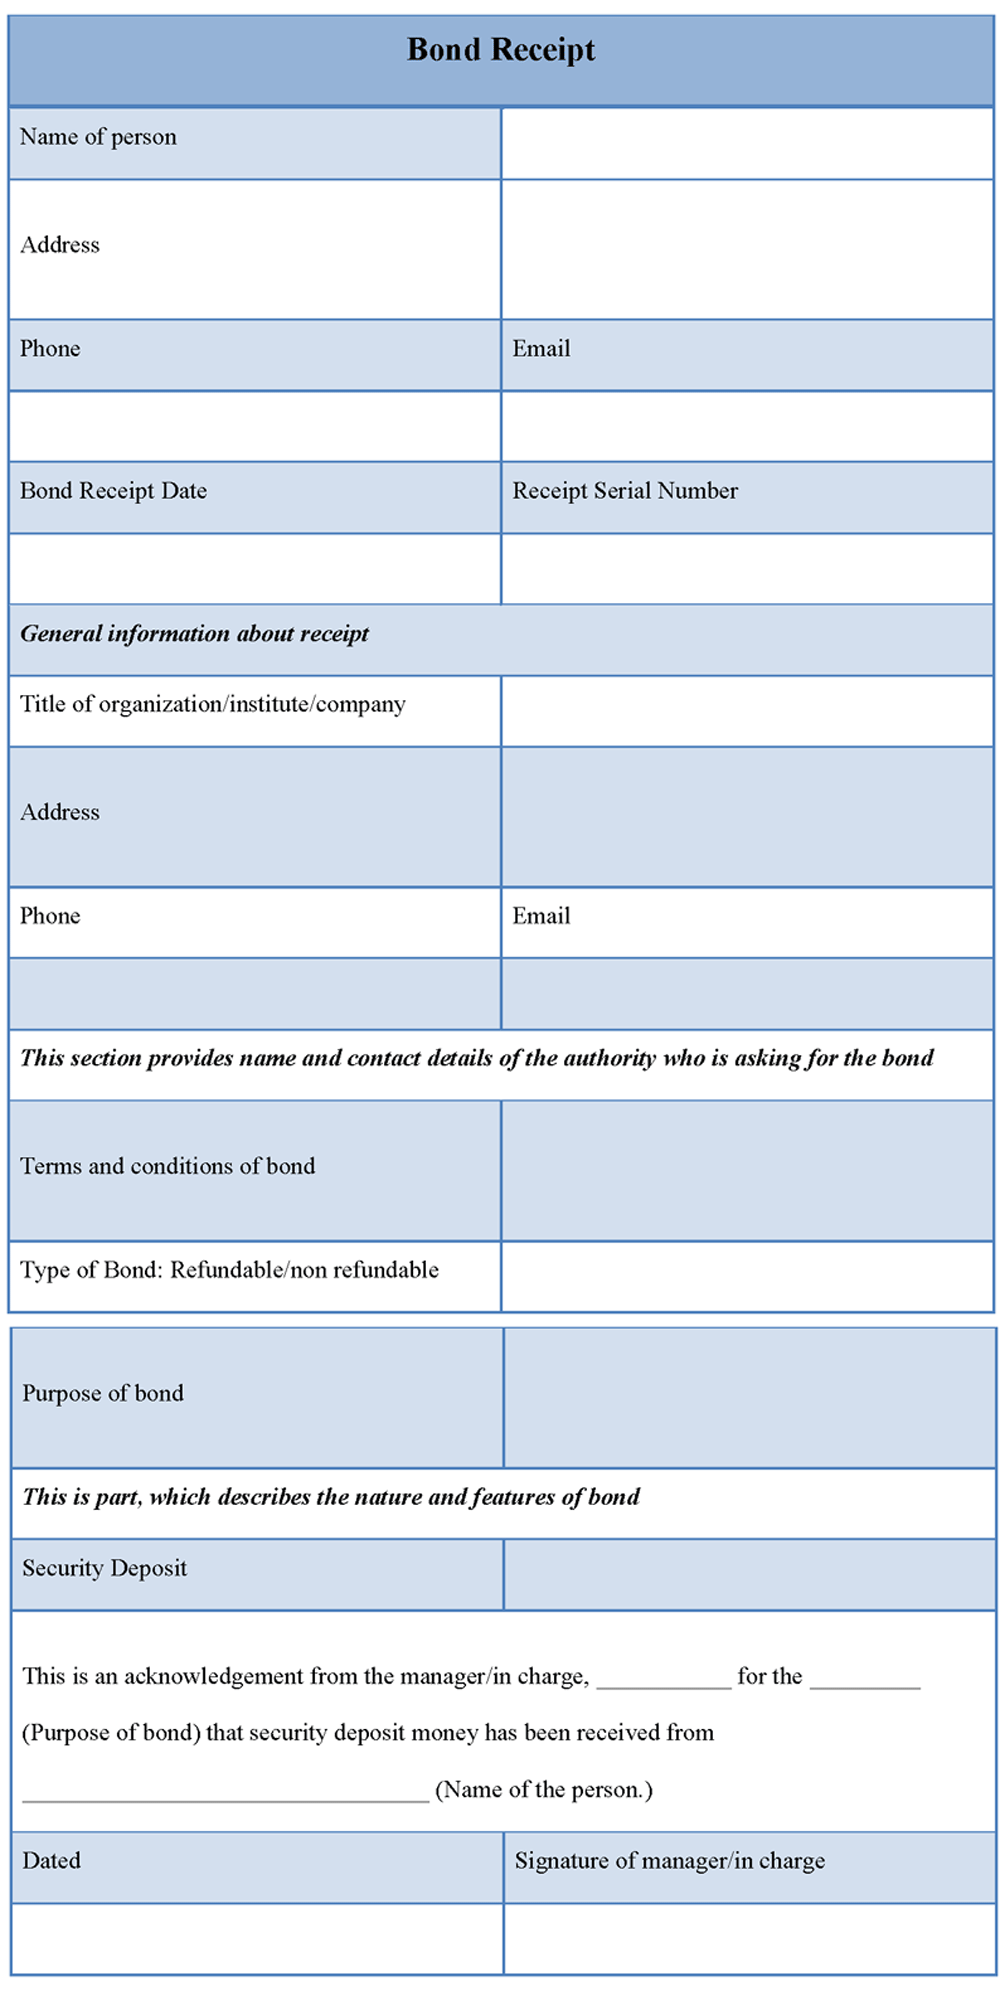
ocrtable
Recognize tables and text from scanned images that contain tables. 从包含表格的扫描图片中识别表格和文字
- 257
- C++
- MIT
- 3 y ago


links-detector
📖 👆🏻 Links Detector makes printed links clickable via your smartphone camera. No need to type a link in, just scan and click on it.
- 186
- TypeScript
- MIT
- 12 mo ago

koreader-base
Base framework offering a Lua scriptable environment for creating document readers
- 236
- Lua
- AGPL-3.0
- 2 d ago


fastmrz
⚡Extracting the Machine Readable Zone (MRZ) from passport or any document images
- 173
- Python
- AGPL-3.0
- 2 d ago

lambda-text-extractor
AWS Lambda functions to extract text from various binary formats.
- 179
- Python
- Apache-2.0
- 9 y ago

LaraOCR
Laravel Optical Character Reader(OCR) package using ocr engines(Tesseract)
- 170
- PHP
- Apache-2.0
- 3 y ago


ocr-python
OCR library to extract text & tables from PDF files and images. Convert any image or PDF to CSV / TXT / JSON / Searchable PDF.
- 129
- Jupyter Notebook
- MIT
- 4 y ago

aws-lambda-tesseract-layer
A layer for AWS Lambda containing the tesseract C libraries and tesseract executable.
- 123
- TypeScript
- Apache-2.0
- 4 d ago


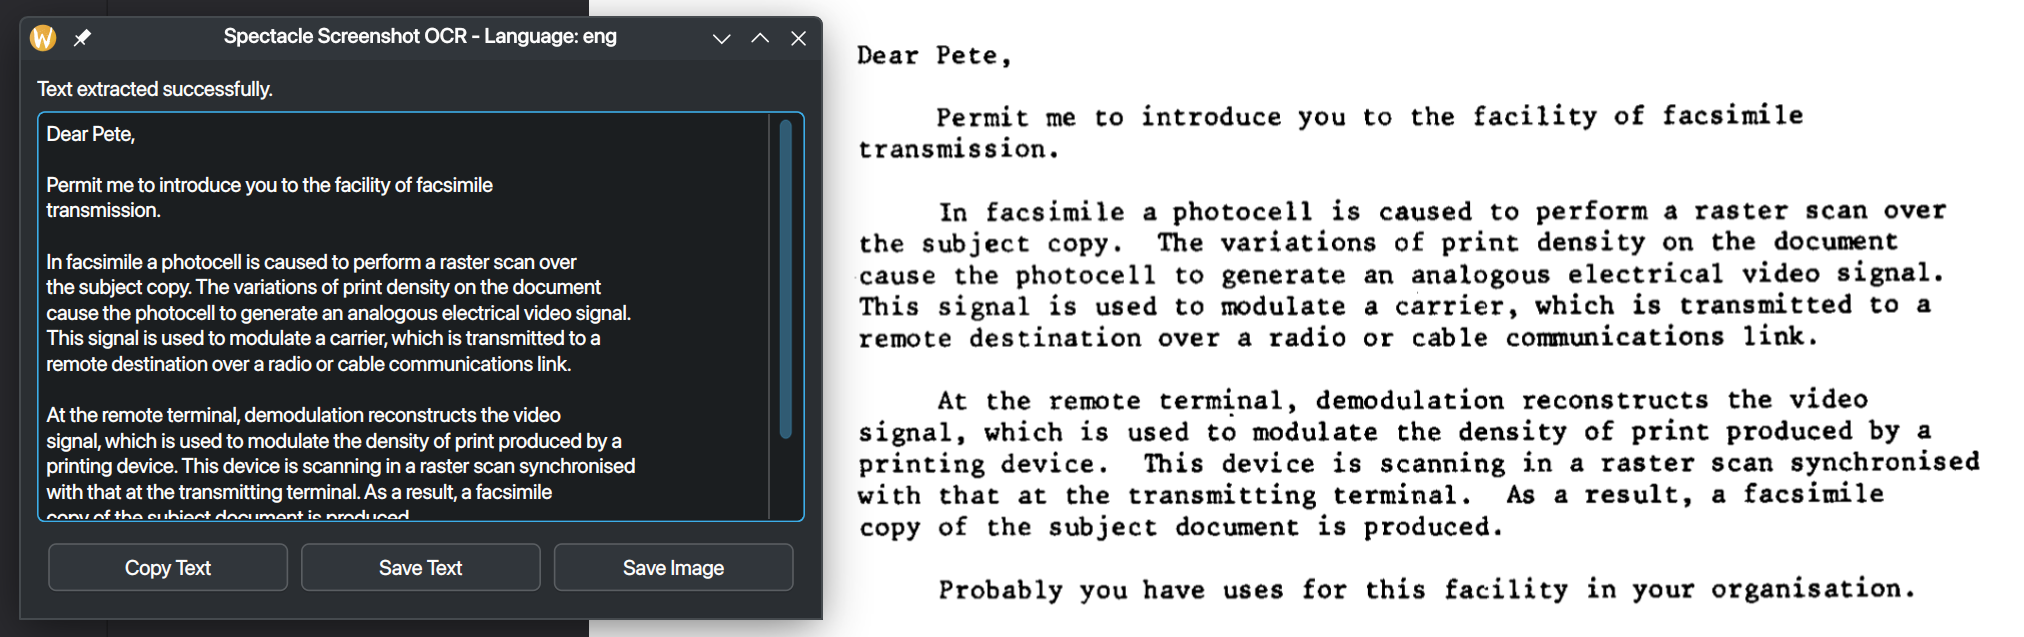
spectacle-ocr-screenshot
A simple utility to automatically extract text from spectacle on plasma desktops
- 93
- Makefile
- MIT
- 15 mo ago


PAN_Card_OCR_Project
To extract details from Indian National Identification Cards such as PAN (completed) & Aadhar, Passport, Driving License (WIP) in a structured format
- 83
- Python
- 7 y ago
