trafilatura
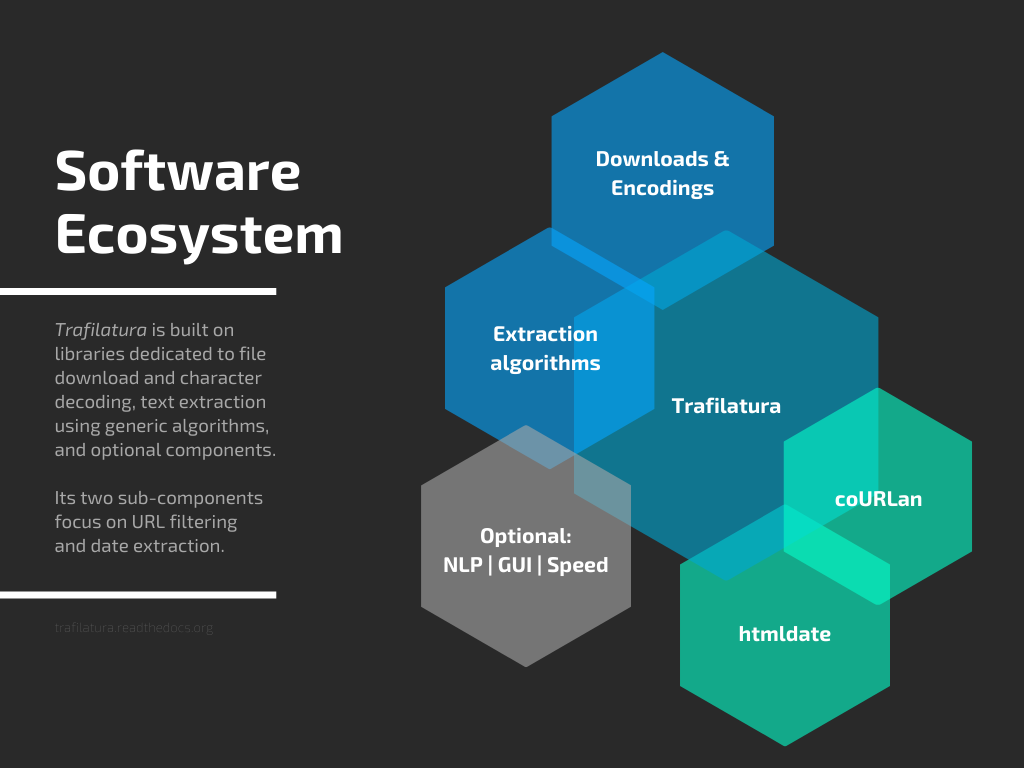
Python & Command-line tool to gather text and metadata on the Web: Crawling, scraping, extraction, output as CSV, JSON, HTML, MD, TXT, XML
- 7.2k
- Python
- Apache-2.0
- 14 h ago
Python & Command-line tool to gather text and metadata on the Web: Crawling, scraping, extraction, output as CSV, JSON, HTML, MD, TXT, XML
E2M converts various file types (doc, docx, epub, html, htm, url, pdf, ppt, pptx, mp3, m4a) into Markdown. It’s easy to install, with dedicated parsers and converters, supporting custom configs. E2M offers an all-in-one, flexible, and open-source solution.
Grammarify is a npm package that safely cleans up text that has mispellings, improper capitalization, lexical illusions, among other things.
Dataiku DSS plugin to detect languages, correct misspellings, and clean text data 🧼
Article title, authors, date and body extraction dataset.
A Scrapy package based web scraper for collecting Kurdish text data from websites. The tool recursively crawls specified domains, extracts article content using Trafilatura, and filters results by language using Facebook's FastText language identification model.