trafilatura
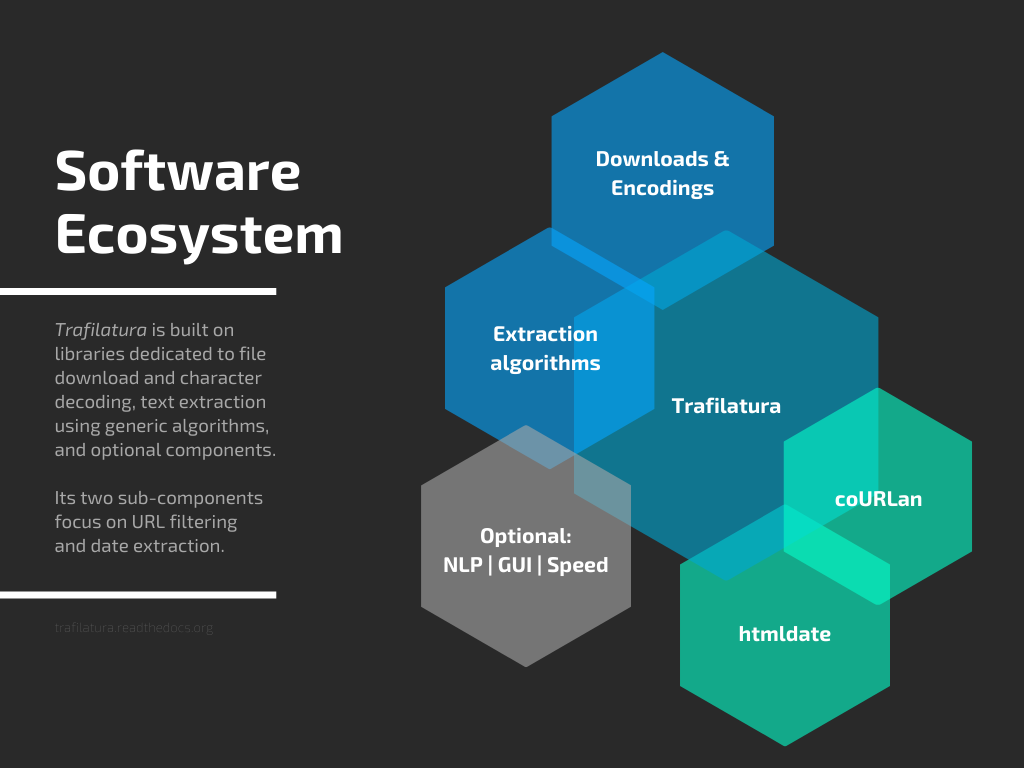
Python & Command-line tool to gather text and metadata on the Web: Crawling, scraping, extraction, output as CSV, JSON, HTML, MD, TXT, XML
- 7.1k
- Python
- Apache-2.0
- 11 h ago
Python & Command-line tool to gather text and metadata on the Web: Crawling, scraping, extraction, output as CSV, JSON, HTML, MD, TXT, XML
:book: A curated list of resources dedicated to Natural Language Processing (NLP)
a curated list of R tutorials for Data Science, NLP and Machine Learning
Starter code to solve real world text data problems. Includes: Gensim Word2Vec, phrase embeddings, Text Classification with Logistic Regression, word count with pyspark, simple text preprocessing, pre-trained embeddings and more.
Open Source research tool to search, browse, analyze and explore large document collections by Semantic Search Engine and Open Source Text Mining & Text Analytics platform (Integrates ETL for document processing, OCR for images & PDF, named entity recognition for persons, organizations & locations, metadata management by thesaurus & ontologies, search user interface & search apps for fulltext sear
Resources for learning about Text Mining and Natural Language Processing
🗣️ Tool to generate adversarial text examples and test machine learning models against them
Curated list of open-access/open-source/off-the-shelf resources and tools developed with a particular focus on German
Text Classification by Convolutional Neural Network in Keras
Reworked https://www.readability.com/ parsing library (now https://mercury.postlight.com/ is living alternative)
A PureScript, browser-based implementation of LDA topic modeling.
Modular, fast NLP framework, compatible with Pytorch and spaCy, offering tailored support for French clinical notes.
✨ Awesome - A curated list of amazing Topic Models (implementations, libraries, and resources)
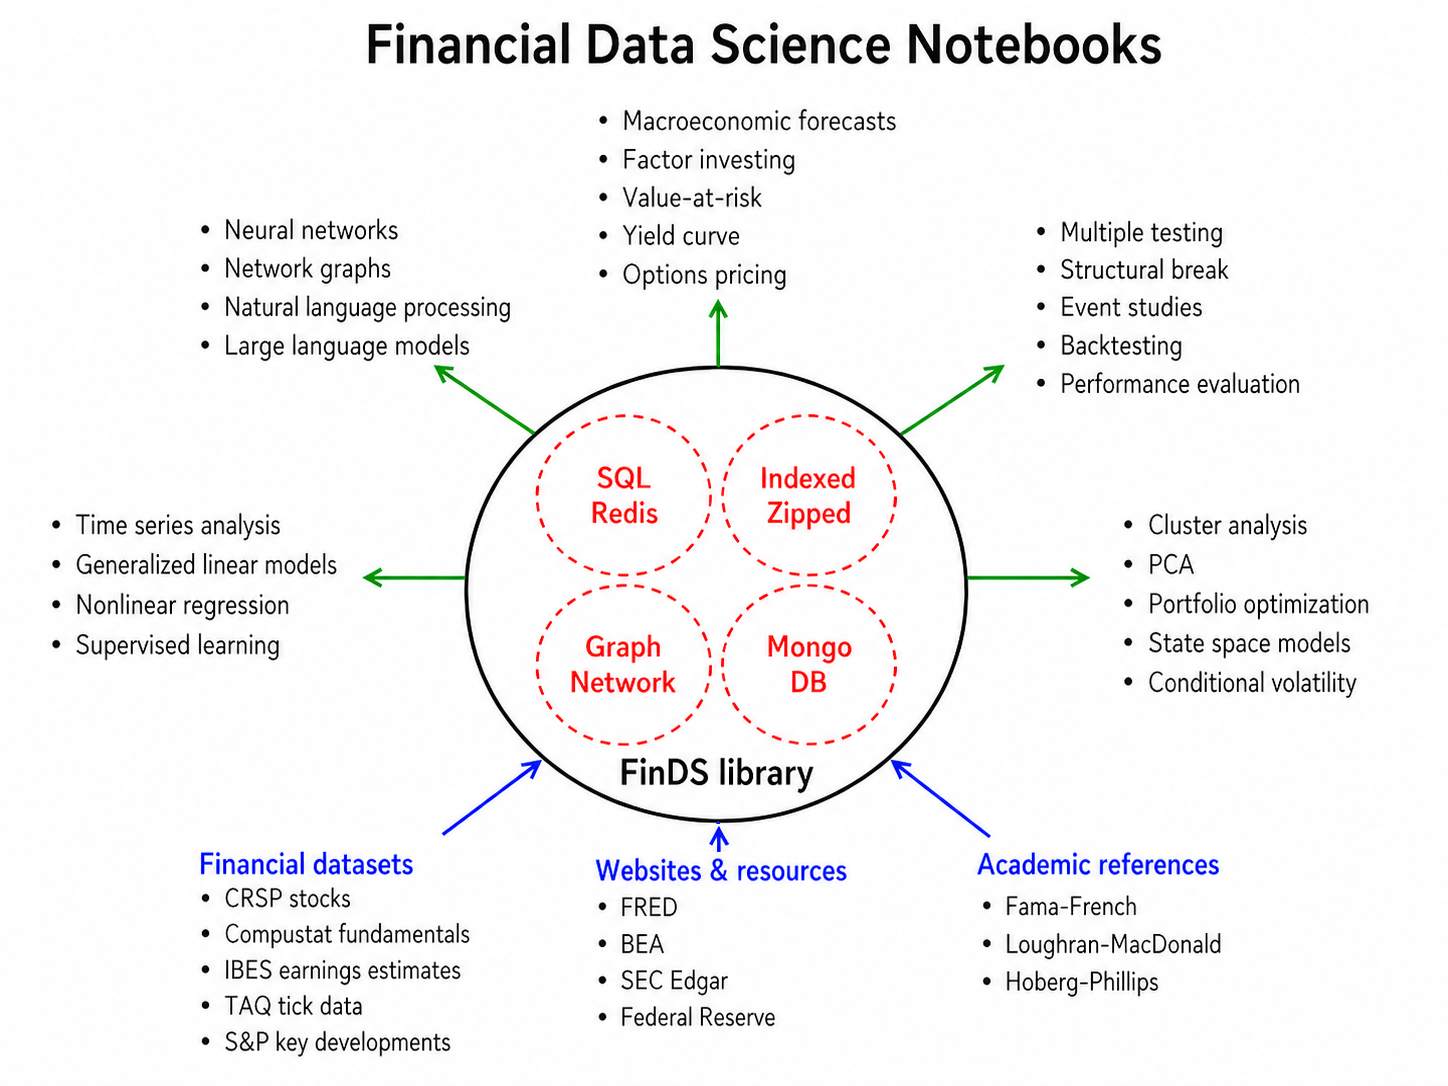
Practical financial data science examples applying statistics, time series analysis, graph analytics, backtesting, machine learning, natural language processing, neural networks and LLMs
A practical guide to topic mining and interactive visualizations
An implementation of "Network Representation Learning with Rich Text Information" (IJCAI '15).
Aim is to come up with a job recommender system, which takes the skills from LinkedIn and jobs from Indeed and throws the best jobs available for you according to your skills.
Machine-learning based pipeline relying on LambdaMART currently used in PubMed for relevance (Best Match) searches
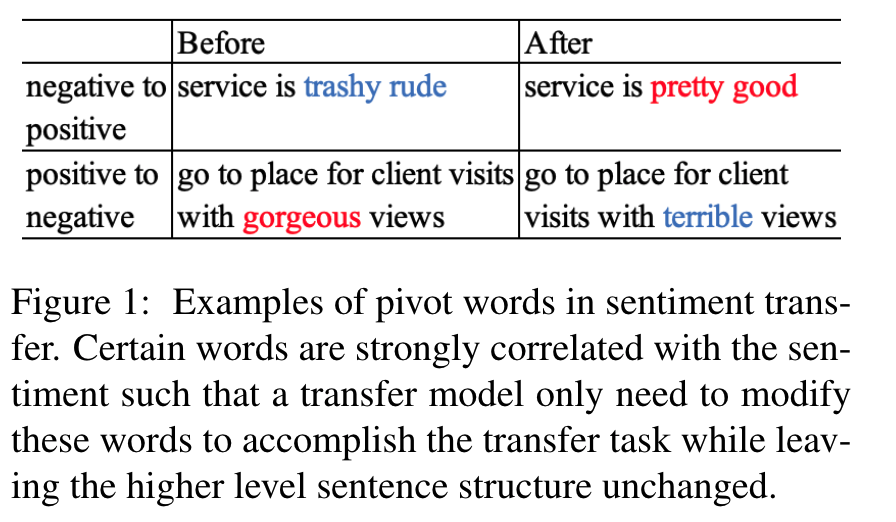
Implementation of INLG 19 paper: Rethinking Text Attribute Transfer: A Lexical Analysis
Utility to compile string of chemical terms into data structure with chemical formula and composition
In this project, you will learn how to generate a complete semantic parse of utterances. First, you will make a discovery on your dataset to get insights about the dataset analytics. Then, you will learn, to extract entities with two different techniques – with spaCy Matcher and by walking on the dependency tree. Next, you will learn different ways of performing intent recognition by analyzing the
This repository will provide an overview and working knowledge of Natural Language Processing (NLP), using Python’s Natural Language Toolkit (NLTK) library and with Keras.
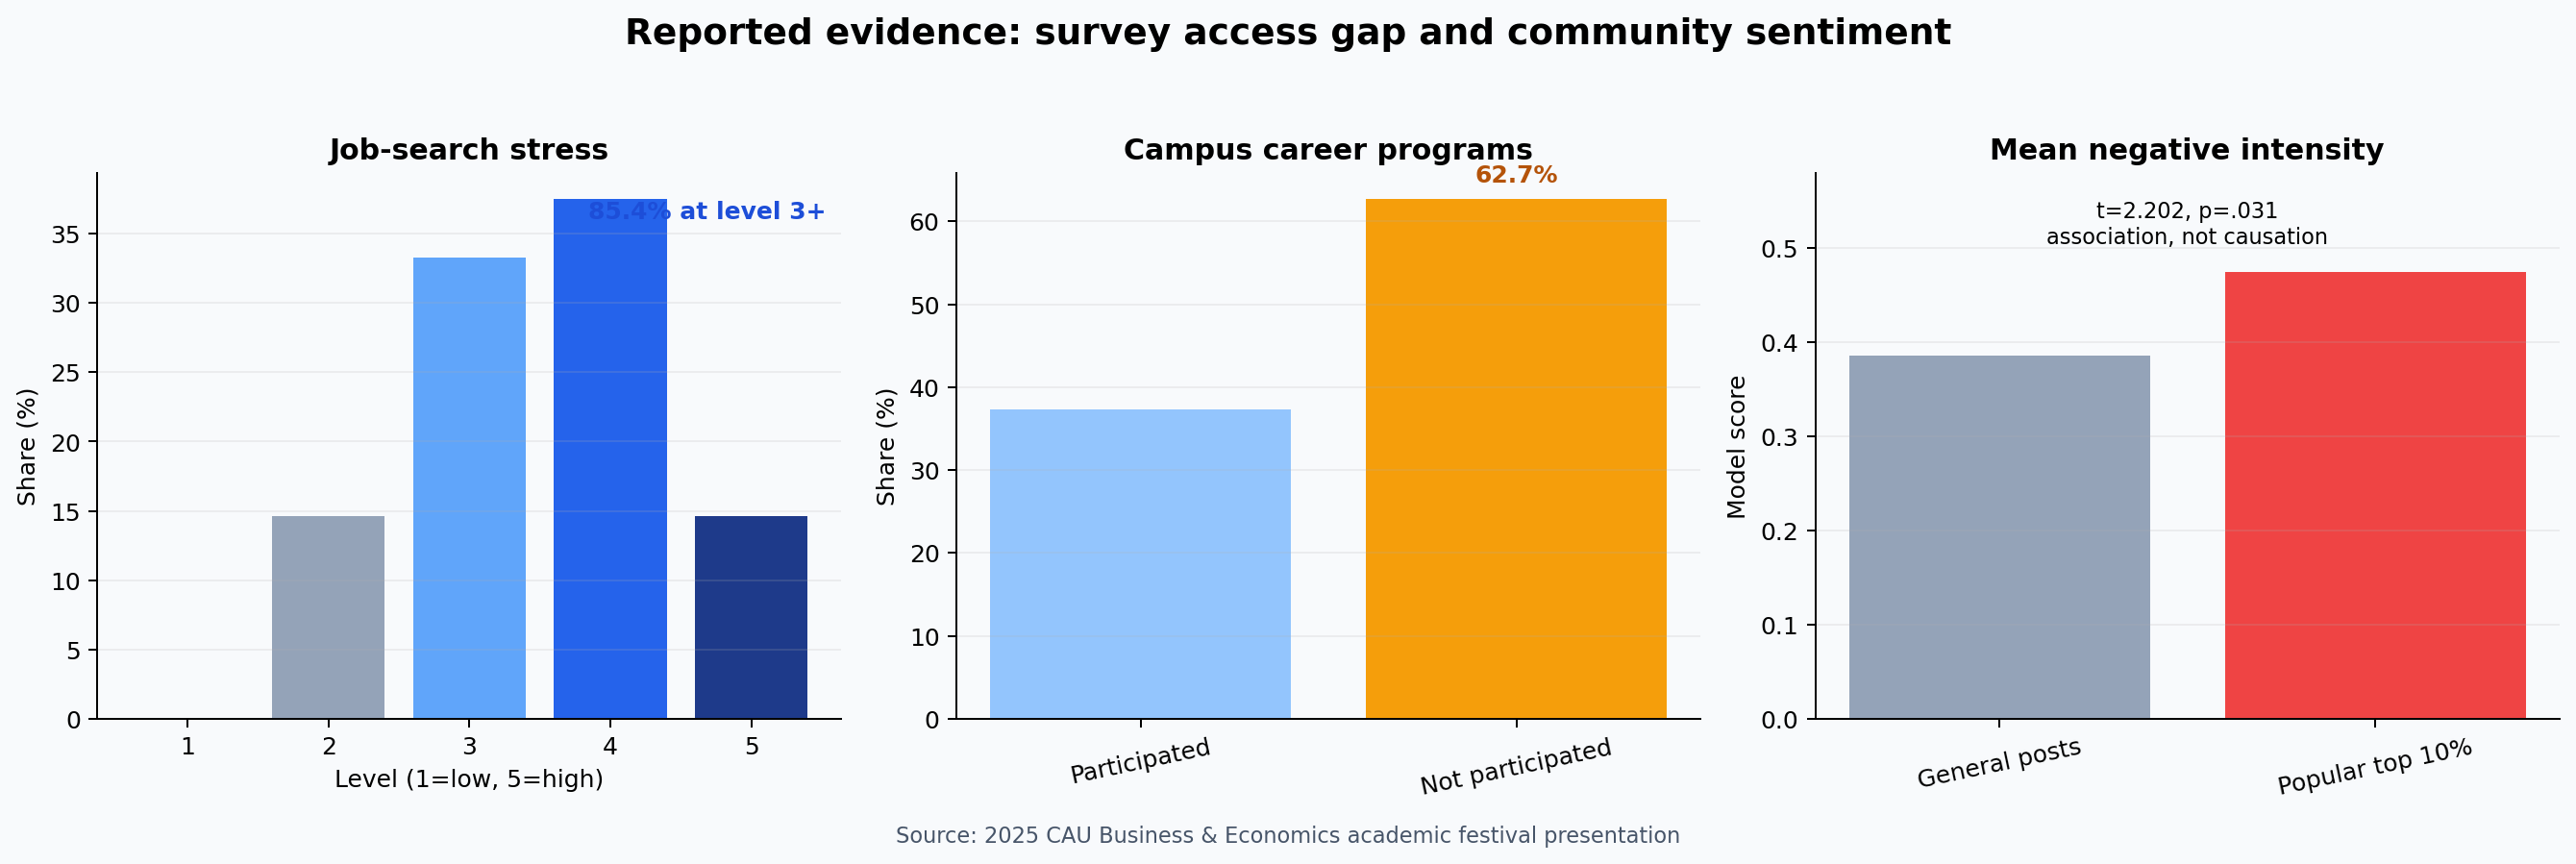
취업 준비 과정의 감정·지원 수요 분석 | KcELECTRA·LDA·군집·설문 기반 지원 제도 제안
A Python-based automation pipeline that scrapes article content from URLs and performs comprehensive NLP-driven sentiment and readability analysis. Outputs include metrics like polarity score, FOG index, word complexity, and more — structured in an Excel-ready format.