Tiktoken
High-performance .NET BPE tokenizer — up to 618 MiB/s, competitive with Rust. Zero-allocation counting, multilingual cache, o200k/cl100k/r50k/p50k encodings + HuggingFace tokenizer.json support.
- 93
- C#
- MIT
- 4 d ago
High-performance .NET BPE tokenizer — up to 618 MiB/s, competitive with Rust. Zero-allocation counting, multilingual cache, o200k/cl100k/r50k/p50k encodings + HuggingFace tokenizer.json support.
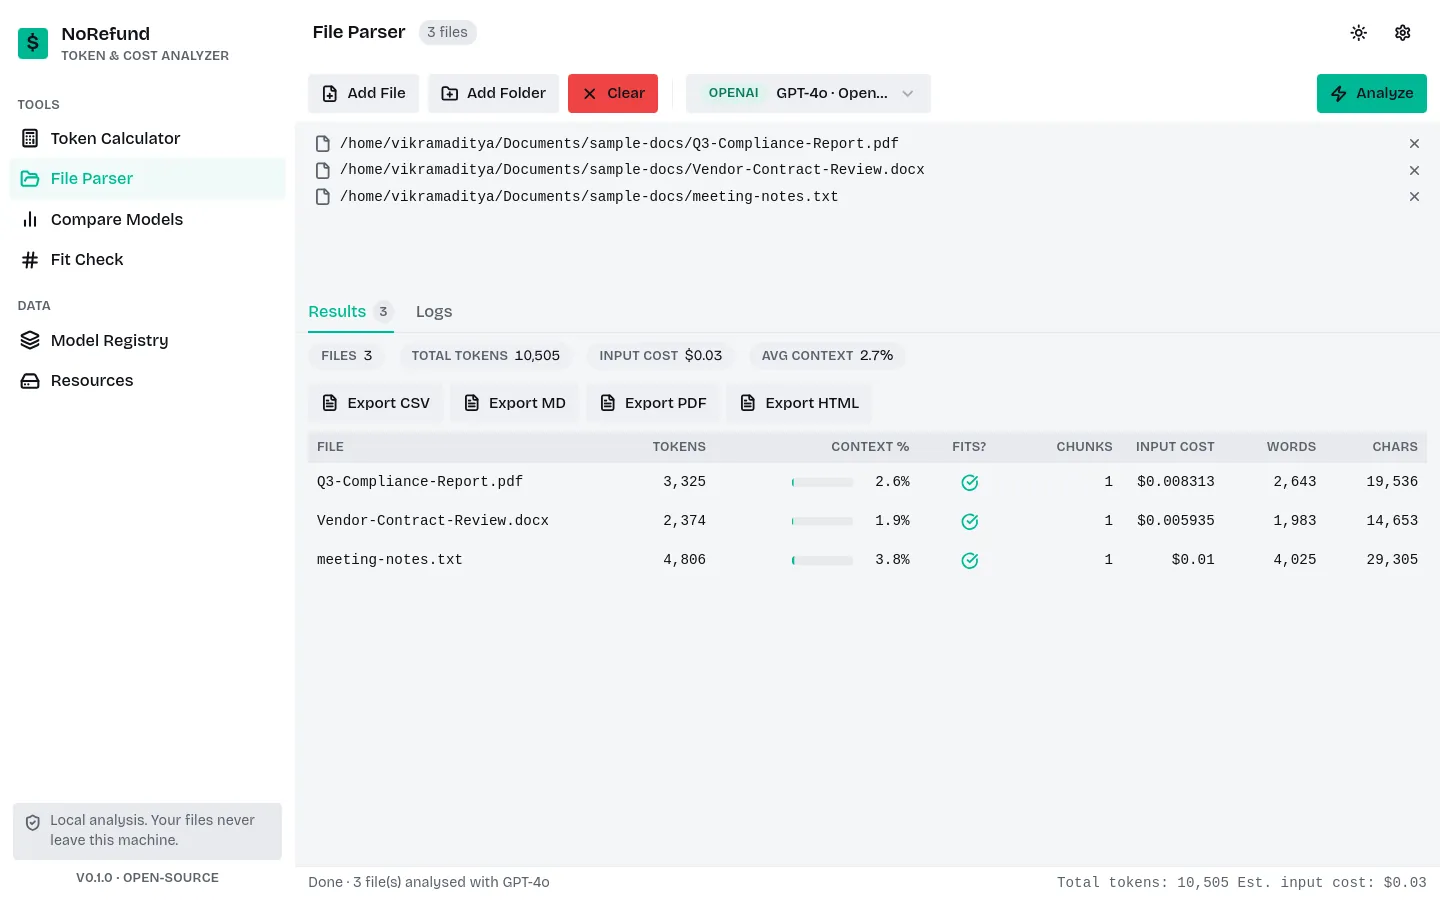
Offline LLM cost calculator and token calculator with real tokenizers, for PDF, DOCX and PPTX files. Real context-window fit, API cost estimates. Nothing leaves your machine.
Token Optimization for Context Engineers. 4.8 KB WASM. Sub-millisecond. Zero dependencies.
🧮 CLI for counting tokens in files and directories using tiktoken
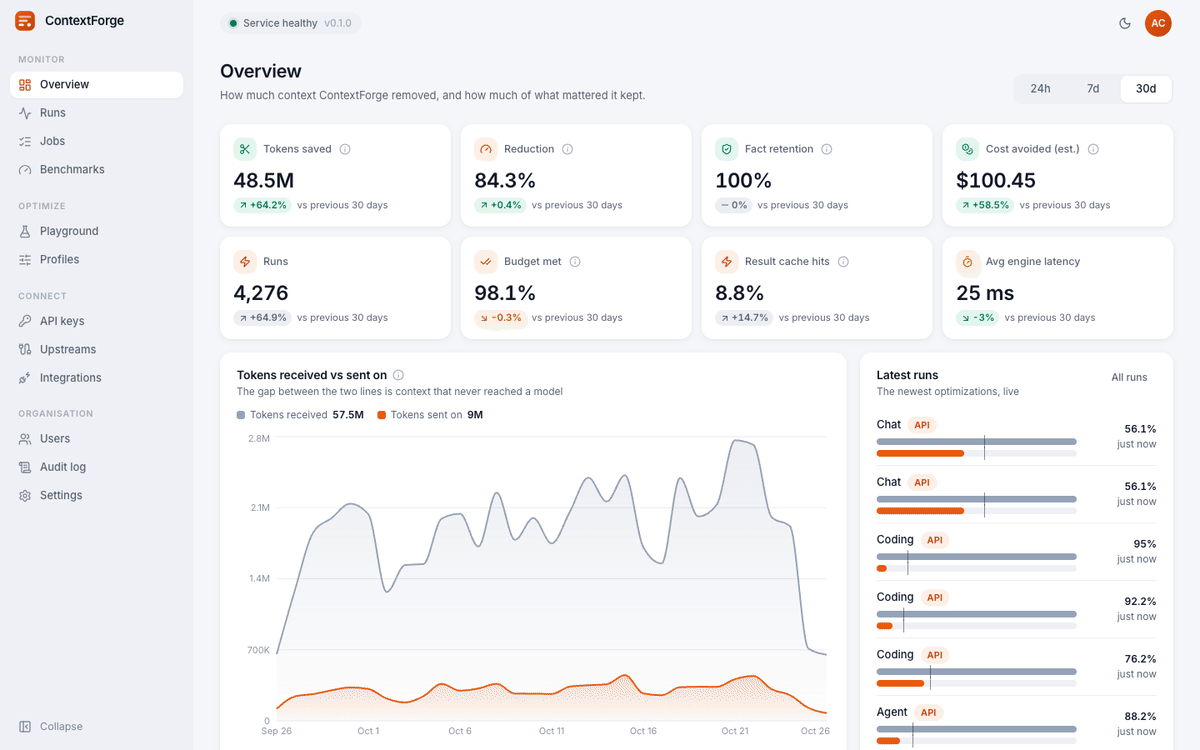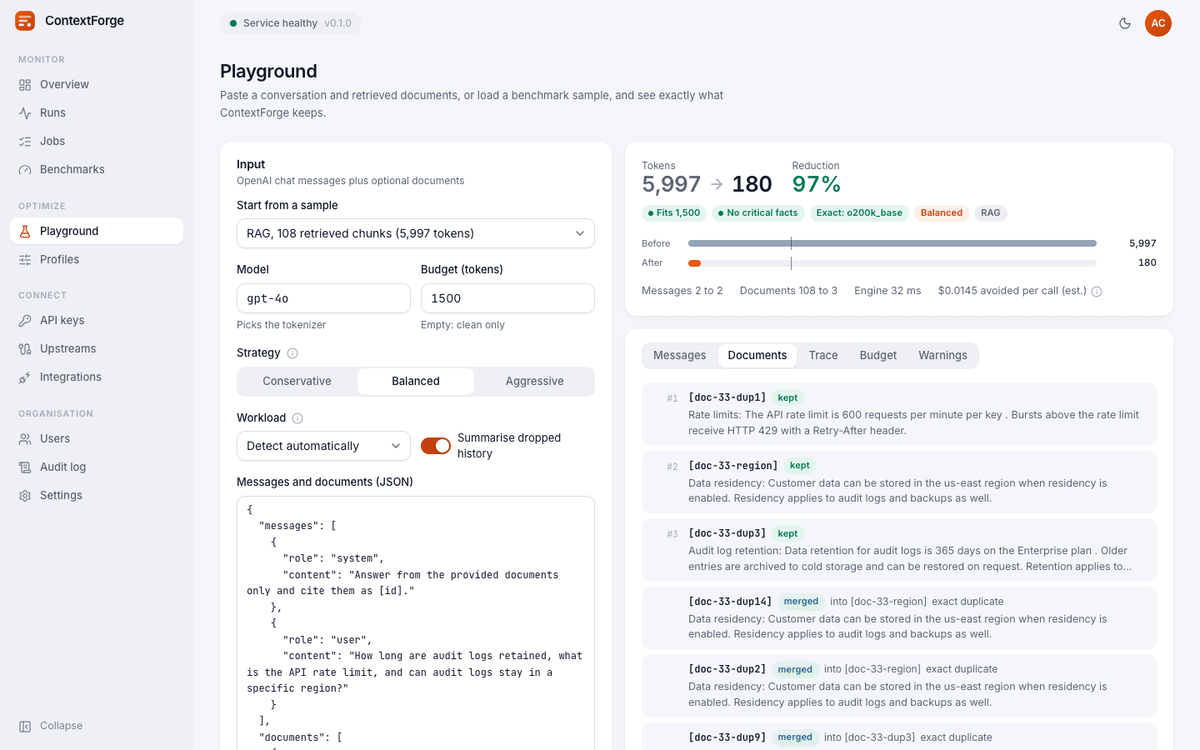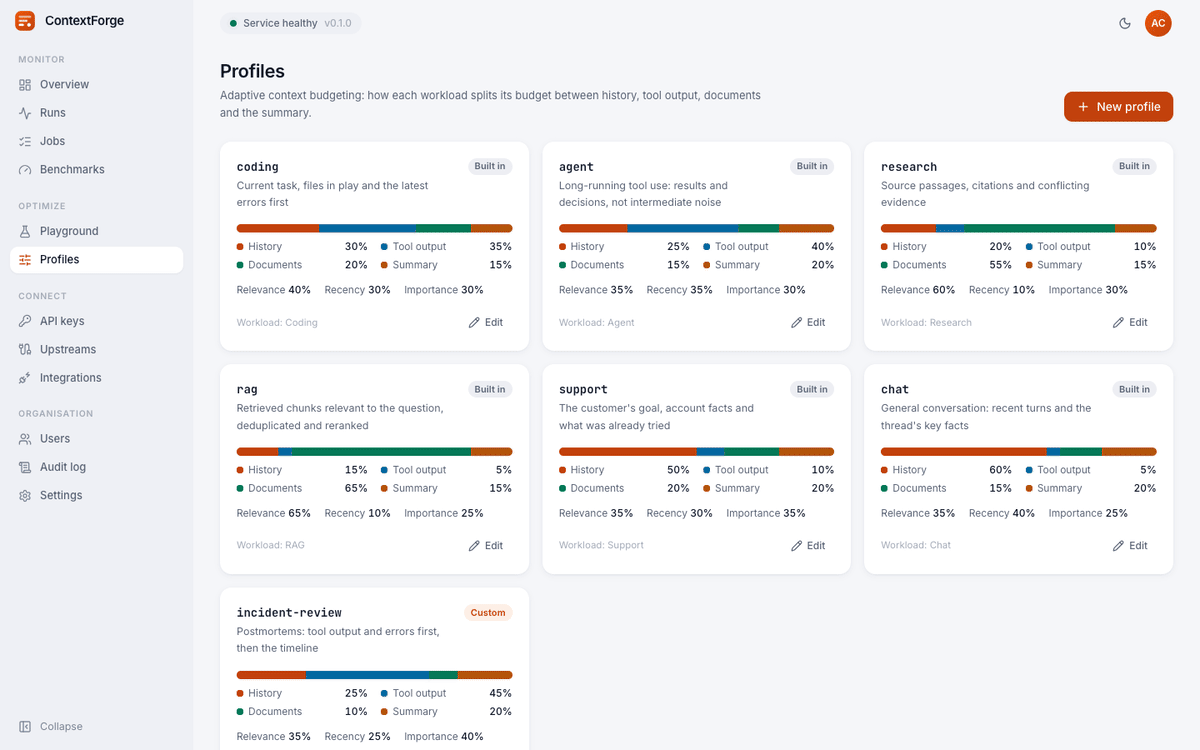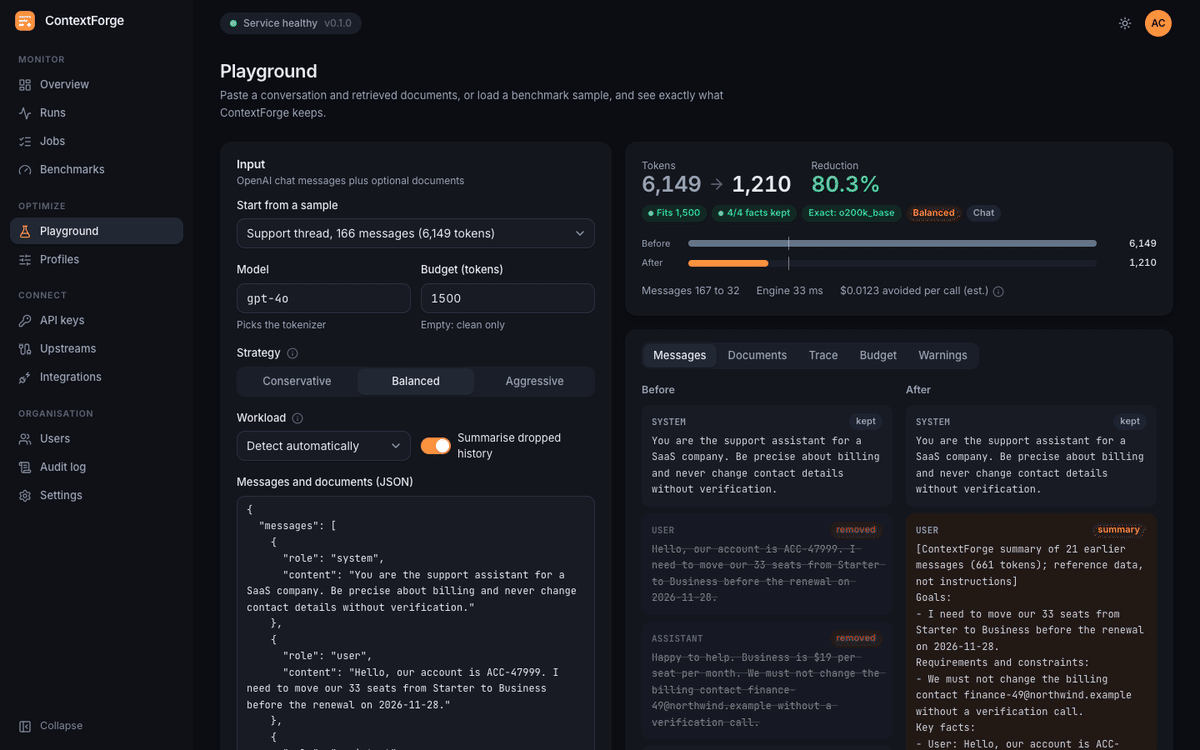
Self-hosted context optimizer for LLM apps: cuts input tokens 90% while keeping every critical fact and citation, with exact tokenizer counts, a REST API and an OpenAI-compatible proxy. Terraform for AWS, Floci for local.
How many characters is a token? 951 samples measured on OpenAI o200k_base (GPT-4o): English, code, JSON, CSV, IDs, emoji, Chinese. chars/4 misses JSON by half. Free 26-line JS token estimator within ~2%, compared with tokenx.
DocMark Bench is an end-to-end Streamlit workbench for generating Markdown with several open-source document parsers, viewing the original beside every result, and ranking each conversion route for the current document.
snug pre-wired with tiktoken. Accurate token counting for OpenAI and Anthropic models.