CrisperWhisper
Controllable Transcription. Verbatim ( every, filler, pause, stutter, vocal sound) , or intended ( what the speaker meant to say, optimized for readability) with word-level timestamps.
- 1.5k
- Python
- 10 d ago
Controllable Transcription. Verbatim ( every, filler, pause, stutter, vocal sound) , or intended ( what the speaker meant to say, optimized for readability) with word-level timestamps.
HeadTTS: Free neural text-to-speech (Kokoro) with timestamps and visemes for lip-sync. Runs in-browser (WebGPU/WASM) or on local Node.js WebSocket/REST server (WebGPU/CPU).
AI agent skill: tell Claude Code, Codex, Gemini or OpenClaw to upload your recording to YouTube — it downloads from Drive, transcribes, generates timestamps and metadata automatically.
git rebase but for time. Easily randomize, sequence, and shift your commit dates.
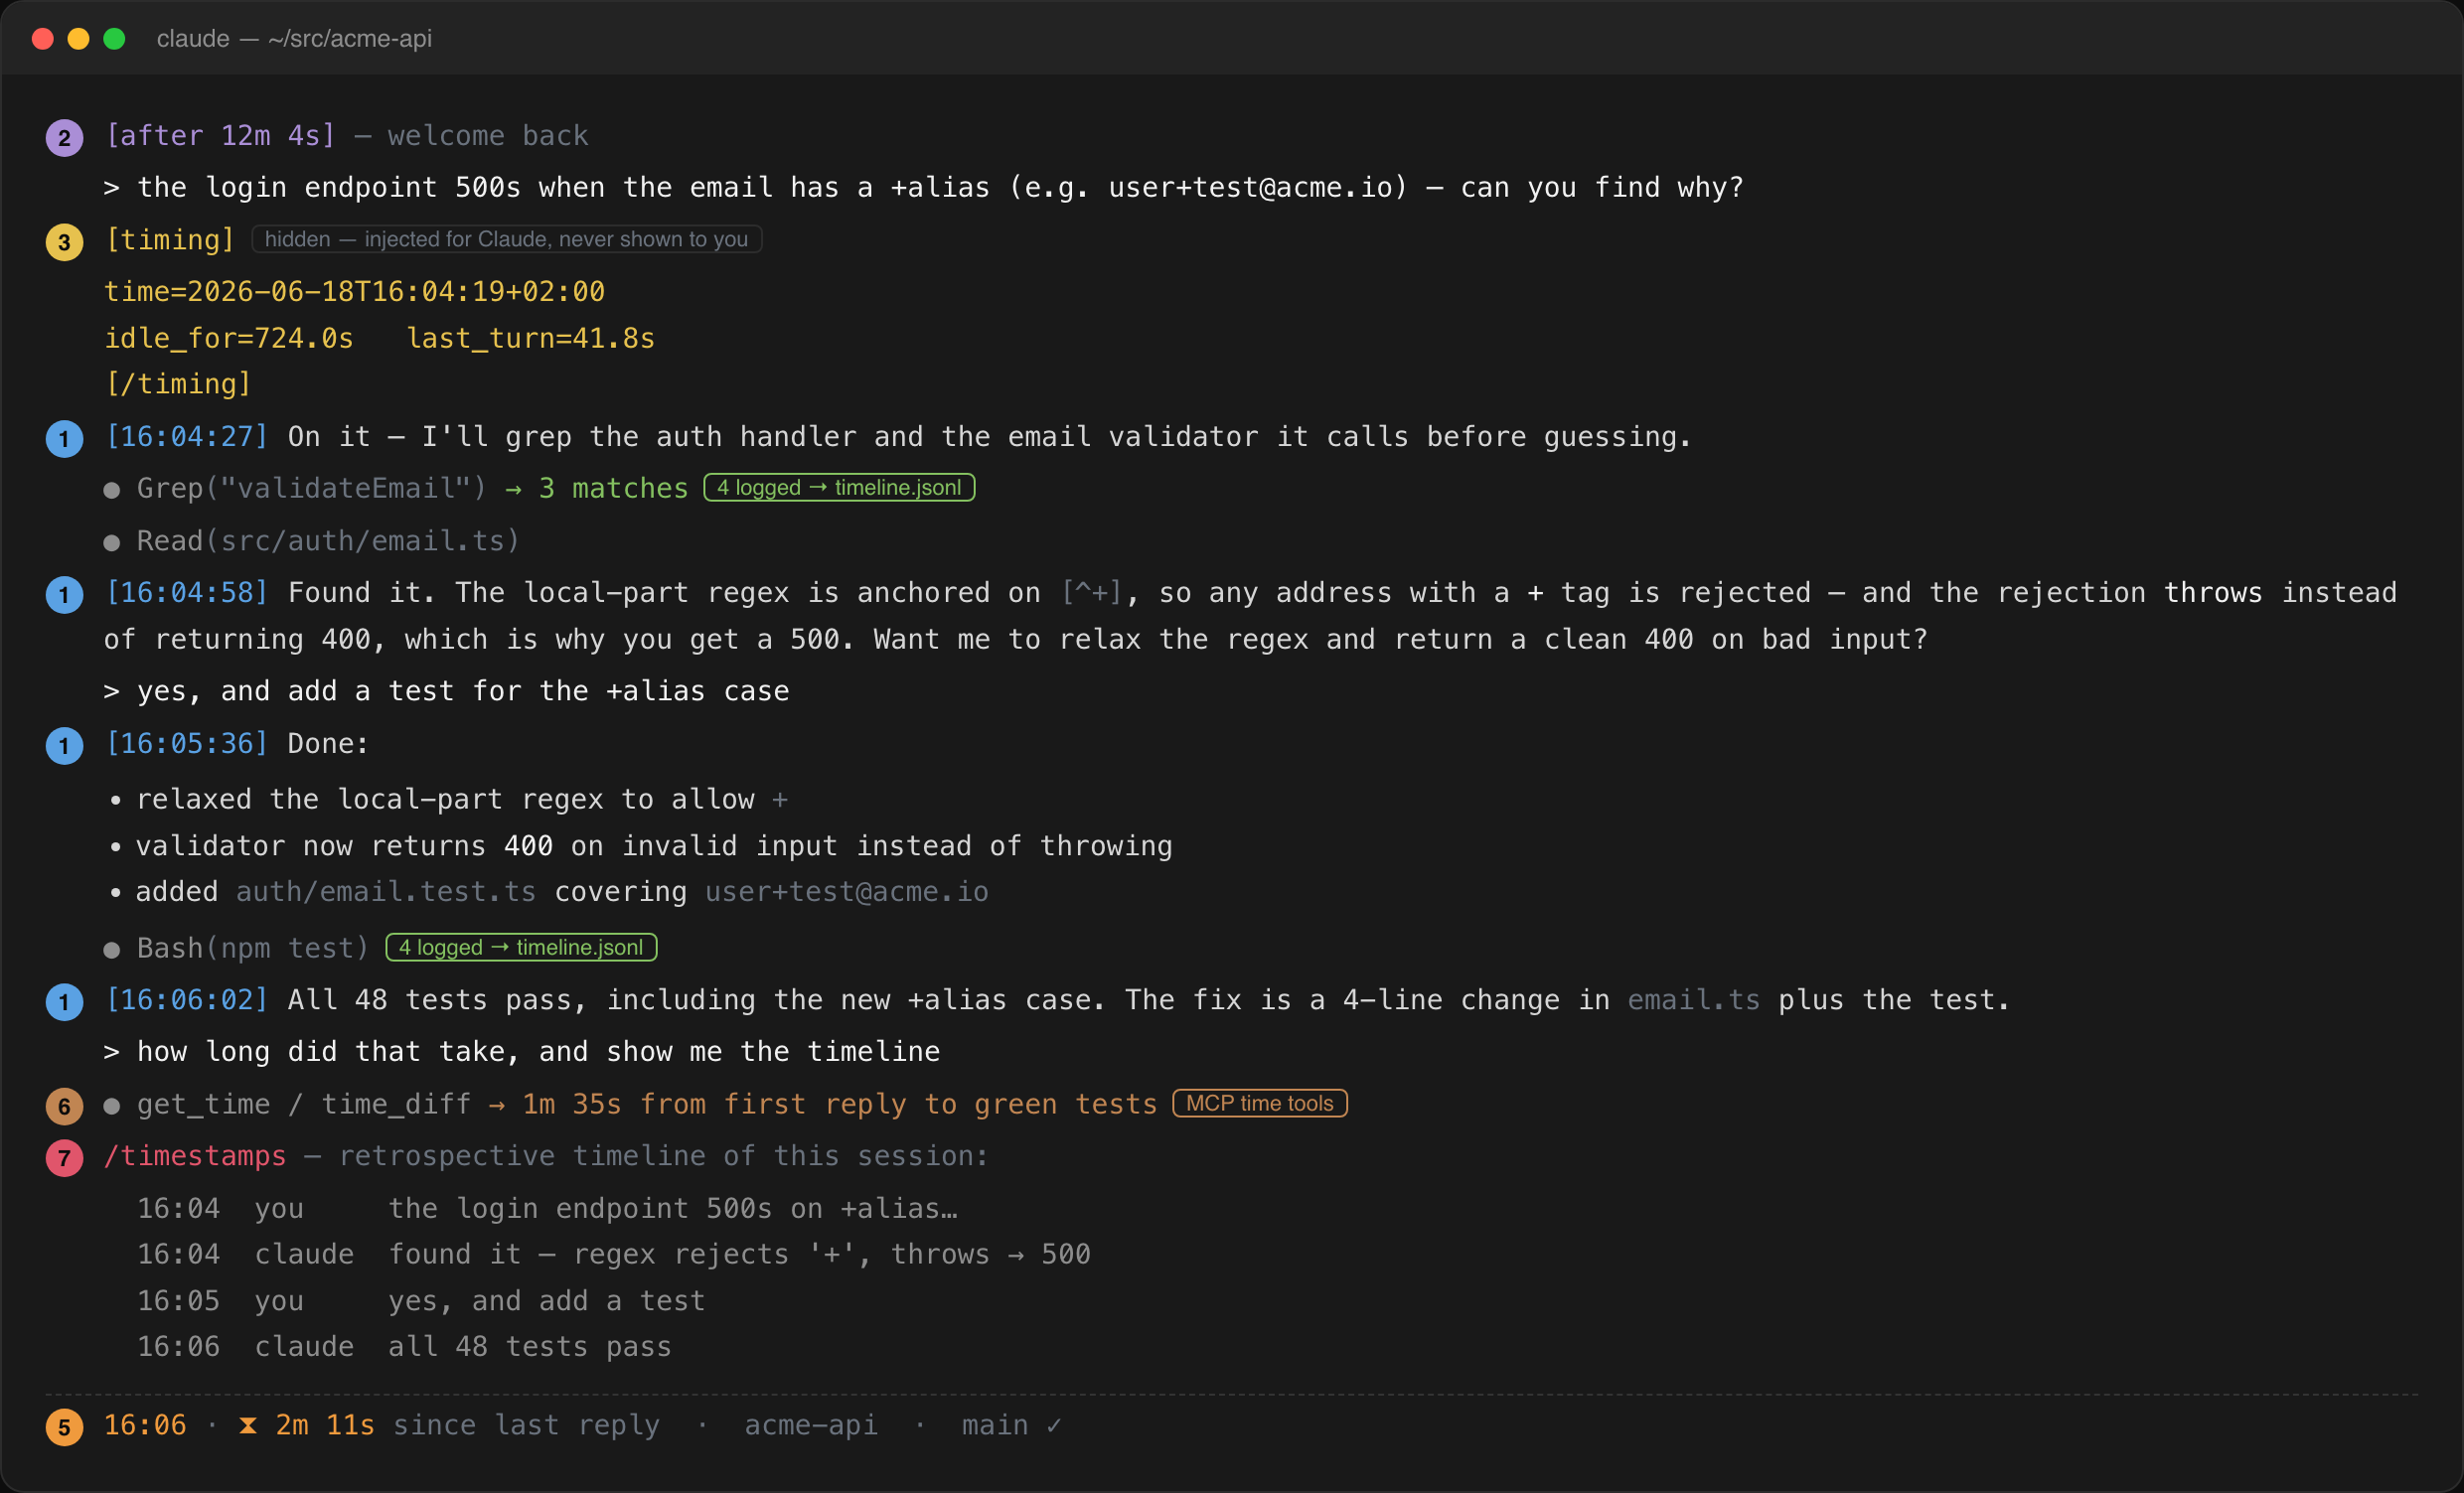
Time awareness for Claude Code — visible per-message timestamps, hidden timing context, MCP time tools, /timestamps timeline, statusline clock. Merges three community plugins into one toggleable whole.
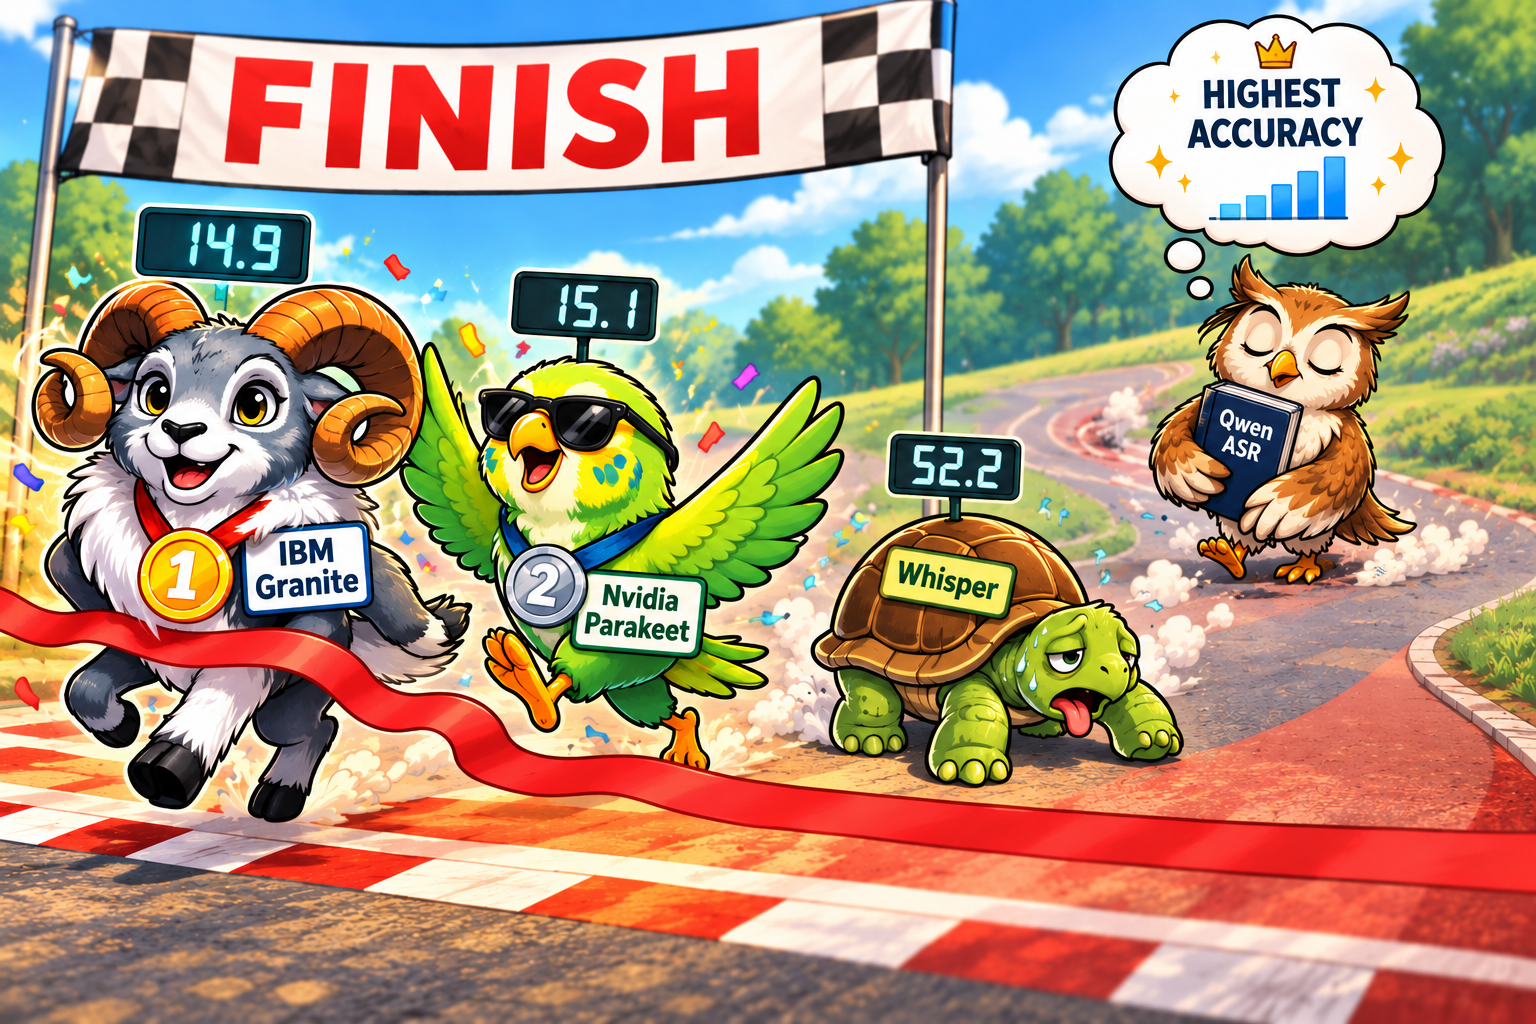
Extremely fast and accurate audio transcriber surpassing Whisper. Fast on GPU or CPU.
Automatic speech recognition model, used with ggml.
Correct timestamps for images exported from Google Photos.