toon
🎒 Token-Oriented Object Notation (TOON) – compact, human-readable serialization of JSON data for LLM prompts. TypeScript SDK, CLI, benchmarks.
- 26k
- TypeScript
- MIT
- 8 d ago
🎒 Token-Oriented Object Notation (TOON) – compact, human-readable serialization of JSON data for LLM prompts. TypeScript SDK, CLI, benchmarks.
LunaSec - Dependency Security Scanner that automatically notifies you about vulnerabilities like Log4Shell or node-ipc in your Pull Requests and Builds. Protect yourself in 30 seconds with the LunaTrace GitHub App: https://github.com/marketplace/lunatrace-by-lunasec/
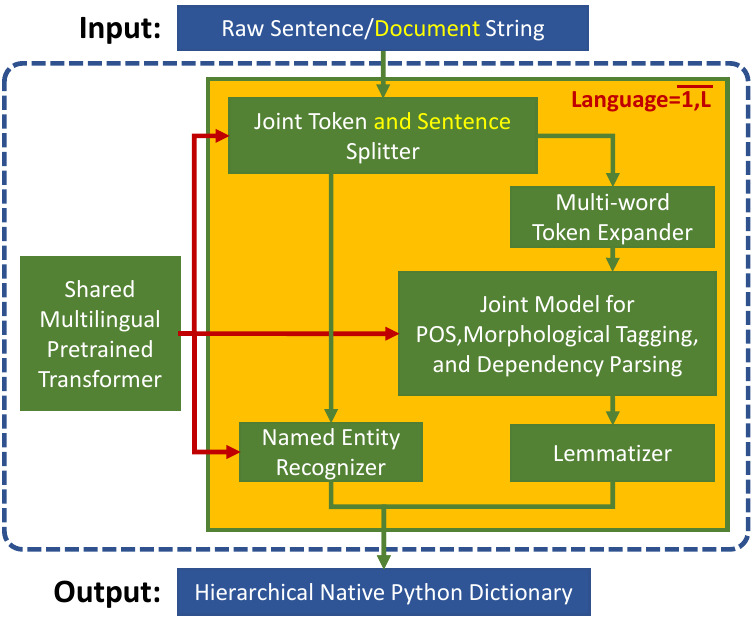
Trankit is a Light-Weight Transformer-based Python Toolkit for Multilingual Natural Language Processing
Natural Language Processing Pipeline - Sentence Splitting, Tokenization, Lemmatization, Part-of-speech Tagging and Dependency Parsing
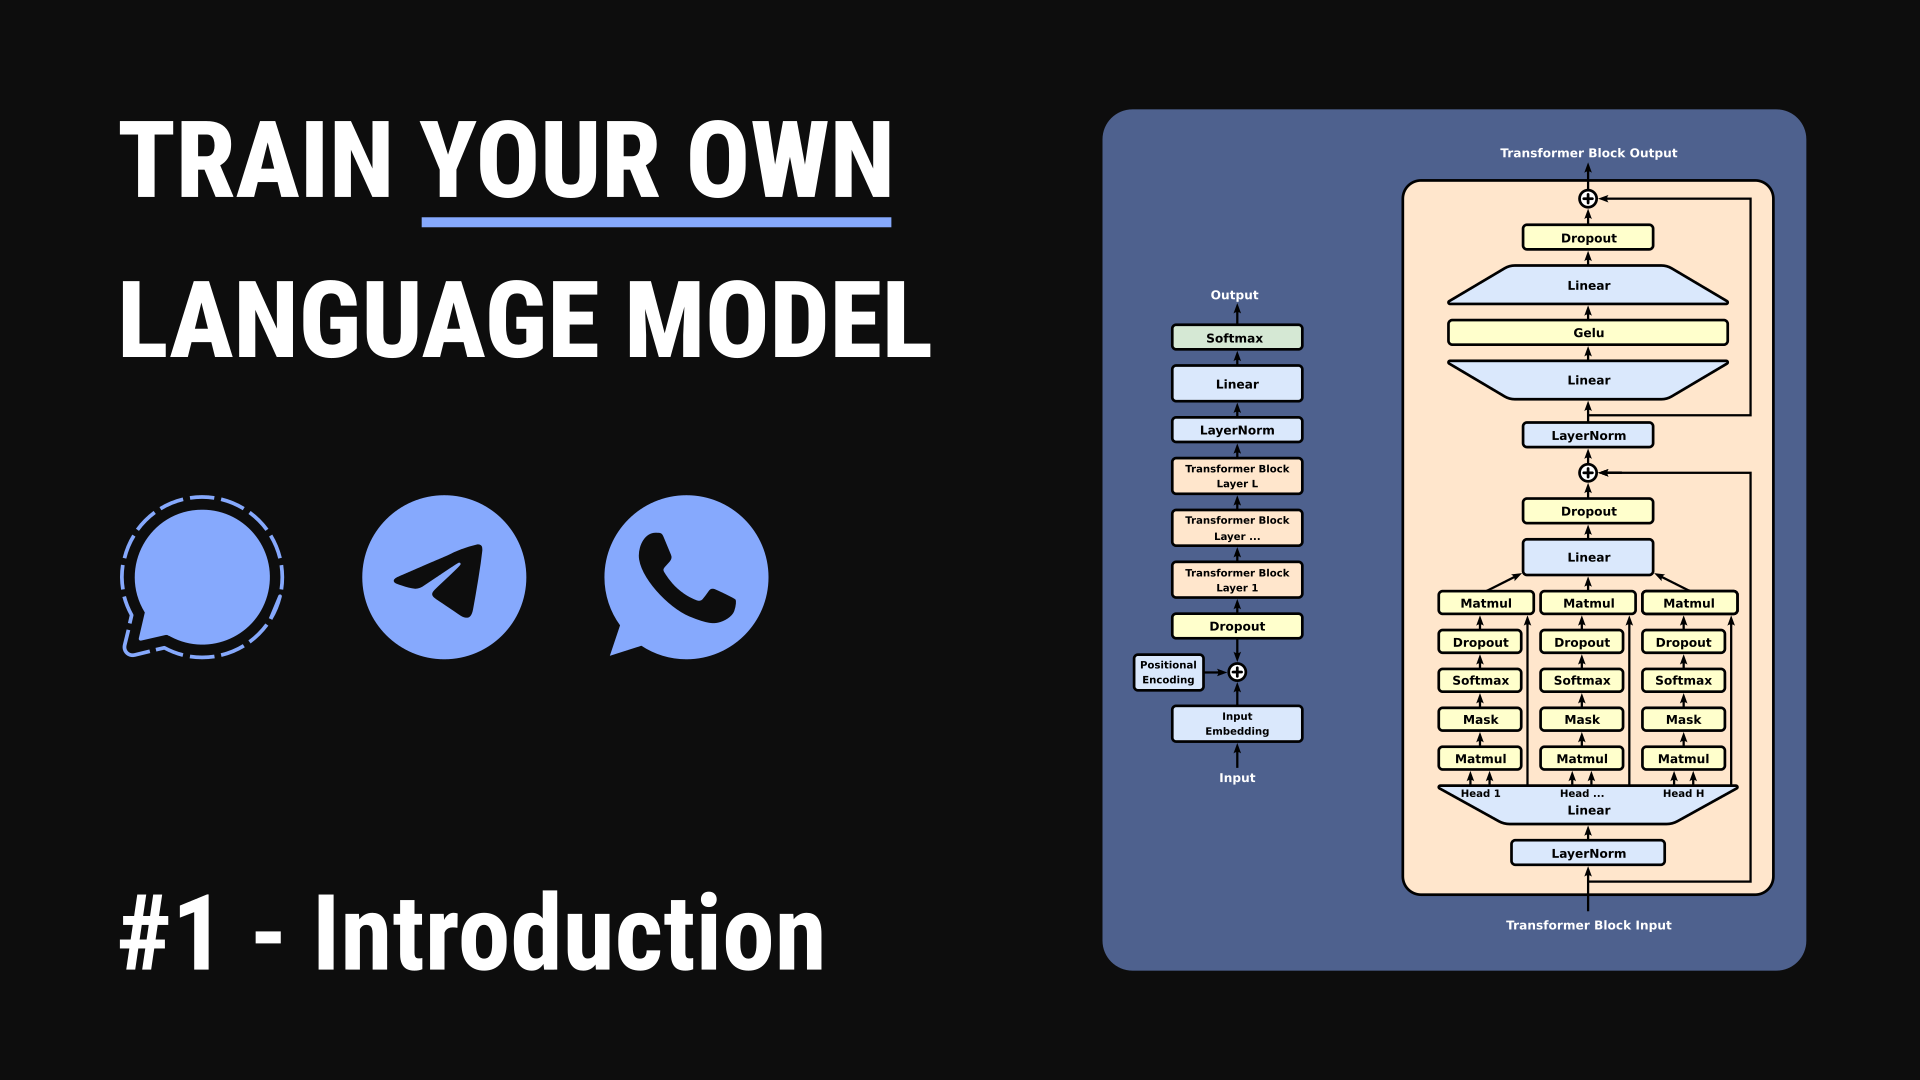
Train a language model to chat like you using your personal conversations from WhatsApp, Telegram, Signal, or other platforms.
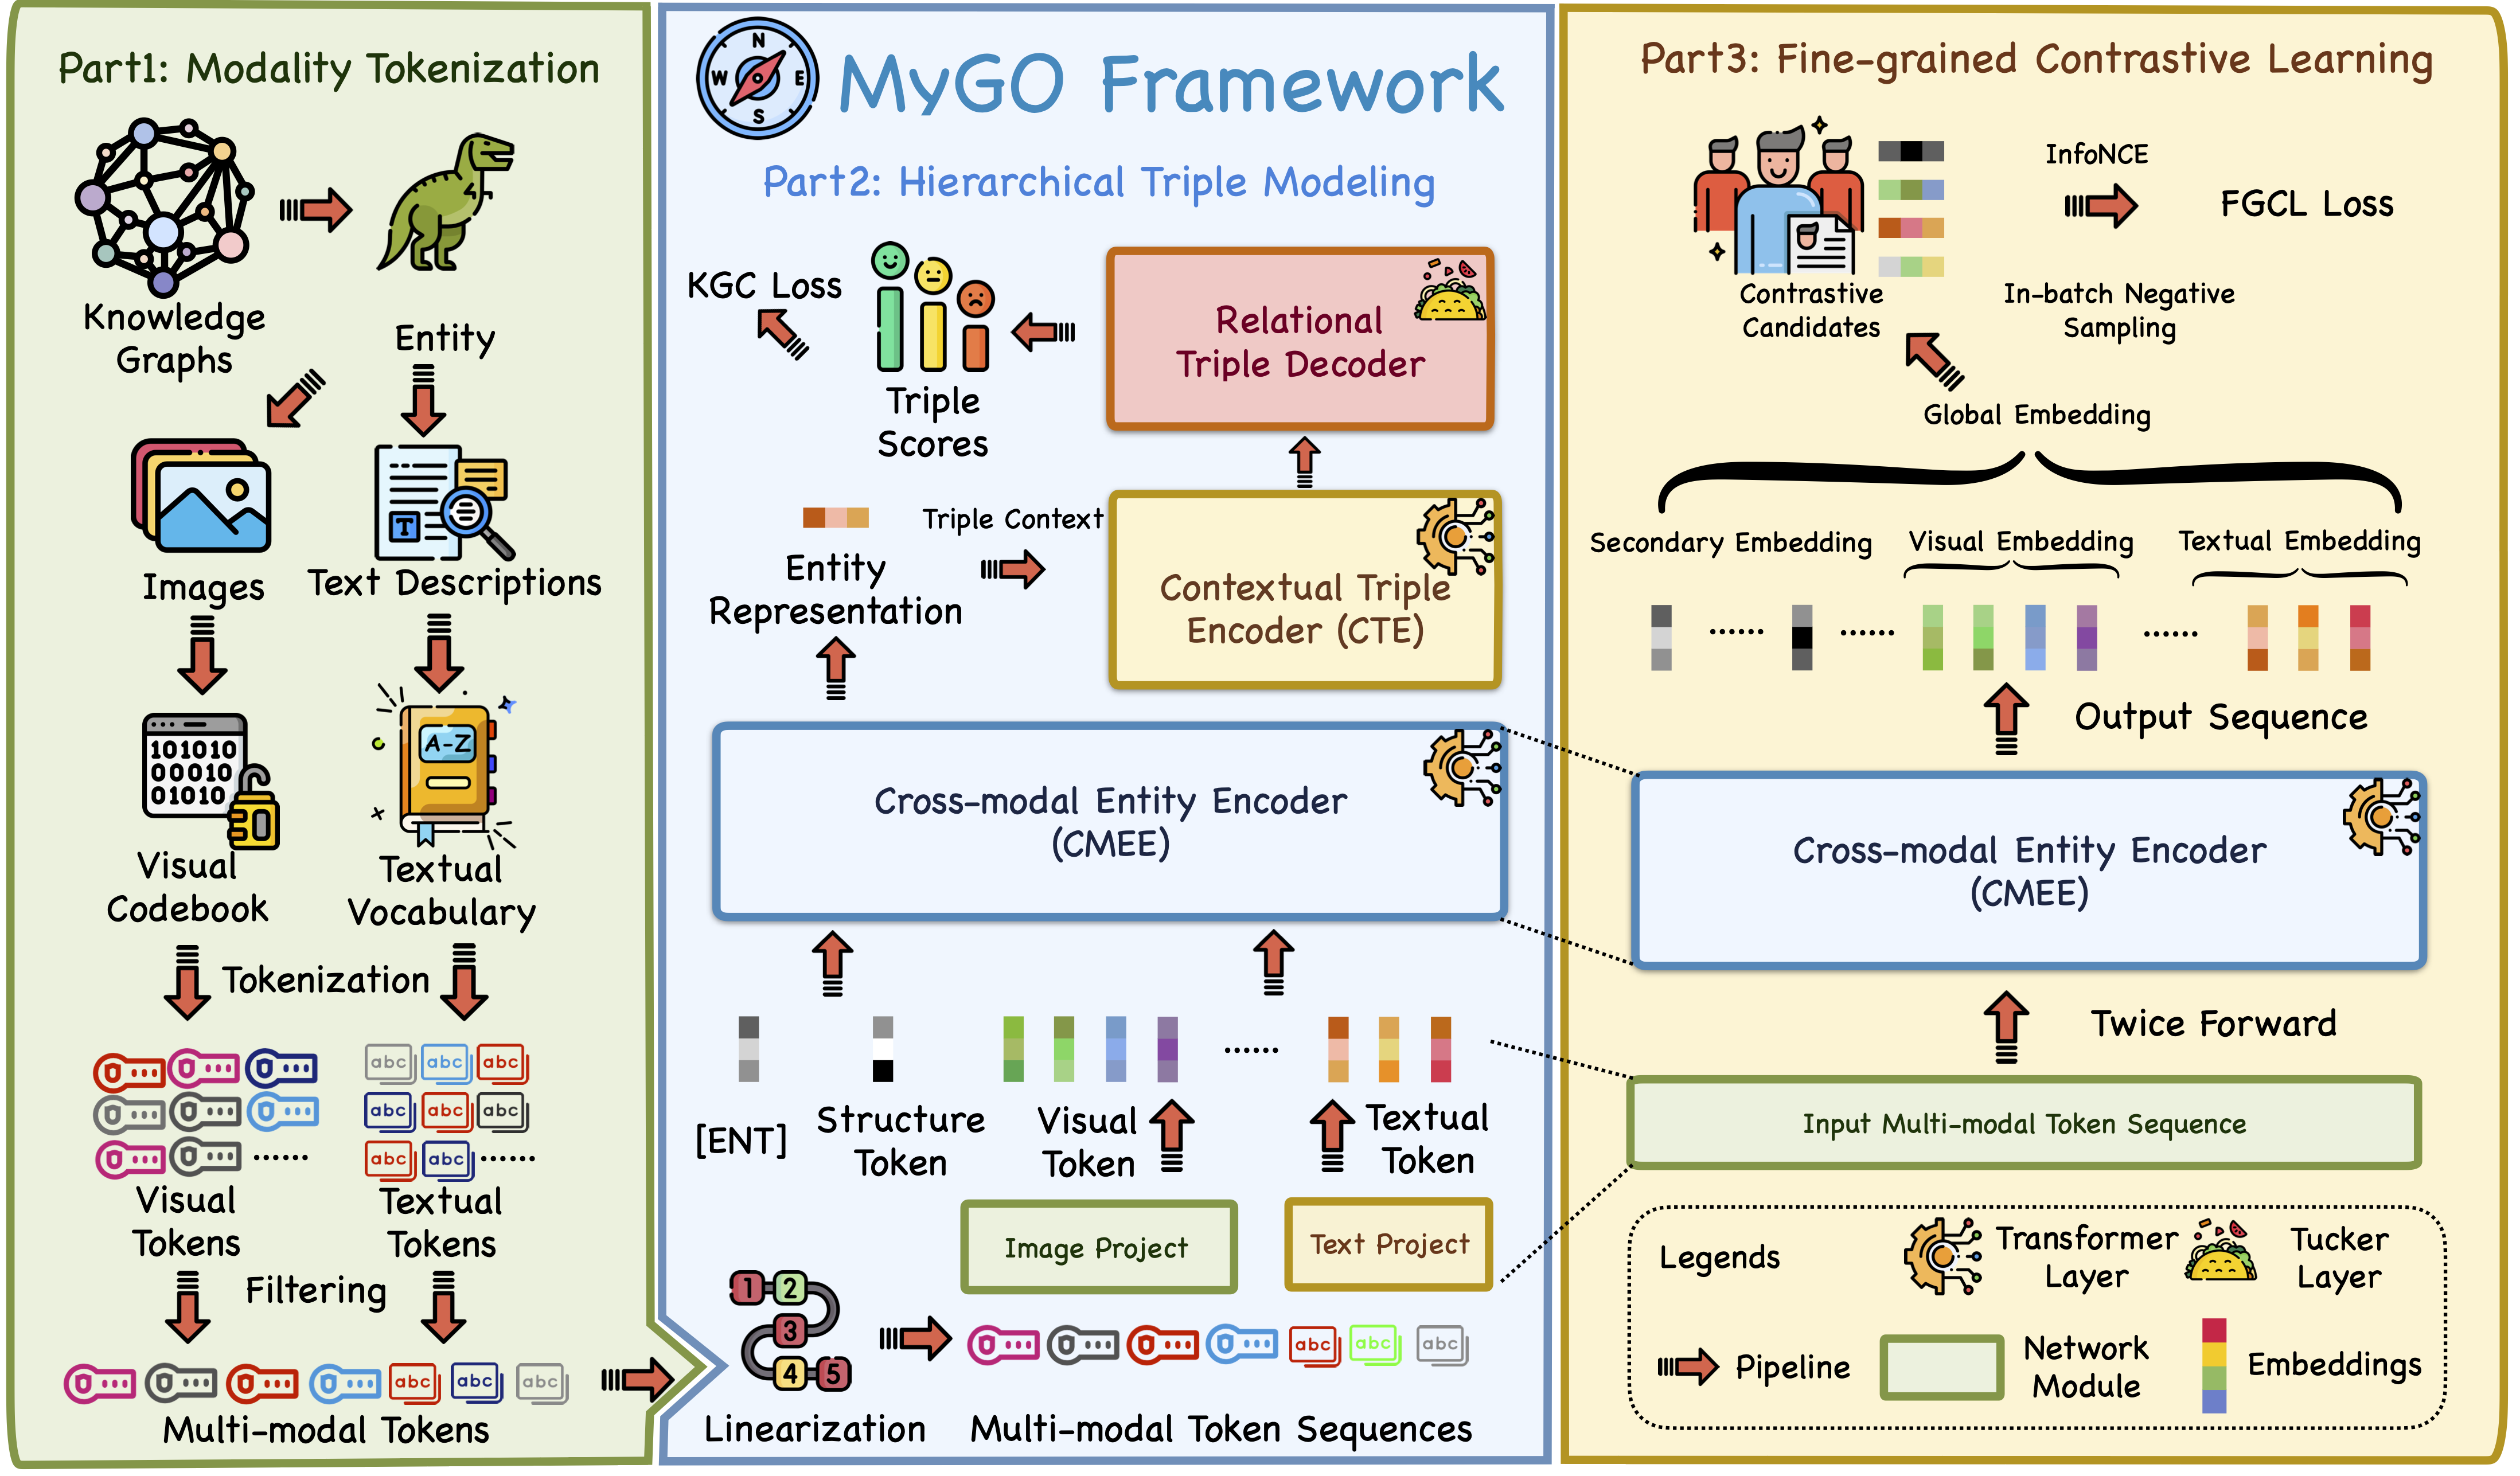
[Paper][AAAI 2025] (MyGO)Tokenization, Fusion, and Augmentation: Towards Fine-grained Multi-modal Entity Representation
NLP Cheat Sheet, Python, spacy, LexNPL, NLTK, tokenization, stemming, sentence detection, named entity recognition
Open-source platform for multi-agent AI orchestration, real-world asset tokenization, workflow automation. Includes OAuth 2.1 MCP agent management, a 44-field RWA schema, Stripe, designed to integrate with AetherNet QUAS & KVS sovereign, post quantum, architecture agnostic omni-substrate, semantic memory, & institutional settlement system.
Simple multilingual lemmatizer for Python, especially useful for speed and efficiency
This repository consists of a complete guide on natural language processing (NLP) in Python where we'll learn various techniques for implementing NLP including parsing & text processing and understand how to use NLP for text feature engineering.
klmbr - a prompt pre-processing technique to break through the barrier of entropy while generating text with LLMs
This Repository Contains Solution to the Assignments of the Natural Language Processing Specialization from Deeplearning.ai on Coursera Taught by Younes Bensouda Mourri, Łukasz Kaiser, Eddy Shyu
Implementation of the dynamic chunking mechanism in H-net by Hwang et al. of Carnegie Mellon
a unix-like du command line tool to count token usage per files and directories
Use Python and NLTK to build out your own text classifiers and solve common NLP problems
A juicy token compression algorithm. Compress upto 95% of tokens without any loss. Free & Opensource
Open-source context engineering for AI coding: context budget, Claude Code, GitHub Copilot and Codex usage in tokens or API-equivalent cost, tab relevance, current model pricing, code maps, and workspace security.
Minimal, clean code for video/image "patchnization" - a process commonly used in tokenizing visual data for use in a Transformer encoder.
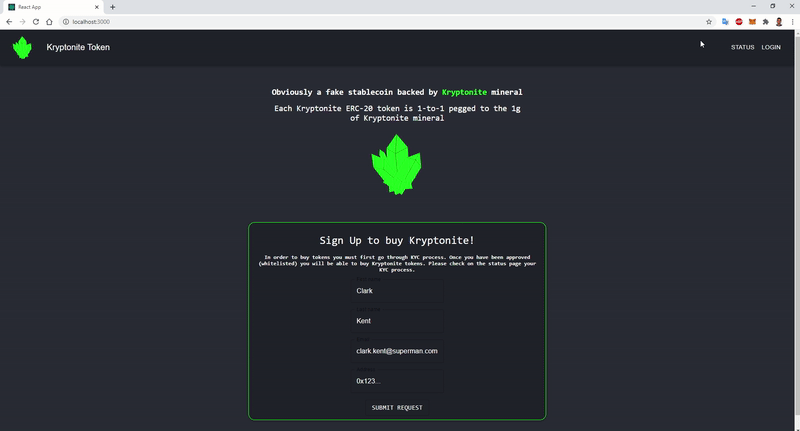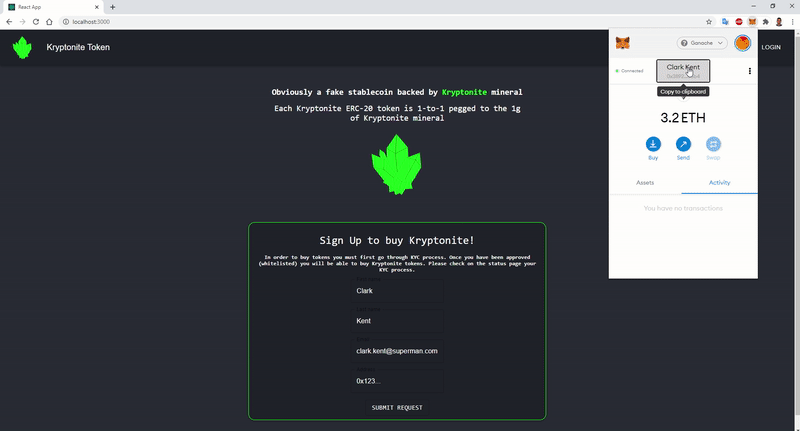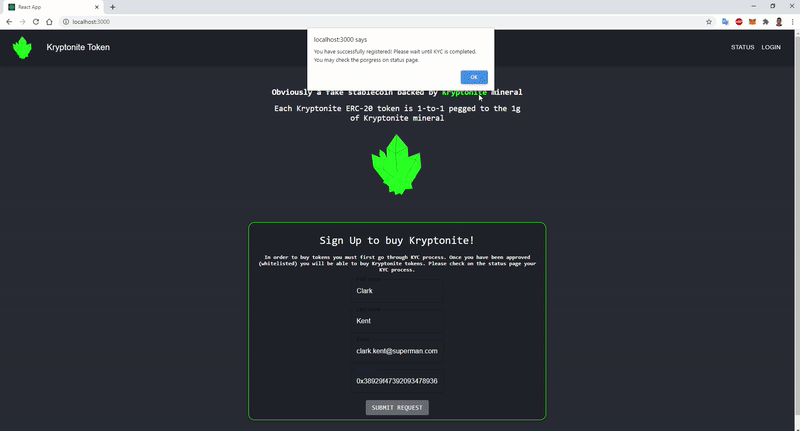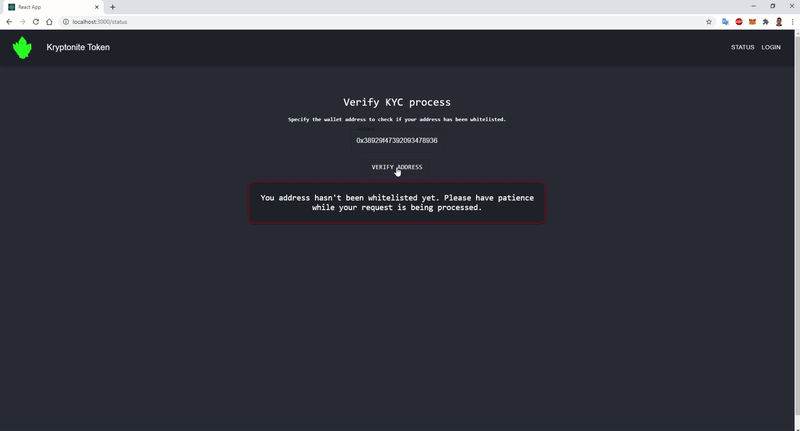
Crowdsale Dapp for ERC-20 Kryptonite token (fake stablecoin backed by Kryptonite mineral).
Gán nhãn từ loại Tiếng Việt sử dụng mô hình Hidden Markov kết hợp thuật toán Viterbi
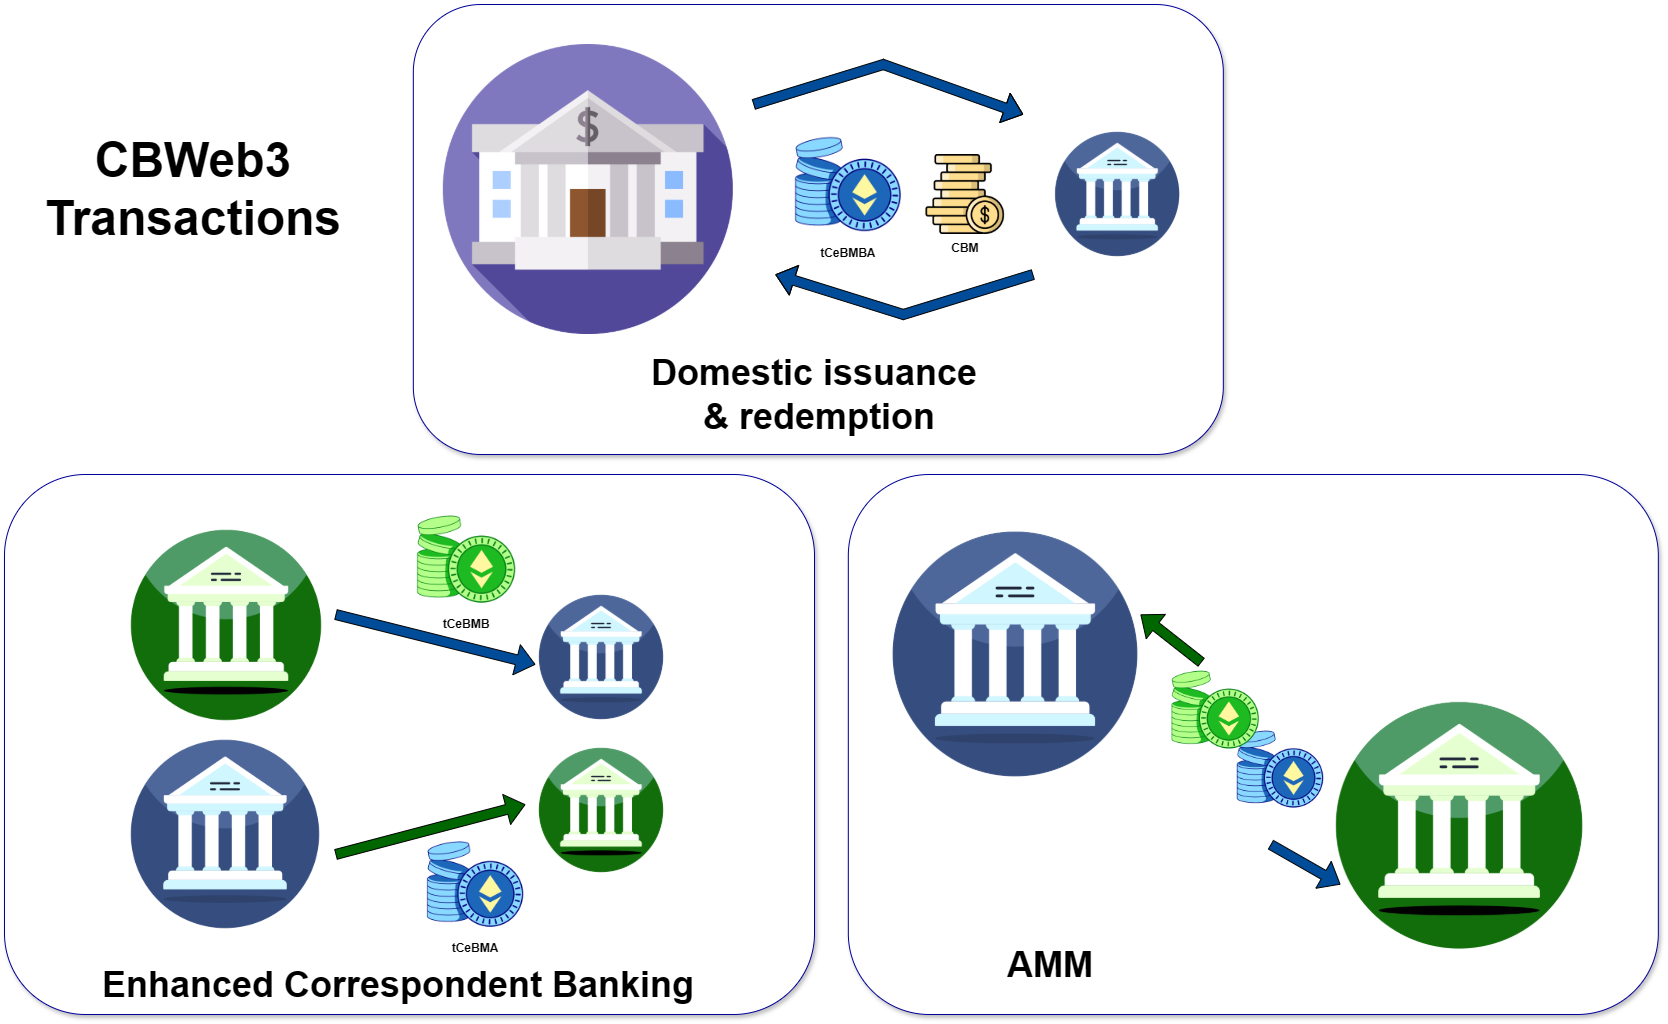
CBWeb3 — cross-border payments with CBDC settlement (PvP/HTLC and AMM scenarios). An LF Decentralized Trust lab.
Build intelligent applications that can interpret the human language to deliver impactful results
This Chatbot completed with combination of Deep Learning, Natural Language Toolkit(NLTK), PyTorch mode. And highest accuracy achieved here.