VoiceStudio
VoiceStudio is the open-source, fully-local ElevenLabs alternative — voice cloning, voice design, video dubbing, dictation, transcription & audiobook creation in 646 languages.
- 114k
- Python
- AGPL-3.0
- 21 h ago
VoiceStudio is the open-source, fully-local ElevenLabs alternative — voice cloning, voice design, video dubbing, dictation, transcription & audiobook creation in 646 languages.
Local UI to run and train LLMs and diffusion models. Supports GGUF, MLX, Qwen3.8, DeepSeek-V4.1, MiniMax-H3, Gemma 4, FLUX and more.
1 min voice data can also be used to train a good TTS model! (few shot voice cloning)
Clone a voice in 5 seconds to generate arbitrary speech in real-time
LocalAI is the open-source AI engine. Run any model - LLMs, vision, voice, image, video - on any hardware. No GPU required.
🐸💬 - a deep learning toolkit for Text-to-Speech, battle-tested in research and production
VoxCPM2: Tokenizer-Free TTS for Multilingual Speech Generation, Creative Voice Design, and True-to-Life Cloning
Readest is a modern, feature-rich ebook reader designed for avid readers offering seamless cross-platform access, powerful tools, and an intuitive interface to elevate your reading experience.
Mastra is the modern TypeScript framework for AI-powered applications and agents.
An Industrial-Level Controllable and Efficient Zero-Shot Text-To-Speech System
Multi-lingual large voice generation model, providing inference, training and deployment full-stack ability.
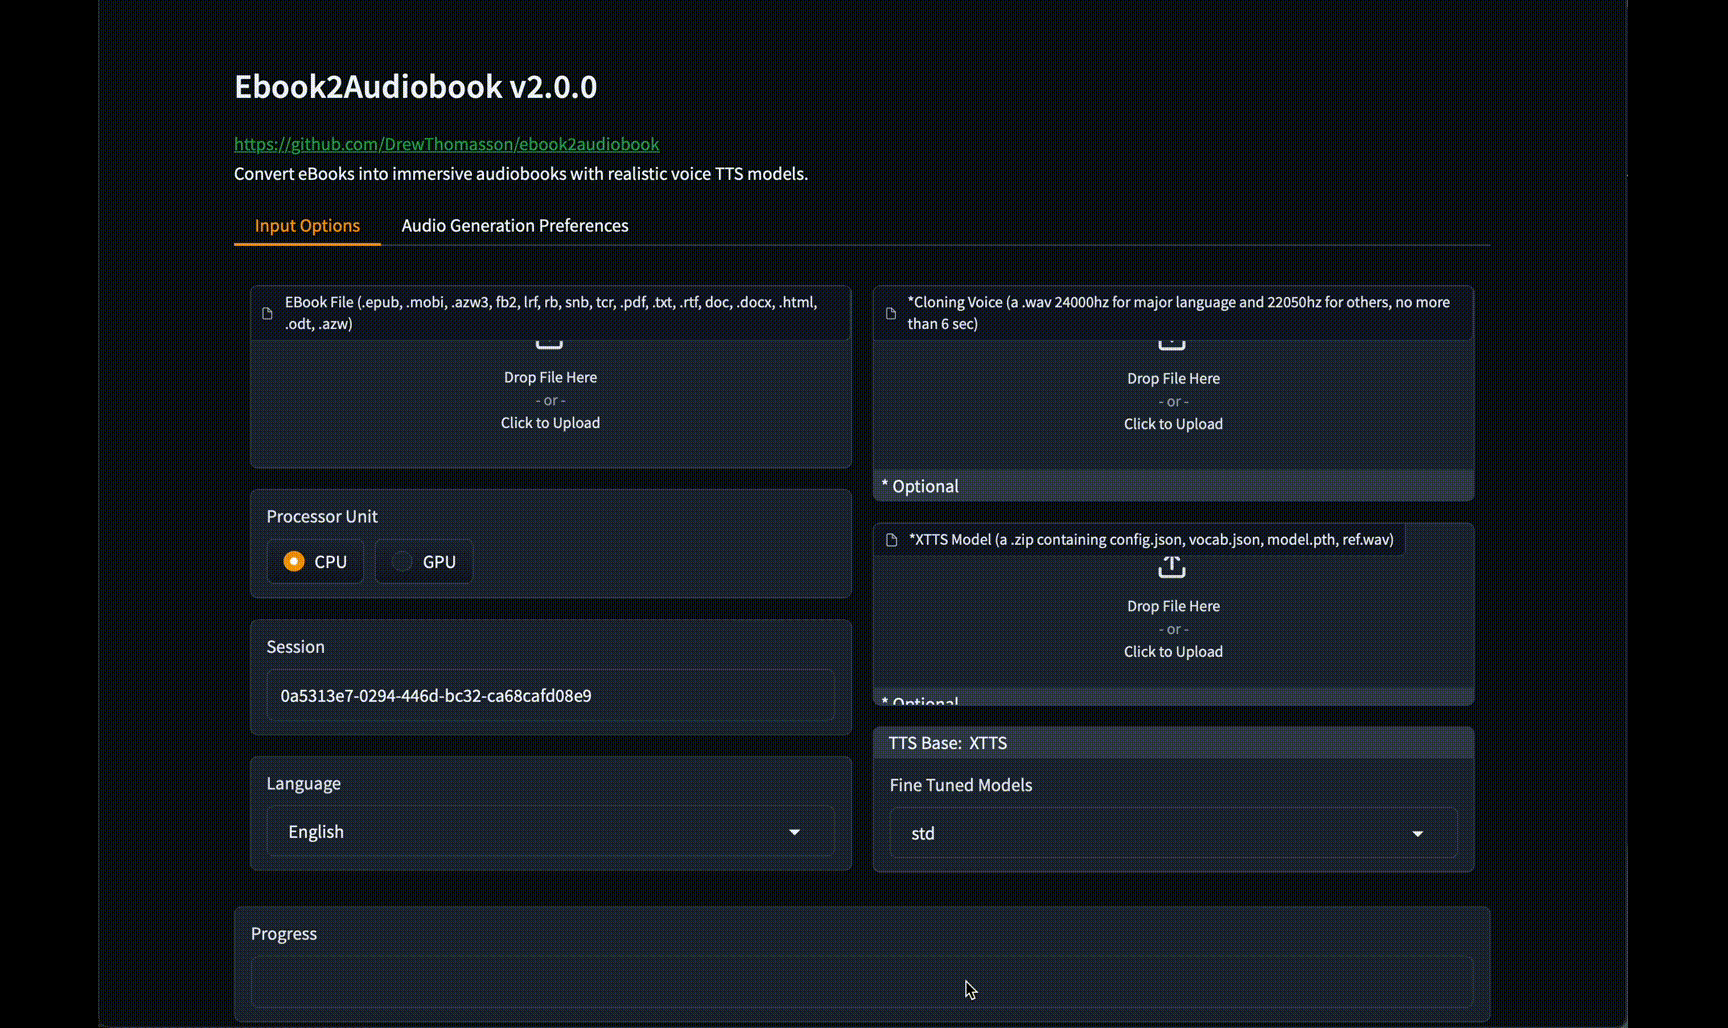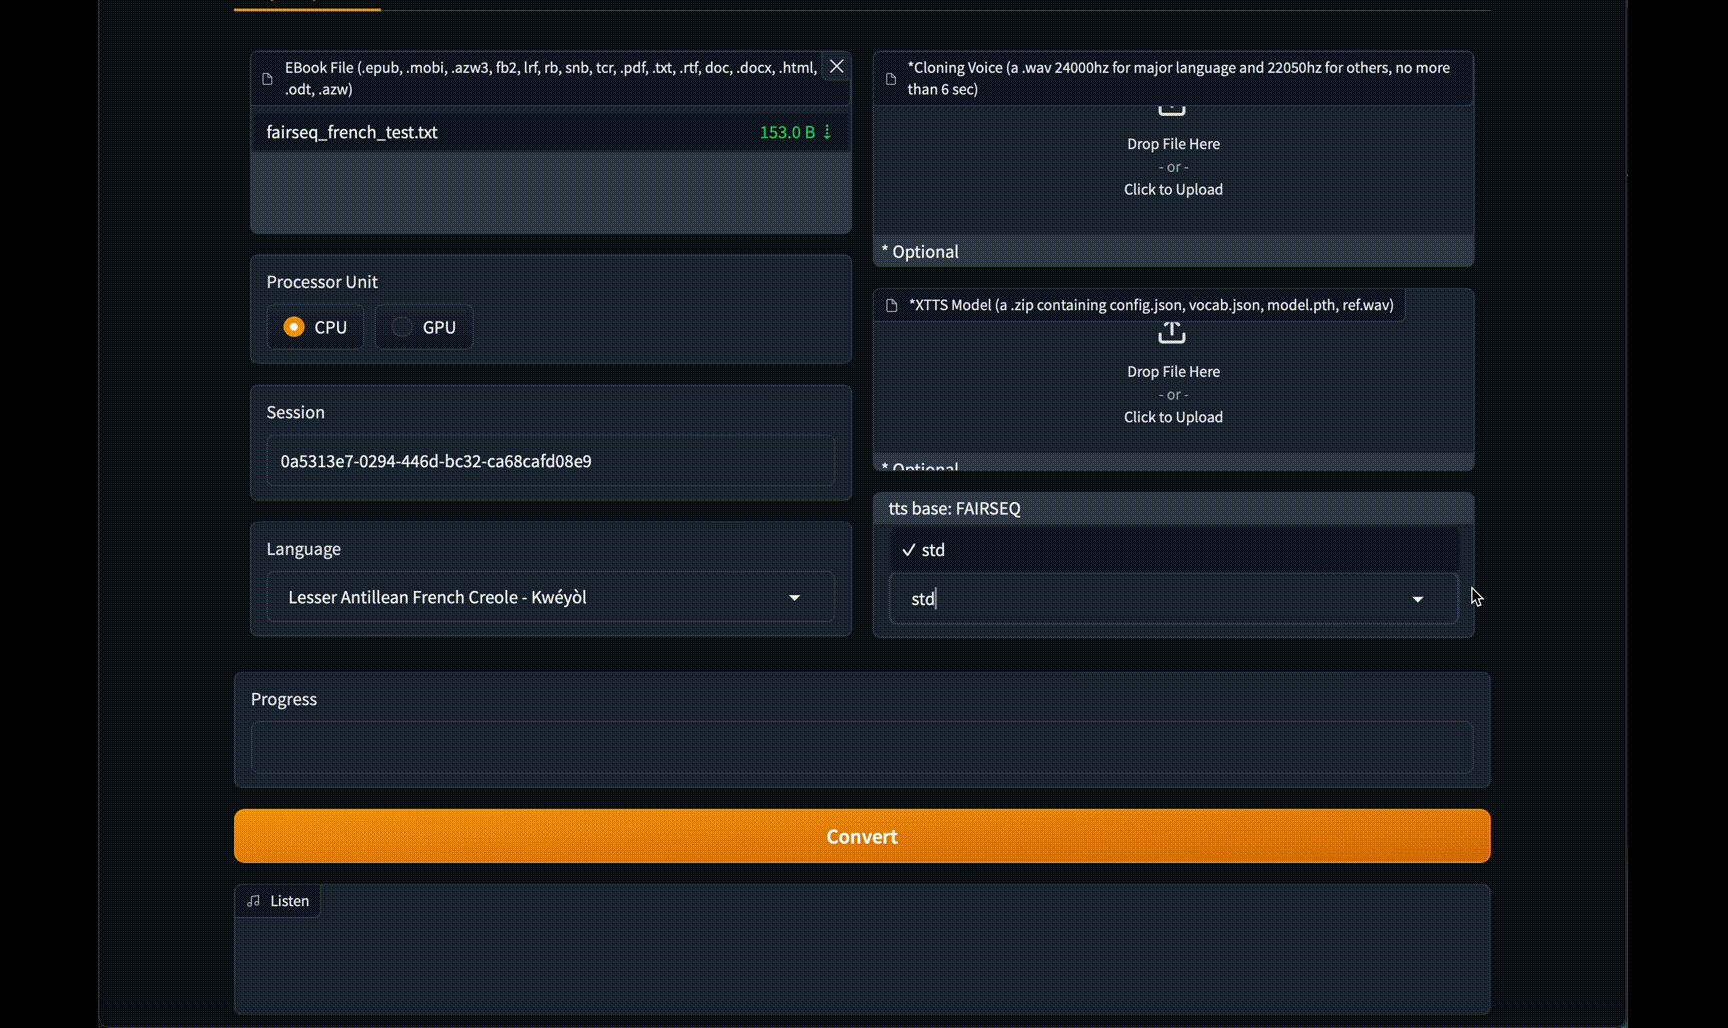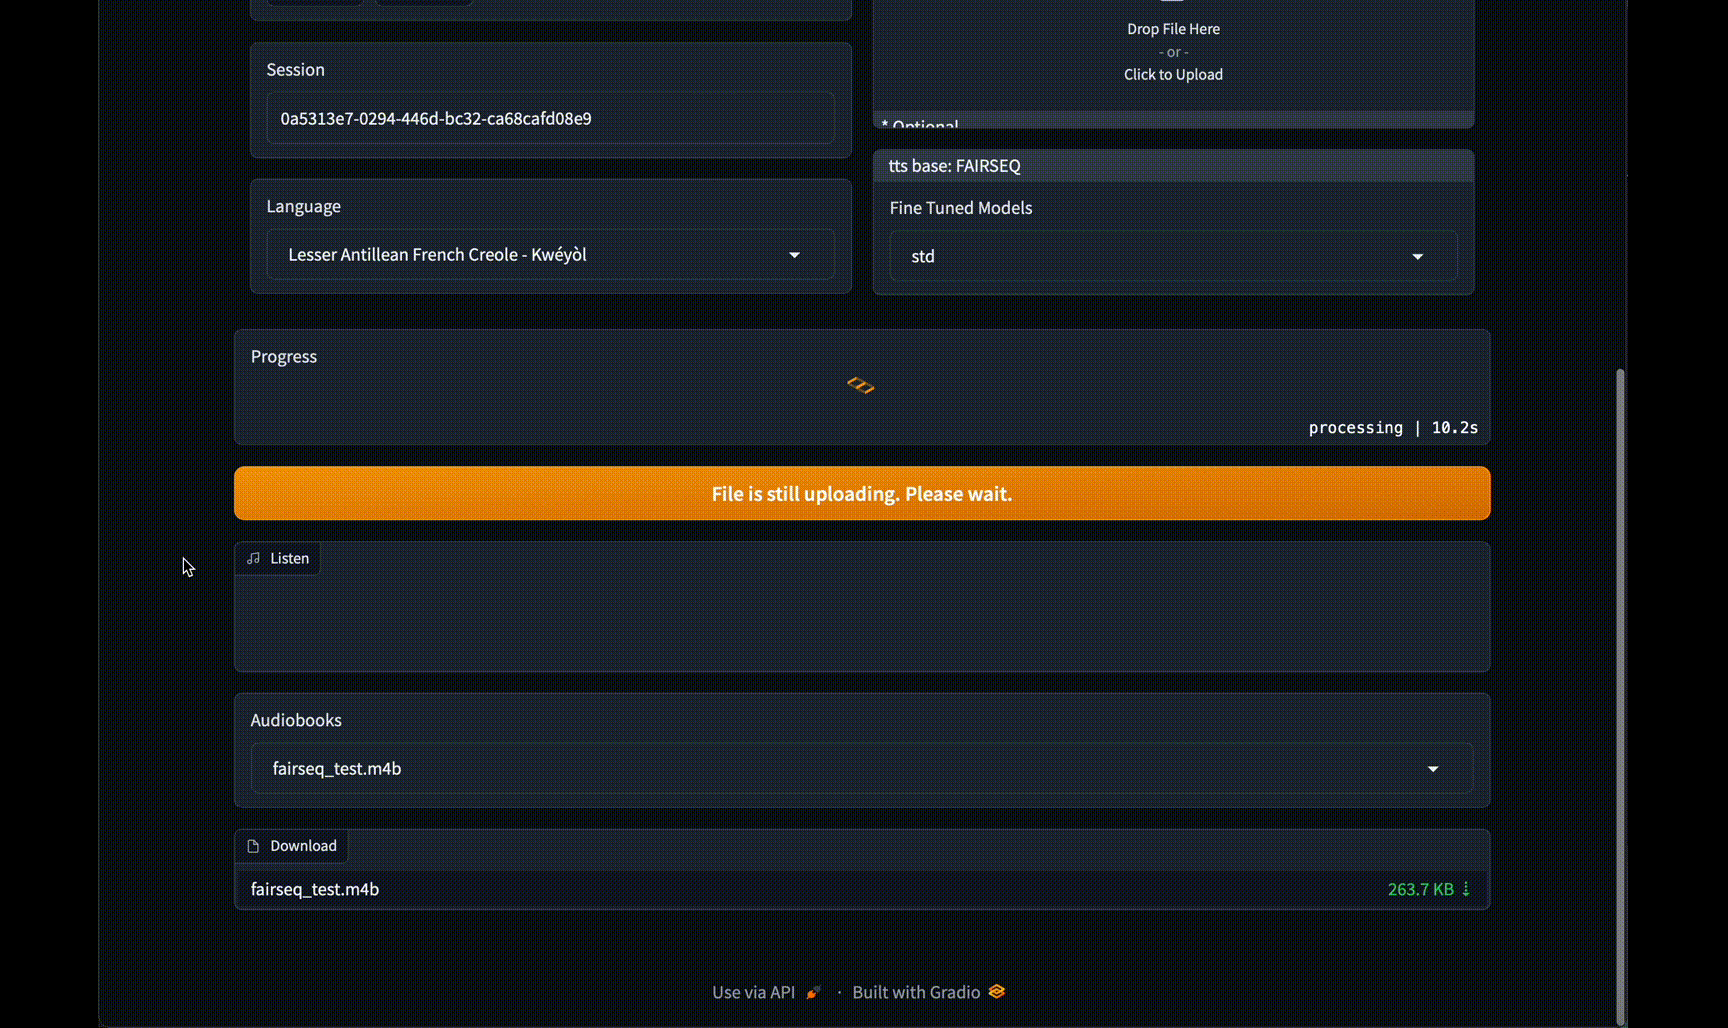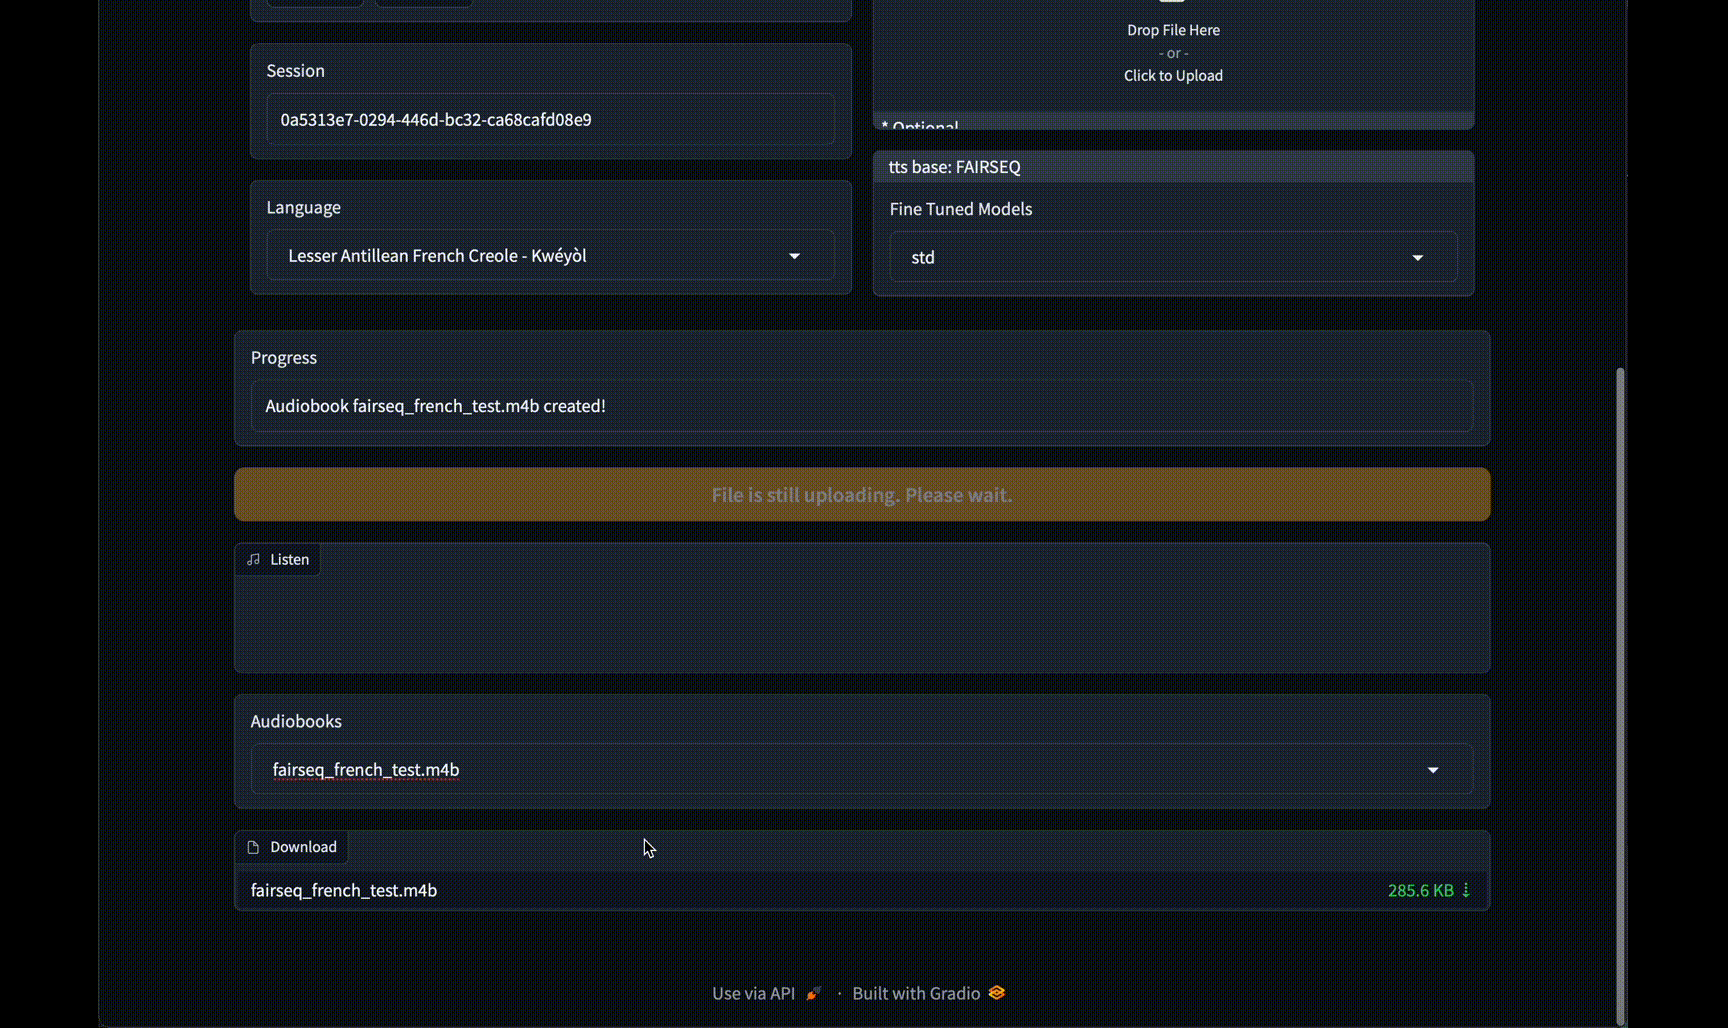
Generate audiobooks from e-books, 50+ TTS engines with voice cloning and 1696 languages!
Translate the video from one language to another and embed dubbing & subtitles.
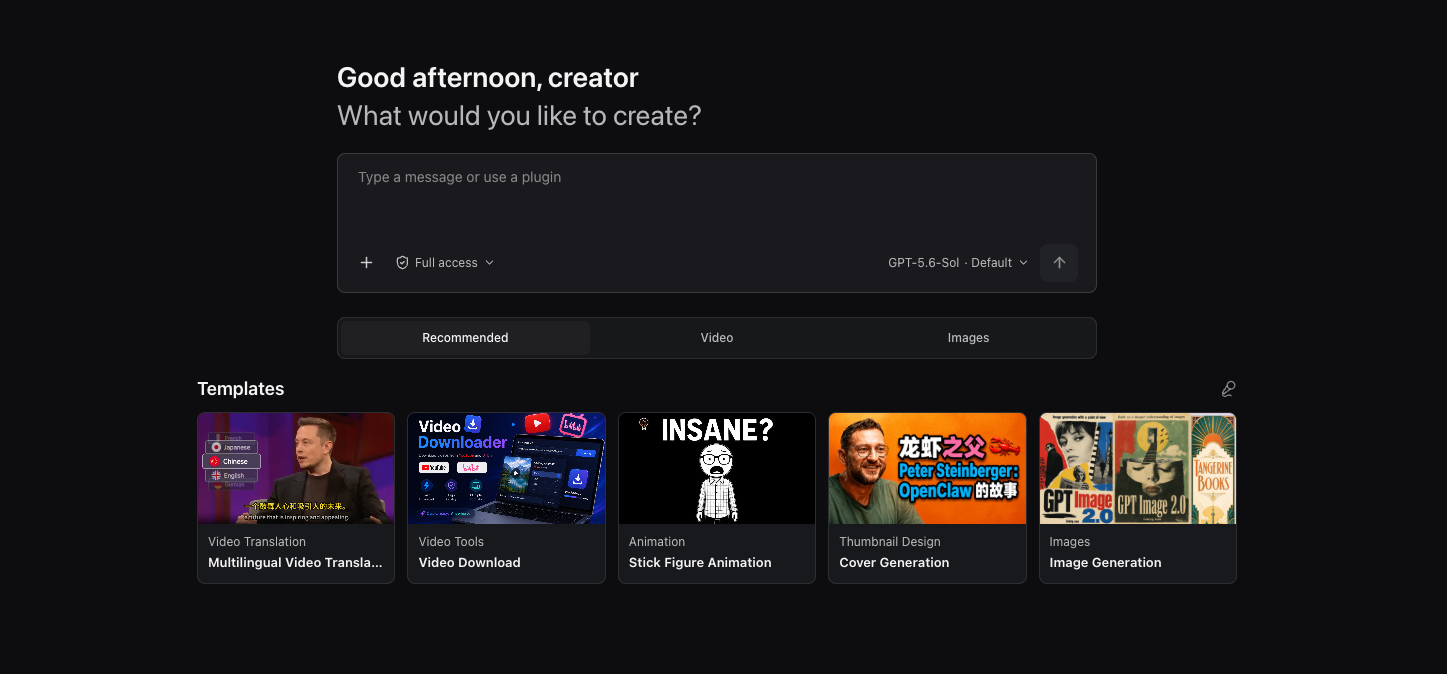
Formerly KrillinAI, VideoTranslation and Dubbing Tool for 120+ Languages. Open-source AI workspace for creators, powered by Codex. Video downloader, video translation, create videos, images, audios, and edits with Agents in one place. For your Social Media like YouTube, TikTok, Instagram, etc.
A scalable generative AI framework built for researchers and developers working on Large Language Models, Multimodal, and Speech AI (Automatic Speech Recognition and Text-to-Speech)
Gradio WebUI for creators and developers, featuring key TTS (Edge-TTS, kokoro) and zero-shot Voice Cloning (E2 & F5-TTS, CosyVoice), with Whisper audio processing, YouTube download, Demucs vocal isolation, and multilingual translation.
Easy-to-use Speech Toolkit including Self-Supervised Learning model, SOTA/Streaming ASR with punctuation, Streaming TTS with text frontend, Speaker Verification System, End-to-End Speech Translation and Keyword Spotting. Won NAACL2022 Best Demo Award.
Use Microsoft Edge's online text-to-speech service from Python WITHOUT needing Microsoft Edge
Very low latency speech to text, intent recognition, and text to speech, for building voice agents and interfaces
AI Agent Engineering Platform built on an Open Source TypeScript AI Agent Framework
:robot: :speech_balloon: Deep learning for Text to Speech (Discussion forum: https://discourse.mozilla.org/c/tts)
Quickly build text, voice and video agents. Fast, Go based Agent backend with SDKs for every language. Sensible defaults for search, knowledge, skills, telephony, sandboxes, memory and persistence. Sovereign AI. Take control of your AI.
VITS: Conditional Variational Autoencoder with Adversarial Learning for End-to-End Text-to-Speech
A general-purpose AIGC video engine: script to finished film in one pipeline — dramas, ads, product videos, otome games, and more. | 通用 AIGC 视频引擎 —— 从剧本到成片一条流水线,漫剧、广告、电商、乙游皆可
一个简单的本地网页界面,使用ChatTTS将文字合成为语音,同时支持对外提供API接口。A simple native web interface that uses ChatTTS to synthesize text into speech, along with support for external API interfaces.
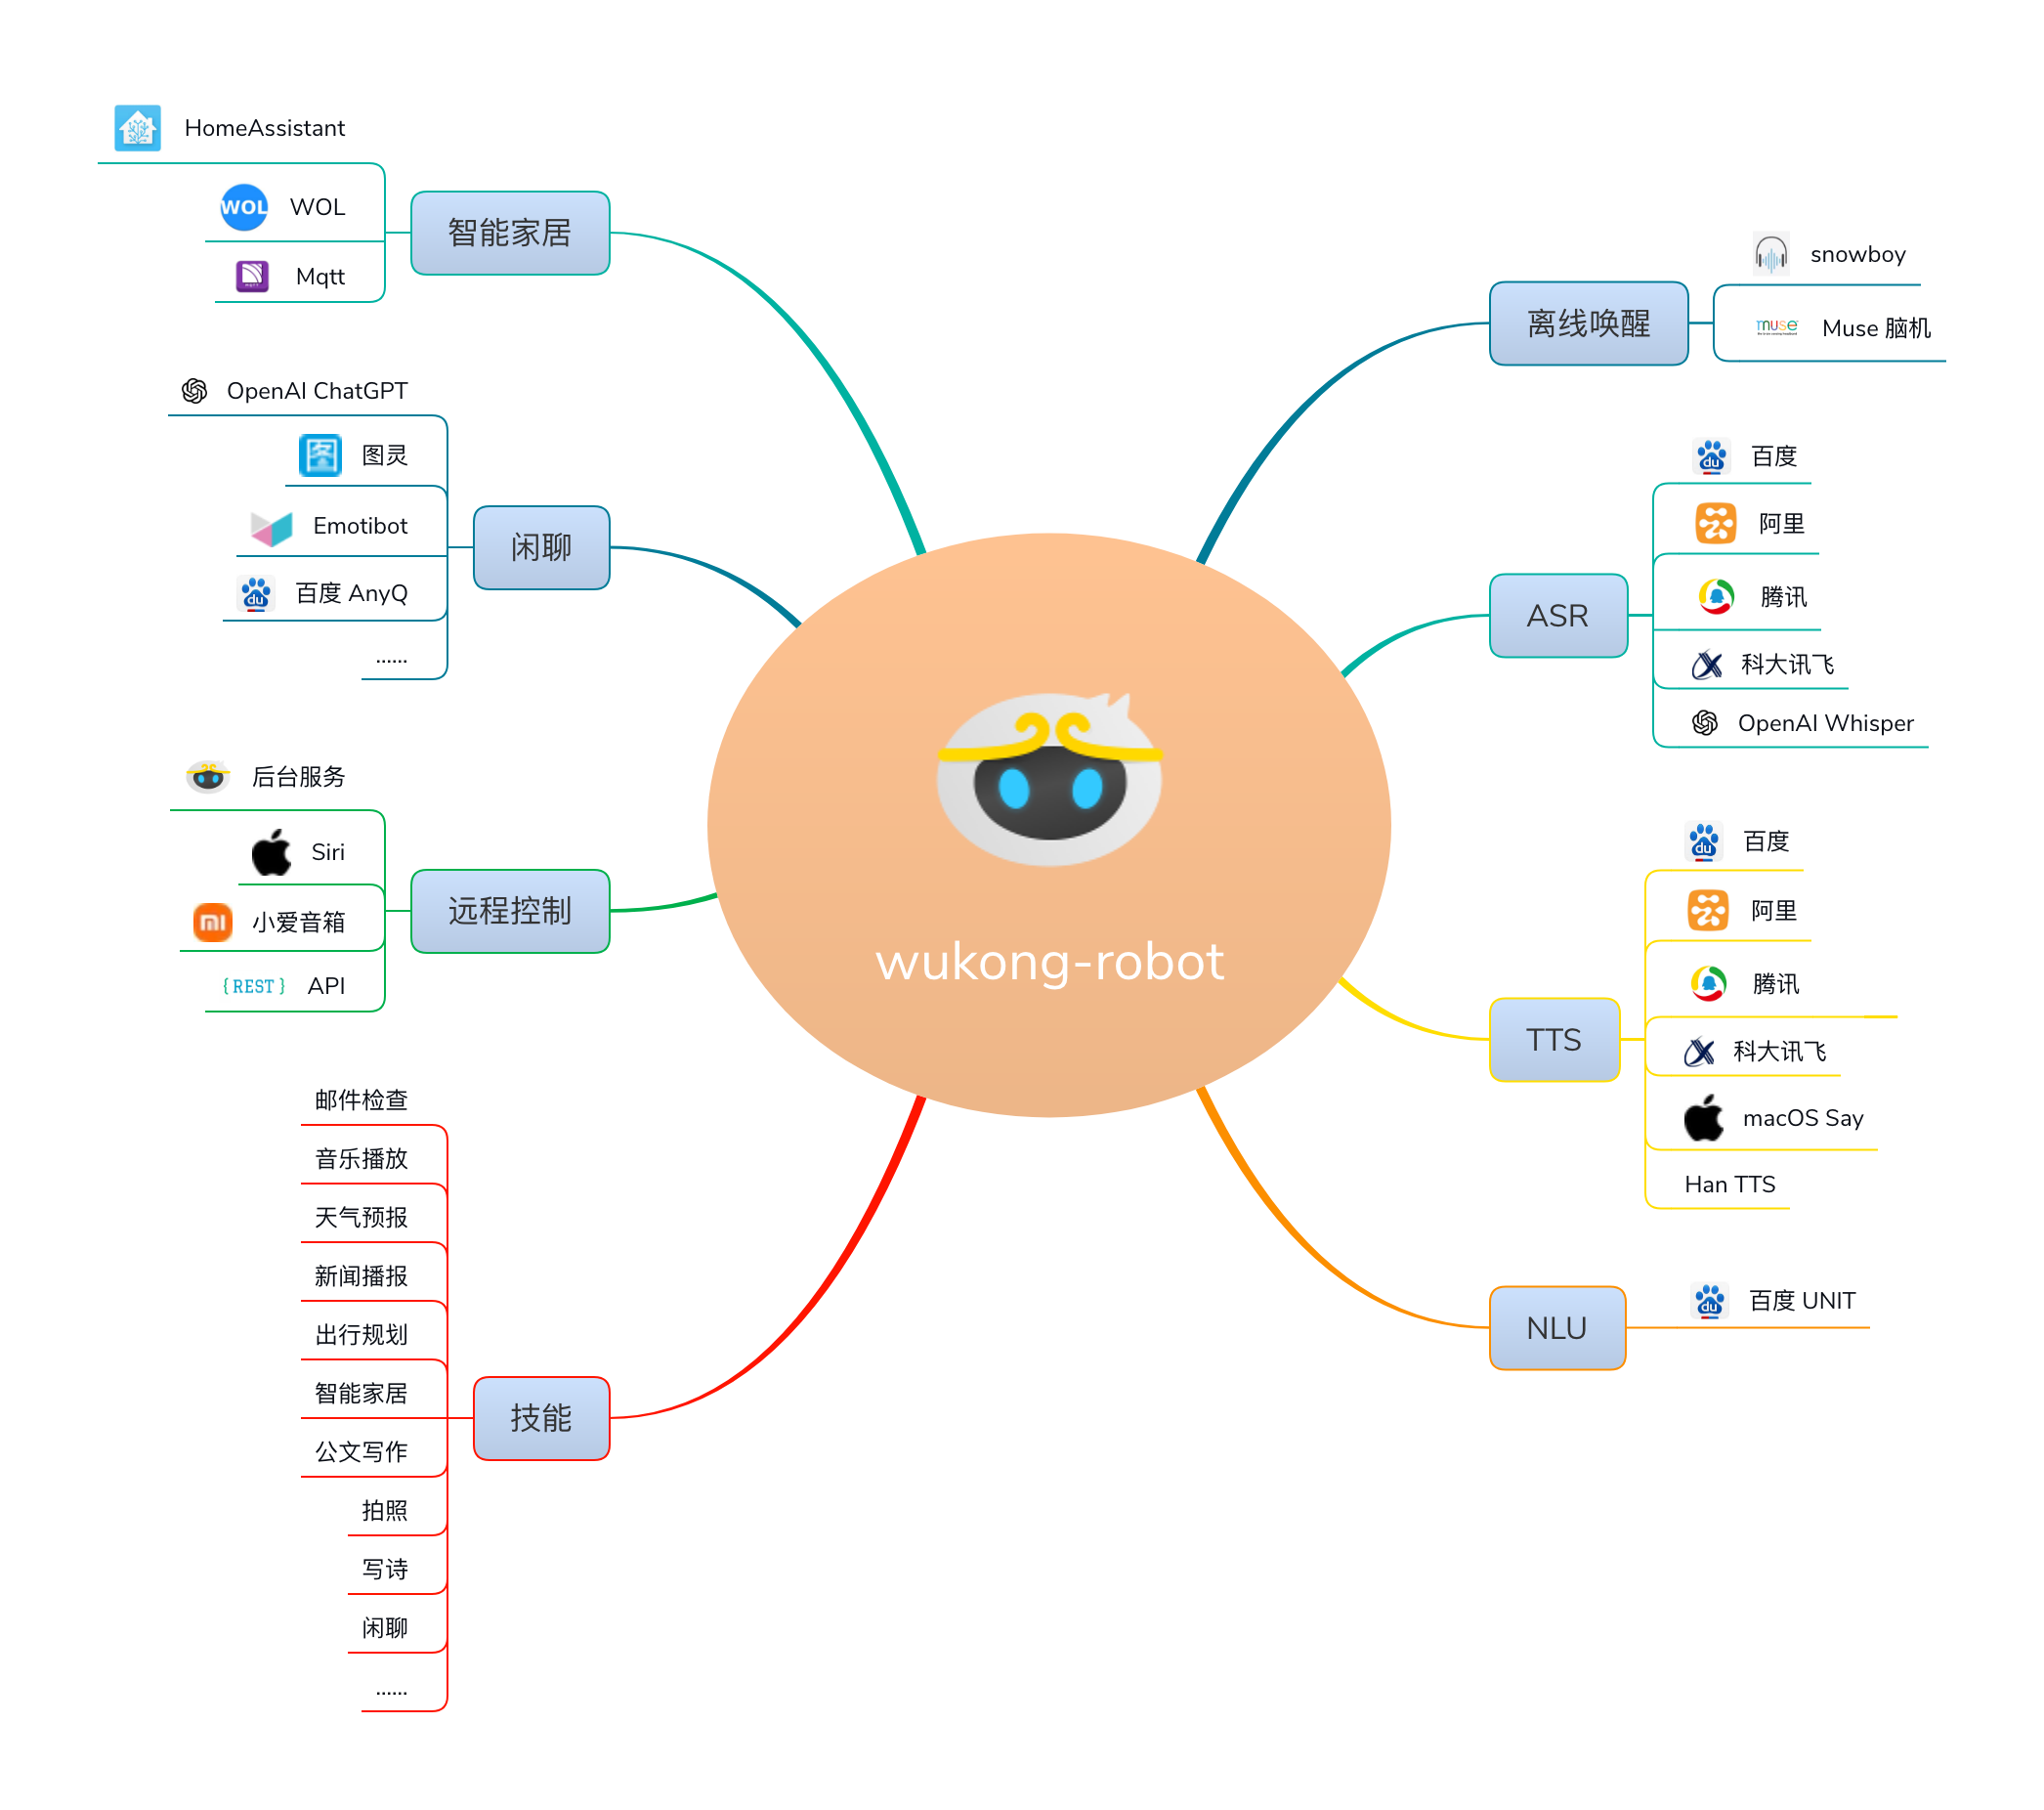
🤖 wukong-robot 是一个简单、灵活、优雅的中文语音对话机器人/智能音箱项目,支持ChatGPT多轮对话能力,还可能是首个支持脑机交互的开源智能音箱项目。
Generate audiobooks from EPUBs, PDFs and text with synchronized captions.
StyleTTS 2: Towards Human-Level Text-to-Speech through Style Diffusion and Adversarial Training with Large Speech Language Models
Silero Models: pre-trained text-to-speech models made embarrassingly simple
TTS systems evaluated on objective metrics.
Runs in the browser on Hugging Face
a lightweight TTS for Natural Anime speech generation.
Runs in the browser on Hugging Face
A cutting-edge speech generation model with stereo support
Runs in the browser on Hugging Face
Controllable TTS via instruction prompting (JPN / Anime)
Runs in the browser on Hugging Face
日本語 TTS(G2P)の誤読プリフライト ModernBERT-Ja
Runs in the browser on Hugging Face