stable-diffusion.cpp
Diffusion model(SD,Flux,Wan,Qwen Image,Z-Image,Minimax H3,...) inference in pure C/C++
- 8.1k
- C++
- MIT
- 5 d ago
Diffusion model(SD,Flux,Wan,Qwen Image,Z-Image,Minimax H3,...) inference in pure C/C++
Apple MLX native implementations of state-of-the-art generative image & video models
Train and block edit and save LoRAs directly inside ComfyUI for Z-image, Flux Klein, SDXL, Flux, WAN 2.2, SD 1.5
A set of ComfyUI nodes designed specifically for the Z-Image / Z-Image Turbo model.
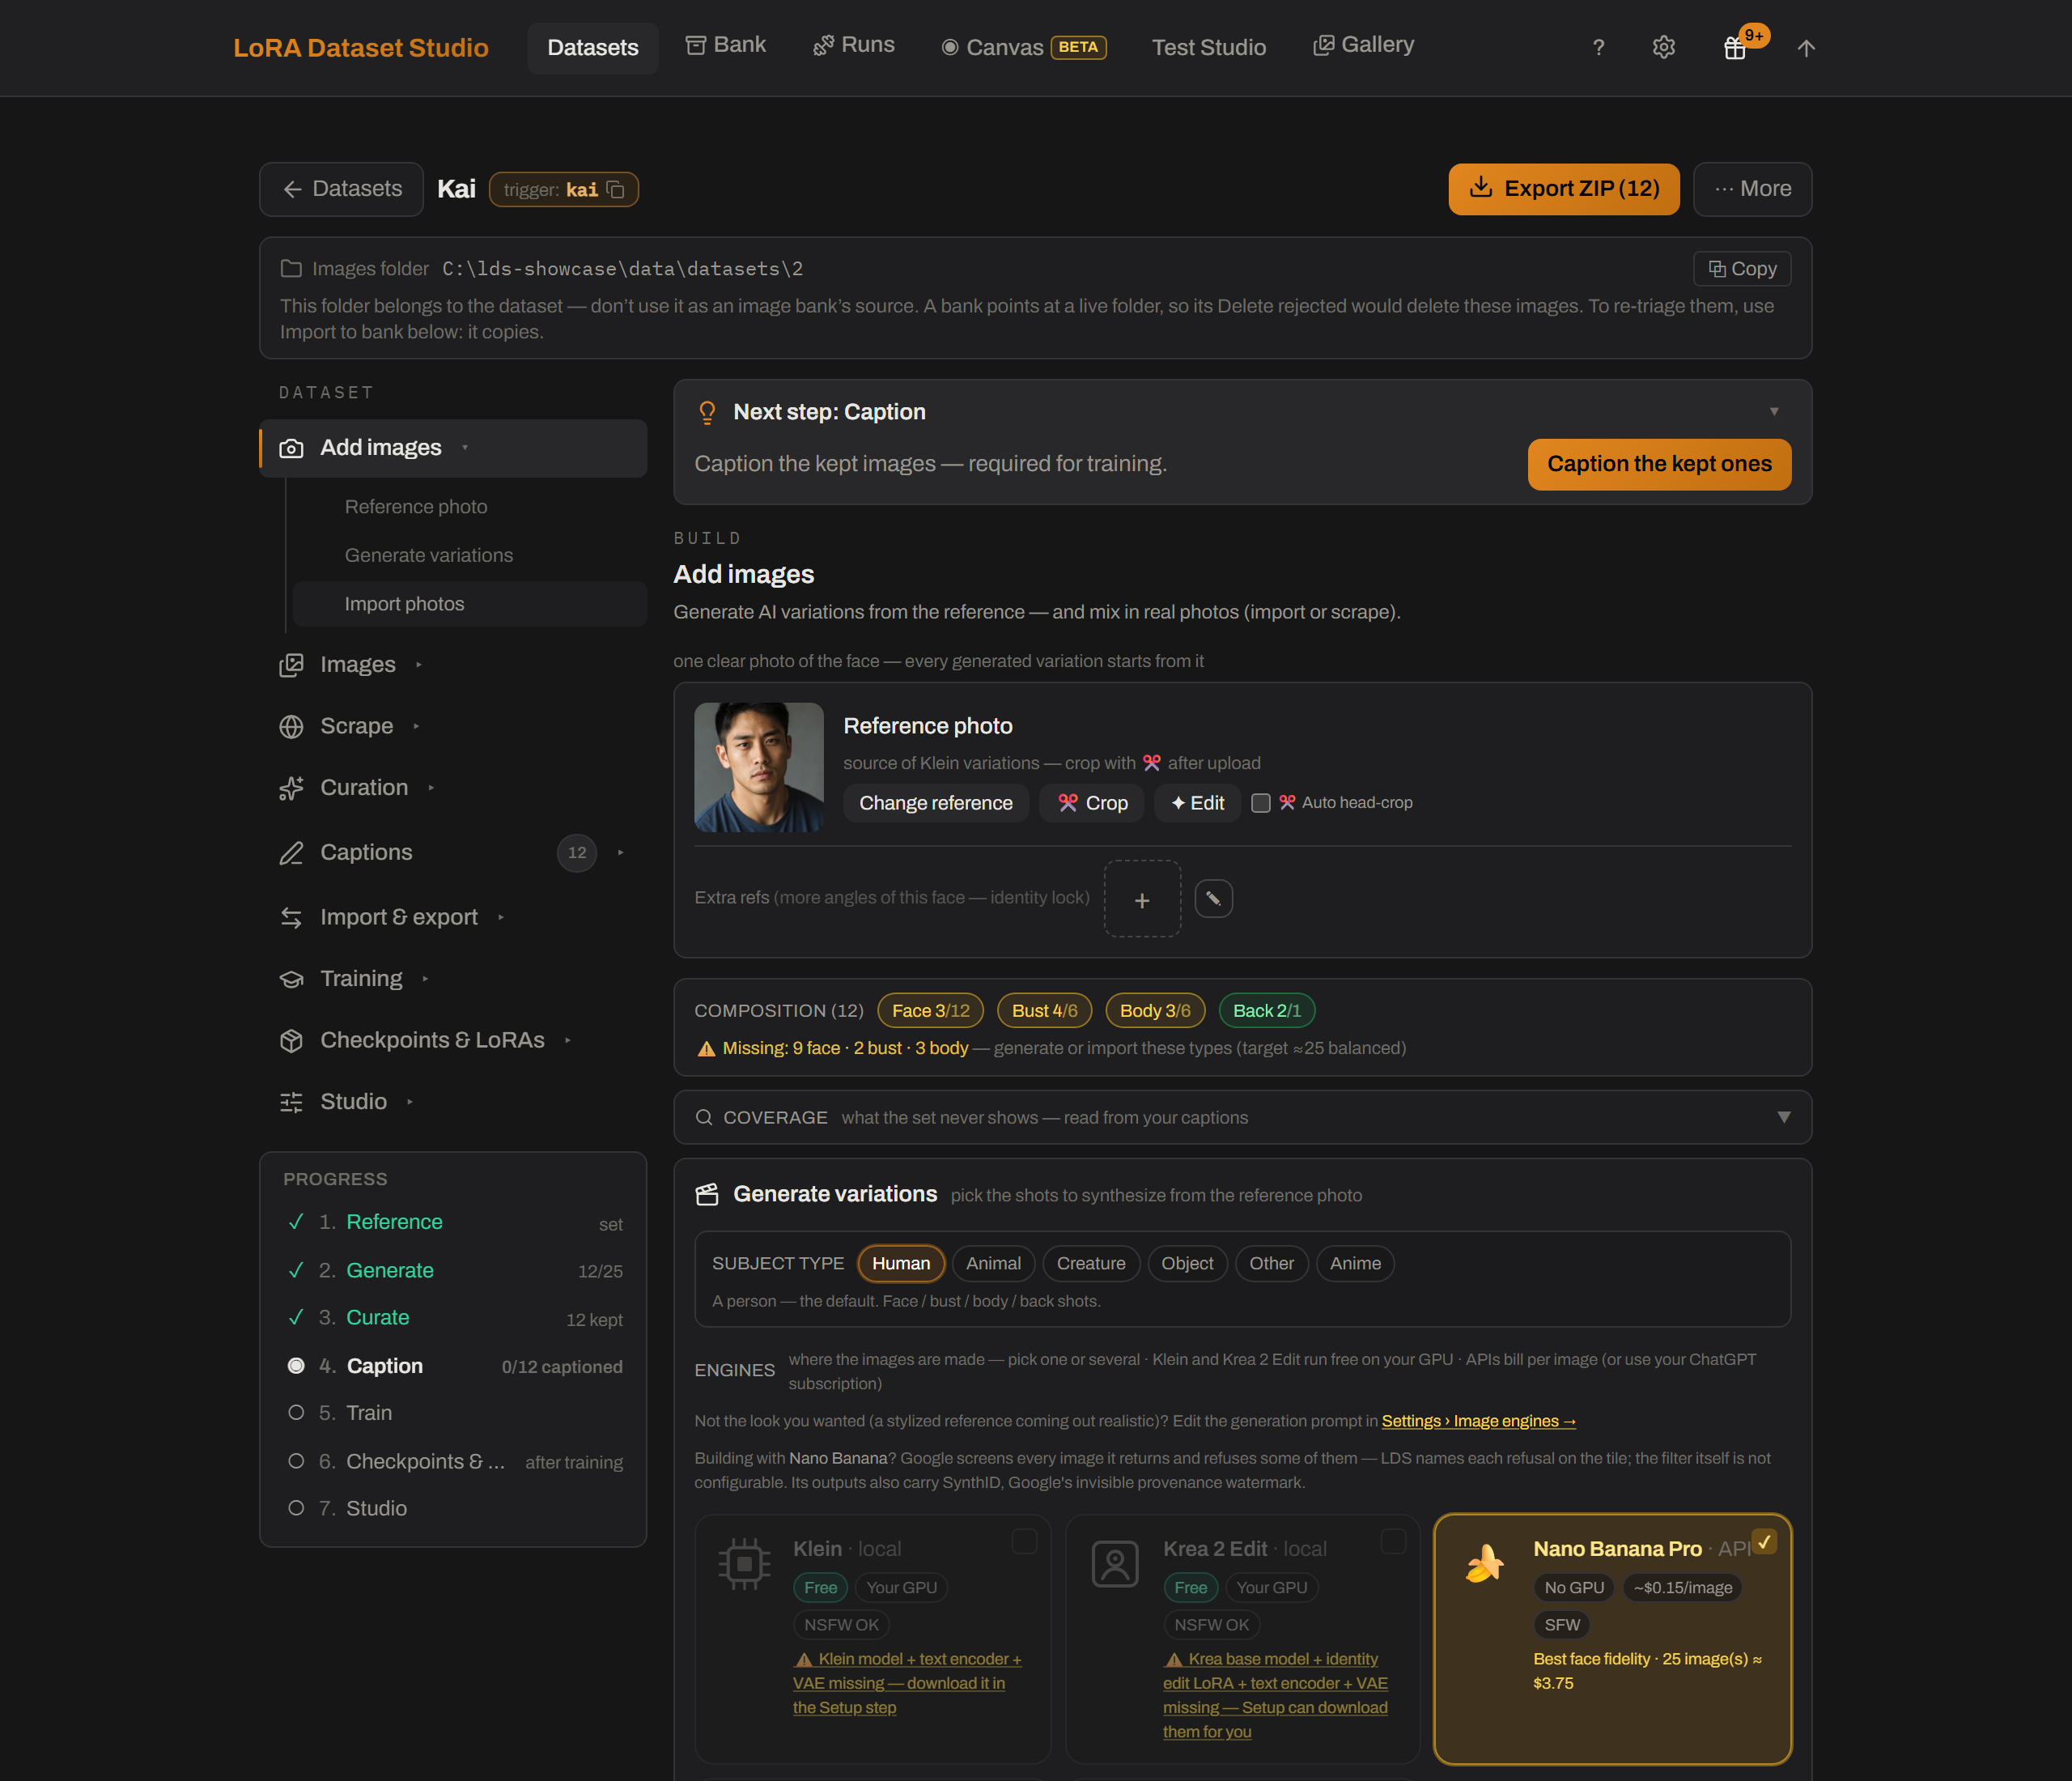
Free local LoRA training studio: build character, style and concept datasets from one photo or a big image folder, caption them (JoyCaption, prose or booru tags), train LoRAs with ai-toolkit for Krea 2, FLUX.1, FLUX.2 Klein, Qwen-Image 2.1, Z-Image, SDXL and Anima, then compare checkpoints side by side. ComfyUI-powered, self-hosted.
Sınırsız Foto: Z-Image-Turbo (Q8_0, full quality) on a 4 GB GTX 1050 Ti laptop with 16 GB RAM. stable-diffusion.cpp + cuDNN VAE, Windows, every number measured. Unofficial. Not affiliated with Tongyi-MAI, leejet or NVIDIA.
ppt-master v6.8.0 fork (ppt-master-comfyui): local ComfyUI image backend — Qwen-Image-2.1 default, MOSS-Image SFT and Z-Image Turbo selectable; grill-me style interview gate; fully editable PPTX. No API key, no per-image cost. Qwen/MOSS weights are non-commercial — see README.
WeeLLM runs large diffusion models with as little as 4 GB of VRAM, without any quantization. It dynamically determines how many layers can fit within the available VRAM and streams the text encoder and transformer layers to the GPU layer by layer, enabling inference on hardware with limited VRAM. It supports both safetensors and GGUF models.
Train LoRAs for Qwen-Image 2.1, FLUX.2 Klein 9B, FLUX.3 Image Klein, Krea 2, Z-Image, MOSS-Image, ERNIE-Image, Ideogram 4, Anima, SDXL (Pony, Illustrious, NoobAI), LTX 2.3, MiniMax-H3, and more on NVIDIA GPUs from 4–8 GB VRAM. One install, one launcher, NF4 models. Windows, Linux and RunPod.
ComfyUI custom node for NVIDIA PiD pixel diffusion decoding and upscale workflows
CLI-native local AI image and video generation for people, scripts, and agents — CUDA on Linux, Metal on macOS, plus desktop, web, iPhone, REST/SSE, and MCP.
Photoreal images on CPU only - no GPU, no CUDA, no Python
Runs in the browser on Hugging Face
Native macOS app for local AI image generation and editing on Apple silicon: Z-Image Turbo, Qwen-Image-2.1, Krea 2 Turbo, Anima Turbo and MOSS-Image in Swift and Metal, fp32, checked against diffusers. Never takes more memory than its budget: ¾ of the Mac's memory minus 2 GB.
RTX 5090 Laptop (24GB) + ComfyUI: 12 model lines / 21 measured configs — MiniMax H3, Wan 2.2, Qwen-Image 2512, HunyuanVideo 1.5, FLUX.2 Klein, Z-Image-Turbo, LTX-Video, ACE-Step 1.5, YuE2, Stable Audio 3, Hunyuan3D 2.1, ERNIE-Image. A controlled A/B proves NVFP4 beats INT8. Bilingual 中文/English, licence-verified.
DeepSeek Harness plugin that drives a local ComfyUI image workflow (Z-Image-Turbo, Qwen-Image-2.1) from the agent
Image generation on Apple Silicon's M5/M6 GPU matrix units: FLUX.2 [klein], Z-Image-Turbo, MiniMax-H3-Image
ComfyUI custom node for AI image generation with Krea 2, Z-Image, Anima, Qwen Image, Qwen Image 2.1 (Turbo) and MOSS-Image. Optional PixelDiT (PiD) 2x/4x upscaling, multi-LoRA and Korean/English UI.
Uncensored AI image generator API examples: Seedream, Qwen Image, Wan 2.7, Grok Imagine and Z-Image text-to-image and image-editing endpoints compared on Muapi
Image-to-Image with Z-Image Turbo
Runs in the browser on Hugging Face