
Dual-AI-Chat
一个先进的聊天应用,演示了一种独特的对话范式:用户的查询首先由两个不同的人工智能角色进行辩论和提炼,然后才提供最终的综合答案。该项目利用 Google Gemini API 驱动一个逻辑型 AI (Cognito) 和一个怀疑型 AI (Muse),它们协作生成更健壮、准确和经过严格审查的响应。
- 349
- TypeScript
- MIT
- 4 mo ago
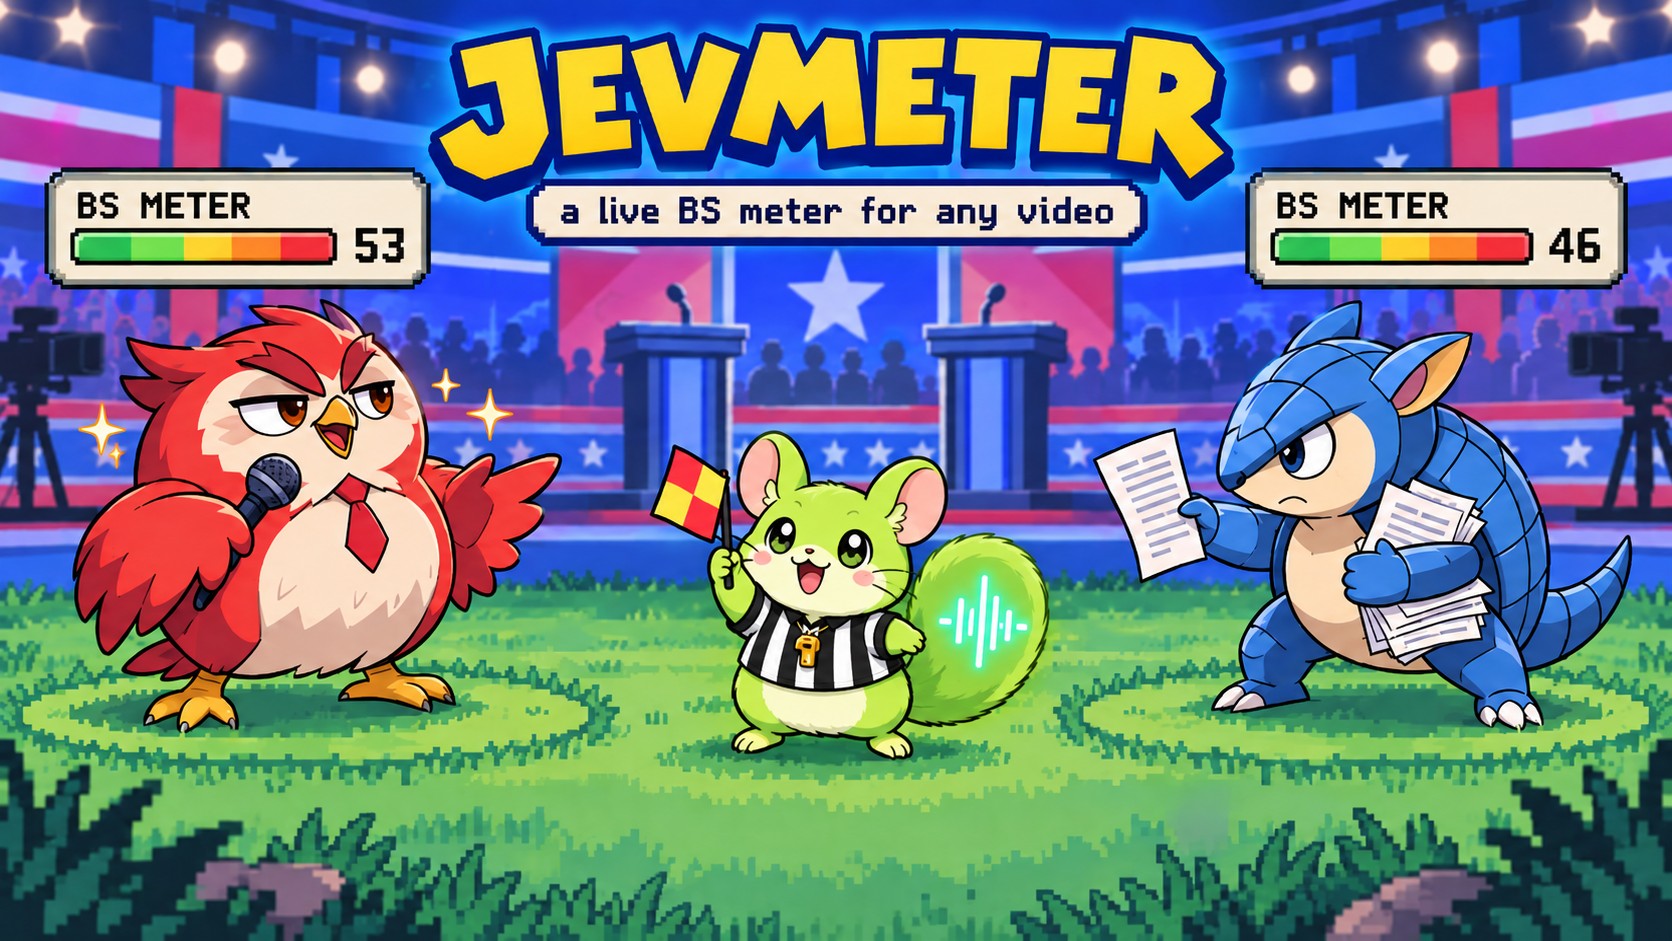
Put a live Jev (TypeSafe) meter on any video: every sentence scored, rendered as a 16:9 edit
Repo ChetasLua/jevmeter, read from GitHub 13 h ago. ChetasLua has not joined Take My Repo.
ChetasLua/jevmeter is a public repo on GitHub by ChetasLua. Put a live Jev (TypeSafe) meter on any video: every sentence scored, rendered as a 16:9 edit. It declares the MIT license on GitHub. It is written mainly in Python, has 114 stars and last changed on 2026-09-17. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-21.

1. Install (macOS or Linux, needs Python 3.9+):
git clone https://github.com/ChetasLua/jevmeter.git && cd jevmeter && ./install.sh
2. Paste your API key when the installer asks. Get one at console.typesafe.ai/keys. It's saved in your user settings, never in this folder, so it can't end up on GitHub.
3. Make a video:
source .venv/bin/activate
jevmeter
Drag your video into the terminal, pick a preset, press Enter a few times, and your edited video appears next to
the original as <name>.jevmeter.mp4. 🎉
🎬  Step 1: your video
    Drag the video file into this window (or paste a path or link), then press Enter.
    Video: ~/Movies/town-hall.mp4

🎴  Step 2: pick a preset
    1. 🦉  Debates & interviews             BS index: evasive, dodged the question, emotional appeal, contradicts self
    2. 🦊  Earnings calls & investor Q&A    Spin index: vague guidance, blaming outside factors, hype, dodges
    3. 🐉  Podcasts & YouTube talk          Hot take index: unsupported claims, overgeneralizations, outrage, self-promotion
    4. 🦚  Pitches, launches & ads          Hype index: buzzwords, overpromises, urgency pressure, vague benefits
    Number [1]:

👥  Step 3: who is speaking?
    Transcript file (press Enter to skip = one meter for everyone):

✂️   Step 4: what kind of video do you want?
    1. Highlights: best moments + hyperlapse + final scoreboard (about 1-2 min, great for posting)
    2. Full: meter over the whole video (or a part of it)
Something not working? Run jevmeter doctor. It checks Python, ffmpeg, speech-to-text and your key, and tells you
exactly what to fix. On Windows, use the manual install below.
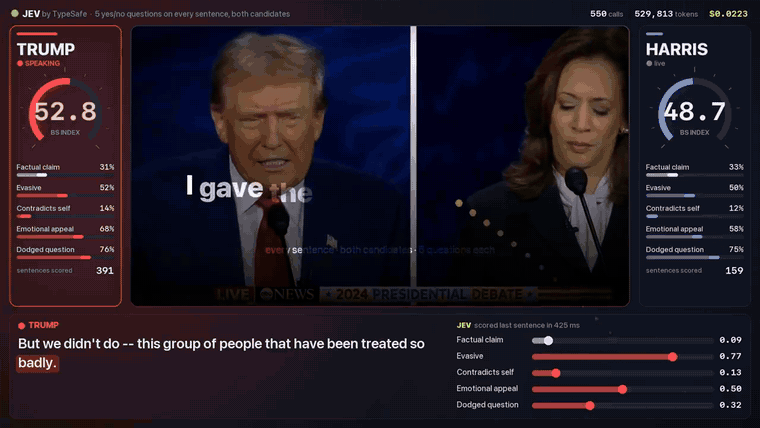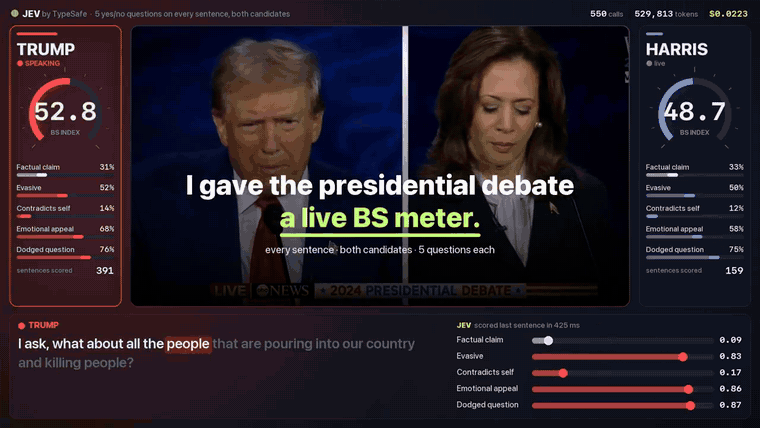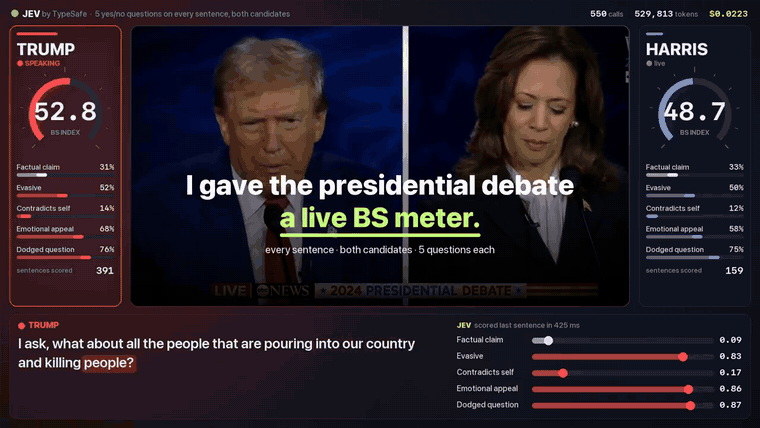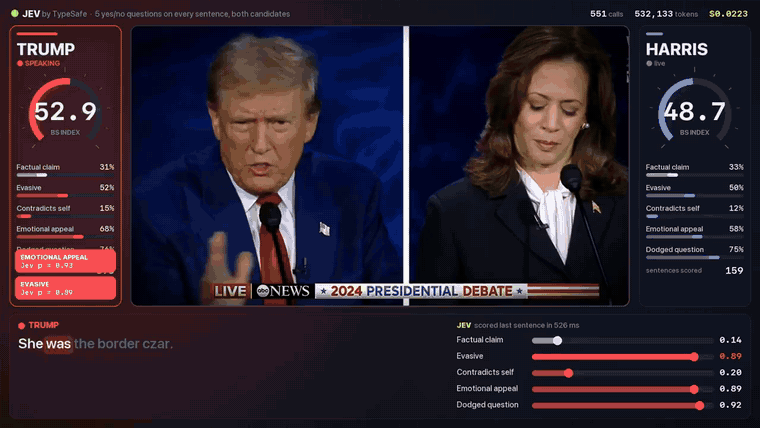
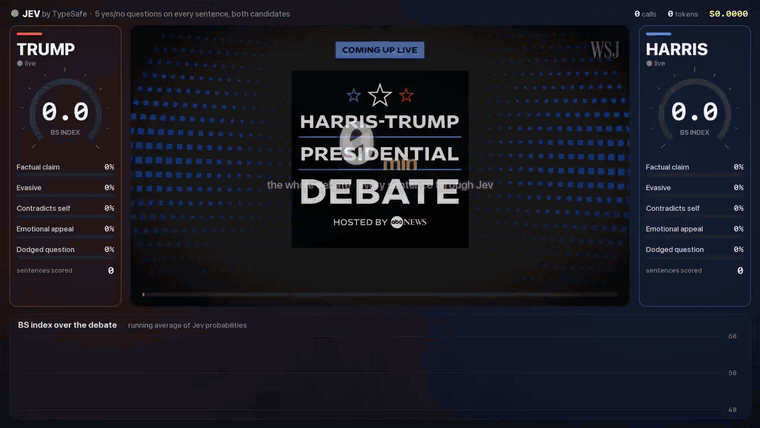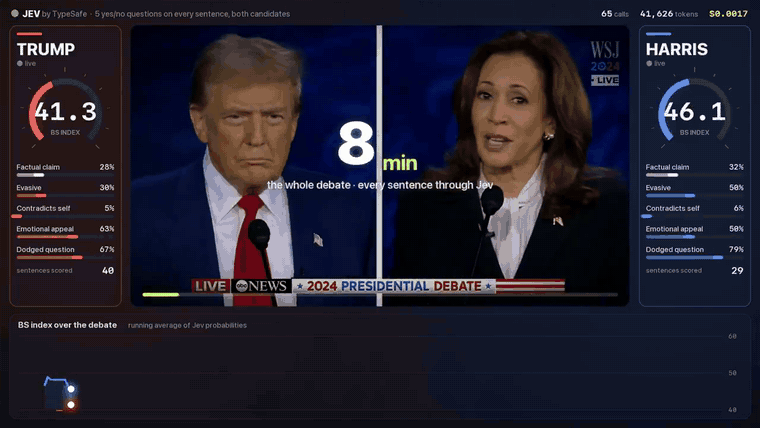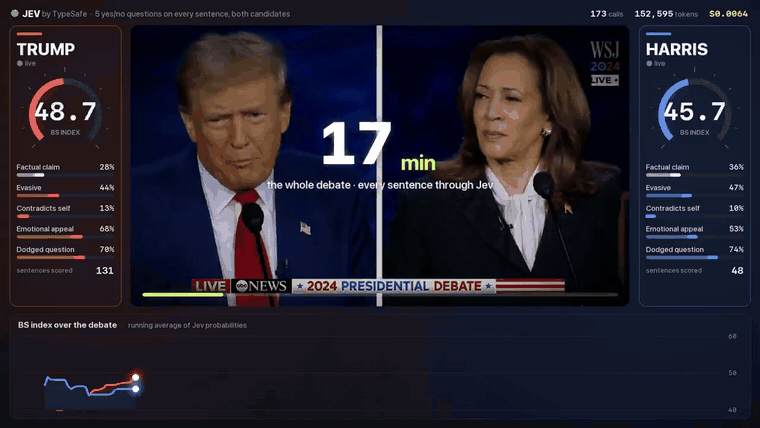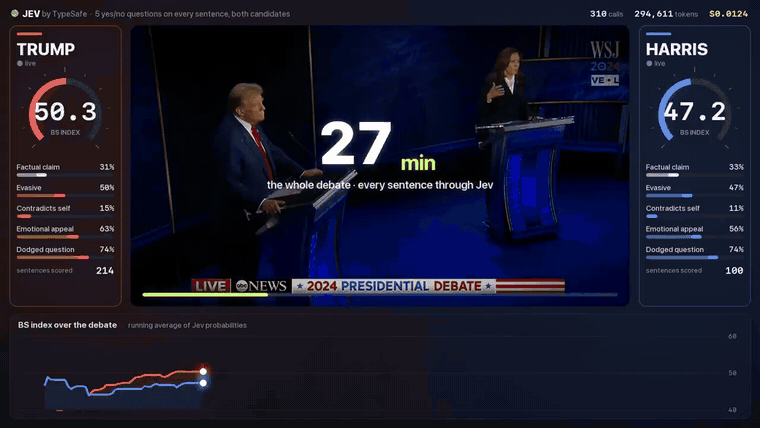
I gave the Trump vs Harris debate a live BS meter using Jev, TypeSafe's decision model that answers yes/no questions with calibrated probabilities instead of writing text. Watch the full video on X →
 |
 |
 |
| Flag! Evasive, Jev p = 0.86 | Camera follows the speaker | Final scoreboard + receipts |
| 🔴 Trump | 🔵 Harris | |
|---|---|---|
| BS INDEX | 53 | 46 |
| Factual claim | 31 | 35 |
| Evasive | 52 | 45 |
| Contradicts self | 17 | 11 |
| Emotional appeal | 68 | 57 |
| Dodged question | 76 | 71 |
| Sentences scored | 832 | 359 |
1,191 Jev calls · 5,955 yes/no answers · 1,182,843 input tokens · $0.0497 total · ~0.4 s median per call
The meters show Jev's probabilities, not a fact-check. Both speakers get the same 5 questions, and the highlight clips are picked by one fixed rule. See Read the numbers responsibly.

| preset | index | questions Jev asks about every sentence |
|---|---|---|
debate |
BS INDEX | factual claim · evasive · contradicts self · emotional appeal · dodged question |
earnings_call |
SPIN INDEX | specific number · vague guidance · blames outside factors · hype language · dodged question |
podcast |
HOT TAKE INDEX | factual claim · unsupported claim · overgeneralization · emotional appeal · self-promotion |
sales_pitch |
HYPE INDEX | concrete metric · buzzwords · overpromise · urgency pressure · vague benefit |
Tested, not guessed. On 200 held-out sentences written separately from the presets (with tricky near-misses, like a polite "thank you" before a real answer, or a promise that contains a number), the shipped presets get 99% accuracy and every question separates yes from no perfectly (AUC 1.00). The first version got 94.5%. Full breakdown and how to rerun it: eval/RESULTS.md.
The questions follow TypeSafe's guidance: each one names the field it judges
(`sentence`, `moderator_question`) and carries structured yes/no criteria with examples.
Want a different fight? A preset is a small JSON file, so write your own.
Manual install (any OS, including Windows):
git clone https://github.com/ChetasLua/jevmeter.git
cd jevmeter
python -m venv .venv && source .venv/bin/activate   # Windows: .venv\Scripts\activate
pip install -e ".[mlx]"      # Apple Silicon (mlx-whisper)
# pip install -e ".[cpu]"    # everything else (faster-whisper)
jevmeter setup               # paste your key once
Your API key, safely. jevmeter looks for the key in this order: the TYPESAFE_API_KEY environment variable, a
.env file in the current folder (git-ignored, see .env.example), then ~/.config/jevmeter/config.json, which
jevmeter setup writes readable only by you. The repo's CI and an optional pre-commit hook
(python scripts/check_secrets.py --install) block commits that contain anything that looks like a key.
Two speakers + transcript (debates, interviews):
jevmeter run debate.mp4 --transcript debate.txt \
  --speakers "TRUMP,HARRIS" --label TRUMP=Trump --label HARRIS=Harris --preset debate
A link instead of a file (needs pip install yt-dlp; only use videos you have the right to use):
jevmeter run "https://www.youtube.com/watch?v=..." --preset podcast --mode full --start 300 --end 420One speaker, no transcript (podcasts, pitches, keynotes):
jevmeter run pitch.mp4 --preset sales_pitch --speakers "Founder" --mode full --start 60 --end 180Try it without any footage: a fictional mock debate made with macOS text-to-speech.
python examples/make_mock_video.py
jevmeter run examples/mock_debate.mp4 --transcript examples/mock_debate_transcript.txt \
  --speakers REYES,PARK --label REYES="MAYOR REYES" --label PARK="CLLR PARK" --clips 2
That run scores 33 sentences for about $0.002. With the shipped presets, Jev rates the evasive mayor at 60.6 and the specific councillor at 12.6.
 |
 |
| Two-speaker mode | Single-speaker mode + live Jev feed |
| 🎙️ Transcribe | mlx-whisper or faster-whisper word timestamps; an optional NAME: text transcript is aligned to the audio |
| ⚡ Score | one Jev request per sentence, with the speaker's history and the last question as context |
| 🎬 Two edit modes | highlights auto-picks clips + hyperlapse + end card; full puts the meter over the whole range |
| 📷 Camera | eases toward whoever is speaking on a broadcast split screen, zoom kick when a flag fires |
| 🟢 Jev effects | scan beam when a sentence is scored, data dot flying into the meter, glowing flag cards |
| 🔊 Sound | original audio + synthesized whooshes, blips and riser, loudness-normalised for social |
| 💾 Resumable | every step is cached; a crash or a tweak never re-pays for transcription or scoring |
A line starting with NAME: begins a turn; other non-empty lines continue it.
MODERATOR: Housing costs rose eleven percent last year. What will you do about it?
REYES: Look, everybody knows this city is the greatest city in the country.
PARK: We will permit four thousand new homes near transit by 2028.
Names and spelling come from your transcript, timing comes from the audio. Speakers you don't pass to --speakers
aren't scored, but their latest turn is given to Jev as context; that's how "dodged question" knows what was asked.
A transcript that repeats itself verbatim, as some news pages do, is de-duplicated automatically. Without a
transcript, all speech counts as one speaker.
{
  "hook": "I gave this keynote a live hype meter.",
  "hook_sub": "every sentence · 2 questions each",
  "index_label": "HYPE INDEX",
  "context_label": "question",
  "end_title": "Final score: the whole keynote",
  "questions": [
    {"key": "benchmark", "label": "Cites a benchmark", "index": false,
     "instructions": "Does this sentence cite a specific benchmark result or number?"},
    {"key": "superlative", "label": "Superlative", "index": true,
     "instructions": "Does this sentence use superlatives (best ever, most powerful) without evidence?"}
  ]
}
Run it with --preset my_questions.json.
index: true questions are averaged into the big gauge.index: false questions (like "factual claim") are shown in neutral grey.flag (0–1) sets the pop-up threshold. By default it's the 98th percentile of that question's scores, with a floor of 0.5.| option | default | what it does |
|---|---|---|
--mode highlights|full |
highlights |
auto-edited highlights, or the meter over the whole range |
--clips N |
3 | clips per speaker in highlights mode |
--start / --end |
whole video | seconds; limits transcription, scoring and rendering |
--hook "text" |
from preset | opening headline; --hook "" turns it off |
--label KEY=Name |
speaker key | display name per speaker (repeatable) |
--colors "#hex,#hex" |
red, blue | speaker colours |
--whisper-model |
small |
any mlx-community / faster-whisper model name |
--threads |
6 | parallel Jev requests |
--workers |
half your cores, max 4 | parallel render processes |
--price |
0.042 | $ per 1M input tokens for the cost counter; check your console |
--score-only |
off | stop after scoring and print the per-speaker summary |
jevmeter setup |
save or replace your API key | |
jevmeter doctor |
check that everything is installed and the key works | |
--work DIR |
<video>.jevmeter/ |
cache folder (words, sentences, scores, EDL, parts) |
difflib aligns transcript words to Whisper's, so every
sentence gets start/end times and per-word timings for the karaoke captions.POST /v1/systemone once per sentence, with each preset question as a noul. The state holds the
speaker, the latest context turn, their previous 25 sentences and the answer so far. Keep-alive connections matter
here: a fresh TLS handshake per call was about 15x slower. Results stream into scores.jsonl, so a crash resumes.edl.json.loudnorm.Hand-edit edl.json and re-render with python -m jevmeter.render <work> out.mp4 0 <num_segments>.
MIT © Chetas Lua. Not affiliated with TypeSafe; "Jev" is TypeSafe's model. The creature artwork is original and was generated with ChatGPT for this project. The demo clips come from the ABC News debate broadcast and are shown here as commentary on the tool's output.
ChetasLua/jevmeter is a public repo on GitHub by ChetasLua. Put a live Jev (TypeSafe) meter on any video: every sentence scored, rendered as a 16:9 edit.
It declares the MIT license on GitHub.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Its last change on GitHub was on 2026-09-17. Take My Repo does not judge from that whether it is maintained.
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.
一个先进的聊天应用,演示了一种独特的对话范式:用户的查询首先由两个不同的人工智能角色进行辩论和提炼,然后才提供最终的综合答案。该项目利用 Google Gemini API 驱动一个逻辑型 AI (Cognito) 和一个怀疑型 AI (Muse),它们协作生成更健壮、准确和经过严格审查的响应。
Non-autoregressive System 1 decision engine. Typed choice, score and yes/no decisions over any text in a single forward pass, in 100+ languages, with a router that picks the right checkpoint per request.
💥 A Lodash-style Go library based on Go 1.18+ Generics (map, filter, contains, find...)
Clone any viral video with AI agents. Not just a script, the whole workflow: swap the face, the words, the B-roll, ship 100 variants in one command, and get your 100M views.
VoiceStudio is the open-source, fully-local ElevenLabs alternative — voice cloning, voice design, video dubbing, dictation, transcription & audiobook creation in 646 languages.
利用 AI 大模型和自动化工作流,根据主题或关键词一键生成高清短视频。Generate HD short videos from a topic or keyword with an automated AI workflow.
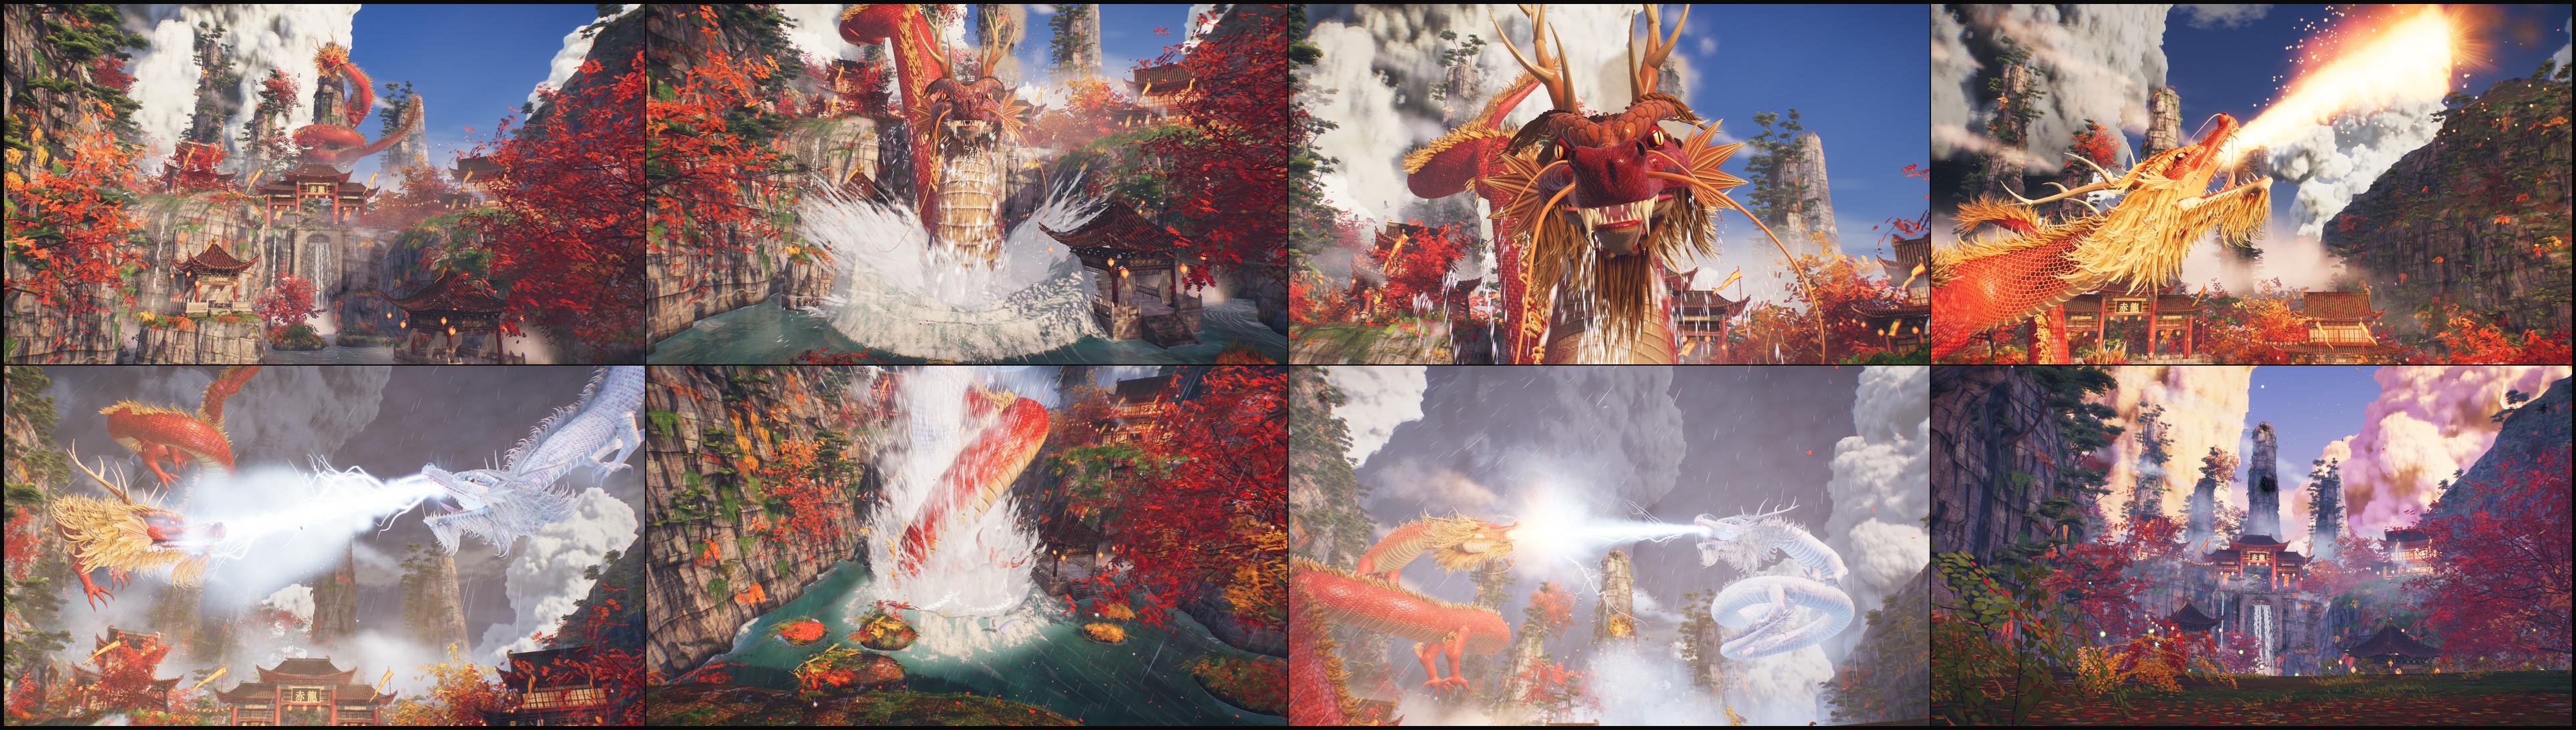
赤龍 Crimson Loong: a 90 s dragon film in one HTML file. Pure three.js, every mesh, texture and note is code, zero assets.
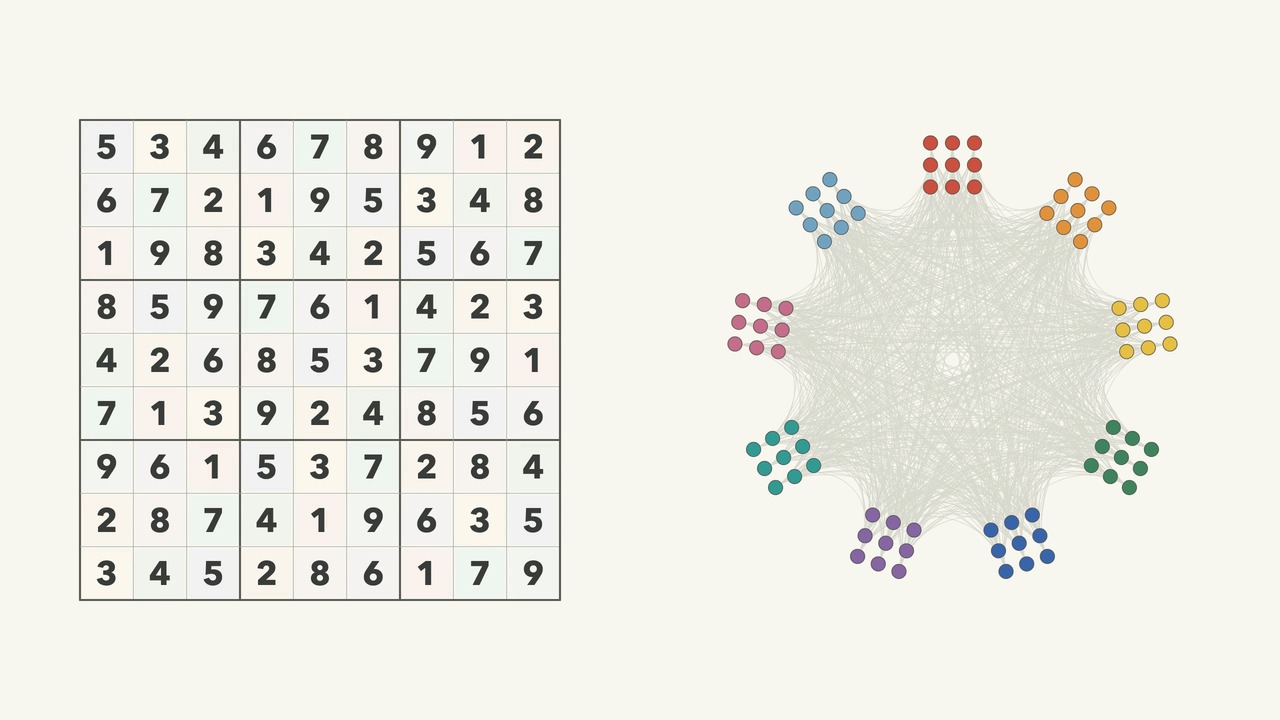
Solve any standard 9x9 Sudoku with exact graph coloring. Interactive browser demo, real backtracking traces, Python solver, and a verified 16:9 animation.
The Mona Lisa, painted live in the browser by 62,430 brush strokes. One HTML file: no image, no assets, no libraries, no network.
100% pure-code, zero-external-asset 13-cut 60fps Three.js & Web Audio character reveal trailer
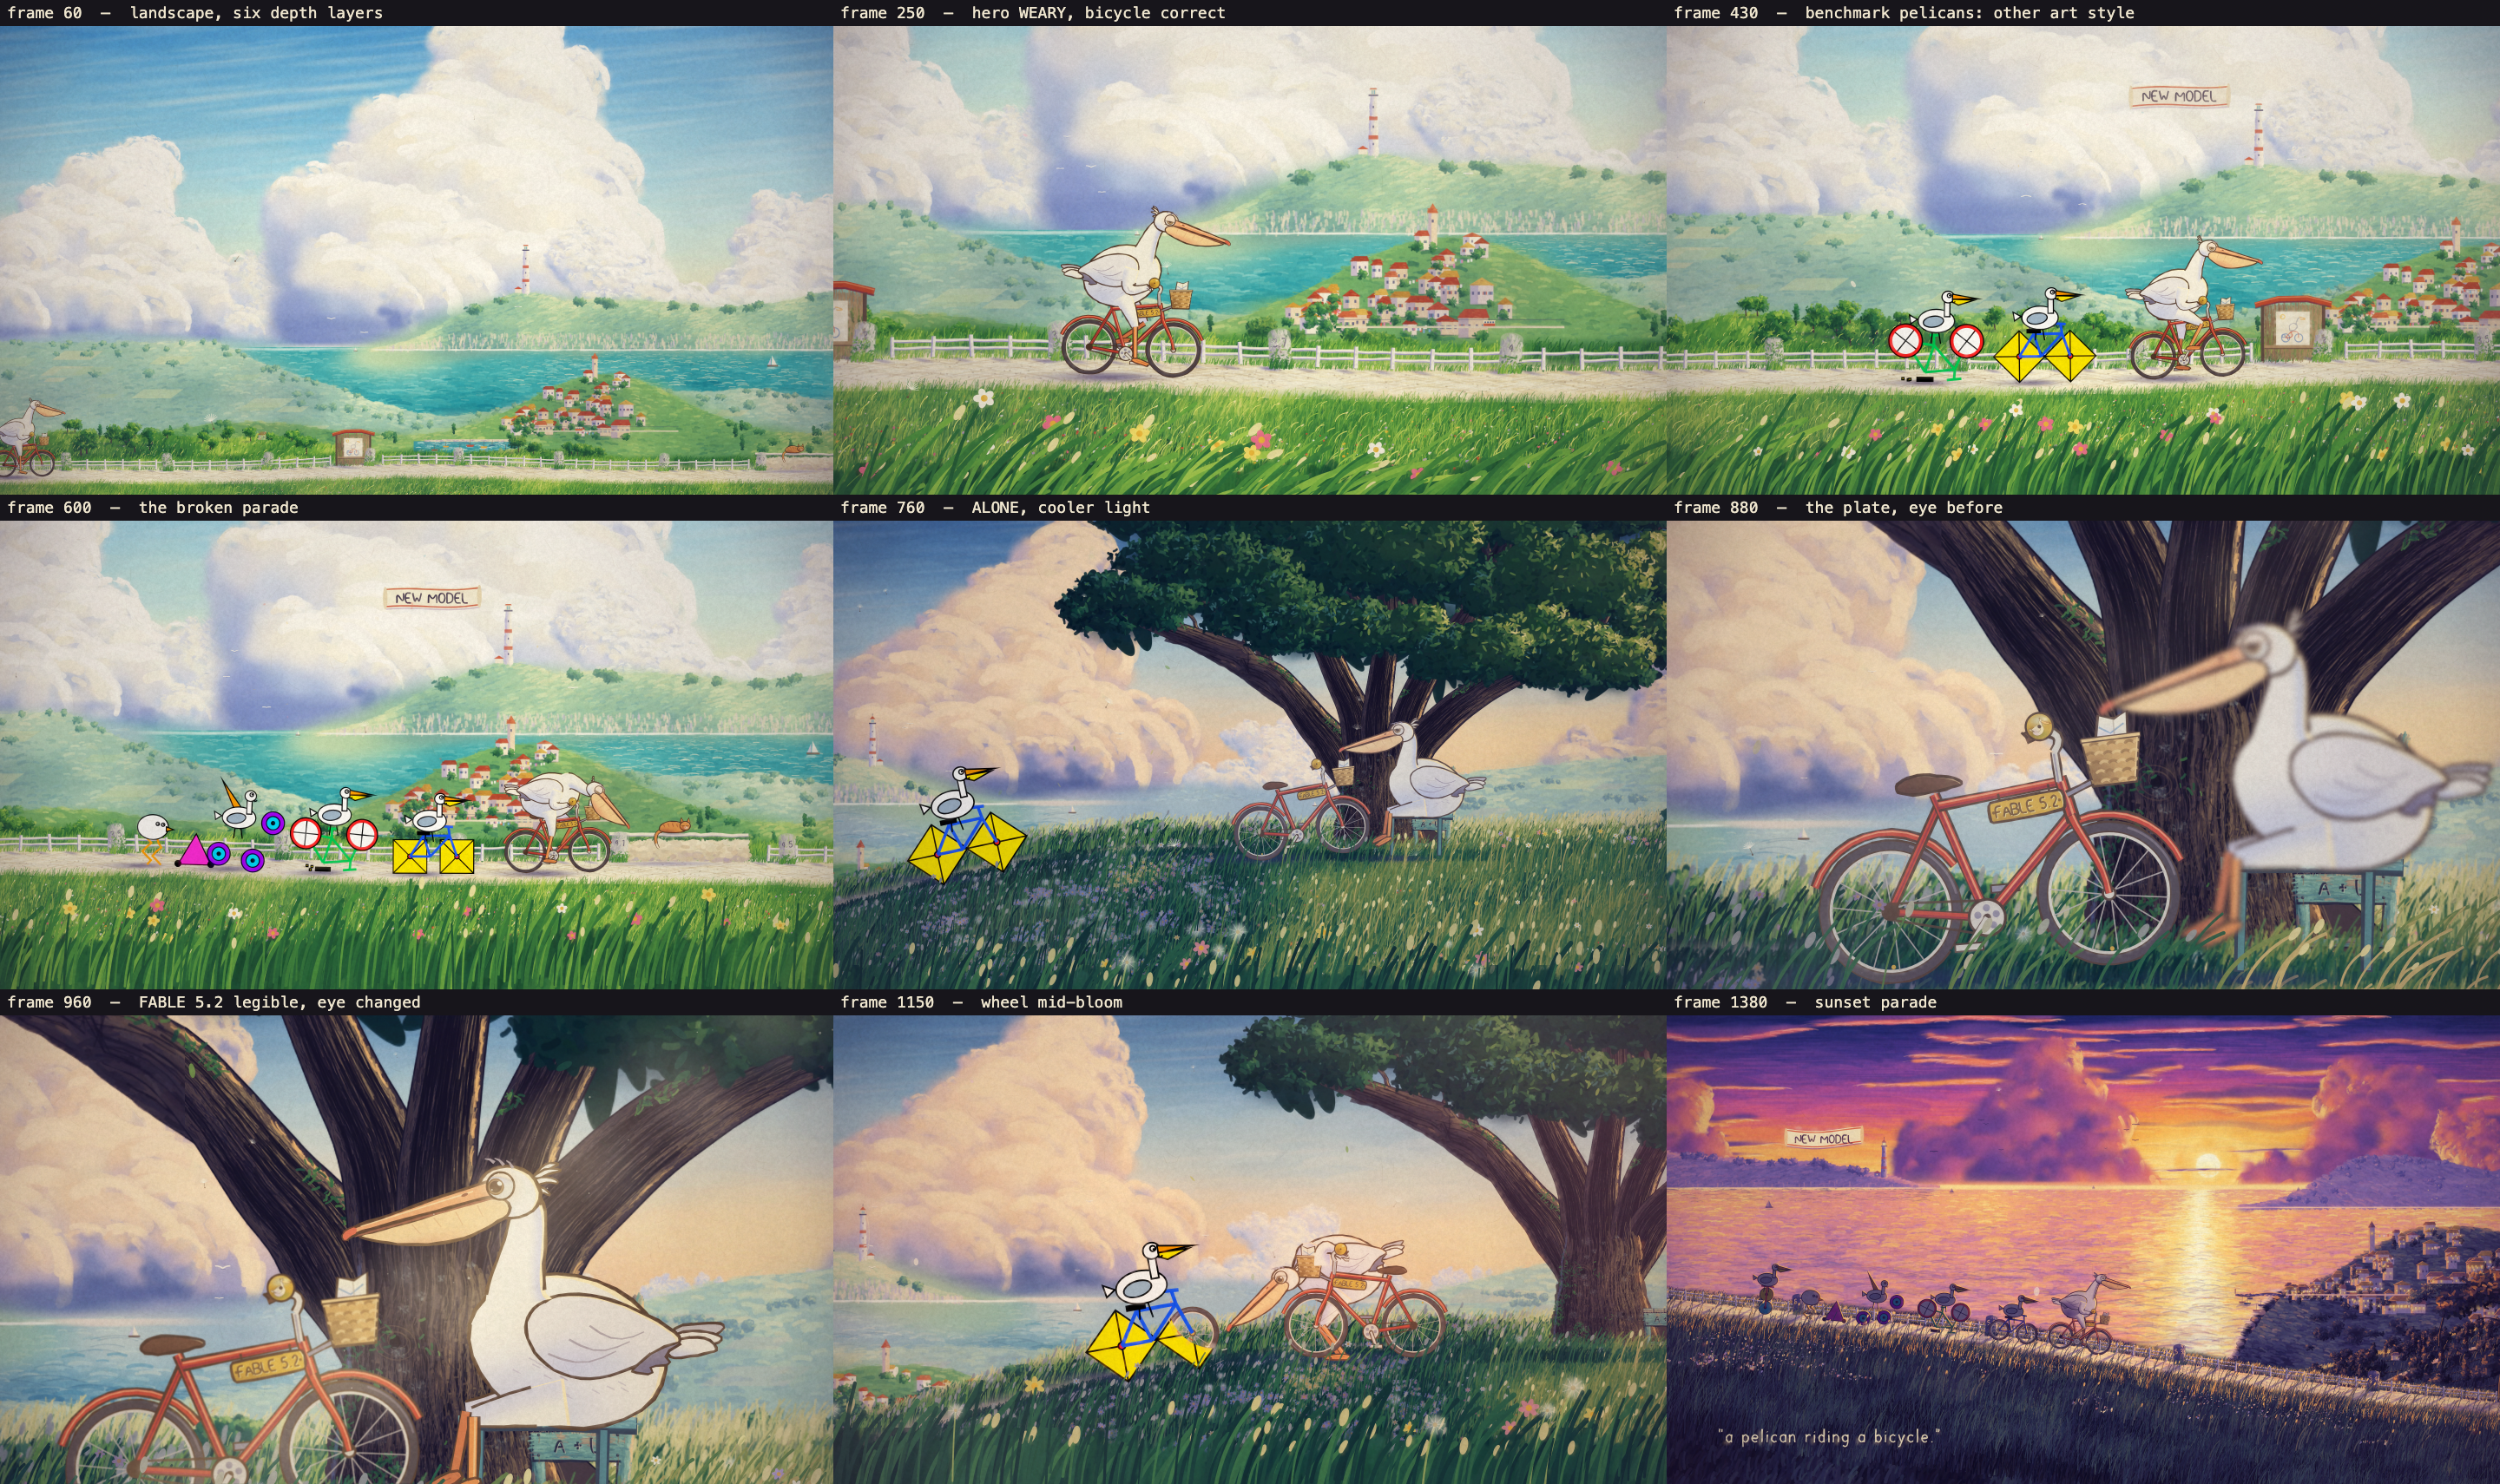
A 60-second hand-painted 2D animated short made entirely in code: Canvas 2D picture, synthesized sound, one HTML file