loopx
The control plane for 24/7 always-on agents. Turn long-horizon goals into verifiable results across Codex, Claude Code, and custom runtimes—from local SQLite to team scale.
- 6.7k
- Python
- Apache-2.0
- 9 h ago
:sunrise: A comprehensive, cutting-edge open-source framework for next-generation Transformers/LLM, with compute-matched benchmarking and a platform for autonomous architecture research.
Repo Interactive-Active-AI/NextTransformer, read from GitHub 14 h ago. Interactive-Active-AI has not joined Take My Repo.
Interactive-Active-AI/NextTransformer is a public repo on GitHub by Interactive-Active-AI. :sunrise: A comprehensive, cutting-edge open-source framework for next-generation Transformers/LLM, with compute-matched benchmarking and a platform for autonomous architecture research. It declares the MIT license on GitHub. It is written mainly in Python, has 487 stars and last changed on 2026-11-20. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-20.
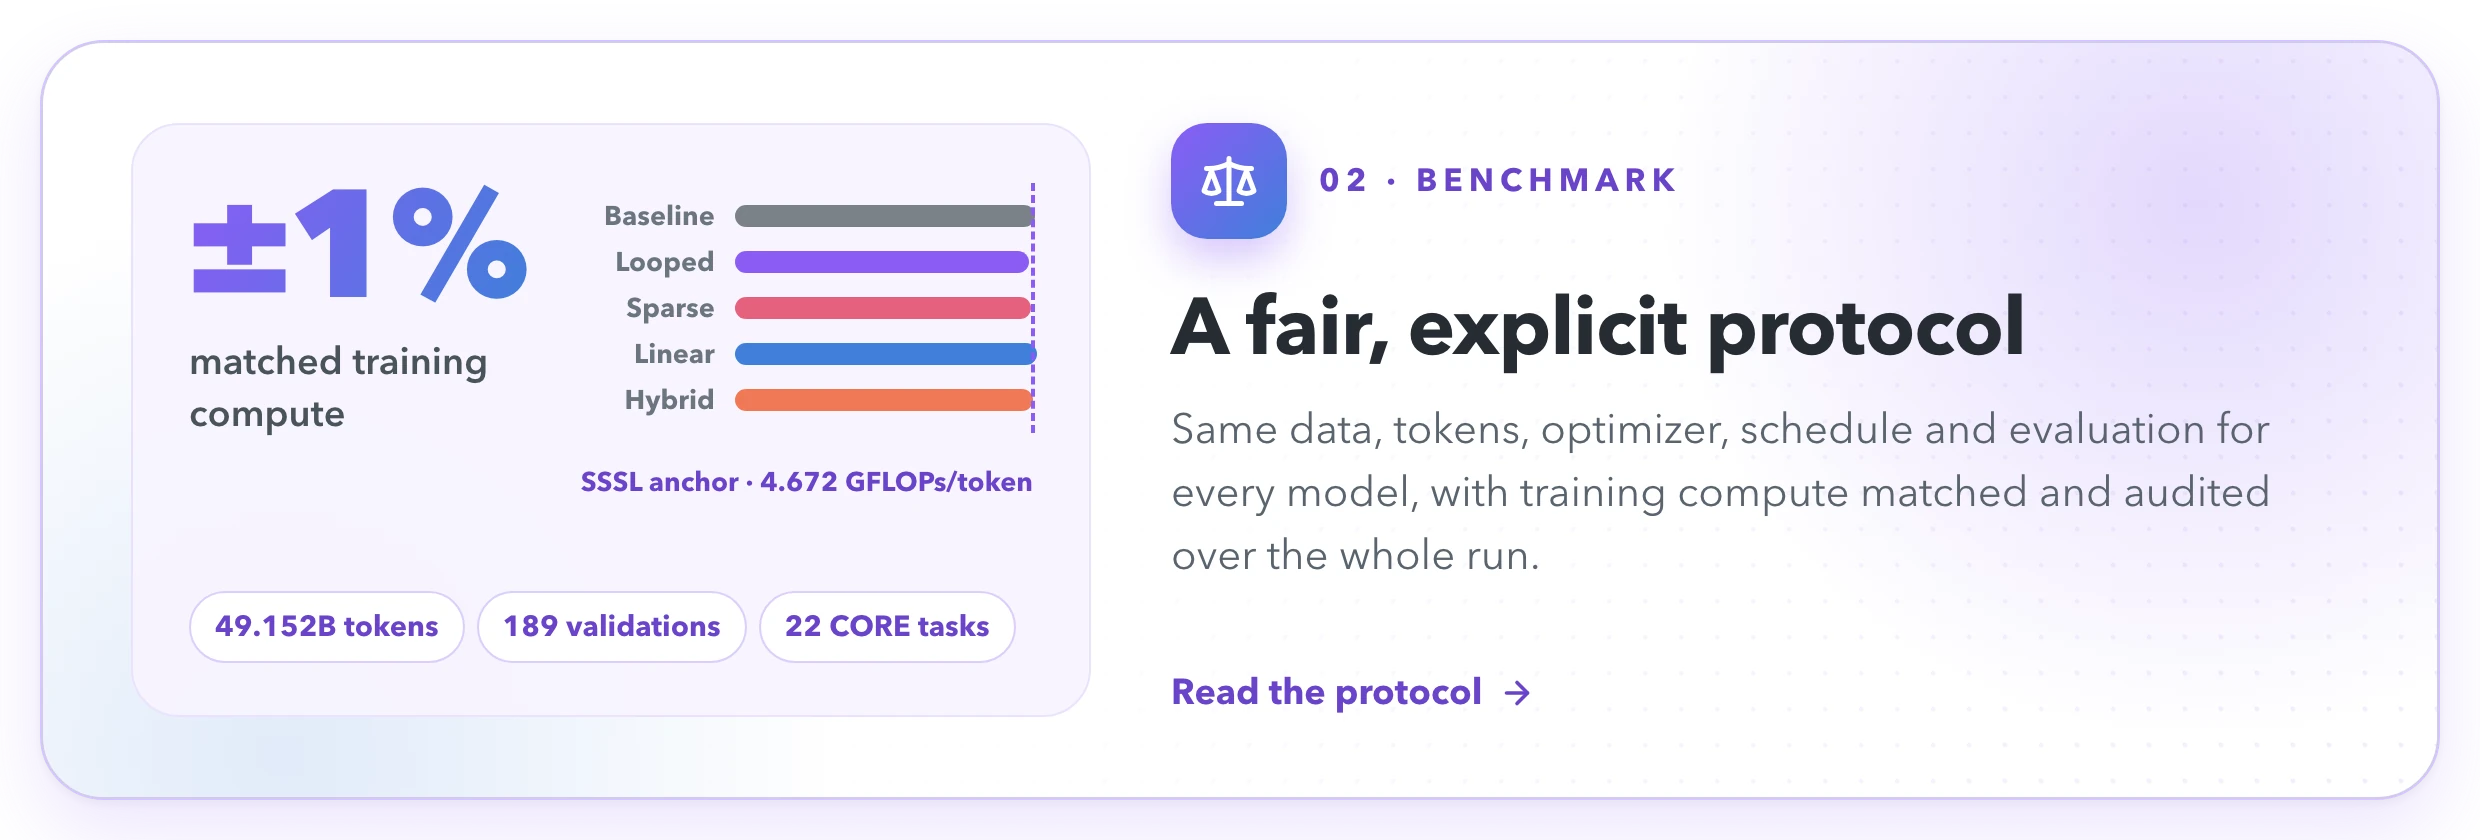
When the training budget is fixed, how should a language model spend its computation? NextTransformer trains recurrent depth, sparse and linear attention, residual-stream variants and hybrids on the same data, for the same 49.152B tokens, at the same theoretical training FLOPs per token, and evaluates them at the same checkpoints. Every result is an audited, file-backed record, and AI agents can research new architectures under the very same rules.
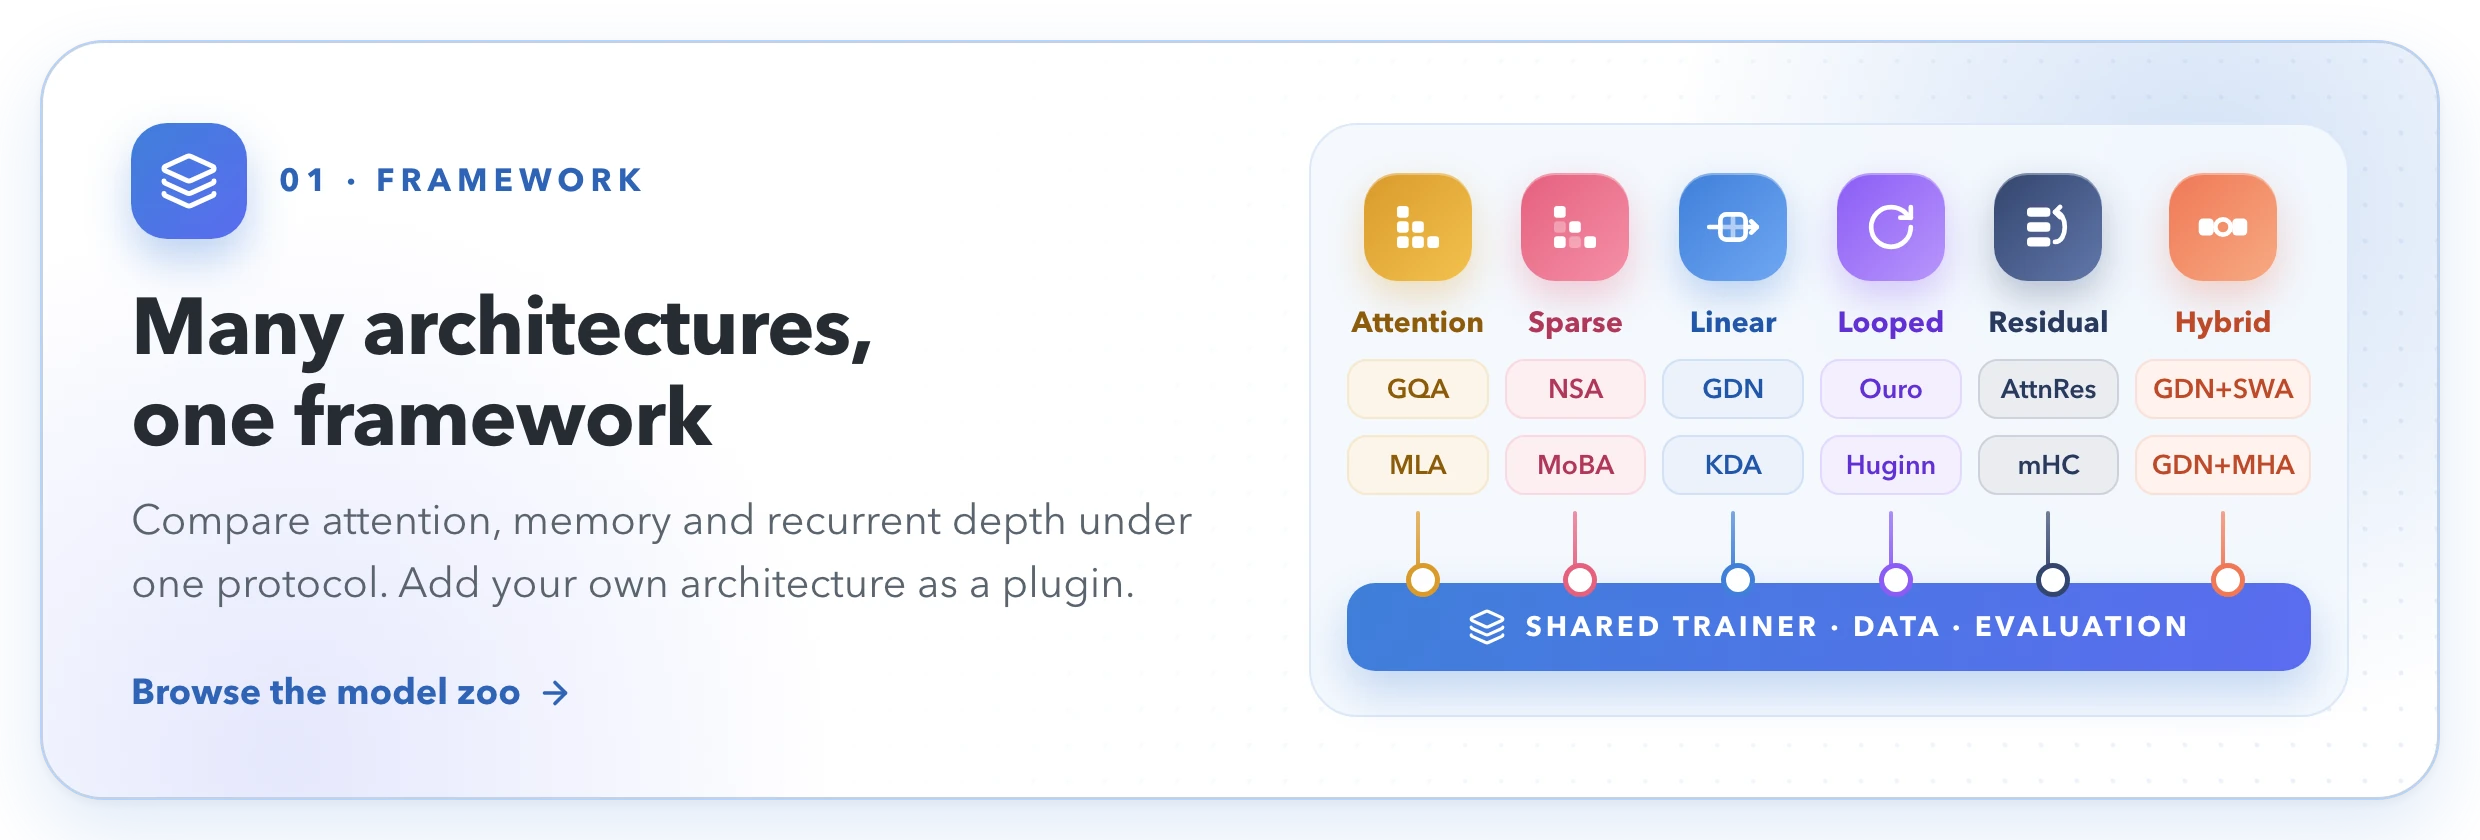
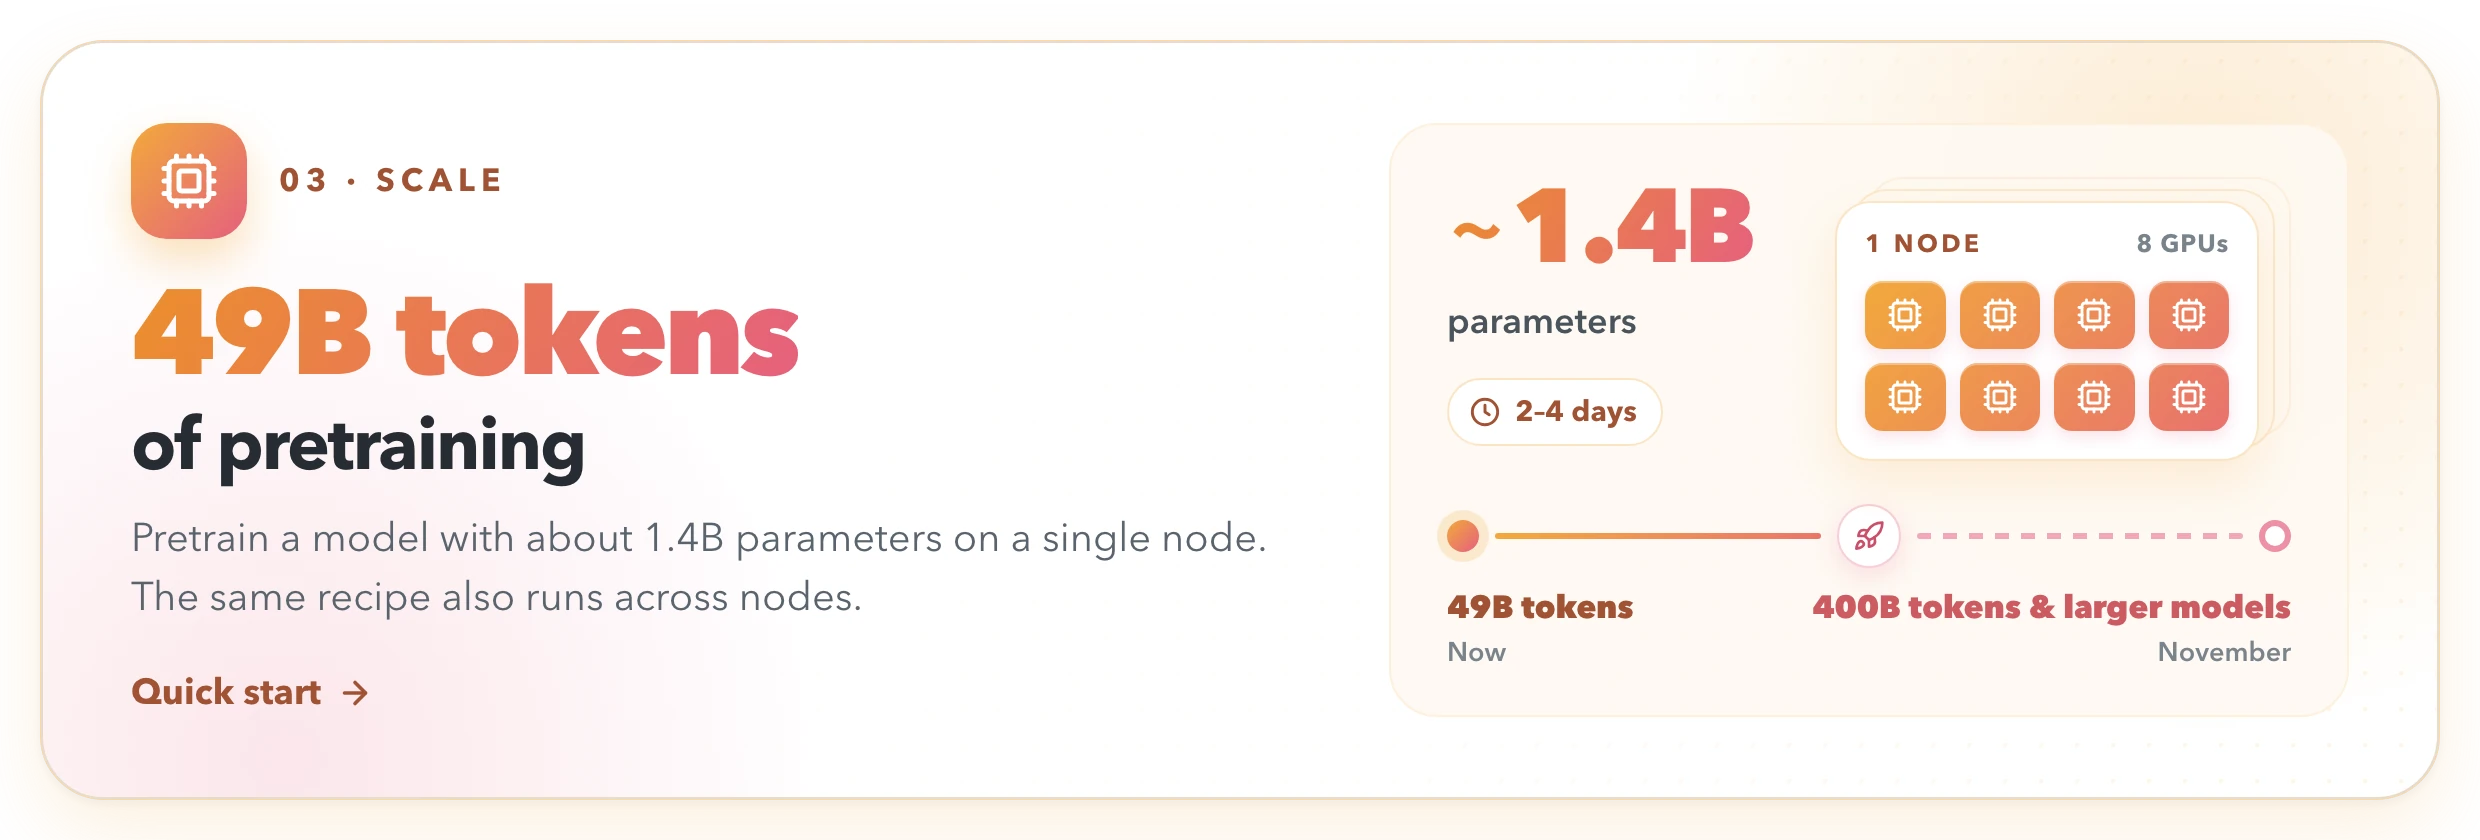
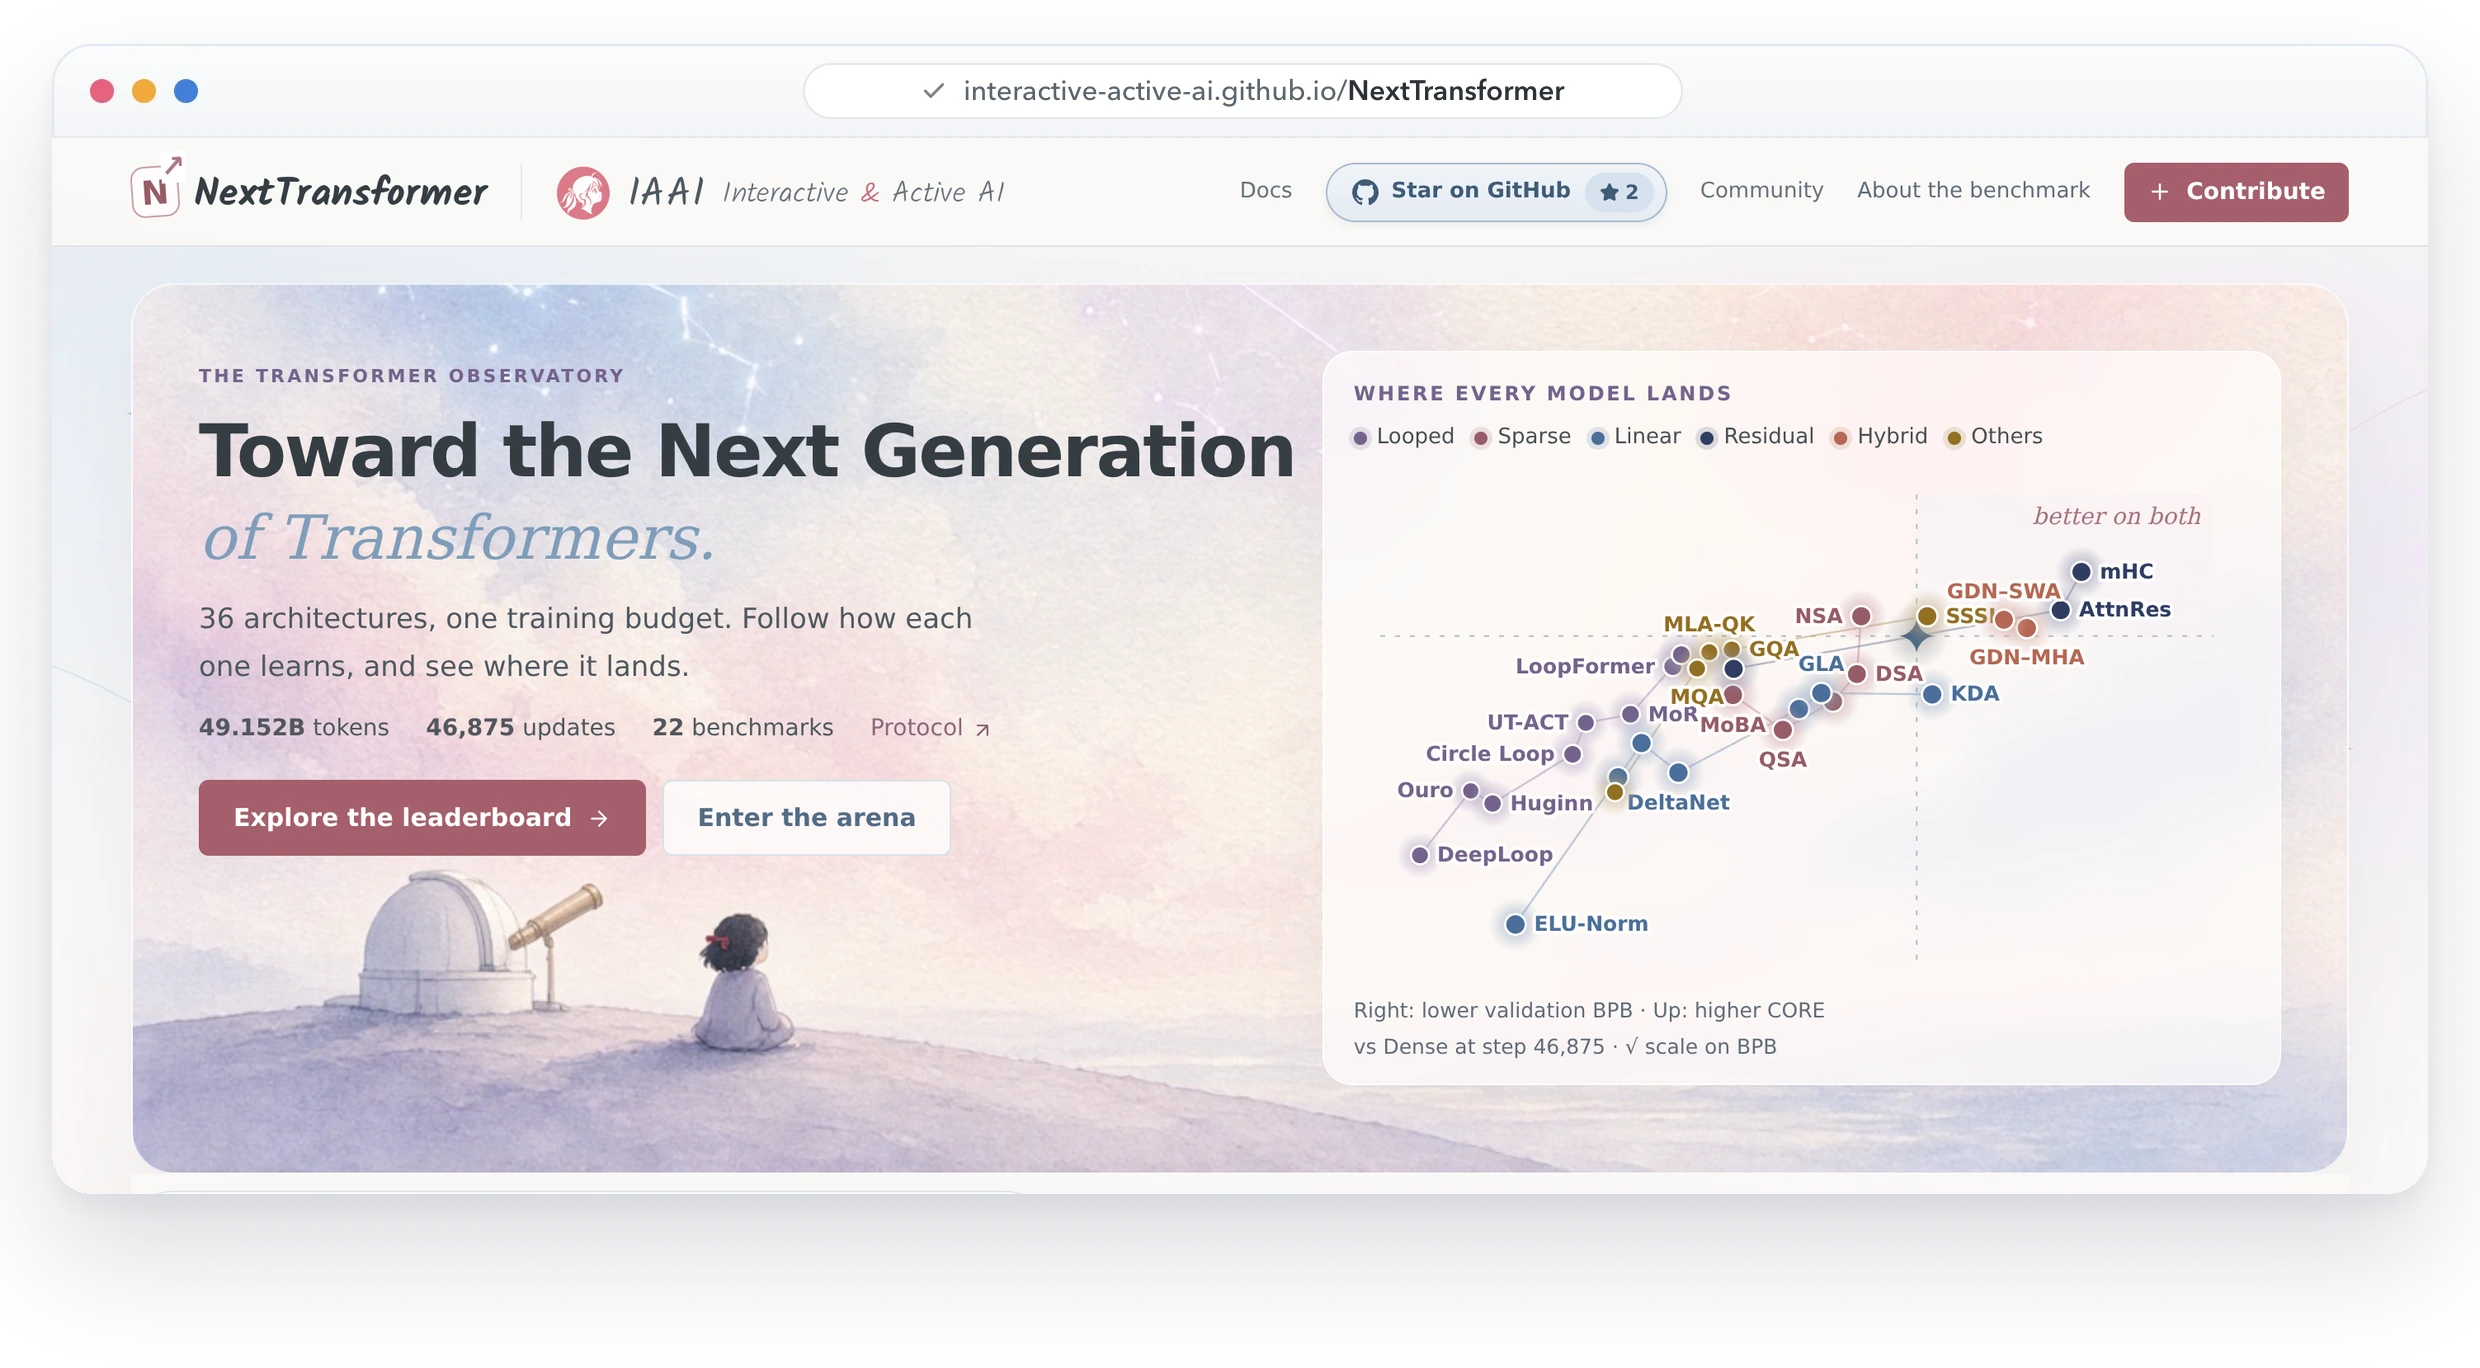
Learning curves of every run, a replayable leaderboard, all 22 CORE tasks, architecture diagrams and model cards, in your browser.
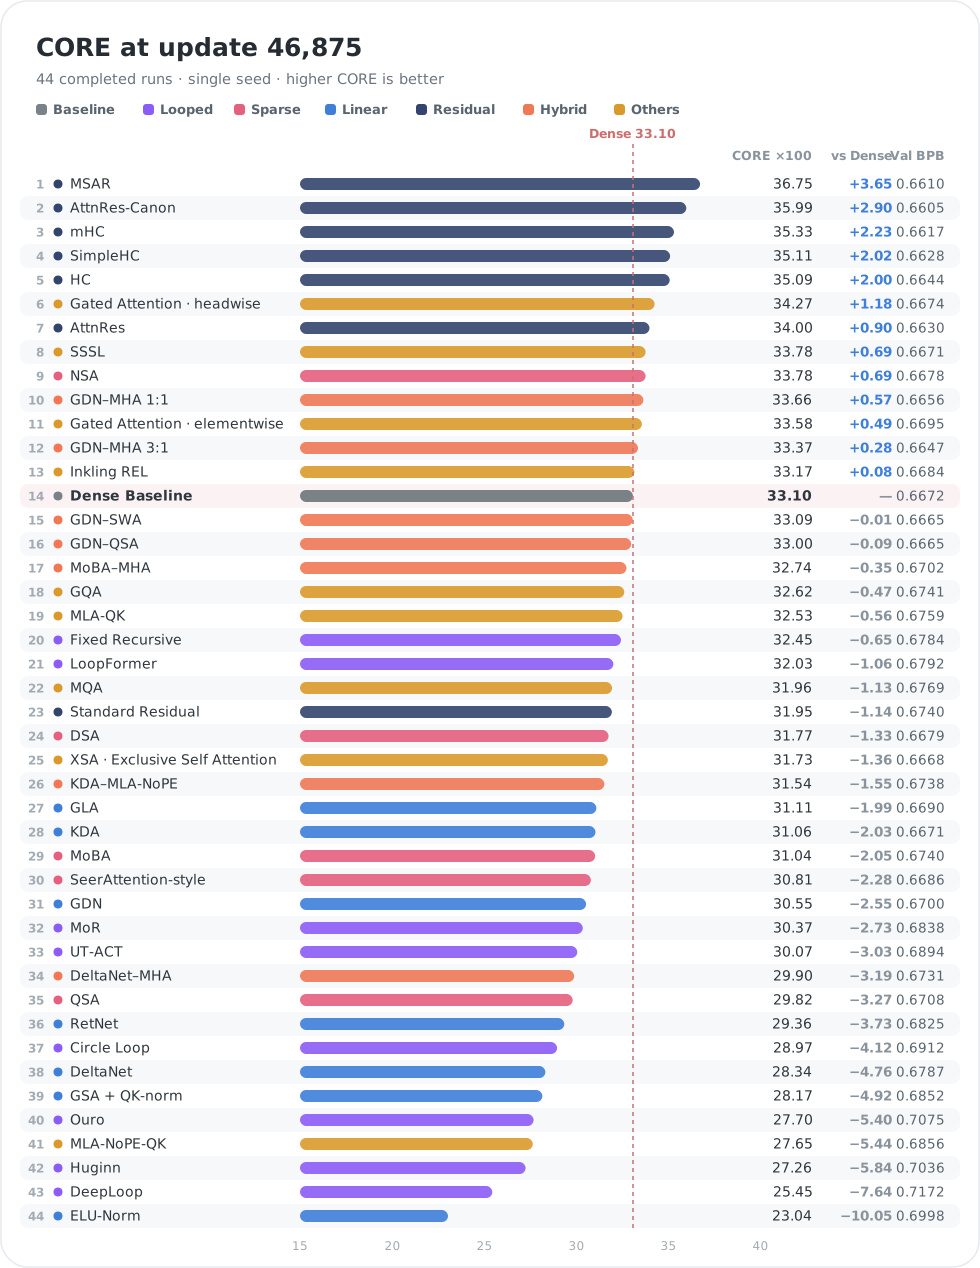
Full leaderboard · Training replay
1. Install (Linux, NVIDIA GPUs, uv):
git clone https://github.com/Interactive-Active-AI/NextTransformer.git && cd NextTransformer
uv sync --frozen --extra gpu --extra upstream && source .venv/bin/activate
uv pip install --no-deps --require-hashes -r requirements/linear.txt   # linear-attention kernels
2. Prepare the data (ClimbMix at a pinned revision, about 600 GB, plus the tokenizer and CORE bundle):
cp site.native.example.json site.local.json        # set runtime_dir, resources and data_dir
hf download karpathy/climbmix-400b-shuffle --repo-type dataset \
  --revision 915333b4f8b8684f39aeaafea600fea6f43fb703 --local-dir /path/to/climbmix-400b-shuffle
source launch/env.sh --site-config site.local.json
python -m nexttransformer.prepare --site-config site.local.json
3. Train on one node with 8 GPUs:
launch/train.sh --config configs/baseline/dense_full.json --site-config site.local.json \
  --output runs/dense_full --micro-batch 8 --formal --resume auto
4. Multi-node training (2 nodes × 8 GPUs)
Install uv pip install accelerate==1.15.0 in the training environment. Submit one distributed job with the following per-node entry point. Map the platform's node rank, main node address and port to the three variables shown:
export FLA_DISABLE_BACKEND_DISPATCH=1   # registered FLA Triton path (linear and hybrid methods)
accelerate launch --config_file launch/accelerate.yaml \
  --machine_rank "$NODE_RANK" --main_process_ip "$MASTER_ADDR" --main_process_port "$MASTER_PORT" \
  -m nexttransformer.train --config configs/linear/gdn.json --site-config site.local.json \
  --output runs/gdn --micro-batch 16 --formal
On Slurm, submit sbatch launch/slurm.sbatch for the same example. The batch script gets the launch parameters from the allocation. Cluster setup and other node counts
Evaluation runs on schedule during training. The quick start guide covers smoke tests, evaluation, auditing and exporting a result.
The NextTransformer organization on Hugging Face is the home for model weights. Check its Models tab for available downloads. The leaderboard lists evaluated runs, including those whose weights have not yet been released.
Contributor-hosted weights: AttnRes-Canon (49B comparison) · Dense (200B-token scaling run).
| Family | Models |
|---|---|
| Dense Baseline | |
| Standard Residual · AttnRes · HC · mHC · MSAR · AttnRes-Canon · SimpleHC | |
| UT-ACT · Fixed Recursive · Huginn · Ouro · DeepLoop · MoR · LoopFormer · Circle Loop | |
| DSA · QSA · NSA · SeerAttention-style · MoBA | |
| DeltaNet · GSA + QK-norm · GLA · KDA · RetNet · ELU-Norm · GDN | |
| GDN–MHA 3:1 · GDN–MHA 1:1 · GDN–SWA · DeltaNet–MHA · KDA–MLA-NoPE · GDN–QSA · MoBA–MHA | |
| SSSL · MQA · GQA · MLA-QK · MLA-NoPE-QK · Gated Attention · elementwise · Gated Attention · headwise · XSA · Exclusive Self Attention · Inkling REL |
* Results coming soon. Papers, adaptations and configurations are in the model zoo.
| Data | ClimbMix at a pinned revision · one 32,768-token tokenizer · 2,048-token context · one global sample order |
| Budget | 49.152B input tokens · 46,875 updates of 1,048,576 tokens · seed 42 |
| Compute | 4.672 GFLOPs per input token (forward, backward, auxiliary and optimizer work); ±1% at admission, ±2% over the run |
| Evaluation | Validation BPB at 189 points · full CORE-22 at six checkpoints · an independent final BPB |
| Baseline | Dense: full causal attention in every layer, trained under the same budget |
Parameters, memory and speed are outcomes, not controls. The protocol explains every rule and the compute accounting what is counted.
New methods and Arena entries follow the same submission process.
--formal run.main with the implementation and result. Link the proposal issue.Start with the plugin guide and CONTRIBUTING.md.
Note
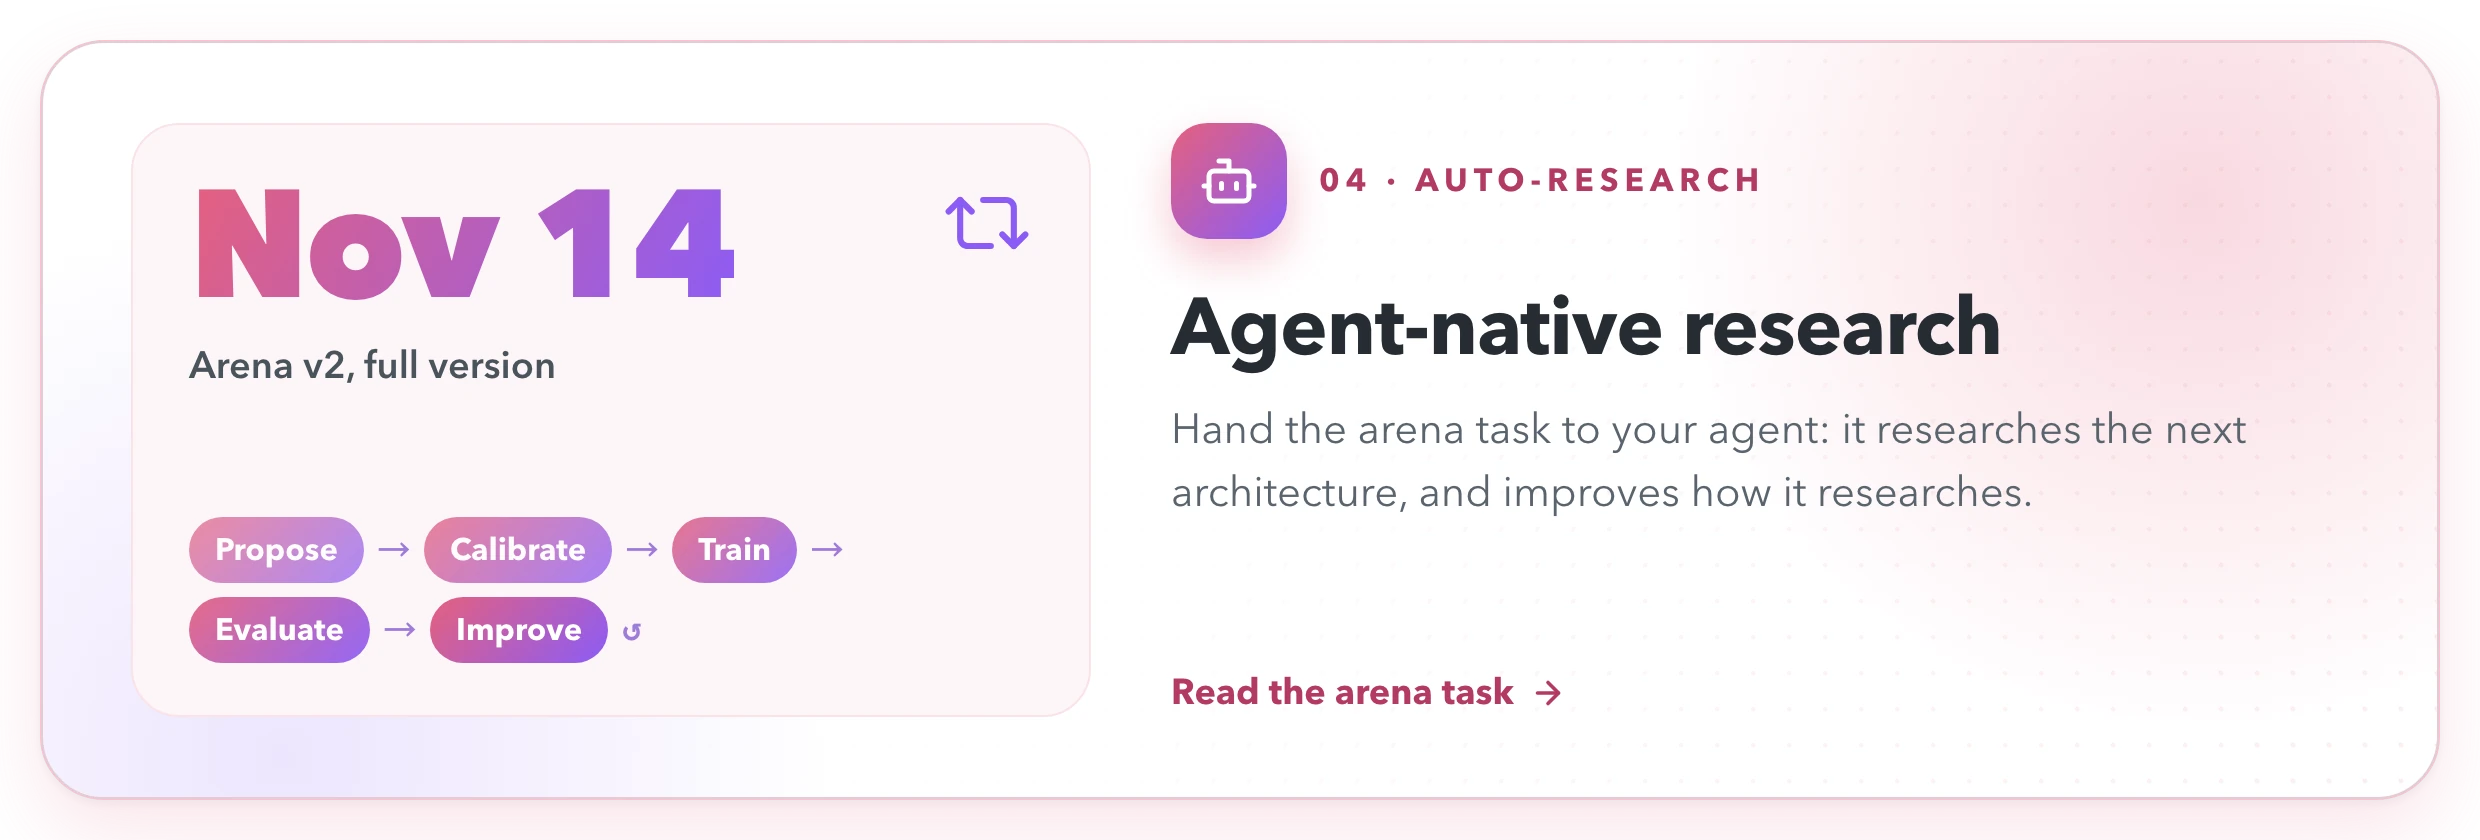
The arena is in active development. Arena v2, with full support for autonomous agent research (a research gym with MCP tools, metered compute, research traces and self-improving research loops), ships by November 14, 2026.
Any LLM, with or without a research framework, can already enter an architecture today: it is trained under the same protocol, ranked on the same leaderboard, and disclosed with how it was found. See the arena.
Community projects that extend NextTransformer.
by @Enderfga Every NextTransformer method on frozen SigLIP2 image tokens interleaved with text at an 8,192-token context, compute-matched within 1%. Its first study, pre-registered, asks where hybrid backbones read the 2D layout of an image. |
by AI4AI for Anything, contributed by @henry-y An agent that profiles, optimizes and validates AI training code. It contributed NextTransformer's opt-in |
Your project hereBuilt something on NextTransformer's code or protocol? Share it in Show and tell or open a pull request that adds a card with a wide banner image. Listed projects are public and say in their README that they build on NextTransformer. |
More on the roadmap.
Contributions are welcome; please read CONTRIBUTING.md and the code of conduct. Community projects are listed under Built on NextTransformer.
@software{nexttransformer2026,
  title   = {NextTransformer: An Open Framework and Fair Benchmark for Next-Generation Transformer Architectures},
  author  = {{NextTransformer contributors}},
  year    = {2026},
  version = {0.1.0},
  url     = {https://github.com/Interactive-Active-AI/NextTransformer}
}
NextTransformer builds on nanochat and ideas from modded-nanogpt, uses flash-linear-attention kernels, and trains on ClimbMix. We thank the authors of every method in the zoo. Released under the MIT License; see third-party notices.
Interactive-Active-AI/NextTransformer is a public repo on GitHub by Interactive-Active-AI. :sunrise: A comprehensive, cutting-edge open-source framework for next-generation Transformers/LLM, with compute-matched benchmarking and a platform for autonomous architecture research.
It declares the MIT license on GitHub.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Its last change on GitHub was on 2026-11-20. Take My Repo does not judge from that whether it is maintained.
The control plane for 24/7 always-on agents. Turn long-horizon goals into verifiable results across Codex, Claude Code, and custom runtimes—from local SQLite to team scale.
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.
🌸 Run LLMs at home, BitTorrent-style. Fine-tuning and inference up to 10x faster than offloading
RWKV (pronounced RwaKuv) is an RNN with great LLM performance, which can also be directly trained like a GPT transformer (parallelizable). We are at RWKV-7 "Goose". So it's combining the best of RNN and transformer - great performance, linear time, constant space (no kv-cache), fast training, infinite ctx_len, and free sentence embedding.
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
:mount_fuji: OneWM: Can World and Action Modeling Benefit Each Other under Unified Causal Training?
An open, visual atlas of looped transformers, recurrent computation, adaptive depth, and latent reasoning.