SpargeAttn
[ICML2025] SpargeAttention: A training-free sparse attention that accelerates any model inference.
- 1.3k
- Cuda
- Apache-2.0
- 9 mo ago
[ICML2025] SpargeAttention: A training-free sparse attention that accelerates any model inference.
Trainable fast and memory-efficient sparse attention
[NeurIPS 2025] Radial Attention: O(nlogn) Sparse Attention with Energy Decay for Long Video Generation
SLA: Beyond Sparsity in Diffusion Transformers via Fine-Tunable Sparse–Linear Attention
:sunrise: A comprehensive, cutting-edge open-source framework for next-generation Transformers/LLM, with compute-matched benchmarking and a platform for autonomous architecture research.
Speed Always Wins: A Survey on Efficient Architectures for Large Language Models
Efficient triton implementation of Native Sparse Attention.
NVIDIA Sol-Attn for ComfyUI / Triton kernel on SM89 - SM121, with zero-copy MiniMax H3 nodes: memory-efficient attention, scheduled tau with graph preview, and feed-forward chunking. Measured 1.14–1.44× vs SageAttention and −37% MLP peak VRAM on H3
🦀 Decoder-only LLM built from scratch in pure Rust using Candle — no Python, no PyTorch. Gated DeltaNet + sparse attention, fine-grained MoE, native video/document understanding, long-horizon tool agents, quantization-aware training. Scales: Tiny (25M) to Large (1.3B).
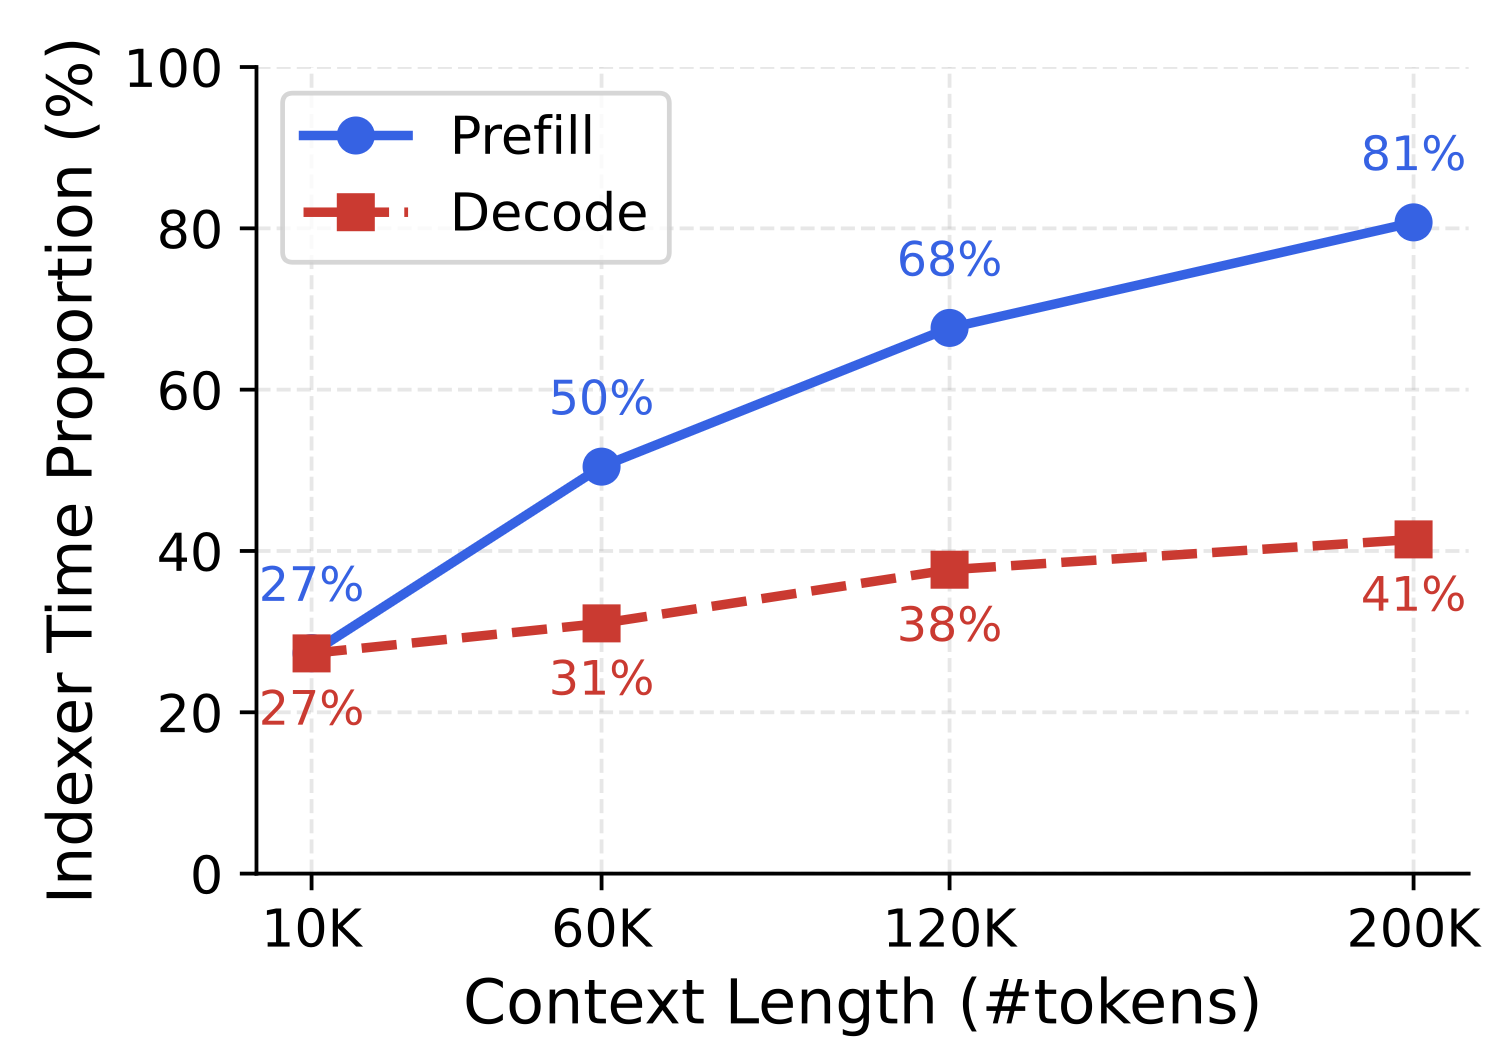
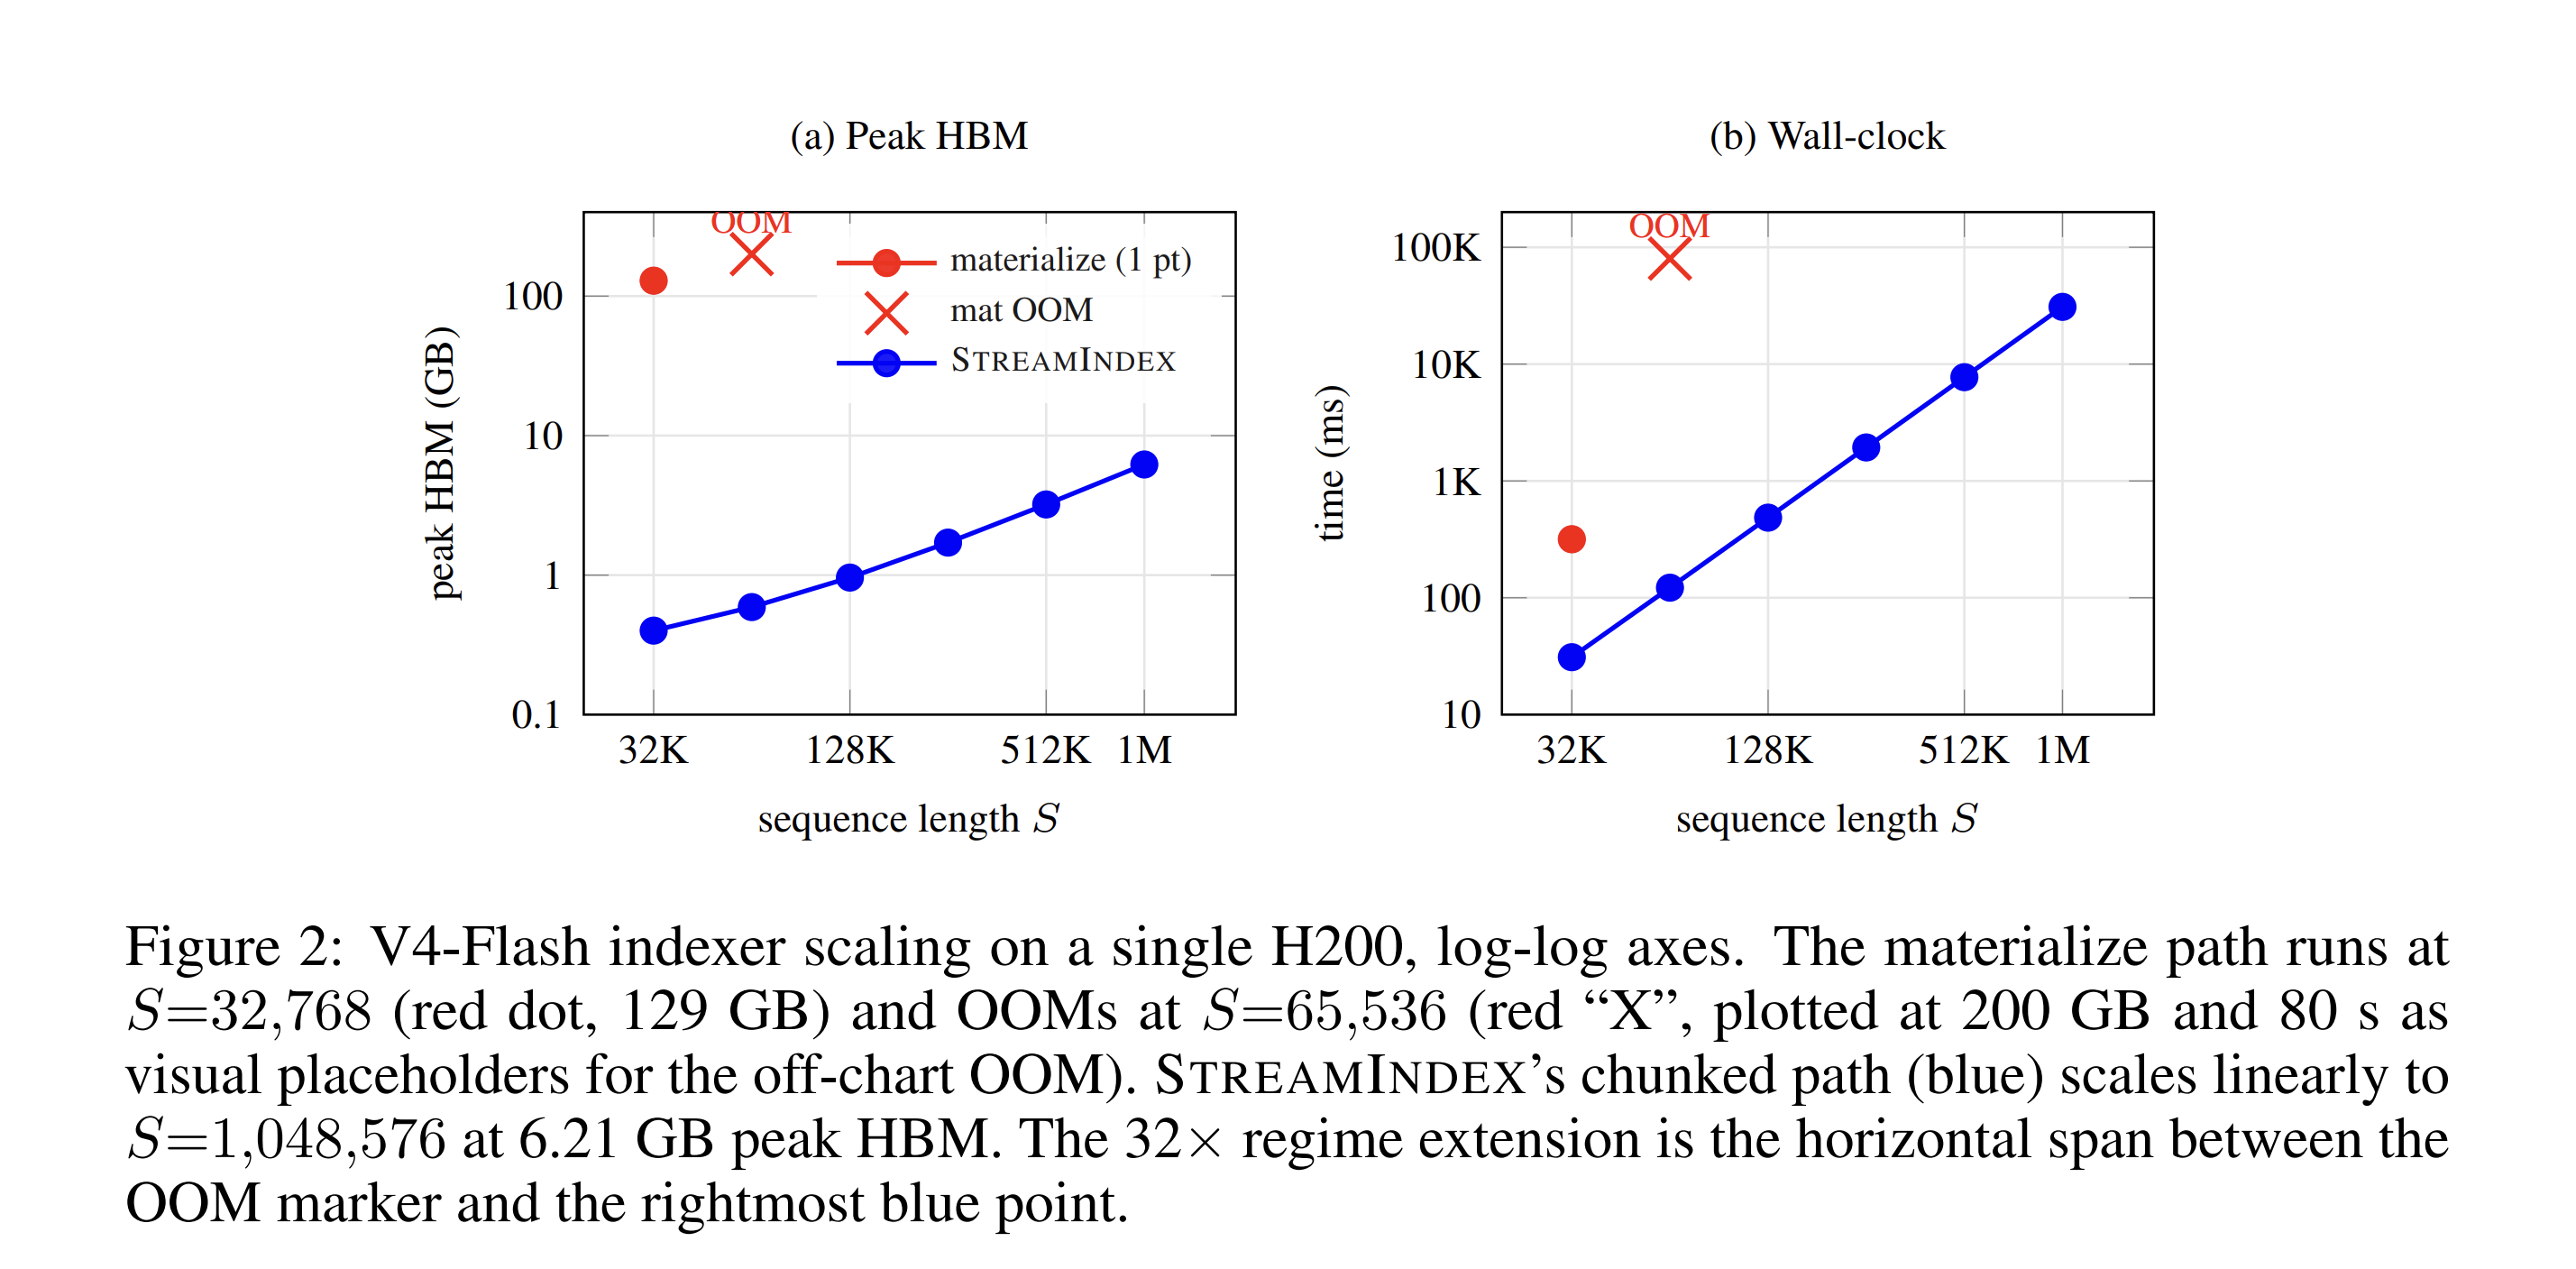
Memory-bounded compressed sparse attention via streaming top-k. Triton kernels for the DeepSeek-V4 lightning indexer. 32x regime extension on a single H200 | by RightNow https://www.rightnowai.co/
Demo code for CVPR2023 paper "Sparsifiner: Learning Sparse Instance-Dependent Attention for Efficient Vision Transformers"
Deterministic sparse-index localization for Apple silicon (MLX/Metal) and CUDA/Triton, with stable ordering, a Python oracle, and reproducible evidence.
QSA HiSparse as an SGLang plugin: 256K CPU KV offload and text/image host prefix reuse for Qwen Sparse Attention on unmodified SGLang
DeepSeek-V4.1-Flash 源码研读:官方参考实现 + 架构笔记(CED/CSA2/mHC/Engram/DSpark/FP4 KV)
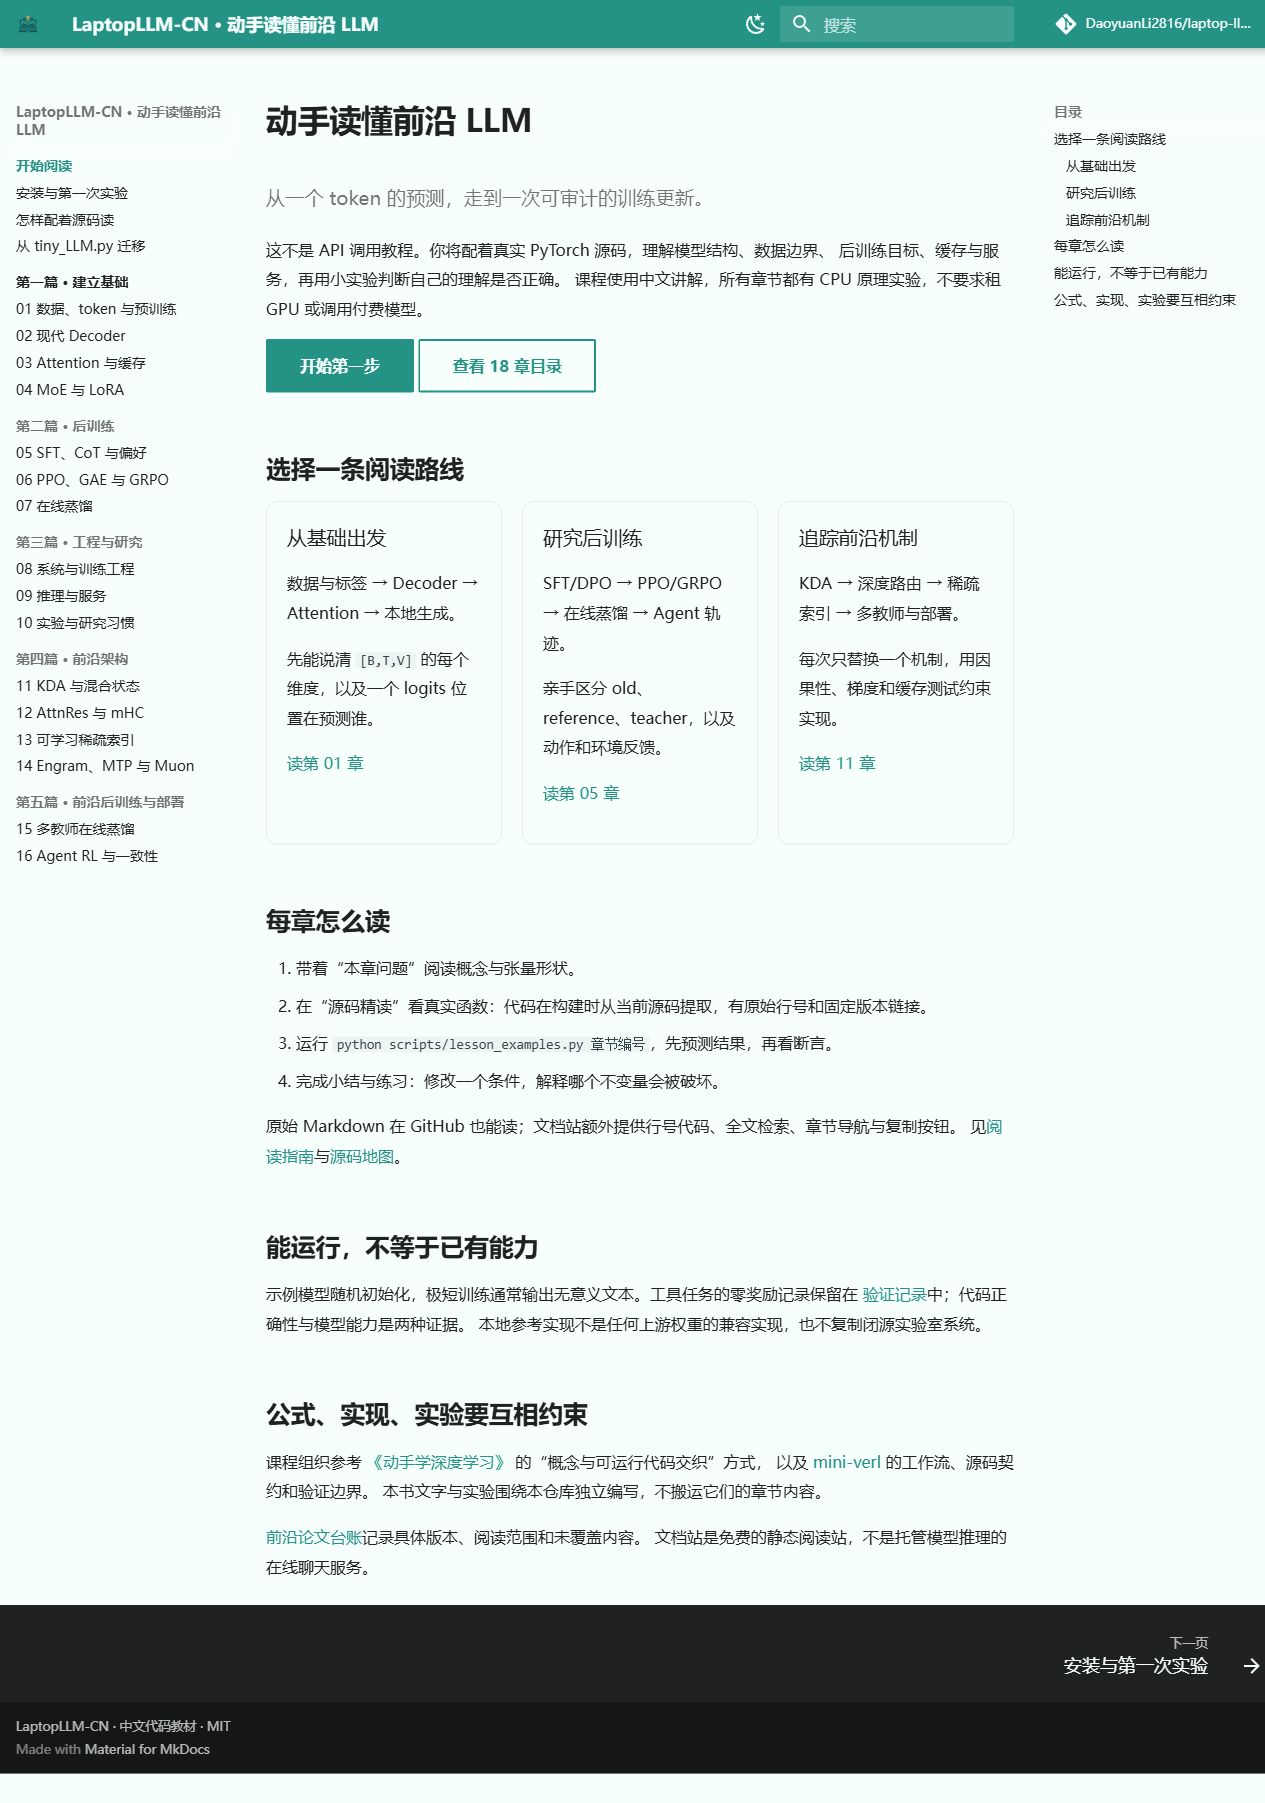
前沿 LLM 中文代码教材:KDA、AttnRes、MSA、mHC、Engram、MTP、Muon、Agent RL、多教师蒸馏、FP4 与本地 Serving · 18 章课程 · 无需云资源