
CoMLRL
Open-Source Library for Cooperative Multi-LLM Reinforcement Learning
- 250
- BSD-3-Clause
- 12 d ago
Repo OpenMLRL/CoMLRL, read from GitHub 3 h ago. OpenMLRL has not joined Take My Repo.
In short
OpenMLRL/CoMLRL is a public repo on GitHub by OpenMLRL. Open-Source Library for Cooperative Multi-LLM Reinforcement Learning. It declares the BSD-3-Clause license on GitHub. It is written mainly in Python, has 250 stars and last changed on 2026-11-10. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-22.

Cooperative Multi-LLM Reinforcement Learning (CoMLRL) is an open-source library for training multiple LLMs to collaborate using Multi-Agent Reinforcement Learning (MARL). It provides implementations of various MARL algorithms for LLM collaboration and support for different environments and benchmarks.

Installation
CoMLRL can be installed from PyPI, conda-forge, or source and supports Python 3.10 or later. Users should also install a PyTorch build compatible with their device.
git clone https://github.com/OpenMLRL/CoMLRL.git
cd CoMLRL
pip install comlrl # install from PyPI
conda install -c conda-forge comlrl # install from conda-forge
pip install -e . # install from source in editable mode
Features
-
Cooperative trainers for LLM collaboration:
- Multi-Agent REINFORCE: Critic-free policy gradient methods, including MAREINFORCE, MAGRPO, MARLOO, MAREMAX.
- Aligned individual response joint with
joint_mode='aligned'. - Cartesian-product joint responses with
joint_mode='cross'. - Decentralized actors or a centralized actor with
collaboration_mode='centralized'.
- Aligned individual response joint with
- Multi-Agent Actor-Critic: Actor-Critic methods, including IAC and MAAC.
- Independent actor-critic (separate critic or value-head over LLM backbone).
- Centralized critic over joint prompts with separate actors.
- Decentralized actors or a centralized actor with
collaboration_mode='centralized'.
- Multi-Agent Preference Learning: MADPO, MARLHF, and their iterative variants.
- Direct joint preference optimization or learned joint rewards followed by RL.
- Decentralized actors or a centralized actor generating a complete joint response.
- Multi-Agent REINFORCE: Critic-free policy gradient methods, including MAREINFORCE, MAGRPO, MARLOO, MAREMAX.
-
Environments that simulate real-world tasks for training and evaluating LLM collaboration:
- Writing: Multiple LLM agents collaborate on processing articles.
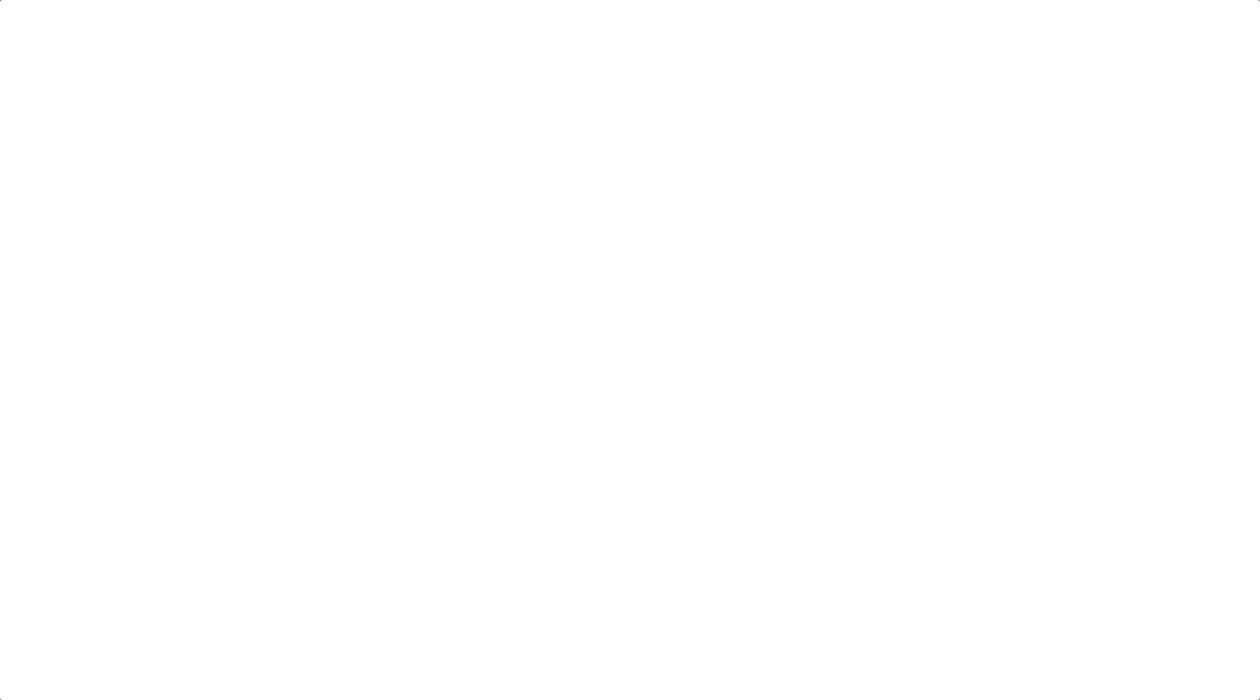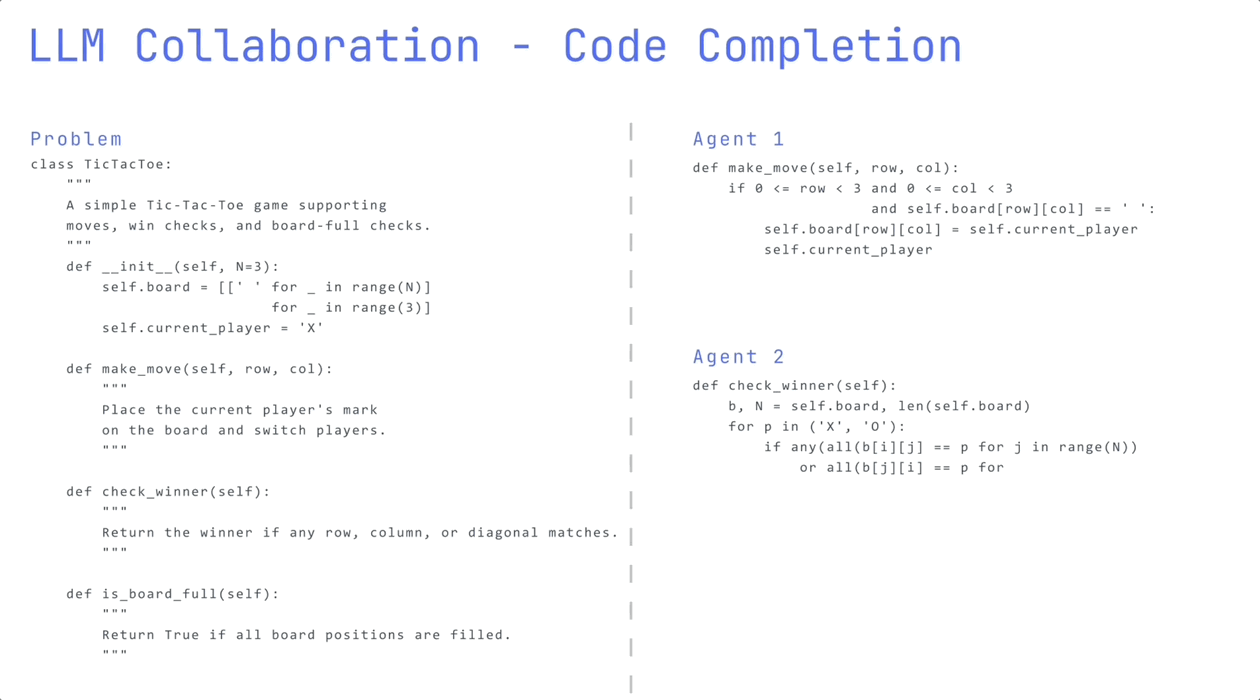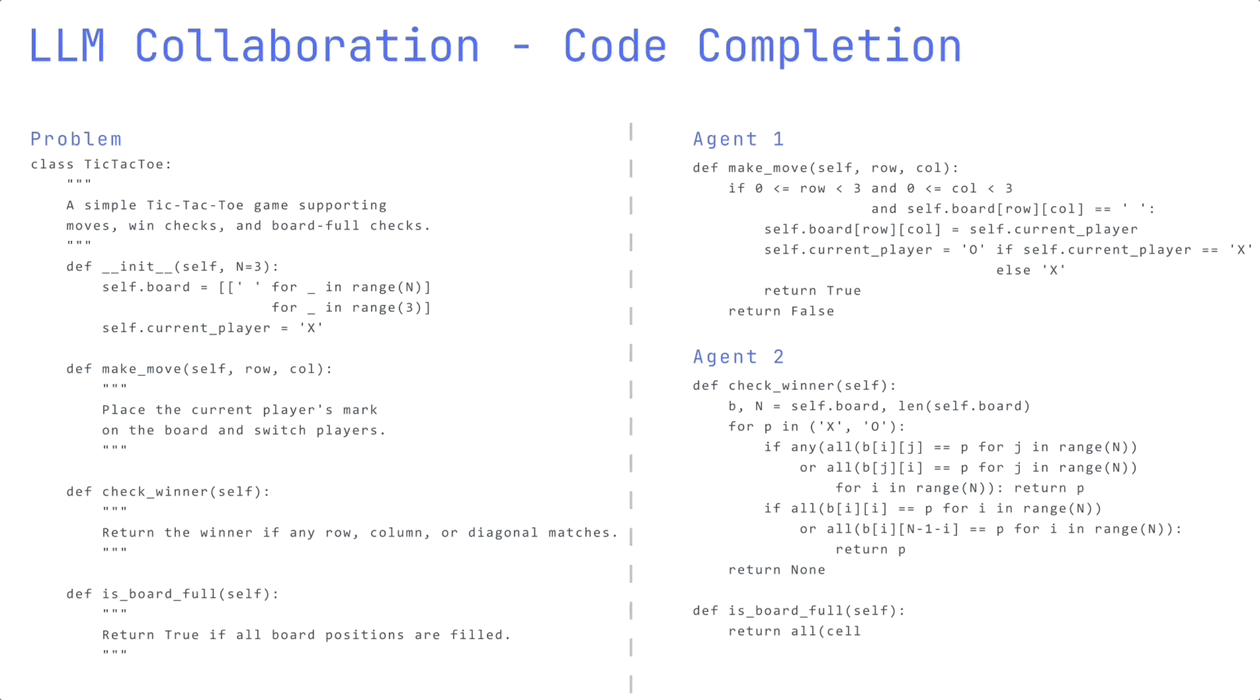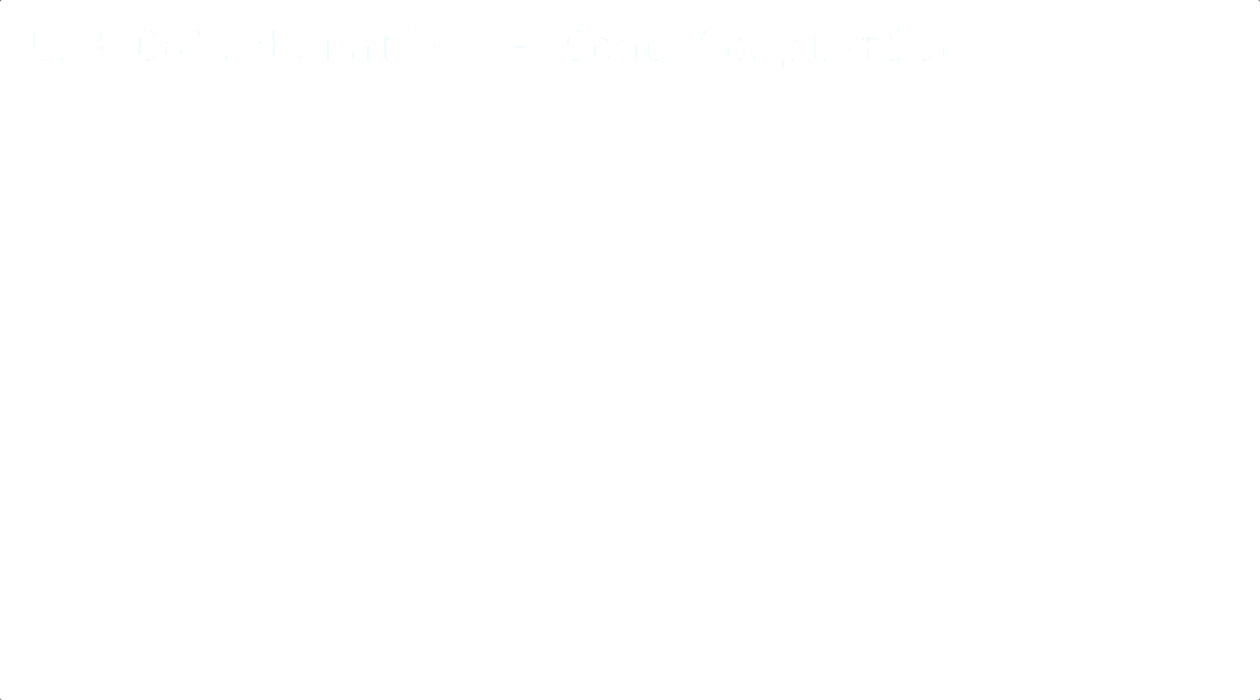
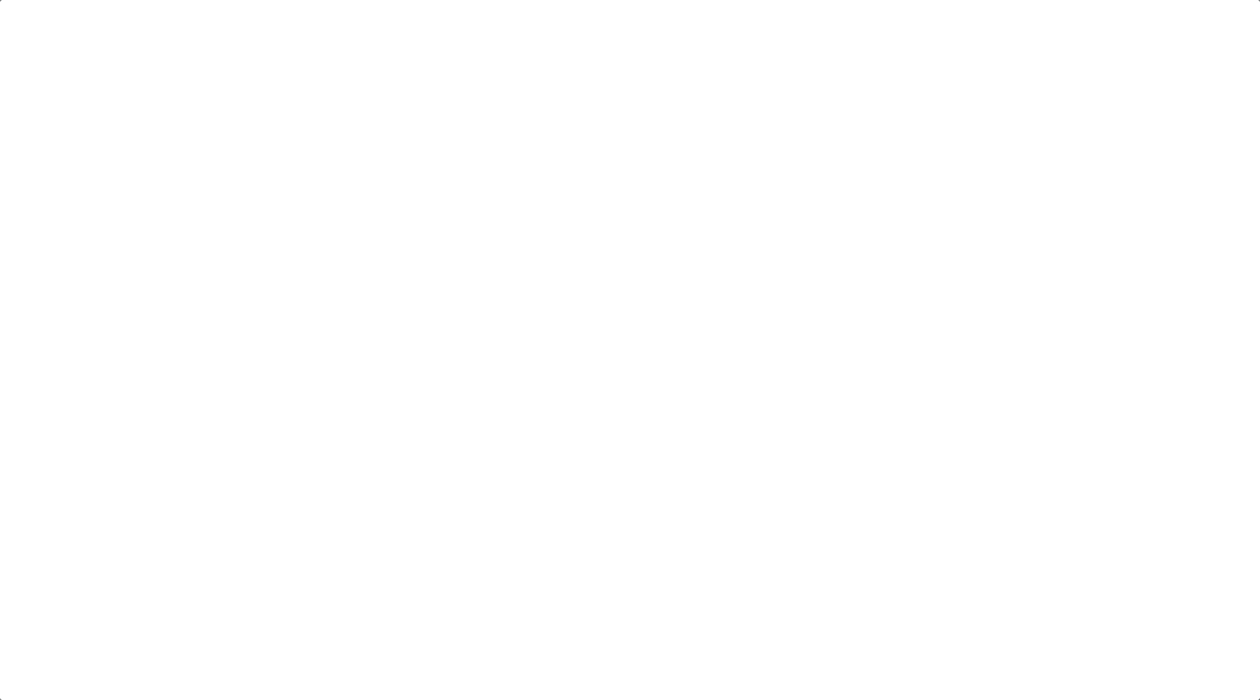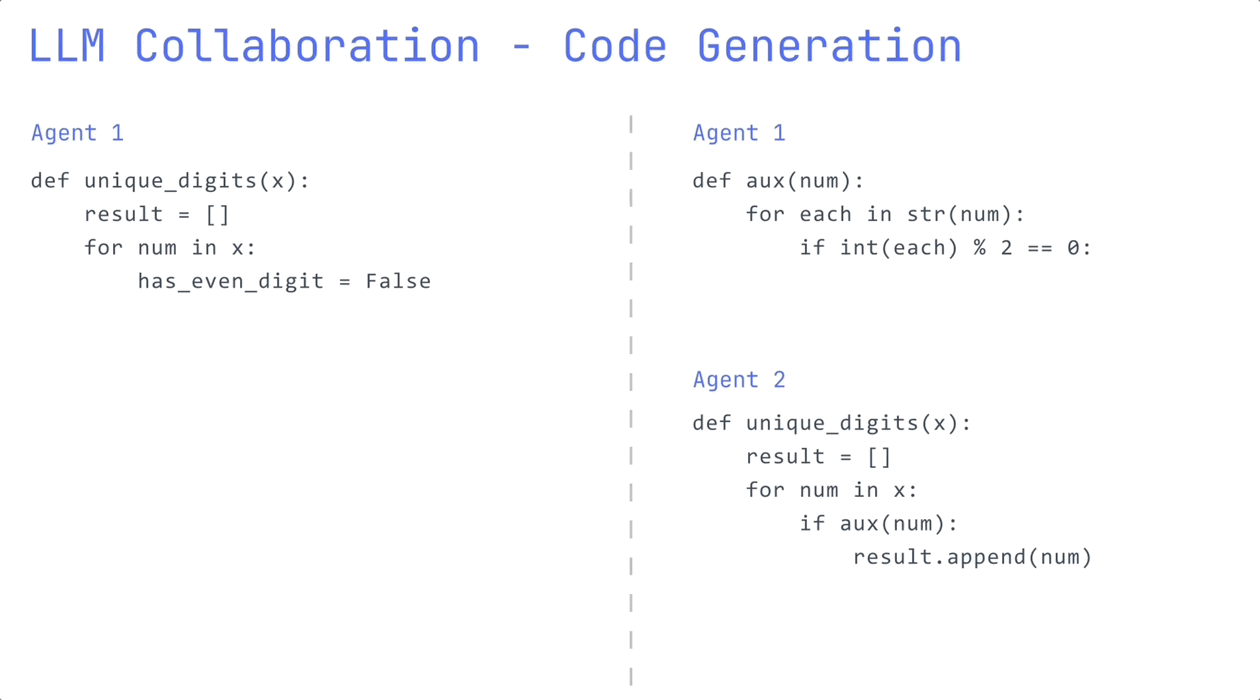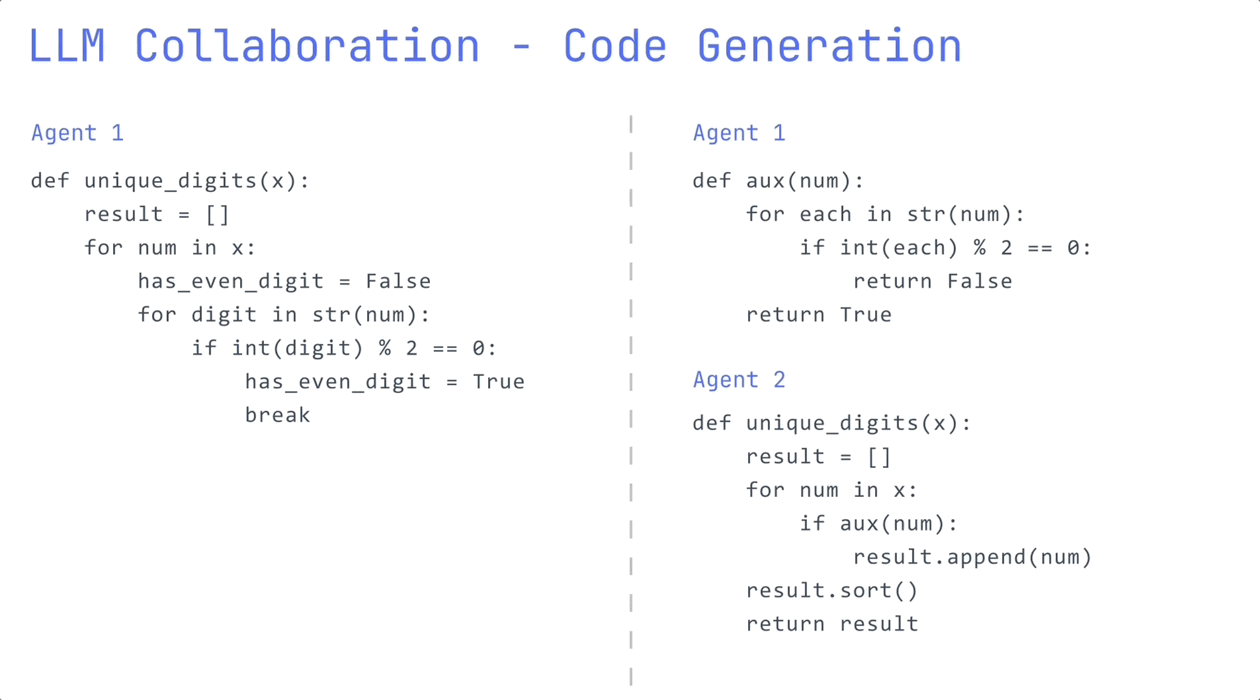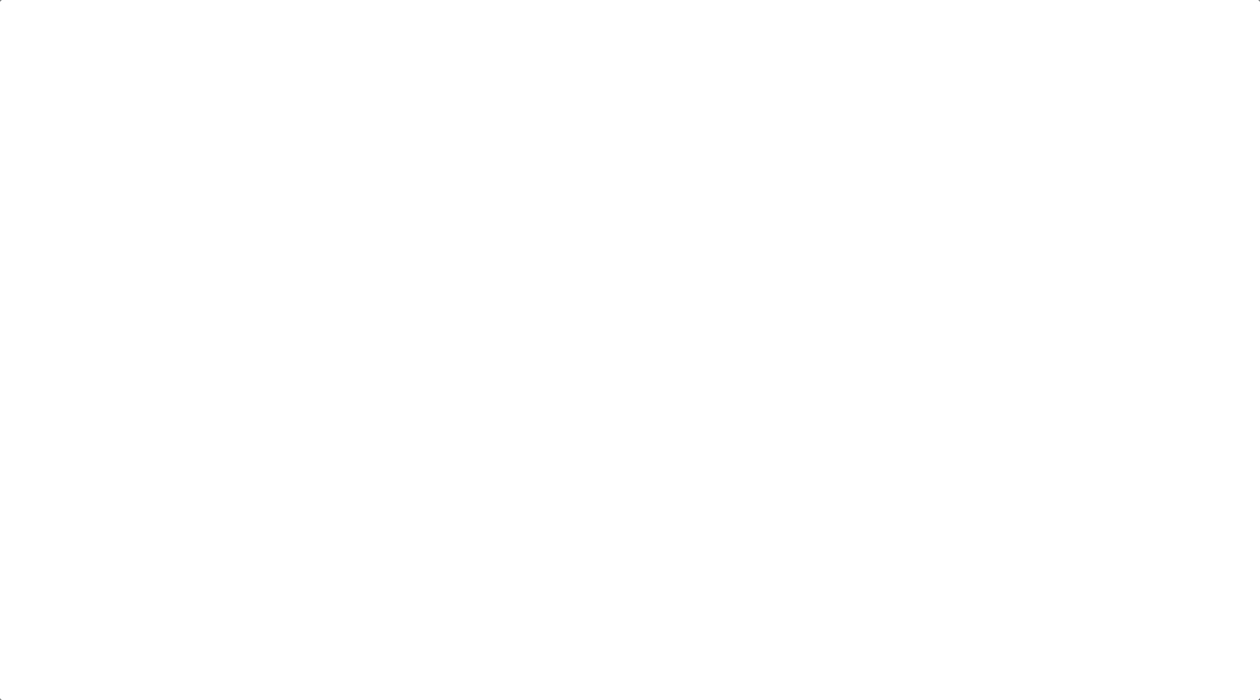
- Coding: Generate code solutions for programming problems.
- MBPP - Mostly basic python problems.
- HumanEval - Handwritten evaluation problems.
- CoopHumanEval - HumanEval with cooperative nature.
- ClassEval - Complete class-level code based on attributes and docstrings.
- Travel: Collaborative travel planning under user constraints.
- TravelPlanner - Planning multi-day trip itineraries.
- Tool-Use: Collaborative function calling with tools using BFCL v4.
- Native Parallel - Making parallel function calls.
Usage
Quick start by training two Qwen-2.5 agents on Reddit prompts with MAGRPO. This toy reward encourages a 3:1 output-length ratio; it does not measure summary quality:
from datasets import load_dataset
from transformers import AutoTokenizer
from comlrl.trainers.reinforce import MAGRPOConfig, MAGRPOTrainer

# Load dataset and tokenizer
tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen2.5-0.5B")
dataset = load_dataset("trl-lib/tldr", split="train").select(range(128))

# Initialize trainer and start training
trainer = MAGRPOTrainer(
    agent_model="Qwen/Qwen2.5-0.5B",
    num_agents=2,
    tokenizer=tokenizer,
    train_dataset=dataset,
    reward_func=lambda a, b: [
        -abs(len(second) / max(len(first), 1) - 3.0)
        for first, second in zip(a, b)
    ],
    formatters=[lambda example: example["prompt"]] * 2,
    args=MAGRPOConfig(num_turns=1),
)
trainer.train()
Contributing
We thank the gracious help of all contributors:
 Shuo Liu 🤔 🚧 💻 📖 |
 Tianle Chen 🚧 💻 🐛 |
 Ryan Amiri 🚧 💻 🐛 |
 Danny Li 📖 🐛 |
 Zeyu Liang 📖 🐛 |
For new contributors, please see contributing guidelines on setting up a dev environment.
Sponsorship
CoMLRL was developed using substantial computational resources. Its growth has been made possible by the generous support of the following organizations and institutions.

We welcome computational sponsorship to support the continued development of CoMLRL. If you are interested in supporting this project, please contact us.
Citation
Please cite the following papers if you find this library useful in your research:
@inproceedings{liu2026llm,
  title={LLM Collaboration with Multi-Agent Reinforcement Learning},
  author={Liu, Shuo and Liang, Zeyu and Lyu, Xueguang and Amato, Christopher},
  booktitle={Proceedings of the AAAI Conference on Artificial Intelligence},
  volume={40},
  number={38},
  pages={32150--32158},
  year={2026}
}

@inproceedings{liu2026learning,
  title   = {Learning Decentralized LLM Collaboration with Multi-Agent Actor Critic},
  author  = {Liu, Shuo and Chen, Tianle and Amiri, Ryan and Amato, Christopher},
  booktitle={Proceedings of the International Conference on Machine Learning.},
  year    = {2026}
}

@article{liu2026improving,
  title={Improving LLM Collaboration via Multi-Agent Preference Learning},
  author={Liu, Shuo and Li, Xinzichen and Chen, Tianle and Amato, Christopher},
  journal={arXiv preprint arXiv:2609.32827},
  year={2026}
}
Questions
What is CoMLRL?
OpenMLRL/CoMLRL is a public repo on GitHub by OpenMLRL. Open-Source Library for Cooperative Multi-LLM Reinforcement Learning.
Is CoMLRL open source?
It declares the BSD-3-Clause license on GitHub.
Does CoMLRL run on macOS, Windows or Linux?
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
How do I install CoMLRL?
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Is CoMLRL still maintained?
Its last change on GitHub was on 2026-11-10. GitHub counts 3 open issues and pull requests. Take My Repo does not judge from that whether it is maintained.
What do people who ran CoMLRL say?
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.