LLM Collaboration – Writing
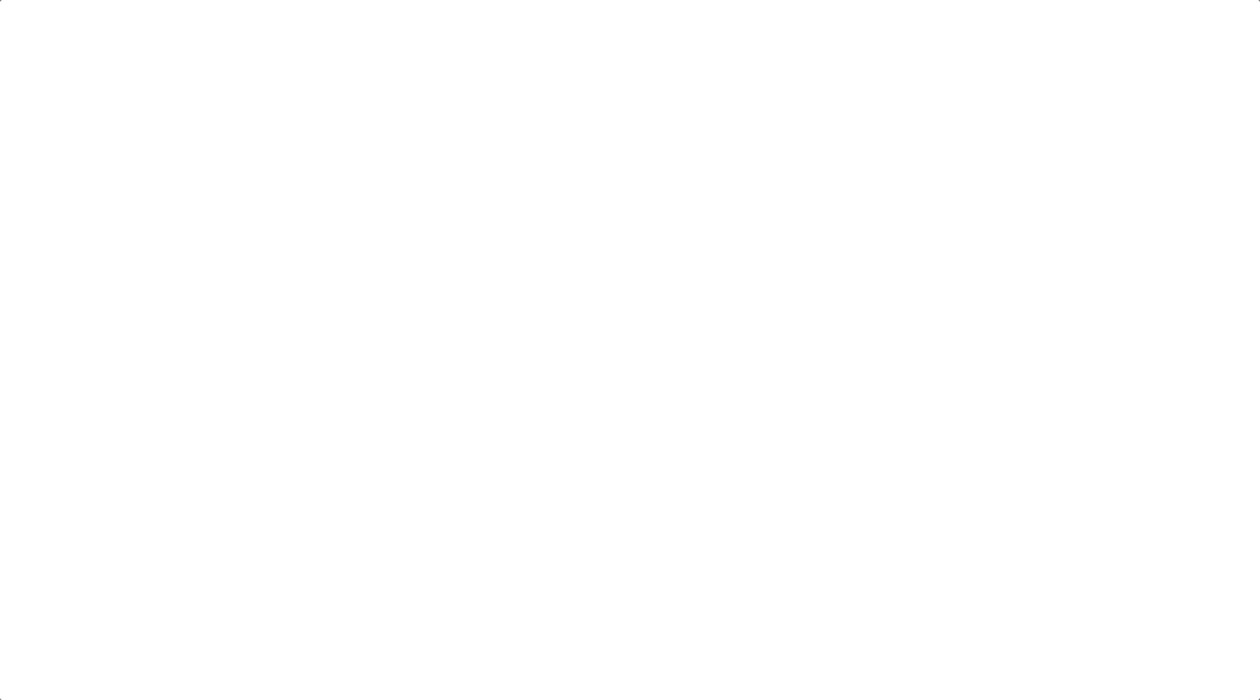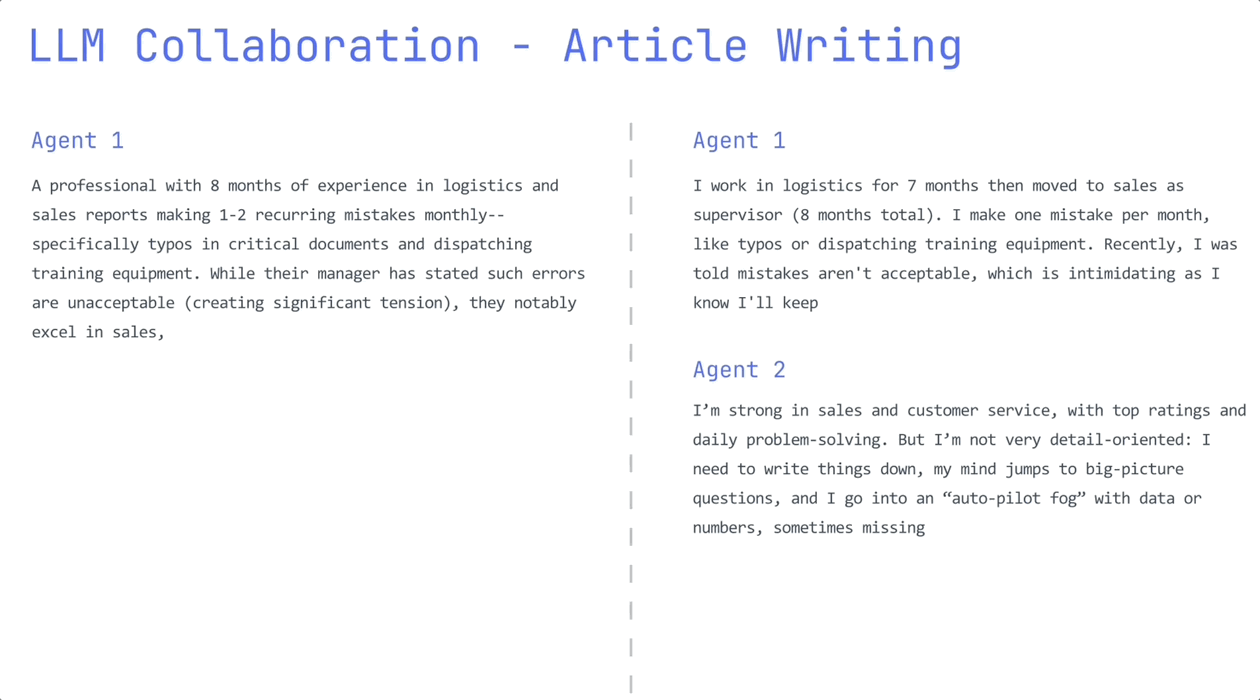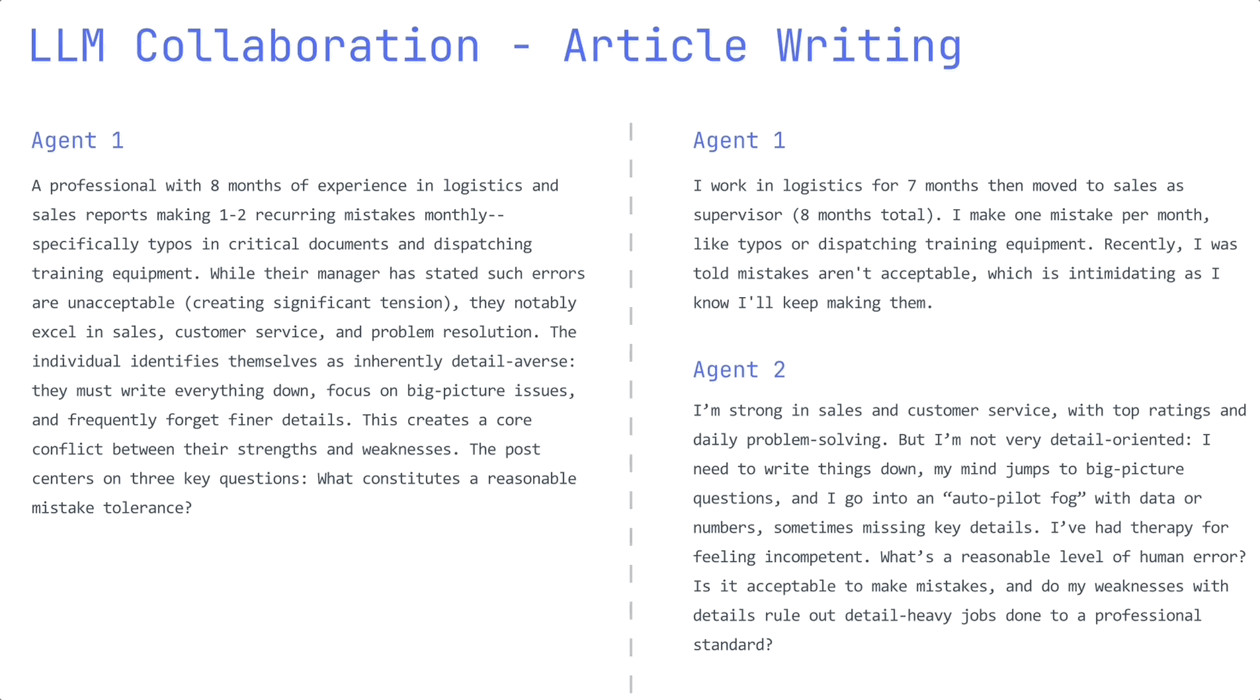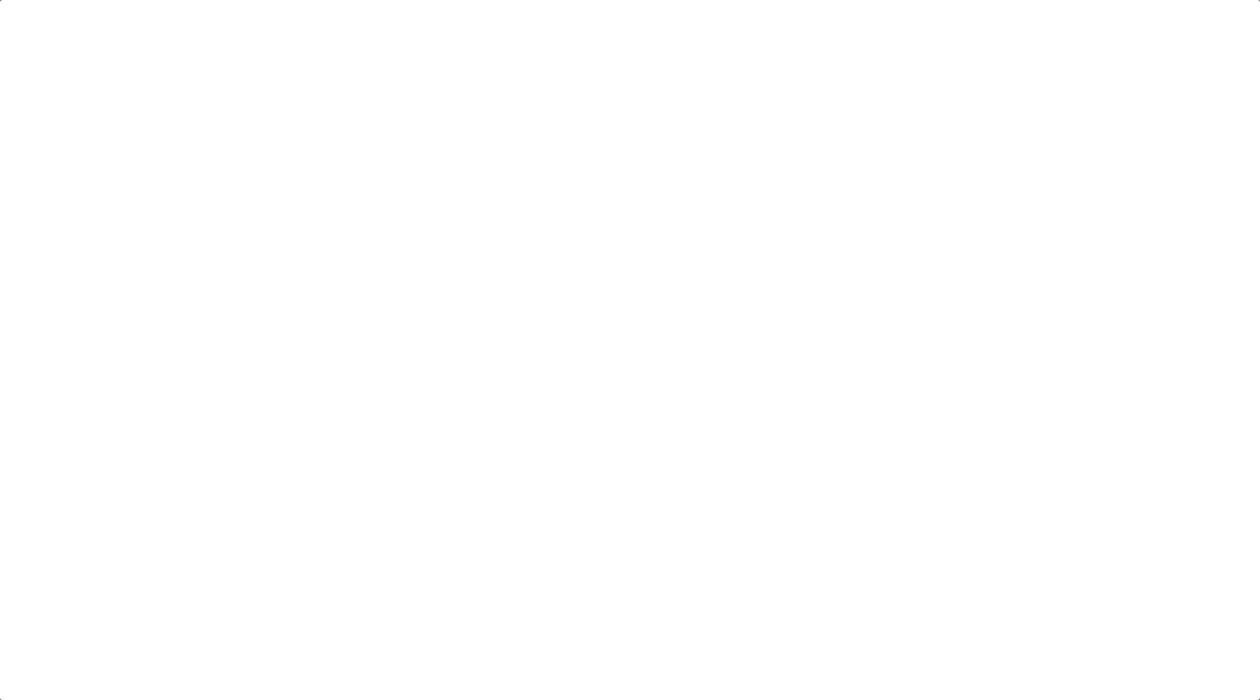
Writing environments for CoMLRL, used in the writing experiments of [AAAI26] LLM Collaboration with Multi‑Agent Reinforcement Learning. Two agents write complementary parts of a text and are trained with a shared reward.
Installation
CoMLRL can be installed from PyPI or conda-forge (conda install -c conda-forge comlrl). Users should also install a PyTorch build compatible with their device.
pip install comlrl
git clone https://github.com/OpenMLRL/LLM_Collab_Writing.git
cd LLM_Collab_Writing
A CoMLRL/ checkout next to this repository takes precedence over the installed package, so local CoMLRL changes are used without reinstalling.
Quick Start
The following command trains two agents with MAGRPO on TLDR summarization:
python train_magrpo.py --config configs/magrpo_tldr_config.yaml
Any configuration value can be changed with --override:
python train_magrpo.py --config configs/magrpo_tldr_config.yaml \
  --override agent_model.name='Qwen/Qwen3-4B' magrpo.agent_learning_rate=3e-6
Tasks
| Task |
Dataset |
Agent 1 |
Agent 2 |
| arXiv abstract expansion |
OpenMLRL/arXiv_abstract (train[:1000], val[:1000]) |
Background and motivation |
Methodology and implications |
| TLDR summarization |
trl-lib/tldr (train[:1000], test[:1000]) |
Concise summary |
Expansion with more details and varied vocabulary |
All runs are single-turn; configs that set num_turns to another value raise an error. The reward follows the paper's level-based metrics: structural token limits, relative length coordination, vocabulary diversity, and style mix (transition-word coverage and Jaccard overlap). The same functions back the evaluation loggers.
Training Scripts
Each script has an arXiv and a TLDR config in configs/, such as configs/madpo_iter_tldr_config.yaml. Without --config, the arXiv config is used.
| Script |
Method |
train_magrpo.py |
MAGRPO |
train_iac.py, train_maac.py |
IAC, MAAC |
train_madpo.py, train_madpo_iter.py |
MADPO and its iterative variant |
train_marlhf.py, train_marlhf_iter.py |
MARLHF and its iterative variant |
train_grpo.py, train_ac.py |
Single-agent GRPO and actor-critic baselines |
In the single-agent baselines, one agent writes both paragraphs, separated by [PARAGRAPH_SPLIT]. The iterative variants support current, history, local-model, and API comparators and several replay modes, as described in Multi-LLM PbRL.
Options
Centralized collaboration. One model can write both roles with --override <method>.collaboration_mode=centralized, for example magrpo.collaboration_mode=centralized; the default is decentralized. num_agents stays 2 for the two roles, while only one model is loaded. The model receives both prompts and writes <agent_0> and <agent_1> sections, which are split only for rewards and evaluation. max_new_tokens then limits the whole joint response, and MARLHF's reward_max_length has to fit the joint prompt and both responses.
Native centralized prompt. By default the centralized prompt concatenates both agents' prompts, so the post or abstract appears twice. magrpo.centralized_prompt=native states the source once and asks one writer for both <agent_0> / <agent_1> responses, with both roles' instructions merged. The parser, reward and evaluation are unchanged. The joint response gets the two roles' combined budget:
python train_magrpo.py --config configs/magrpo_tldr_config.yaml --override \
  magrpo.collaboration_mode=centralized magrpo.max_new_tokens=512 \
  magrpo.centralized_prompt=native
Centralized comparator. The iterative preference methods can pair decentralized agents with one centralized comparator, which writes both responses in a single answer. madpo_iter.centralized_prompt (or marlhf_iter.centralized_prompt) picks that comparator's prompt, concatenated by default or native. In centralized preference runs, the joint actor uses the same prompt. The comparator's joint answer shares max_new_tokens with the agents, 256 in the iterative configs, unless madpo_iter.comparator_centralized_max_new_tokens gives it its own budget:
python train_madpo_iter.py --config configs/madpo_iter_tldr_config.yaml --override \
  madpo_iter.comparator_generation_mode=centralized madpo_iter.centralized_prompt=native
Checkpoints. A top-level checkpoint section is passed to CoMLRL's trainer.train(); without it, no training checkpoints are saved.
checkpoint:
  checkpoint_dir: ./checkpoints
  checkpoint_interval: 1
  checkpoint_total_limit: 3
  # resume_from_checkpoint: ./checkpoints/checkpoint-1
Resuming does not save new checkpoints unless checkpoint_dir is also set. A resumed run continues logging to the saved W&B run unless wandb.id or wandb.resume is set.
Logging. W&B is configured through wandb.project, wandb.entity, and wandb.name; wandb: null or wandb.enabled: false disables it.