ECC
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
- 308k
- JavaScript
- MIT
- 1 d ago
Scalable Parameter and Memory Efficient Pretraining for LLM: Recent Algorithmic Advances and Benchmarking
Repo OptimAI-Lab/Memory_Efficient_Pretraining, read from GitHub 17 min ago. OptimAI-Lab has not joined Take My Repo.
OptimAI-Lab/Memory_Efficient_Pretraining is a public repo on GitHub by OptimAI-Lab. Scalable Parameter and Memory Efficient Pretraining for LLM: Recent Algorithmic Advances and Benchmarking. It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it. It is written mainly in Python, has 11 stars and last changed on 2026-07-02. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-21.
GitHub is limiting requests or did not answer. The facts on this page still come from the last successful read.
Open on GitHubOptimAI-Lab/Memory_Efficient_Pretraining is a public repo on GitHub by OptimAI-Lab. Scalable Parameter and Memory Efficient Pretraining for LLM: Recent Algorithmic Advances and Benchmarking.
It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.
Its last change on GitHub was on 2026-07-02. Take My Repo does not judge from that whether it is maintained.
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.
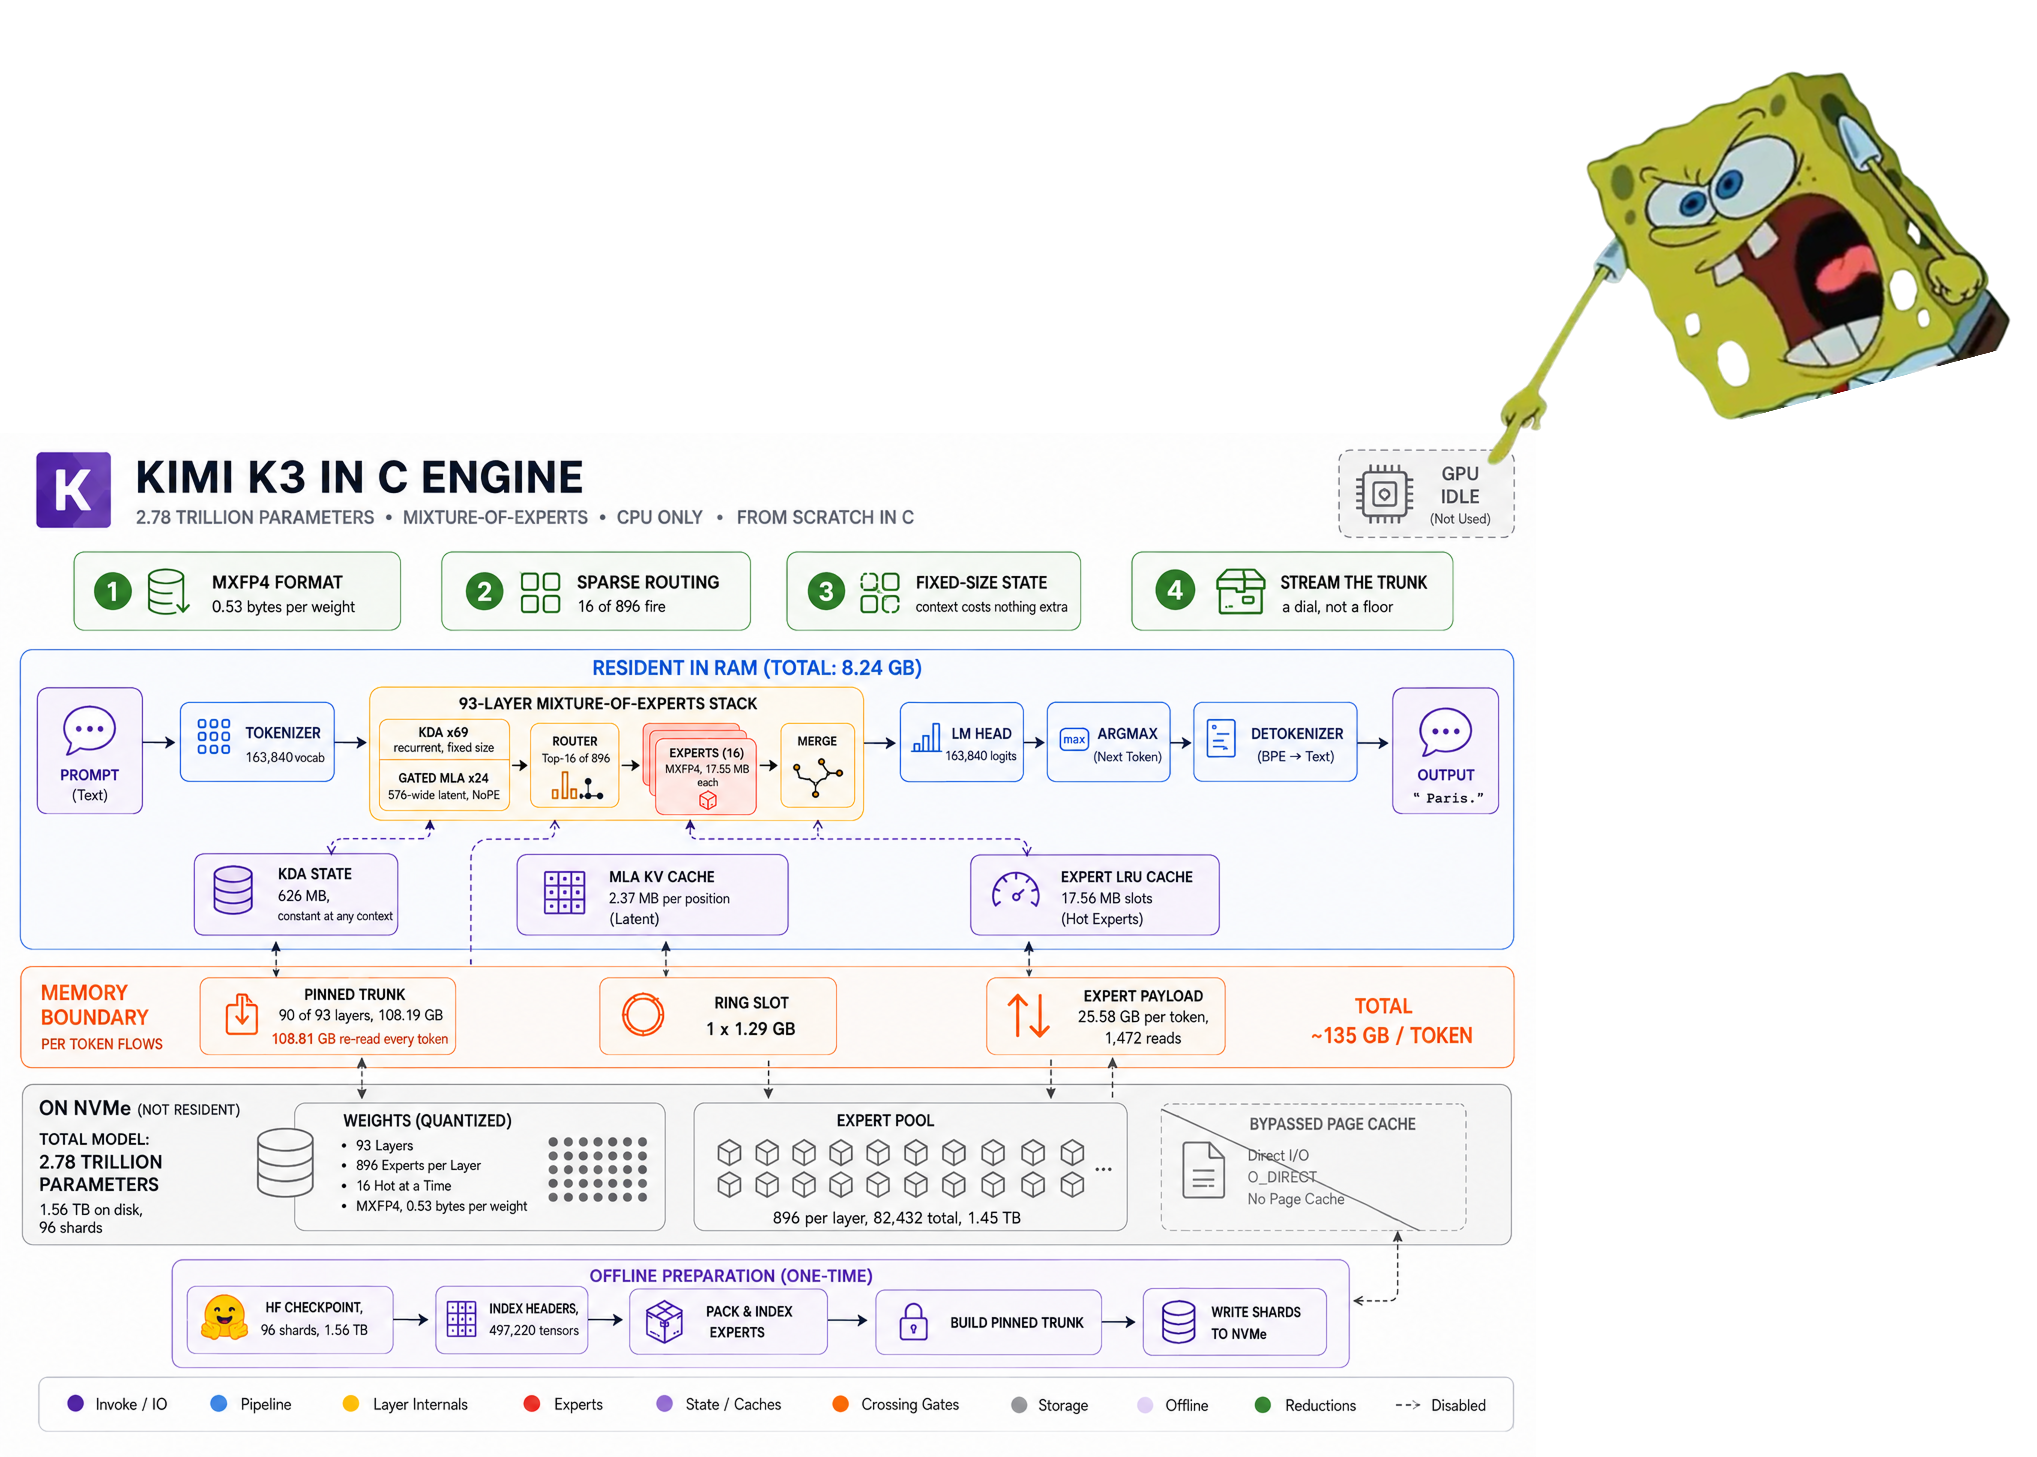
A 2.78-trillion-parameter Kimi K3 running inference on a single CPU in 8.24 GB of RAM. Portable C99: no BLAS, no framework, no GPU.
🧑🏫 60+ Implementations/tutorials of deep learning papers with side-by-side notes 📝; including transformers (original, xl, switch, feedback, vit, ...), optimizers (adam, adabelief, sophia, ...), gans(cyclegan, stylegan2, ...), 🎮 reinforcement learning (ppo, dqn), capsnet, distillation, ... 🧠
Implement a ChatGPT-like LLM in PyTorch from scratch, step by step
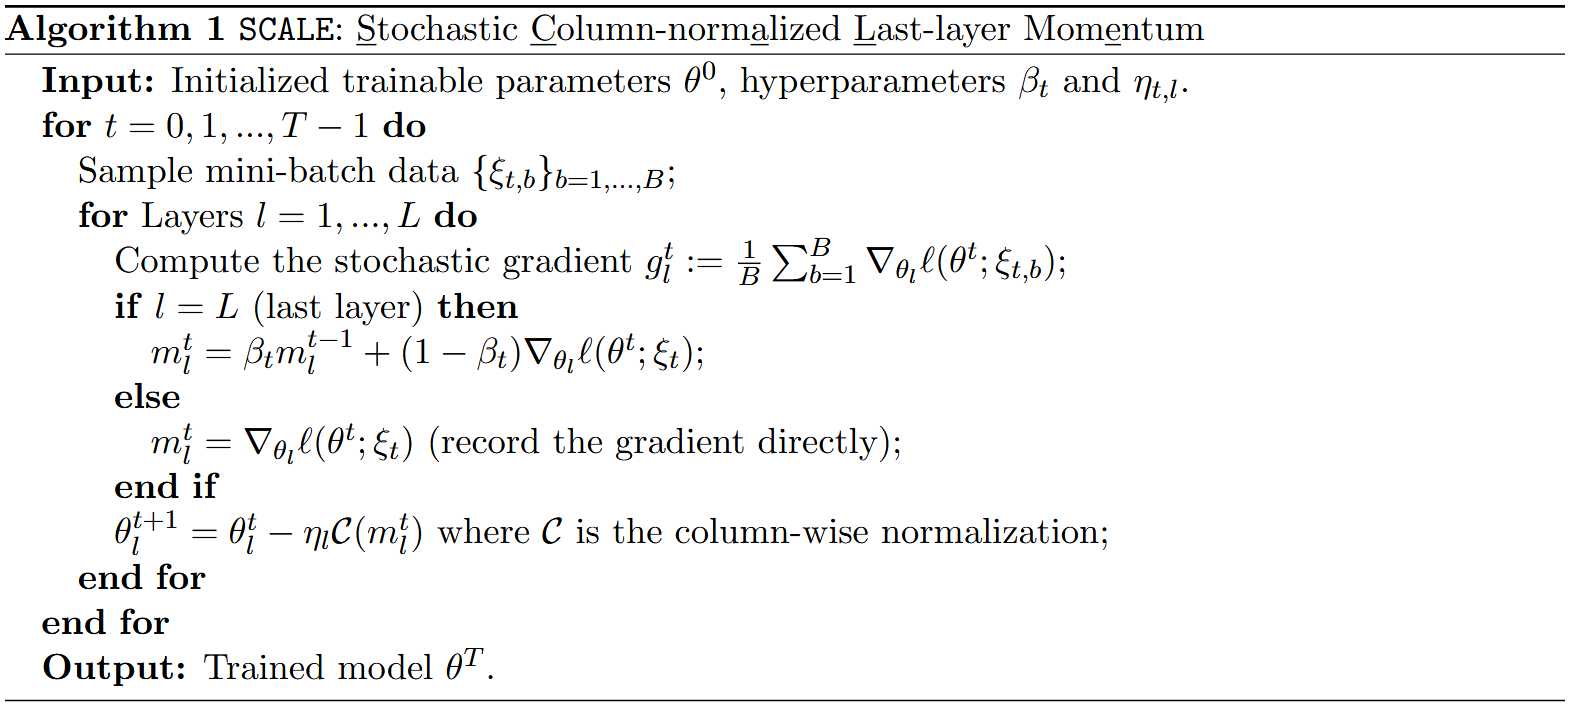
[ICML 2026] Memory-Efficient LLM Pretraining via Minimalist Optimizer Design
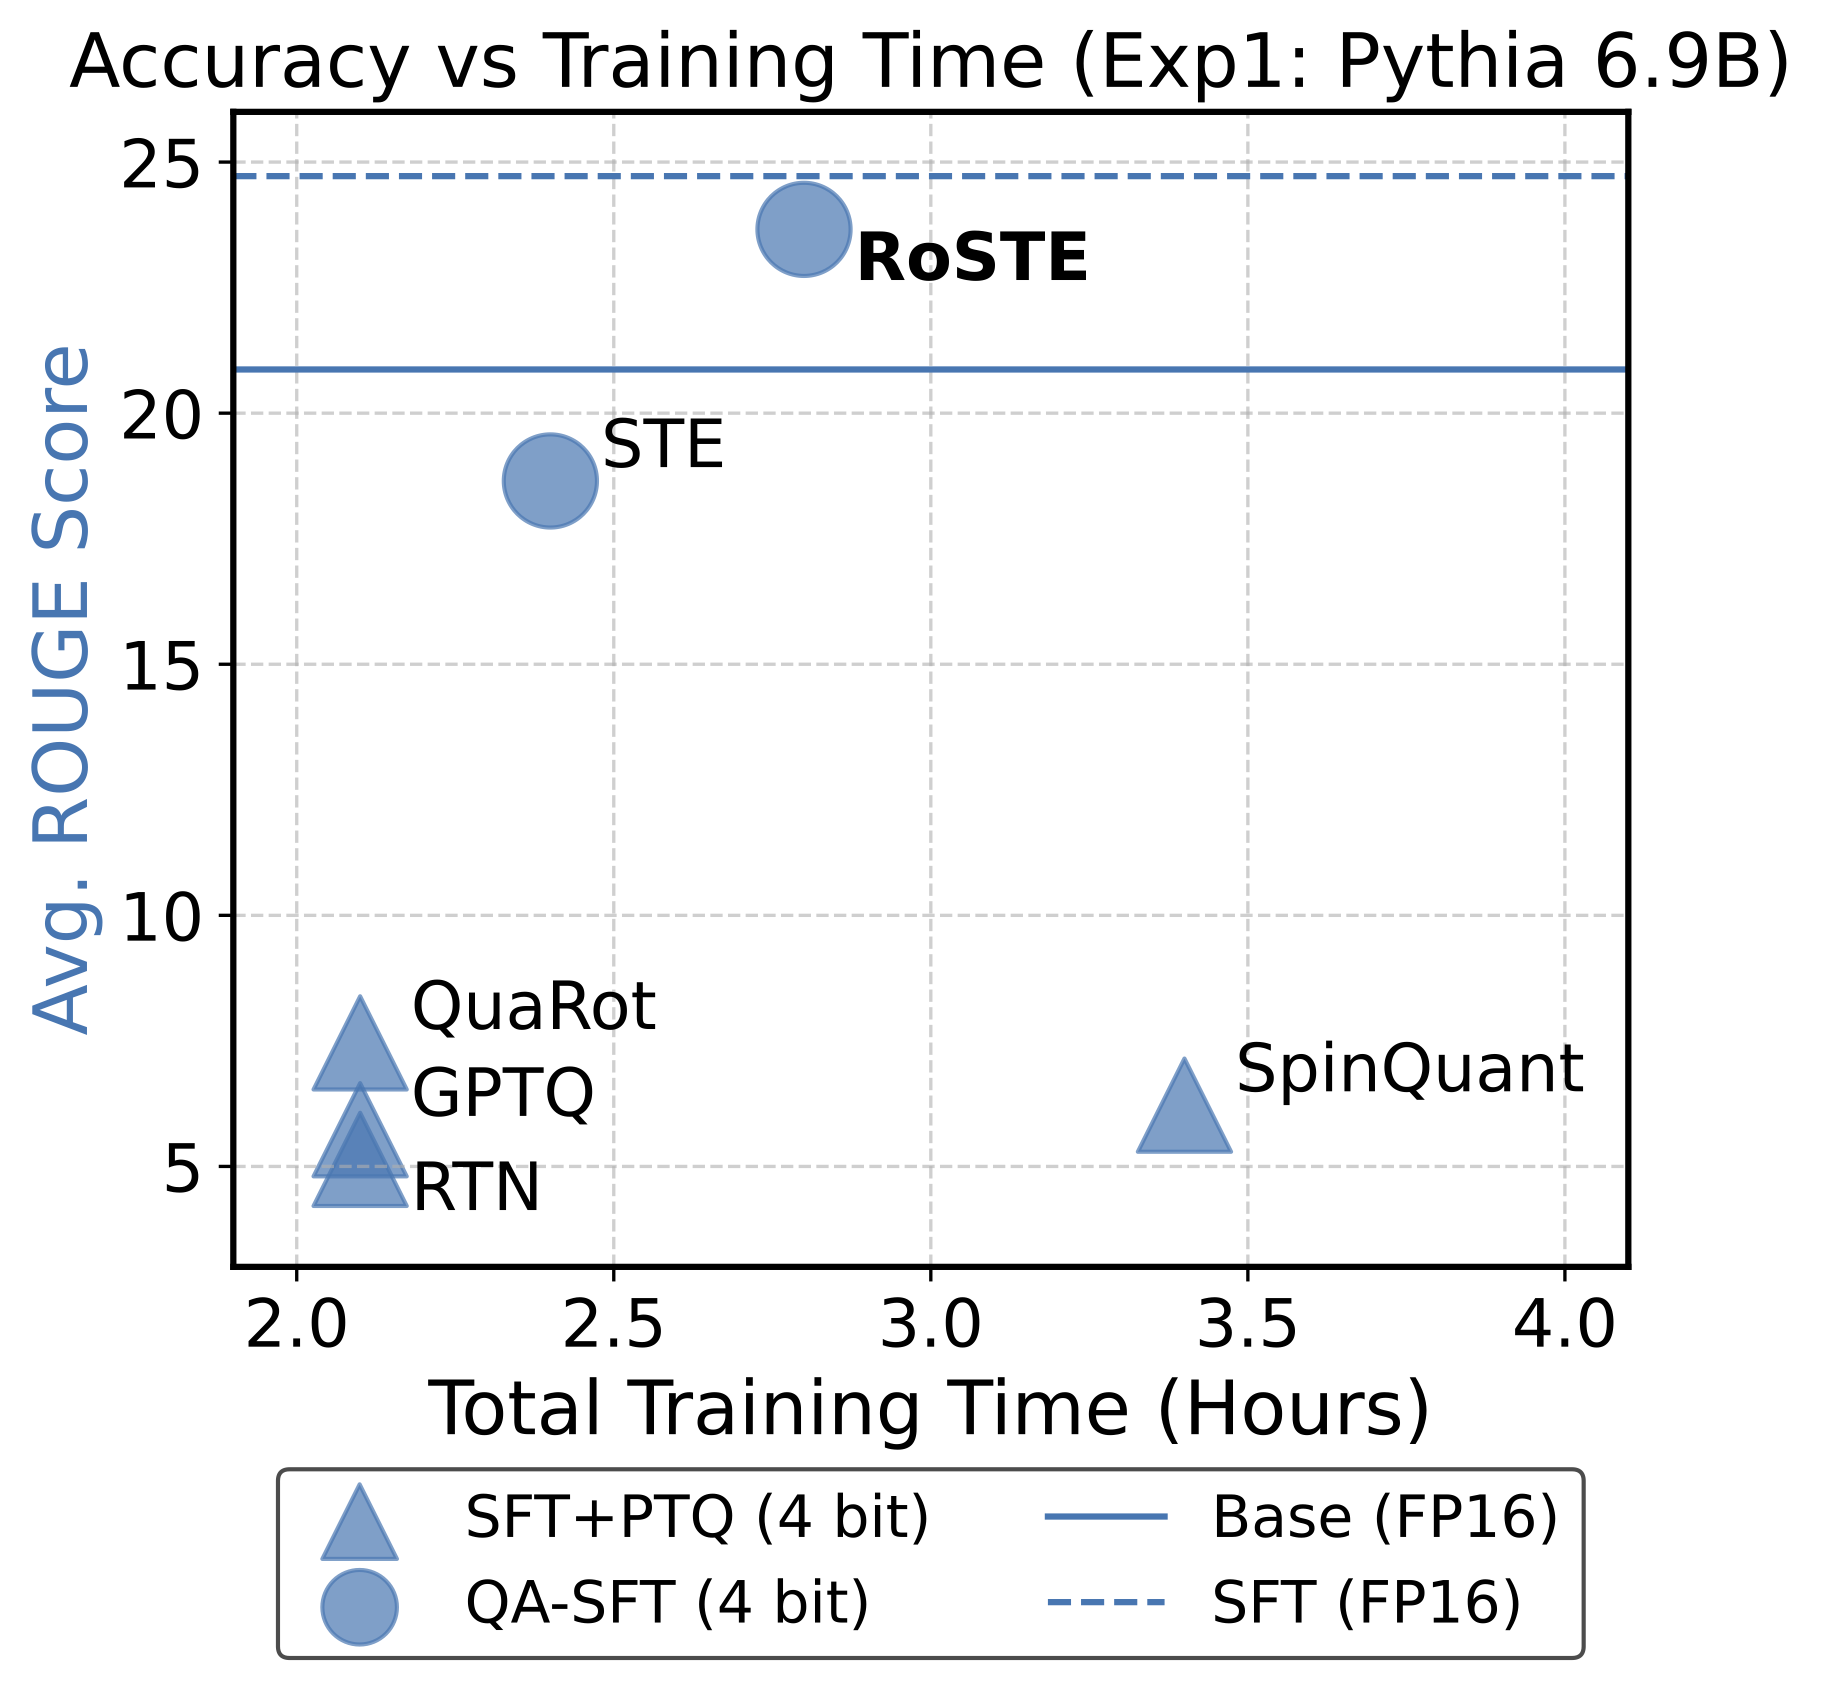
[ICML 2025] Official code for the paper "RoSTE: An Efficient Quantization-Aware Supervised Fine-Tuning Approach for Large Language Models"
[EACL 2026] BLUR: A Bi-Level Optimization Approach for LLM Unlearning
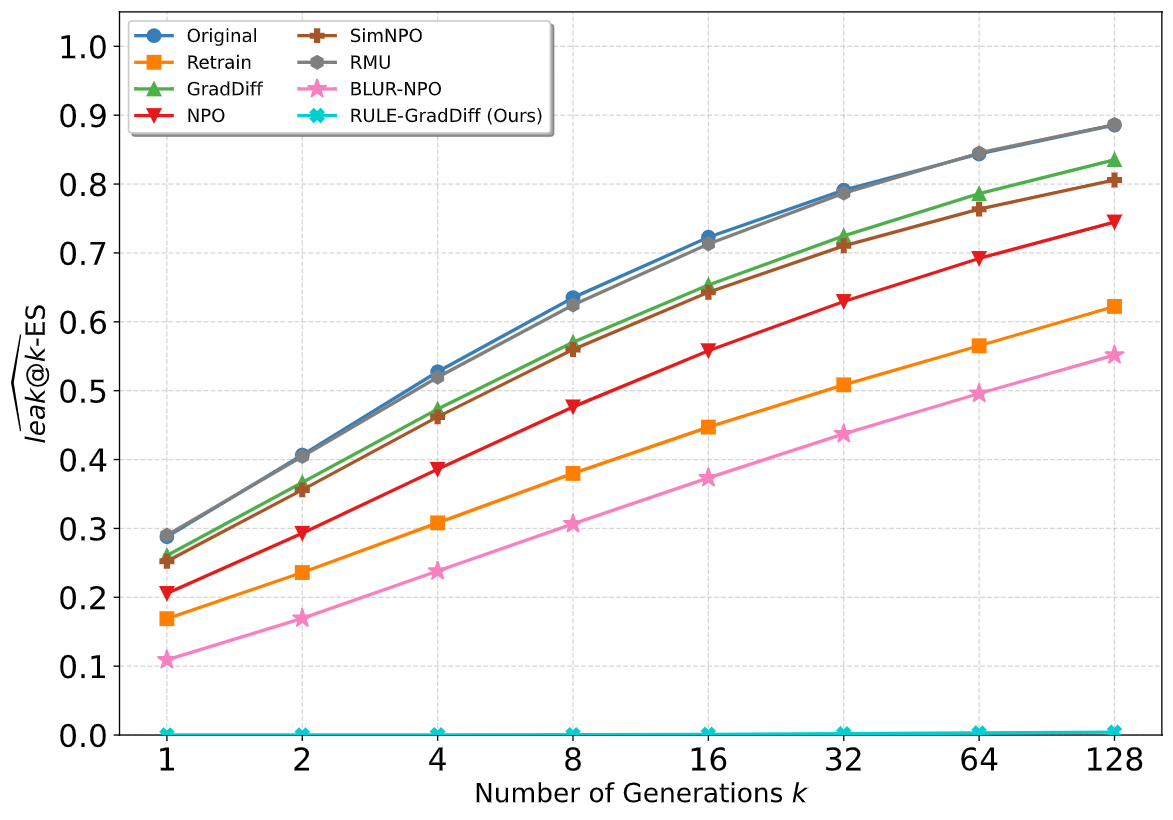
[ICML 2026] Leak@$k$: Unlearning Does Not Make LLMs Forget Under Probabilistic Decoding