quantization


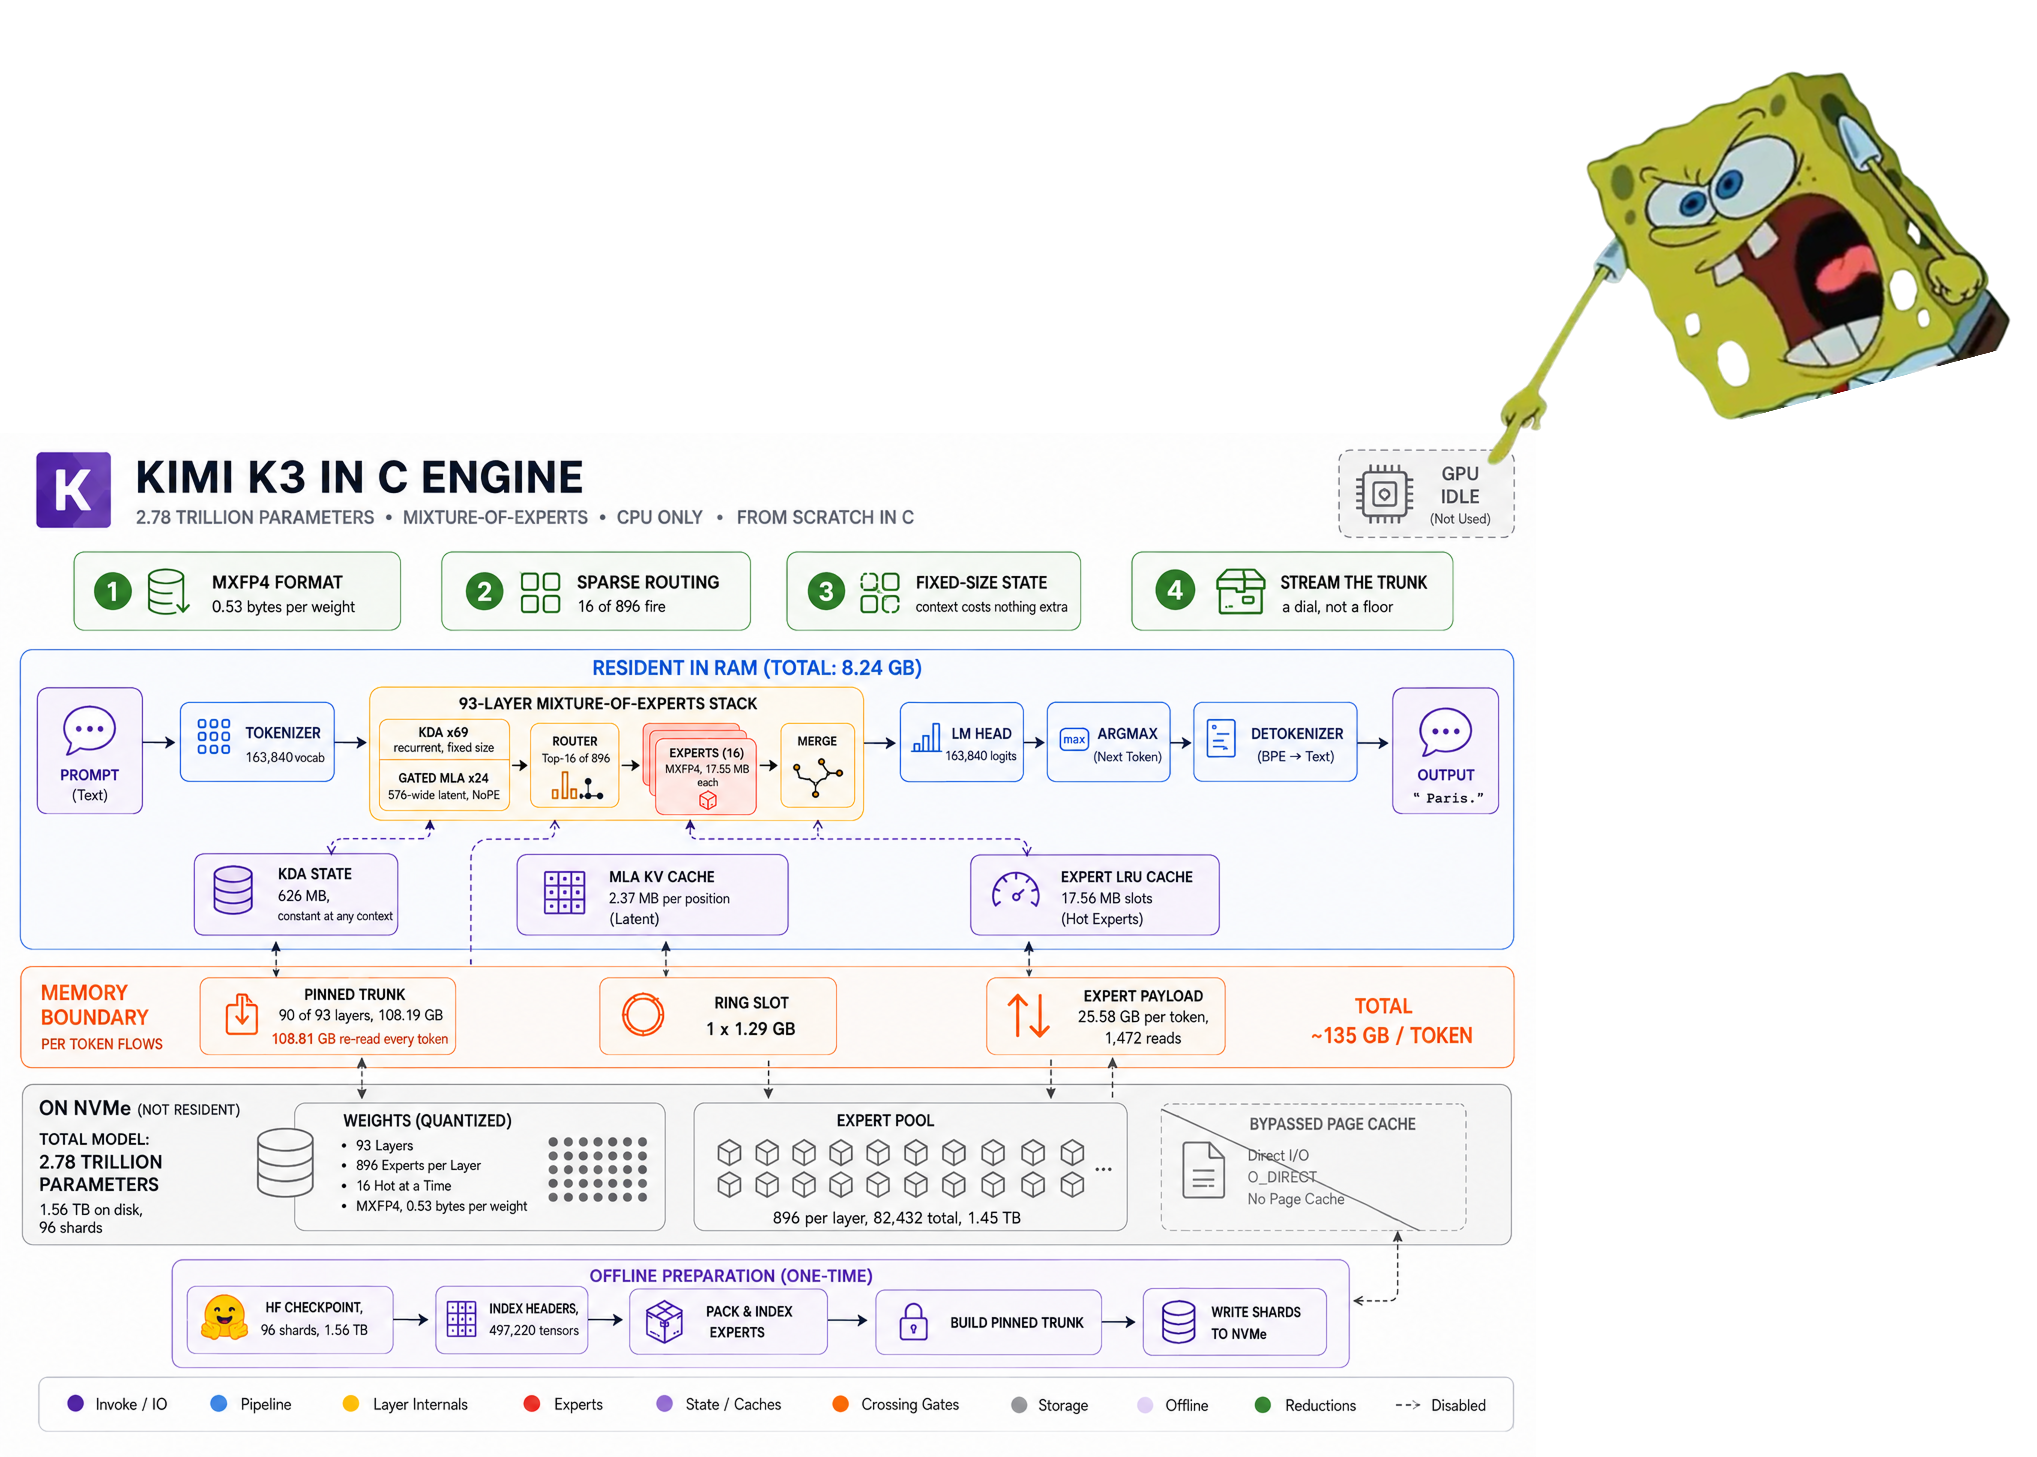
kimi-k3-in-c
A 2.78-trillion-parameter Kimi K3 running inference on a single CPU in 8.24 GB of RAM. Portable C99: no BLAS, no framework, no GPU.
- 12k
- C
- Apache-2.0
- 2 d ago

bitsandbytes
Accessible large language models via k-bit quantization for PyTorch.
- 8.5k
- Python
- MIT
- 2 wk ago

llm-compressor
State-of-the-art LLM compression, built for production inference with vLLM
- 4k
- Python
- Apache-2.0
- 16 min ago

ai-engineering-interview-questions
Your Cheat Sheet for AI Engineering Interview – Questions and Answers.
- 3.7k
- Markdown
- Apache-2.0
- 17 h ago

optimum
🚀 Accelerate inference and training of 🤗 Transformers, Diffusers, TIMM and Sentence Transformers with easy to use hardware optimization tools
- 3.5k
- Python
- Apache-2.0
- 2 d ago

Pretrained-Language-Model
Pretrained language model and its related optimization techniques developed by Huawei Noah's Ark Lab.
- 3.2k
- Python
- 3 y ago


project-maya
Run GLM-5.3 (744B), GLM-5.3-Flash (321B), DeepSeek-V4.1-Flash (748B) and MiniMax-M3.1-Flash (428B) on your own GPUs - one engine, one dashboard, OpenAI- and Anthropic-compatible API.
- 3k
- C++
- MIT
- 7 h ago

HyperQwen
Serve large Qwen models fast on the GPUs you actually own. Qwen3.8-27B on a single 24 GB card with vLLM: 127 tok/s single-user (381 when the answer quotes the prompt), ~1,035 tok/s at 64 concurrent, 150k-262k context. vLLM patches, requant pipeline, benchmarks.
- 2.8k
- Python
- Apache-2.0
- 9 d ago


aimet
AIMET is a library that provides advanced quantization and compression techniques for trained neural network models.
- 2.8k
- Python
- 15 h ago

neural-compressor
SOTA low-bit LLM quantization (INT8/FP8/MXFP8/INT4/MXFP4/NVFP4) & sparsity; leading model compression techniques on PyTorch, TensorFlow, and ONNX Runtime
- 2.7k
- Python
- Apache-2.0
- 4 h ago


micronet
micronet, a model compression and deploy lib. compression: 1、quantization: quantization-aware-training(QAT), High-Bit(>2b)(DoReFa/Quantization and Training of Neural Networks for Efficient Integer-Arithmetic-Only Inference)、Low-Bit(≤2b)/Ternary and Binary(TWN/BNN/XNOR-Net); post-training-quantization(PTQ), 8-bit(tensorrt); 2、 pruning: normal、regular and group convolutional channel pruning; 3、 grou
- 2.3k
- Python
- MIT
- 19 mo ago

ppq
PPL Quantization Tool (PPQ) is a powerful offline neural network quantization tool.
- 1.8k
- Python
- Apache-2.0
- 3 y ago


geti
Build, train, optimize, and run computer vision models locally, from raw images to live inference. Open source, optimized for Intel® XPU (CUDA also supported).
- 1.4k
- Python
- Apache-2.0
- 4 h ago

model-optimization
A toolkit to optimize ML models for deployment for Keras and TensorFlow, including quantization and pruning.
- 1.6k
- Python
- Apache-2.0
- 19 h ago


llama-modchip
Run 284B DeepSeek-V4-Flash (<59GiB RAM: 41.1 cold pp, 9.1 N=1 tg, up to 25.3 spec tok/s) & 30B MoEs (22.4 N=1 / 111.6 spec tok/s) on 64GB CPU (0 GPUs).
- 1.4k
- Python
- Apache-2.0
- 24 h ago

nncf
Neural Network Compression Framework for enhanced OpenVINO™ inference
- 1.2k
- Python
- Apache-2.0
- 10 h ago


Qwen3.8-Flash-Next-GSQ-RCO-abliterated-GGUF
Image text to text model, used with gguf.
- 1.1k
- 4.2M
- apache-2.0
- 7 wk ago
onnx2tf
A tool for converting ONNX files to LiteRT/TFLite/TensorFlow, PyTorch native code (nn.Module), TorchScript (.pt), state_dict (.pt), Exported Program (.pt2), and Dynamo ONNX. It also supports direct conversion from LiteRT to PyTorch.
- 1k
- Python
- MIT
- 2 mo ago



tinyengine
[NeurIPS 2020] MCUNet: Tiny Deep Learning on IoT Devices; [NeurIPS 2021] MCUNetV2: Memory-Efficient Patch-based Inference for Tiny Deep Learning; [NeurIPS 2022] MCUNetV3: On-Device Training Under 256KB Memory
- 970
- C
- MIT
- 24 mo ago


halo
Halo is an open-source framework built by White Circle for training large language and multimodal models
- 865
- Python
- 12 min ago

Awesome-Quantization-Papers
List of papers related to neural network quantization in recent AI conferences and journals.
- 856
- MIT
- 20 mo ago

Awesome-AutoML-and-Lightweight-Models
A list of high-quality (newest) AutoML works and lightweight models including 1.) Neural Architecture Search, 2.) Lightweight Structures, 3.) Model Compression, Quantization and Acceleration, 4.) Hyperparameter Optimization, 5.) Automated Feature Engineering.
- 854
- 5 y ago


LightCompress
[EMNLP 2024 & AAAI 2026] A powerful toolkit for compressing large models including LLMs, VLMs, and video generative models.
- 755
- Python
- Apache-2.0
- 6 mo ago

llm-algo-leetcode
Hands-on LLM algorithms and systems with PyTorch, Triton & CUDA.《大模型算法与系统教程》:模型架构与训练、后训练、推理加速、性能与算子优化,配套 Notebook 练习、答案解析、测试与实验。
- 805
- Jupyter Notebook
- 2 d ago

janas
37 tok/s from Qwen3-Next-80B (48 GB) on a 32 GB laptop, 24 without drafts vs 2.8 for llama.cpp; reading 62 vs 16 tok/s. Faster than llama.cpp on all 13 models compared in Q4_K_M. LLMs bigger than your RAM, pure C, CPU or GPU.
- 734
- C
- GPL-3.0
- 15 h ago

hailo_model_zoo
The Hailo Model Zoo includes pre-trained models and a full building and evaluation environment
- 725
- Python
- MIT
- 3 d ago

Qwen3.8-Flash-Next-GSQ-RCO-Coder-GGUF
Image text to text model, used with gguf.
- 638
- 846k
- apache-2.0
- 8 wk ago

BEVFormer_tensorrt
BEVFormer inference on TensorRT, including INT8 Quantization and Custom TensorRT Plugins (float/half/half2/int8).
- 584
- Python
- Apache-2.0
- 3 y ago

Qwen3.8-27B-Coder390-EfficientThink-Opus5.5-GPT6Astra-Grok4.7-DSV4Pro-K3-SFT-RLOO-MTP-DFlash2
Image text to text model.
- 581
- 876k
- apache-2.0
- 6 wk ago
DeepSeek-V4.1-Flash-1017-GSQ-RCO-Coder-GGUF
Image text to text model, used with gguf.
- 238
- 519k
- mit
- 2 wk ago
TurboQuant on Consumer GPUs — 100K Context on RTX 3090, 64K on RTX 4070
Runs in the browser on Hugging Face
- 15
- cc-by-4.0
- 8 mo ago
DeepSeek V4.1 Flash memory requirements
VRAM and RAM per quant, from the 48 shard headers
Runs in the browser on Hugging Face
- 2
- mit
- 8 wk ago
The Physical AI Inference Gap in Batch-1 LLM Decode
Interactive companion to the batch-1 LLM decode paper
Runs in the browser on Hugging Face
- 1
- cc-by-4.0
- 6 mo ago