Lambda the Ultimate Pattern Factory
My first programming languages were Lisp, Scheme, and ML. When I later started to work in OO languages like C++ and Java I noticed that idioms that are standard vocabulary in functional programming (fp) were not so easy to achieve and required sophisticated structures. Books like Design Patterns: Elements of Reusable Object-Oriented Software were a great starting point to reason about those structures. One of my earliest findings was that several of the GoF-Patterns had a stark resemblance of structures that are built into in functional languages: for instance the strategy pattern corresponds to higher order functions in fp (more details see below).
Recently, while re-reading through the Typeclassopedia I thought it would be a good exercise to map the structure of software design-patterns to the concepts found in the Haskell type class library and in functional programming in general.
By searching the web I found some blog entries studying specific patterns, but I did not come across any comprehensive study. As it seemed that nobody did this kind of work yet I found it worthy to spend some time on it and write down all my findings on the subject.
I think this kind of exposition could be helpful if you are:
- a programmer with an OO background who wants to get a better grip on how to implement more complex designs in functional programming
- a functional programmer who wants to get a deeper intuition for type classes.
- studying the Typeclassopedia and are looking for an accompanying reading providing example use cases and working code.
This project is work in progress, so please feel free to contact me with any corrections, adjustments, comments, suggestions and additional ideas you might have.
Please use the Issue Tracker to enter your requests.
Table of contents
The Patternopedia
The Typeclassopedia is a now classic paper that introduces the Haskell type classes by clarifying their algebraic and category-theoretic background. In particular it explains the relationships among those type classes.
In this chapter I'm taking a tour through the Typeclassopedia from a design pattern perspective.
For each of the Typeclassopedia type classes I try to explain how it corresponds to structures applied in software design patterns.
As a reference map I have included the following chart that depicts the Relationships between type classes covered in the Typeclassopedia:

- Solid arrows point from the general to the specific; that is, if there is an arrow from Foo to Bar it means that every Bar is (or should be, or can be made into) a Foo.
- Dotted lines indicate some other sort of relationship.
- Monad and ArrowApply are equivalent.
- Apply and Comonad are greyed out since they are not actually (yet?) in the standard Haskell libraries ∗.
Data Transfer Object → Functor
In the field of programming a data transfer object (DTO) is an object that carries data between processes.
The motivation for its use is that communication between processes is usually done resorting to remote interfaces
(e.g., web services), where each call is an expensive operation.
Because the majority of the cost of each call is related to the round-trip time between the client and the server,
one way of reducing the number of calls is to use an object (the DTO) that aggregates the data that would have been
transferred by the several calls, but that is served by one call only.
(quoted from Wikipedia
Data Transfer Object is a pattern from Martin Fowler's Patterns of Enterprise Application Architecture.
It is typically used in multi-layered applications where data is transferred between backends and frontends.
The aggregation of data usually also involves a denormalization of data structures. As an example, please refer to the following
diagram where two entities from the backend (Album and Artist) are assembled to a compound denormalized DTO AlbumDTO:
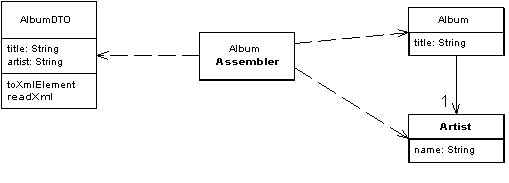
Of course, there is also an inverse mapping from AlbumDTO to Album which is not shown in this diagram.
In Haskell Album, Artist and AlbumDTO can be represented as data types with record notation:
data Album = Album {
    title       :: String
  , publishDate :: Int
  , labelName   :: String
  , artist      :: Artist
} deriving (Show)

data Artist = Artist {
    publicName :: String
  , realName   :: Maybe String
} deriving (Show)

data AlbumDTO = AlbumDTO {
    albumTitle  :: String
  , published   :: Int
  , label       :: String
  , artistName  :: String
} deriving (Show, Read)
The transfer from an Album to an AlbumDTO and vice versa can be achieved by two simple functions, that perfom the
intended field wise mappings:
toAlbumDTO :: Album -> AlbumDTO
toAlbumDTO Album {title = t, publishDate = d, labelName = l, artist = a} =
  AlbumDTO {albumTitle = t, published = d, label = l, artistName = (publicName a)}

toAlbum :: AlbumDTO -> Album
toAlbum AlbumDTO {albumTitle = t, published = d, label = l, artistName = n} =
  Album {title = t, publishDate = d, labelName = l, artist = Artist {publicName = n, realName = Nothing}}
In this few lines we have covered the basic idea of the DTO pattern.
Now, let's consider the typical situation that you don't have to transfer only a single Album instance but a whole
list of Album instances, e.g.:
albums :: [Album]
albums =
    [
      Album {title = "Microgravity",
             publishDate = 1991,
             labelName = "Origo Sound",
             artist = Artist {publicName = "Biosphere", realName = Just "Geir Jenssen"}}
    , Album {title = "Apollo - Atmospheres & Soundtracks",
             publishDate = 1983,
             labelName = "Editions EG",
             artist = Artist {publicName = "Brian Eno", realName = Just "Brian Peter George St. John le Baptiste de la Salle Eno"}}
    ]
In this case we have to apply the toAlbumDTO function to all elements of the list.
In Haskell this higher order operation is called map:
map :: (a -> b) -> [a] -> [b]
map _f []    = []
map f (x:xs) = f x : map f xs
map takes a function f :: (a -> b) (a function from type a to type b) and an [a] list and returns a [b] list.
The b elements are produced by applying the function f to each element of the input list.
Applying toAlbumDTO to a list of albums can thus be done in the Haskell REPL GHCi as follows:
λ> map toAlbumDTO albums
[AlbumDTO {albumTitle = "Microgravity", published = 1991, label = "Origo Sound", artistName = "Biosphere"},
 AlbumDTO {albumTitle = "Apollo - Atmospheres & Soundtracks", published = 1983, label = "Editions EG", artistName = "Brian Eno"}]
This mapping of functions over lists is a basic technique known in many functional languages.
In Haskell further generalises this technique with the concept of the Functor type class.
The Functor class is the most basic and ubiquitous type class in the Haskell libraries.
A simple intuition is that a Functor represents a “container” of some sort, along with the ability to apply a
function uniformly to every element in the container. For example, a list is a container of elements,
and we can apply a function to every element of a list, using map.
As another example, a binary tree is also a container of elements, and it’s not hard to come up with a way to
recursively apply a function to every element in a tree.
Another intuition is that a Functor represents some sort of “computational context”.
This intuition is generally more useful, but is more difficult to explain, precisely because it is so general.
Quoted from Typeclassopedia
Basically, all instances of the Functor type class must provide a function fmap:
class  Functor f  where
    fmap :: (a -> b) -> f a -> f b
For Lists the implementation is simply the map function that we already have seen above:
instance Functor [] where
    fmap = map
Functors have interesting properties, they fulfill the two so called functor laws,
which are part of the definition of a mathematical functor:
fmap id = id                        -- (1)
fmap (g . h) = (fmap g) . (fmap h)  -- (2)
The first law (1) states that mapping the identity function over every item in a container has no effect.
The second (2) says that mapping a composition of two functions over every item in a container is the same as first
mapping one function, and then mapping the other.
These laws are very useful when we consider composing complex mappings from simpler operations.
Say we want to extend our DTO mapping functionality by also providing some kind of marshalling. For a single album instance,
we can use function composition (f . g) x == f (g x), which is defined in Haskell as:
(.) :: (b -> c) -> (a -> b) -> a -> c
(.) f g x = f (g x)
In the following GHCi session we are using (.) to first convert an Album to its AlbumDTO representation and then
turn that into a String by using the show function:
λ> album1 = albums !! 0
λ> print album1
Album {title = "Microgravity", publishDate = 1991, labelName = "Origo Sound", artist = Artist {publicName = "Biosphere", realName = Just "Geir Jenssen"}}
λ> marshalled = (show . toAlbumDTO) album1
λ> :t marshalled
marshalled :: String
λ> print marshalled
"AlbumDTO {albumTitle = \"Microgravity\", published = 1991, label = \"Origo Sound\", artistName = \"Biosphere\"}"
As we can rely on the functor law fmap (g . h) = (fmap g) . (fmap h) we can use fmap to use the same composed
function on any functor, for example our list of albums:
λ> fmap (show . toAlbumDTO) albums
["AlbumDTO {albumTitle = \"Microgravity\", published = 1991, label = \"Origo Sound\", artistName = \"Biosphere\"}",
 "AlbumDTO {albumTitle = \"Apollo - Atmospheres & Soundtracks\", published = 1983, label = \"Editions EG\", artistName = \"Brian Eno\"}"]
We can build more complex mappings by chaining multiple functions, to produce for example a gzipped byte string output:
λ> gzipped = (compress . pack . show . toAlbumDTO) album1
As the sequence of operation must be read from right to left for the (.) operator this becomes quite unintuitive for longer sequences.
Thus, Haskellers often use the flipped version of (.), (>>>) which is defined as:
Using (>>>) the intent of our composition chain becomes much clearer (at least when you are trained to read from left to right):
λ> gzipped = (toAlbumDTO >>> show >>> pack >>> compress) album1
Unmarshalling can be defined using the inverse operations:
λ> unzipped = (decompress >>> unpack >>> read >>> toAlbum) gzipped
λ> :t unzipped
unzipped :: Album
λ> print unzipped
Album {title = "Microgravity", publishDate = 1991, labelName = "Origo Sound", artist = Artist {publicName = "Biosphere", realName = Nothing}}
Of course, we can use fmap to apply such composed mapping function to any container type instantiating the Functor
type class:
λ> marshalled   = fmap (toAlbumDTO >>> show >>> pack >>> compress) albums
λ> unmarshalled = fmap (decompress >>> unpack >>> read >>> toAlbum) marshalled
λ> print unmarshalled
[Album {title = "Microgravity", publishDate = 1991, labelName = "Origo Sound", artist = Artist {publicName = "Biosphere", realName = Nothing}},
 Album {title = "Apollo - Atmospheres & Soundtracks", publishDate = 1983, labelName = "Editions EG", artist = Artist {publicName = "Brian Eno", realName = Nothing}}]
Sourcecode for this section
Singleton → Applicative
"The singleton pattern is a software design pattern that restricts the instantiation of a class to one object. This is useful when exactly one object is needed to coordinate actions across the system."
(quoted from Wikipedia
The singleton pattern ensures that multiple requests to a given object always return one and the same singleton instance.
In functional programming this semantics can be achieved by let:
let singleton = someExpensiveComputation
in  mainComputation

--or in lambda notation:
(\singleton -> mainComputation) someExpensiveComputation
Via the let-Binding we can thread the singleton through arbitrary code in the in block. All occurences of singleton in the mainComputationwill point to the same instance.
Type classes provide several tools to make this kind of threading more convenient or even to avoid explicit threading of instances.
Using Applicative Functor for threading of singletons
The following code defines a simple expression evaluator:
data Exp e = Var String
           | Val e
           | Add (Exp e) (Exp e)
           | Mul (Exp e) (Exp e)

-- the environment is a list of tuples mapping variable names to values of type e
type Env e = [(String, e)]

-- a simple evaluator reducing expression to numbers
eval :: Num e => Exp e -> Env e -> e
eval (Var x)   env = fetch x env
eval (Val i)   env = i
eval (Add p q) env = eval p env + eval q env
eval (Mul p q) env = eval p env * eval q env
eval is a classic evaluator function that recursively evaluates sub-expression before applying + or *.
Note how the explicit envparameter is threaded through the recursive eval calls. This is needed to have the
environment avalailable for variable lookup at any recursive call depth.
If we now bind env to a value as in the following snippet it is used as an immutable singleton within the recursive evaluation of eval exp env.
main = do
  let exp = Mul (Add (Val 3) (Val 1))
                (Mul (Val 2) (Var "pi"))
      env = [("pi", pi)]
  print $ eval exp env
Experienced Haskellers will notice the "eta-reduction smell" in eval (Var x) env = fetch x env which hints at the possibilty to remove env as an explicit parameter. We can not do this right away as the other equations for eval do not allow eta-reduction. In order to do so we have to apply the combinators of the Applicative Functor:
class Functor f => Applicative f where
    pure  :: a -> f a
    (<*>) :: f (a -> b) -> f a -> f b

instance Applicative ((->) a) where
    pure        = const
    (<*>) f g x = f x (g x)
This Applicative allows us to rewrite eval as follows:
eval :: Num e => Exp e -> Env e -> e
eval (Var x)   = fetch x
eval (Val i)   = pure i
eval (Add p q) = pure (+) <*> eval p  <*> eval q
eval (Mul p q) = pure (*) <*> eval p  <*> eval q
Any explicit handling of the variable env is now removed.
(I took this example from the classic paper Applicative programming with effects which details how pure and <*> correspond to the combinatory logic combinators K and S.)
Sourcecode for this section
Pipeline → Monad
In software engineering, a pipeline consists of a chain of processing elements (processes, threads, coroutines, functions, etc.), arranged so that the output of each element is the input of the next; the name is by analogy to a physical pipeline.
(Quoted from: Wikipedia
The concept of pipes and filters in Unix shell scripts is a typical example of the pipeline architecture pattern.
$ echo "hello world" | wc -w | xargs printf "%d*3\n" | bc -l
6
This works exactly as stated in the wikipedia definition of the pattern: the output of echo "hello world" is used as input for the next command wc -w. The ouptput of this command is then piped as input into xargs printf "%d*3\n" and so on.
On the first glance this might look like ordinary function composition. We could for instance come up with the following approximation in Haskell:
((3 *) . length . words) "hello world"
6
But with this design we missed an important feature of the chain of shell commands: The commands do not work on elementary types like Strings or numbers but on input and output streams that are used to propagate the actual elementary data around. So we can't just send a String into the wc command as in "hello world" | wc -w. Instead we have to use echo to place the string into a stream that we can then use as input to the wc command:
> echo "hello world" | wc -w
So we might say that echo injects the String "hello world" into the stream context.
We can capture this behaviour in a functional program like this:
-- The Stream type is a wrapper around an arbitrary payload type 'a'
newtype Stream a = Stream a deriving (Show)

-- echo injects an item of type 'a' into the Stream context
echo :: a -> Stream a
echo = Stream

-- the 'andThen' operator used for chaining commands
infixl 7 |>
(|>) :: Stream a -> (a -> Stream b) -> Stream b
Stream x |> f = f x


-- echo and |> are used to create the actual pipeline
pipeline :: String -> Stream Int
pipeline str =
  echo str |> echo . length . words |> echo . (3 *)
-- now executing the program in ghci repl:
ghci> pipeline "hello world"
Stream 6
The echo function injects any input into the Stream context:
ghci> echo "hello world"
Stream "hello world"
The |> (pronounced as "andThen") does the function chaining:
ghci> echo "hello world" |> echo . words
Stream ["hello","world"]
The result of |> is of type Stream b that's why we cannot just write echo "hello world" |> words. We have to use echo to create a Stream output that can be digested by a subsequent |>.
The interplay of a Context type Stream a and the functions echo and |> is a well known pattern from functional languages: it's the legendary Monad. As the Wikipedia article on the pipeline pattern states:
Pipes and filters can be viewed as a form of functional programming, using byte streams as data objects; more specifically, they can be seen as a particular form of monad for I/O.
There is an interesting paper available elaborating on the monadic nature of Unix pipes: Monadic Shell.
Here is the definition of the Monad type class in Haskell:
class Applicative m => Monad m where
    -- | Sequentially compose two actions, passing any value produced
    -- by the first as an argument to the second.
    (>>=)  :: m a -> (a -> m b) -> m b

    -- | Inject a value into the monadic type.
    return :: a -> m a
    return = pure
By looking at the types of >>= and return it's easy to see the direct correspondence to |> and echo in the pipeline example above:
    (|>)   :: Stream a -> (a -> Stream b) -> Stream b
    echo   :: a -> Stream a
Mhh, this is nice, but still looks a lot like ordinary composition of functions, just with the addition of a wrapper.
In this simplified example that's true, because we have designed the |> operator to simply unwrap a value from the Stream and bind it to the formal parameter of the subsequent function:
But we are free to implement the andThen operator in any way that we seem fit as long we maintain the type signature and the monad laws.
So we could for instance change the semantics of >>= to keep a log along the execution pipeline:
-- The DeriveFunctor Language Pragma provides automatic derivation of Functor instances
{-# LANGUAGE DeriveFunctor #-}

-- a Log is just a list of Strings
type Log = [String]

-- the Stream type is extended by a Log that keeps track of any logged messages
newtype LoggerStream a = LoggerStream (a, Log) deriving (Show, Functor)

instance Applicative LoggerStream where
  pure = return
  LoggerStream (f, _) <*> r = fmap f r

-- our definition of the Logging Stream Monad:
instance Monad LoggerStream where
  -- returns a Stream wrapping a tuple of the actual payload and an empty Log
  return a = LoggerStream (a, [])

  -- we define (>>=) to return a tuple (composed functions, concatenated logs)
  m1 >>= m2  = let LoggerStream(f1, l1) = m1
                   LoggerStream(f2, l2) = m2 f1
               in LoggerStream(f2, l1 ++ l2)

-- compute length of a String and provide a log message
logLength :: String -> LoggerStream Int
logLength str = let l = length(words str)
                in LoggerStream (l, ["length(" ++ str ++ ") = " ++ show l])

-- multiply x with 3 and provide a log message
logMultiply :: Int -> LoggerStream Int
logMultiply x = let z = x * 3
                in LoggerStream (z, ["multiply(" ++ show x ++ ", 3" ++") = " ++ show z])

-- the logging version of the pipeline
logPipeline :: String -> LoggerStream Int
logPipeline str =
  return str >>= logLength >>= logMultiply

-- and then in Ghci:
> logPipeline "hello logging world"
LoggerStream (9,["length(hello logging world) = 3","multiply(3, 3) = 9"])
What's noteworthy here is that Monads allow to make the mechanism of chaining functions explicit. We can define what andThen should mean in our pipeline by choosing a different Monad implementation.
So in a sense Monads could be called programmable semicolons
To make this statement a bit clearer we will have a closer look at the internal workings of the Maybe Monad in the next section.
Sourcecode for this section
NullObject → Maybe Monad
[...] a null object is an object with no referenced value or with defined neutral ("null") behavior. The null object design pattern describes the uses of such objects and their behavior (or lack thereof).
Quoted from Wikipedia
In functional programming the null object pattern is typically formalized with option types:
[...] an option type or maybe type is a polymorphic type that represents encapsulation of an optional value; e.g., it is used as the return type of functions which may or may not return a meaningful value when they are applied. It consists of a constructor which either is empty (named None or Nothing), or which encapsulates the original data type A (written Just A or Some A).
Quoted from Wikipedia
(See also: Null Object as Identity)
In Haskell the most simple option type is Maybe. Let's directly dive into an example. We define a reverse index, mapping songs to album titles.
If we now lookup up a song title we may either be lucky and find the respective album or not so lucky when there is no album matching our song:
import           Data.Map (Map, fromList)
import qualified Data.Map as Map (lookup) -- avoid clash with Prelude.lookup

-- type aliases for Songs and Albums
type Song   = String
type Album  = String

-- the simplified reverse song index
songMap :: Map Song Album
songMap = fromList
    [("Baby Satellite","Microgravity")
    ,("An Ending", "Apollo: Atmospheres and Soundtracks")]
We can lookup this map by using the function Map.lookup :: Ord k => k -> Map k a -> Maybe a.
If no match is found it will return Nothing if a match is found it will return Just match:
ghci> Map.lookup "Baby Satellite" songMap
Just "Microgravity"
ghci> Map.lookup "The Fairy Tale" songMap
Nothing
Actually the Maybe type is defined as:
data  Maybe a  =  Nothing | Just a
    deriving (Eq, Ord)
All code using the Map.lookup function will never be confronted with any kind of Exceptions, null pointers or other nasty things. Even in case of errors a lookup will always return a properly typed Maybe instance. By pattern matching for Nothing or Just a client code can react on failing matches or positive results:
    case Map.lookup "Ancient Campfire" songMap of
        Nothing -> print "sorry, could not find your song"
        Just a  -> print a
Let's try to apply this to an extension of our simple song lookup.
Let's assume that our music database has much more information available. Apart from a reverse index from songs to albums, there might also be an index mapping album titles to artists.
And we might also have an index mapping artist names to their websites:
type Song   = String
type Album  = String
type Artist = String
type URL    = String

songMap :: Map Song Album
songMap = fromList
    [("Baby Satellite","Microgravity")
    ,("An Ending", "Apollo: Atmospheres and Soundtracks")]

albumMap :: Map Album Artist
albumMap = fromList
    [("Microgravity","Biosphere")
    ,("Apollo: Atmospheres and Soundtracks", "Brian Eno")]

artistMap :: Map Artist URL
artistMap = fromList
    [("Biosphere","http://www.biosphere.no//")
    ,("Brian Eno", "http://www.brian-eno.net")]

lookup' :: Ord a => Map a b -> a -> Maybe b
lookup' = flip Map.lookup

findAlbum :: Song -> Maybe Album
findAlbum = lookup' songMap

findArtist :: Album -> Maybe Artist
findArtist = lookup' albumMap

findWebSite :: Artist -> Maybe URL
findWebSite = lookup' artistMap
With all this information at hand we want to write a function that has an input parameter of type Song and returns a Maybe URL by going from song to album to artist to website url:
findUrlFromSong :: Song -> Maybe URL
findUrlFromSong song =
    case findAlbum song of
        Nothing    -> Nothing
        Just album ->
            case findArtist album of
                Nothing     -> Nothing
                Just artist ->
                    case findWebSite artist of
                        Nothing  -> Nothing
                        Just url -> Just url
This code makes use of the pattern matching logic described before. It's worth to note that there is some nice circuit breaking happening in case of a Nothing. In this case Nothing is directly returned as result of the function and the rest of the case-ladder is not executed.
What's not so nice is "the dreaded ladder of code marching off the right of the screen" (quoted from Real World Haskell).
For each find function we have to repeat the same ceremony of pattern matching on the result and either return Nothing or proceed with the next nested level.
The good news is that it is possible to avoid this ladder.
We can rewrite our search by applying the andThen operator >>= as Maybe is an instance of Monad:
findUrlFromSong' :: Song -> Maybe URL
findUrlFromSong' song =
    findAlbum song   >>= \album ->
    findArtist album >>= \artist ->
    findWebSite artist
or even shorter as we can eliminate the lambda expressions by applying eta-conversion:
findUrlFromSong'' :: Song -> Maybe URL
findUrlFromSong'' song =
    findAlbum song >>= findArtist >>= findWebSite
Using it in GHCi:
ghci> findUrlFromSong'' "All you need is love"
Nothing
ghci> findUrlFromSong'' "An Ending"
Just "http://www.brian-eno.net"
The expression findAlbum song >>= findArtist >>= findWebSite and the sequencing of actions in the pipeline example return str >>= return . length . words >>= return . (3 *) have a similar structure.
But the behaviour of both chains is quite different: In the Maybe Monad a >>= b does not evaluate b if a == Nothing but stops the whole chain of actions by simply returning Nothing.
The pattern matching and 'short-circuiting' is directly coded into the definition of (>>=) in the Monad implementation of Maybe:
instance  Monad Maybe  where
    (Just x) >>= k      = k x
    Nothing  >>= _      = Nothing
This elegant feature of (>>=) in the Maybe Monad allows us to avoid ugly and repetetive coding.
Avoiding partial functions by using Maybe
Maybe is often used to avoid the exposure of partial functions to client code. Take for example division by zero or computing the square root of negative numbers which are undefined (at least for real numbers).
Here come safe – that is total – definitions of these functions that return Nothing for undefined cases:
safeRoot :: Double -> Maybe Double
safeRoot x
    | x >= 0    = Just (sqrt x)
    | otherwise = Nothing

safeReciprocal :: Double -> Maybe Double
safeReciprocal x
    | x /= 0    = Just (1/x)
    | otherwise = Nothing
As we have already learned the monadic >>= operator allows to chain such function as in the following example:
safeRootReciprocal :: Double -> Maybe Double
safeRootReciprocal x = return x >>= safeReciprocal >>= safeRoot
This can be written even more terse as:
safeRootReciprocal :: Double -> Maybe Double
safeRootReciprocal = safeReciprocal >=> safeRoot
The use of the Kleisli 'fish' operator >=> makes it more evident that we are actually aiming at a composition of the monadic functions safeReciprocal and safeRoot.
There are many predefined Monads available in the Haskell curated libraries and it's also possible to combine their effects by making use of MonadTransformers. But that's a different story...
Sourcecode for this section
Interpreter → Reader Monad
In computer programming, the interpreter pattern is a design pattern that specifies how to evaluate sentences in a language. The basic idea is to have a class for each symbol (terminal or nonterminal) in a specialized computer language. The syntax tree of a sentence in the language is an instance of the composite pattern and is used to evaluate (interpret) the sentence for a client.
Quoted from Wikipedia
In the section Singleton → Applicative we have already written a simple expression evaluator. From that section it should be obvious how easy the definition of evaluators and interpreters is in functional programming languages.
The main ingredients are:
- Algebraic Data Types (ADT) used to define the expression data type which is to be evaluated
- An evaluator function that uses pattern matching on the expression ADT
- 'implicit' threading of an environment
In the section on Singleton we have seen that some kind of 'implicit' threading of the environment can be already achieved with `Applicative Functors.
We still had the environment as an explicit parameter of the eval function:
eval :: Num e => Exp e -> Env e -> e
but we could omit it in the pattern matching equations:
eval (Var x)   = fetch x
eval (Val i)   = pure i
eval (Add p q) = pure (+) <*> eval p  <*> eval q
eval (Mul p q) = pure (*) <*> eval p  <*> eval q
By using Monads the handling of the environment can be made even more implicit.
I'll demonstrate this with a slightly extended version of the evaluator. In the first step we extend the expression syntax to also provide let expressions and generic support for binary operators:
-- | a simple expression ADT
data Exp a =
      Var String                            -- a variable to be looked up
    | BinOp (BinOperator a) (Exp a) (Exp a) -- a binary operator applied to two expressions
    | Let String (Exp a) (Exp a)            -- a let expression
    | Val a                                 -- an atomic value

-- | a binary operator type
type BinOperator a =  a -> a -> a

-- | the environment is just a list of mappings from variable names to values
type Env a = [(String, a)]
With this data type we can encode expressions like:
as:
Let "x" (BinOp (+) (Val 4) (Val 5))
        (BinOp (*) (Val 2) (Var "x"))
In order to evaluate such expression we must be able to modify the environment at runtime to create a binding for the variable x which will be referred to in the in part of the expression.
Next we define an evaluator function that pattern matches the above expression ADT:
eval :: MonadReader (Env a) m => Exp a -> m a
eval (Val i)          = return i
eval (Var x)          = asks (fetch x)
eval (BinOp op e1 e2) = liftM2 op (eval e1) (eval e2)
eval (Let x e1 e2)    = eval e1 >>= \v -> local ((x,v):) (eval e2)
Let's explore this dense code line by line.
eval :: MonadReader (Env a) m => Exp a -> m a
The most simple instance for MonadReader is the partially applied function type ((->) env).
Let's assume the compiler will choose this type as the MonadReader instance. We can then rewrite the function signature as follows:
eval :: Exp a -> ((->) (Env a)) a  -- expanding m to ((->) (Env a))
eval :: Exp a -> Env a -> a        -- applying infix notation for (->)
This is exactly the signature we were using for the Applicative eval function which matches our original intent to eval an expression of type Exp a in an environment of type Env a to a result of type a.
In this line we are pattern matching for a (Val i). The atomic value i is returned, that is lifted to a value of the type Env a -> a.
eval (Var x) = asks (fetch x)
asks is a helper function that applies its argument f :: env -> a (in our case (fetch x) which looks up variable x) to the environment. asks is thus typically used to handle environment lookups:
asks :: (MonadReader env m) => (env -> a) -> m a
asks f = ask >>= return . f
Now to the next line handling the application of a binary operator:
eval (BinOp op e1 e2) = liftM2 op (eval e1) (eval e2)
op is a binary function of type a -> a -> a (typical examples are binary arithmetic functions like +, -, *, /).
We want to apply this operation on the two expressions (eval e1) and (eval e2).
As these expressions both are to be executed within the same monadic context we have to use liftM2 to lift op into this context:
-- | Promote a function to a monad, scanning the monadic arguments from
-- left to right.  For example,
--
-- > liftM2 (+) [0,1] [0,2] = [0,2,1,3]
-- > liftM2 (+) (Just 1) Nothing = Nothing
--
liftM2  :: (Monad m) => (a1 -> a2 -> r) -> m a1 -> m a2 -> m r
liftM2 f m1 m2 = do { x1 <- m1; x2 <- m2; return (f x1 x2) }
The last step is the evaluation of Let x e1 e2 expressions like Let "x" (Val 7) (BinOp (+) (Var "x") (Val 5)). To make this work we have to evaluate e1 and extend the environment by a binding of the variable x to the result of that evaluation.
Then we have to evaluate e2 in the context of the extended environment:
eval (Let x e1 e2)    = eval e1 >>= \v ->           -- bind the result of (eval e1) to v
                        local ((x,v):) (eval e2)    -- add (x,v) to the env, eval e2 in the extended env
The interesting part here is the helper function local f m which applies f to the environment and then executes m against the (locally) changed environment.
Providing a locally modified environment as the scope of the evaluation of e2 is exactly what the let binding intends:
-- | Executes a computation in a modified environment.
local :: (r -> r) -- ^ The function to modify the environment.
        -> m a    -- ^ @Reader@ to run in the modified environment.
        -> m a

instance MonadReader r ((->) r) where
    local f m = m . f
Now we can use eval to evaluate our example expression:
interpreterDemo = do
    putStrLn "Interpreter -> Reader Monad + ADTs + pattern matching"
    let exp1 = Let "x"
                (BinOp (+) (Val 4) (Val 5))
                (BinOp (*) (Val 2) (Var "x"))
    print $ runReader (eval exp1) env

-- an then in GHCi:

> interpreterDemo
18
By virtue of the local function we used MonadReader as if it provided modifiable state. So for many use cases that require only local state modifications its not required to use the somewhat more tricky MonadState.
Writing the interpreter function with a MonadState looks like follows:
eval1 :: (MonadState (Env a) m) => Exp a -> m a
eval1 (Val i)          = return i
eval1 (Var x)          = gets (fetch x)
eval1 (BinOp op e1 e2) = liftM2 op (eval1 e1) (eval1 e2)
eval1 (Let x e1 e2)    = eval1 e1        >>= \v ->
                         modify ((x,v):) >>
                         eval1 e2
This section was inspired by ideas presented in Quick Interpreters with the Reader Monad.
Sourcecode for this section
Aspect Weaving → Monad Transformers
In computing, aspect-oriented programming (AOP) is a programming paradigm that aims to increase modularity by allowing the separation of cross-cutting concerns. It does so by adding additional behavior to existing code (an advice) without modifying the code itself, instead separately specifying which code is modified via a "pointcut" specification, such as "log all function calls when the function's name begins with 'set'". This allows behaviors that are not central to the business logic (such as logging) to be added to a program without cluttering the code, core to the functionality.
Quoted from Wikipedia
Stacking Monads
In section
Interpreter -> Reader Monad
we specified an Interpreter of a simple expression language by defining a monadic eval function:
eval :: Exp a -> Reader (Env a) a
eval (Var x)          = asks (fetch x)
eval (Val i)          = return i
eval (BinOp op e1 e2) = liftM2 op (eval e1) (eval e2)
eval (Let x e1 e2) = eval e1 >>= \v -> local ((x,v):) (eval e2)
Using the Reader Monad allows to thread an environment through all recursive calls of eval.
A typical extension to such an interpreter would be to provide a log mechanism that allows tracing of the actual sequence of all performed evaluation steps.
In Haskell the typical way to provide such a log is by means of the Writer Monad.
But how to combine the capabilities of the Reader monad code with those of the Writer monad?
The answer is MonadTransformers: specialized types that allow us to stack two monads into a single one that shares the behavior of both.
In order to stack the Writer monad on top of the Reader we use the transformer type WriterT:
-- adding a logging capability to the expression evaluator
eval :: Show a => Exp a -> WriterT [String] (Reader (Env a)) a
eval (Var x)          = tell ["lookup " ++ x] >> asks (fetch x)
eval (Val i)          = tell [show i] >> return i
eval (BinOp op e1 e2) = tell ["Op"] >> liftM2 op (eval e1) (eval e2)
eval (Let x e1 e2)    = do
    tell ["let " ++ x]
    v <- eval e1
    tell ["in"]
    local ((x,v):) (eval e2)
The signature of eval has been extended by Wrapping WriterT [String] around (Reader (Env a)). This denotes a Monad that combines a Reader (Env a) with a Writer [String]. Writer [String] is a Writer that maintains a list of strings as log.
The resulting Monad supports function of both MonadReader and MonadWriter typeclasses. As you can see in the equation for eval (Var x) we are using MonadWriter.tell for logging and MonadReader.asks for obtaining the environment and compose both monadic actions by >>:
eval (Var x) = tell ["lookup " ++ x] >> asks (fetch x)
In order to execute this stacked up monads we have to apply the run functions of WriterT and Reader:
ghci> runReader (runWriterT (eval letExp)) [("pi",pi)]
(6.283185307179586,["let x","let y","Op","5.0","7.0","in","Op","lookup y","6.0","in","Op","lookup pi","lookup x"])
For more details on MonadTransformers please have a look at the following tutorials:
MonadTransformers Wikibook
Monad Transformers step by step
Specifying AOP semantics with MonadTransformers
What we have seen so far is that it possible to form Monad stacks that combine the functionality of the Monads involved: In a way a MonadTransformer adds capabilities that are cross-cutting to those of the underlying Monad.
In the following lines I want to show how MonadTransformers can be used to specify the formal semantics of Aspect Oriented Programming. I have taken the example from Mark P. Jones paper
The Essence of AspectJ.
An interpreter for MiniPascal
We start by defining a simple imperative language – MiniPascal:
-- | an identifier type
type Id = String

-- | Integer expressions
data IExp = Lit Int
    | IExp :+: IExp
    | IExp :*: IExp
    | IExp :-: IExp
    | IExp :/: IExp
    | IVar Id deriving (Show)

-- | Boolean expressions
data BExp = T
    | F
    | Not BExp
    | BExp :&: BExp
    | BExp :|: BExp
    | IExp :=: IExp
    | IExp :<: IExp deriving (Show)

-- | Staments
data Stmt = Skip        -- no op
    | Id := IExp        -- variable assignment
    | Begin [Stmt]      -- a sequence of statements
    | If BExp Stmt Stmt -- an if statement
    | While BExp Stmt   -- a while loop
    deriving (Show)
With this igredients its possible to write imperative programs like the following while loop that sums up the natural numbers from 1 to 10:
-- an example program: the MiniPascal equivalent of `sum [1..10]`
program :: Stmt
program =
    Begin [
        "total" := Lit 0,
        "count" := Lit 0,
        While (IVar "count" :<: Lit 10)
            (Begin [
                "count" := (IVar "count" :+: Lit 1),
                "total" := (IVar "total" :+: IVar "count")
            ])
    ]
We define the semantics of this language with an interpreter:
-- | the store used for variable assignments
type Store = Map Id Int

-- | evaluate numeric expression.
iexp :: MonadState Store m => IExp -> m Int
iexp (Lit n) = return n
iexp (e1 :+: e2) = liftM2 (+) (iexp e1) (iexp e2)
iexp (e1 :*: e2) = liftM2 (*) (iexp e1) (iexp e2)
iexp (e1 :-: e2) = liftM2 (-) (iexp e1) (iexp e2)
iexp (e1 :/: e2) = liftM2 div (iexp e1) (iexp e2)
iexp (IVar i)    = getVar i

-- | evaluate logic expressions
bexp :: MonadState Store m => BExp -> m Bool
bexp T           = return True
bexp F           = return False
bexp (Not b)     = fmap not (bexp b)
bexp (b1 :&: b2) = liftM2 (&&) (bexp b1) (bexp b2)
bexp (b1 :|: b2) = liftM2 (||) (bexp b1) (bexp b2)
bexp (e1 :=: e2) = liftM2 (==) (iexp e1) (iexp e2)
bexp (e1 :<: e2) = liftM2 (<)  (iexp e1) (iexp e2)

-- | evaluate statements
stmt :: MonadState Store m => Stmt -> m ()
stmt Skip       = return ()
stmt (i := e)   = do x <- iexp e; setVar i x
stmt (Begin ss) = mapM_ stmt ss
stmt (If b t e) = do
    x <- bexp b
    if x then stmt t
         else stmt e
stmt (While b t) = loop
    where loop = do
            x <- bexp b
            when x $ stmt t >> loop

-- | a variable assignments updates the store (which is maintained in the state)
setVar :: (MonadState (Map k a) m, Ord k) => k -> a -> m ()
setVar i x = do
    store <- get
    put (Map.insert i x store)

-- | lookup a variable in the store. return 0 if no value is found
getVar :: MonadState Store m => Id -> m Int
getVar i = do
    s <- get
    case Map.lookup i s of
        Nothing  -> return 0
        (Just v) -> return v

-- | evaluate a statement
run :: Stmt -> Store
run s = execState (stmt s) (Map.fromList [])

-- and then in GHCi:
ghci> run program
fromList [("count",10),("total",55)]
So far this is nothing special, just a minimal interpreter for an imperative language. Side effects in form of variable assignments are modelled with an environment that is maintained in a state monad.
In the next step we want to extend this language with features of aspect oriented programming in the style of AspectJ: join points, point cuts, and advices.
An Interpreter for AspectPascal
To keep things simple we will specify only two types of joint points: variable assignment and variable reading:
data JoinPointDesc = Get Id | Set Id
Get i describes a join point at which the variable i is read, while Set i described a join point at which
a value is assigned to the variable i.
Following the concepts of ApectJ pointcut expressions are used to describe sets of join points.
The abstract syntax for pointcuts is as follows:
data PointCut = Setter                  -- the pointcut of all join points at which a variable is being set
              | Getter                  -- the pointcut of all join points at which a variable is being read
              | AtVar Id                -- the point cut of all join points at which a the variable is being set or read
              | NotAt PointCut          -- not a
              | PointCut :||: PointCut  -- a or b
              | PointCut :&&: PointCut  -- a and b
For example this syntax can be used to specify the pointcut of
all join points at which the variable x is set:
The following function computes whether a PointCut contains a given JoinPoint:
includes :: PointCut -> (JoinPointDesc -> Bool)
includes Setter     (Set i) = True
includes Getter     (Get i) = True
includes (AtVar i)  (Get j) = i == j
includes (AtVar i)  (Set j) = i == j
includes (NotAt p)  d       = not (includes p d)
includes (p :||: q) d       = includes p d || includes q d
includes (p :&&: q) d       = includes p d && includes q d
includes _ _                = False
In AspectJ aspect oriented extensions to a program are described using the notion of advices.
We follow the same design here: each advice includes a pointcut to specify the join points at which the
advice should be used, and a statement (in MiniPascal syntax) to specify the action that should be performed at each matching join point.
In AspectPascal we only support two kinds of advice: Before, which will be executed on entry to a join point, and
After which will be executed on the exit from a join point:
data Advice = Before PointCut Stmt
            | After  PointCut Stmt
This allows to define Advices like the following:
-- the countSets Advice traces each setting of a variable and increments the counter "countSet"
countSets = After (Setter :&&: NotAt (AtVar "countSet") :&&: NotAt (AtVar "countGet"))
                  ("countSet" := (IVar "countSet" :+: Lit 1))

-- the countGets Advice traces each lookup of a variable and increments the counter "countGet"
countGets = After (Getter :&&: NotAt (AtVar "countSet") :&&: NotAt (AtVar "countGet"))
                  ("countGet" := (IVar "countGet" :+: Lit 1))
The rather laborious PointCut definition is used to select access to all variable apart from countGet and countSet.
This is required as the action part of the Advices are normal MiniPascal statements that are executed by the same interpreter as the main program which is to be extended by advices. If those filters were not present execution of those advices would result in non-terminating loops, as the action statements also access variables.
A complete AspectPascal program will now consist of a stmt (the original program) plus a list of advices that should be executed to implement the cross-cutting aspects:
-- | Aspects are just a list of Advices
type Aspects = [Advice]
In order to extend our interpreter to execute additional behaviour decribed in advices we will have to provide all evaluating functions with access to the Aspects.
As the Aspects will not be modified at runtime the typical solution would be to provide them by a Reader Aspects monad.
We already have learnt that we can use a MonadTransformer to stack our existing State monad with a Reader monad. The respective Transformer is ReaderT.
We thus extend the signature of the evaluation functions accordingly, eg:
-- from:
iexp :: MonadState Store m => IExp -> m Int

-- to:
iexp :: MonadState Store m => IExp -> ReaderT Aspects m Int
Apart from extendig the signatures we have to modify all places where variables are accessed to apply the matching advices.
So for instance in the equation for iexp (IVar i) we specify that (getVar i) should be executed with applying all advices that match the read access to variable i – that is (Get i) by writing:
iexp (IVar i) = withAdvice (Get i) (getVar i)
So the complete definition of iexp is:
iexp :: MonadState Store m => IExp -> ReaderT Aspects m Int
iexp (Lit n) = return n
iexp (e1 :+: e2) = liftM2 (+) (iexp e1) (iexp e2)
iexp (e1 :*: e2) = liftM2 (*) (iexp e1) (iexp e2)
iexp (e1 :-: e2) = liftM2 (-) (iexp e1) (iexp e2)
iexp (e1 :/: e2) = liftM2 div (iexp e1) (iexp e2)
iexp (IVar i)    = withAdvice (Get i) (getVar i)
[...] if c is a computation corresponding to some join point with description d, then withAdvice d c wraps the
execution of c with the execution of the appropriate Before and After advice, if any:
withAdvice :: MonadState Store m => JoinPointDesc -> ReaderT Aspects m a -> ReaderT Aspects m a
withAdvice d c = do
    aspects <- ask                -- obtaining the Aspects from the Reader monad
    mapM_ stmt (before d aspects) -- execute the statements of all Before advices
    x <- c                        -- execute the actual business logic
    mapM_ stmt (after d aspects)  -- execute the statements of all After advices
    return x

-- collect the statements of Before and After advices matching the join point
before, after :: JoinPointDesc -> Aspects -> [Stmt]
before d as = [s | Before c s <- as, includes c d]
after  d as = [s | After  c s <- as, includes c d]
In the same way the equation for variable assignment stmt (i := e) we specify that (setVar i x) should be executed with applying all advices that match the write access to variable i – that is (Set i) by noting:
stmt (i := e) = do x <- iexp e; withAdvice (Set i) (setVar i x)
The complete implementation for stmt then looks like follows:
stmt :: MonadState Store m => Stmt -> ReaderT Aspects m ()
stmt Skip       = return ()
stmt (i := e)   = do x <- iexp e; withAdvice (Set i) (setVar i x)
stmt (Begin ss) = mapM_ stmt ss
stmt (If b t e) = do
    x <- bexp b
    if x then stmt t
         else stmt e
stmt (While b t) = loop
    where loop = do
            x <- bexp b
            when x $ stmt t >> loop
Finally we have to extend run function to properly handle the monad stack:
run :: Aspects -> Stmt -> Store
run a s = execState (runReaderT (stmt s) a) (Map.fromList [])

-- and then in GHCi:
ghci> run [] program
fromList [("count",10),("total",55)]

ghci> run [countSets] program
fromList [("count",10),("countSet",22),("total",55)]

ghci> run [countSets, countGets] program
fromList [("count",10),("countGet",41),("countSet",22),("total",55)]
So executing the program with an empty list of advices yields the same result as executing the program with initial interpreter. Once we execute the program with the advices countGets and countSets the resulting map contains values for the variables countGet and countSet which have been incremented by the statements of both advices.
We have utilized Monad Transformers to extend our original interpreter in a minamally invasive way, to provide a formal and executable semantics for a simple aspect-oriented language in the style of AspectJ.
Composite → SemiGroup → Monoid
In software engineering, the composite pattern is a partitioning design pattern. The composite pattern describes a group of objects that is treated the same way as a single instance of the same type of object. The intent of a composite is to "compose" objects into tree structures to represent part-whole hierarchies. Implementing the composite pattern lets clients treat individual objects and compositions uniformly.
(Quoted from Wikipedia)
A typical example for the composite pattern is the hierarchical grouping of test cases to TestSuites in a testing framework. Take for instance the following class diagram from the JUnit cooks tour which shows how JUnit applies the Composite pattern to group TestCases to TestSuites while both of them implement the Test interface:

In Haskell we could model this kind of hierachy with an algebraic data type (ADT):
-- the composite data structure: a Test can be either a single TestCase
-- or a TestSuite holding a list of Tests
data Test = TestCase TestCase
          | TestSuite [Test]

-- a test case produces a boolean when executed
type TestCase = () -> Bool
The function run as defined below can either execute a single TestCase or a composite TestSuite:
-- execution of a Test.
run :: Test -> Bool
run (TestCase t)  = t () -- evaluating the TestCase by applying t to ()
run (TestSuite l) = all (True ==) (map run l) -- running all tests in l and return True if all tests pass

-- a few most simple test cases
t1 :: Test
t1 = TestCase (\() -> True)
t2 :: Test
t2 = TestCase (\() -> True)
t3 :: Test
t3 = TestCase (\() -> False)
-- collecting all test cases in a TestSuite
ts = TestSuite [t1,t2,t3]
As run is of type run :: Test -> Bool we can use it to execute single TestCases or complete TestSuites.
Let's try it in GHCI:
ghci> run t1
True
ghci> run ts
False
In order to aggregate TestComponents we follow the design of JUnit and define a function addTest. Adding two atomic Tests will result in a TestSuite holding a list with the two Tests. If a Test is added to a TestSuite, the test is added to the list of tests of the suite. Adding TestSuites will merge them.
-- adding Tests
addTest :: Test -> Test -> Test
addTest t1@(TestCase _) t2@(TestCase _)   = TestSuite [t1,t2]
addTest t1@(TestCase _) (TestSuite list)  = TestSuite ([t1] ++ list)
addTest (TestSuite list) t2@(TestCase _)  = TestSuite (list ++ [t2])
addTest (TestSuite l1) (TestSuite l2)     = TestSuite (l1 ++ l2)
If we take a closer look at addTest we will see that it is a associative binary operation on the set of Tests.
In mathemathics a set with an associative binary operation is a Semigroup.
We can thus make our type Test an instance of the type class Semigroup with the following declaration:
instance Semigroup Test where
    (<>)   = addTest
What's not visible from the JUnit class diagram is how typical object oriented implementations will have to deal with null-references. That is the implementations would have to make sure that the methods run and addTest will handle empty references correctly.
With Haskells algebraic data types we would rather make this explicit with a dedicated Empty element.
Here are the changes we have to add to our code:
-- the composite data structure: a Test can be Empty, a single TestCase
-- or a TestSuite holding a list of Tests
data Test = Empty
          | TestCase TestCase
          | TestSuite [Test]

-- execution of a Test.
run :: Test -> Bool
run Empty         = True -- empty tests will pass
run (TestCase t)  = t () -- evaluating the TestCase by applying t to ()
--run (TestSuite l) = foldr ((&&) . run) True l
run (TestSuite l) = all (True ==) (map run l) -- running all tests in l and return True if all tests pass

-- addTesting Tests
addTest :: Test -> Test -> Test
addTest Empty t                           = t
addTest t Empty                           = t
addTest t1@(TestCase _) t2@(TestCase _)   = TestSuite [t1,t2]
addTest t1@(TestCase _) (TestSuite list)  = TestSuite ([t1] ++ list)
addTest (TestSuite list) t2@(TestCase _)  = TestSuite (list ++ [t2])
addTest (TestSuite l1) (TestSuite l2)     = TestSuite (l1 ++ l2)
From our additions it's obvious that Empty is the identity element of the addTest function. In Algebra a Semigroup with an identity element is called Monoid:
In abstract algebra, [...] a monoid is an algebraic structure with a single associative binary operation and an identity element.
Quoted from Wikipedia
With haskell we can declare Test as an instance of the Monoid type class by defining:
instance Monoid Test where
    mempty = Empty
We can now use all functions provided by the Monoid type class to work with our Test:
compositeDemo = do
    print $ run $ t1 <> t2
    print $ run $ t1 <> t2 <> t3
We can also use the function mconcat :: Monoid a => [a] -> a on a list of Tests: mconcat composes a list of Tests into a single Test. That's exactly the mechanism of forming a TestSuite from atomic TestCases.
compositeDemo = do
    print $ run $ mconcat [t1,t2]
    print $ run $ mconcat [t1,t2,t3]
This particular feature of mconcat :: Monoid a => [a] -> a to condense a list of Monoids to a single Monoid can be used to drastically simplify the design of our test framework.
We need just one more hint from our mathematician friends:
Functions are monoids if they return monoids
Quoted from blog.ploeh.dk
Currently our TestCases are defined as functions yielding boolean values:
type TestCase = () -> Bool
If Bool was a Monoid we could use mconcat to form test suite aggregates. Bool in itself is not a Monoid; but together with a binary associative operation like (&&) or (||) it will form a Monoid.
The intuitive semantics of a TestSuite is that a whole Suite is "green" only when all enclosed TestCases succeed. That is the conjunction of all TestCases must return True.
So we are looking for the Monoid of boolean values under conjunction (&&). In Haskell this Monoid is called All):
-- | Boolean monoid under conjunction ('&&').
-- >>> getAll (All True <> mempty <> All False)
-- False
-- >>> getAll (mconcat (map (\x -> All (even x)) [2,4,6,7,8]))
-- False
newtype All = All { getAll :: Bool }

instance Semigroup All where
        (<>) = coerce (&&)

instance Monoid All where
        mempty = All True
Making use of All our improved definition of TestCases is as follows:
type SmartTestCase = () -> All
Now our test cases do not directly return a boolean value but an All wrapper, which allows automatic conjunction of test results to a single value.
Here are our redefined TestCases:
tc1 :: SmartTestCase
tc1 () = All True
tc2 :: SmartTestCase
tc2 () = All True
tc3 :: SmartTestCase
tc3 () = All False
We now implement a new evaluation function run' which evaluates a SmartTestCase (which may be either an atomic TestCase or a TestSuite assembled by mconcat) to a single boolean result.
run' :: SmartTestCase -> Bool
run' tc = getAll $ tc ()
This version of run is much simpler than the original and we can completely avoid the rather laborious addTest function. We also don't need any composite type Test.
By just sticking to the Haskell built-in type classes we achieve cleanly designed functionality with just a few lines of code.
compositeDemo = do
    -- execute a single test case
    print $ run' tc1

    --- execute a complex test suite
    print $ run' $ mconcat [tc1,tc2]
    print $ run' $ mconcat [tc1,tc2,tc3]
For more details on Composite as a Monoid please refer to the following blog:
Composite as Monoid
Sourcecode for this section
Visitor → Foldable
[...] the visitor design pattern is a way of separating an algorithm from an object structure on which it operates. A practical result of this separation is the ability to add new operations to existent object structures without modifying the structures. It is one way to follow the open/closed principle.
(Quoted from Wikipedia)
In functional languages - and Haskell in particular - we have a whole armada of tools serving this purpose:
- higher order functions like map, fold, filter and all their variants allow to "visit" lists
- The Haskell type classes
Functor, Foldable, Traversable, etc. provide a generic framework to allow visiting any algebraic datatype by just deriving one of these type classes.
Using Foldable
-- we are re-using the Exp data type from the Singleton example
-- and transform it into a Foldable type:
instance Foldable Exp where
    foldMap f (Val x)   = f x
    foldMap f (Add x y) = foldMap f x `mappend` foldMap f y
    foldMap f (Mul x y) = foldMap f x `mappend` foldMap f y

filterF :: Foldable f => (a -> Bool) -> f a -> [a]
filterF p = foldMap (\a -> if p a then [a] else [])

visitorDemo = do
    let exp = Mul (Add (Val 3) (Val 2))
                  (Mul (Val 4) (Val 6))
    putStr "size of exp: "
    print $ length exp
    putStrLn "filter even numbers from tree"
    print $ filterF even exp
By virtue of the instance declaration Exp becomes a Foldable instance an can be used with arbitrary functions defined on Foldable like length in the example.
foldMap can for example be used to write a filtering function filterFthat collects all elements matching a predicate into a list.
Alternative approaches
Visitory as Sum type
Sourcecode for this section
Iterator → Traversable
[...] the iterator pattern is a design pattern in which an iterator is used to traverse a container and access the container's elements. The iterator pattern decouples algorithms from containers; in some cases, algorithms are necessarily container-specific and thus cannot be decoupled.
Quoted from Wikipedia
Iterating over a Tree
The most generic type class enabling iteration over algebraic data types is Traversable as it allows combinations of map and fold operations.
We are re-using the Exp type from earlier examples to show what's needed for enabling iteration in functional languages.
instance Functor Exp where
    fmap f (Var x)       = Var x
    fmap f (Val a)       = Val $ f a
    fmap f (Add x y)     = Add (fmap f x) (fmap f y)
    fmap f (Mul x y)     = Mul (fmap f x) (fmap f y)

instance Traversable Exp where
    traverse g (Var x)   = pure $ Var x
    traverse g (Val x)   = Val <$> g x
    traverse g (Add x y) = Add <$> traverse g x <*> traverse g y
    traverse g (Mul x y) = Mul <$> traverse g x <*> traverse g y
With this declaration we can traverse an Exp tree:
iteratorDemo = do
    putStrLn "Iterator -> Traversable"
    let exp = Mul (Add (Val 3) (Val 1))
                (Mul (Val 2) (Var "pi"))
        env = [("pi", pi)]
    print $ traverse (\x c -> if even x then [x] else [2*x]) exp 0
In this example we are touching all (nested) Val elements and multiply all odd values by 2.
Combining traversal operations
Compared with Foldable or Functor the declaration of a Traversable instance looks a bit intimidating. In particular the type signature of traverse:
traverse :: (Traversable t, Applicative f) => (a -> f b) -> t a -> f (t b)
looks like quite a bit of over-engineering for simple traversals as in the above example.
In oder to explain the real power of the Traversable type class we will look at a more sophisticated example in this section. This example was taken from the paper
The Essence of the Iterator Pattern.
The Unix utility wc is a good example for a traversal operation that performs