WindowsAgentArena
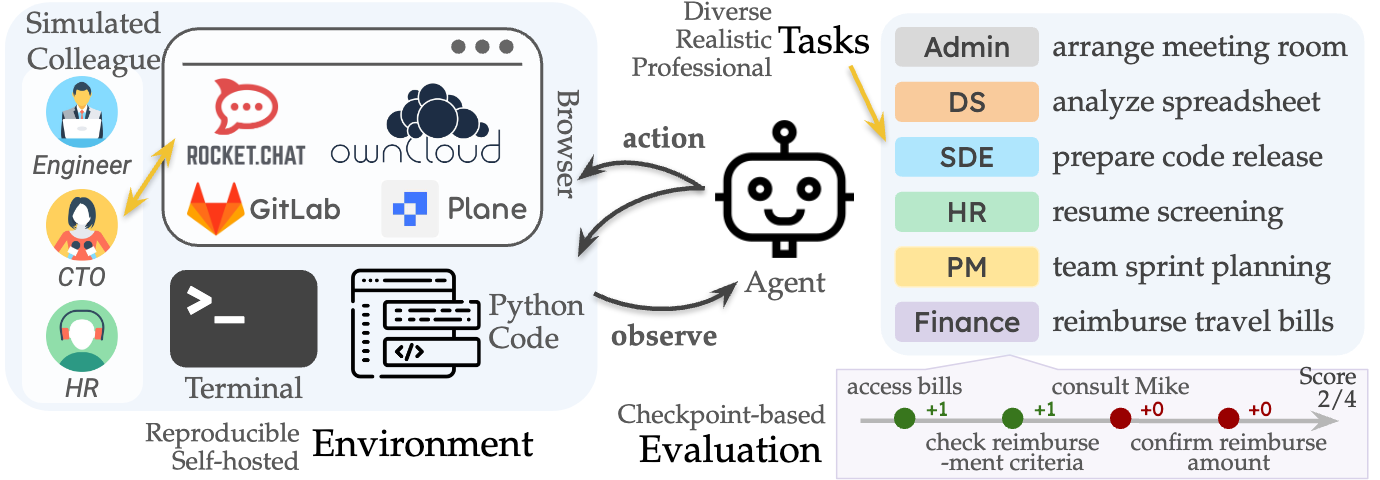
Windows Agent Arena (WAA) 🪟 is a scalable OS platform for testing and benchmarking of multi-modal AI agents.
- 917
- Python
- MIT
- 4 wk ago
Windows Agent Arena (WAA) 🪟 is a scalable OS platform for testing and benchmarking of multi-modal AI agents.
Track 52,867+ AI benchmark, eval, dataset, and data-quality records from 41 public sources, with linked evidence and daily updates.
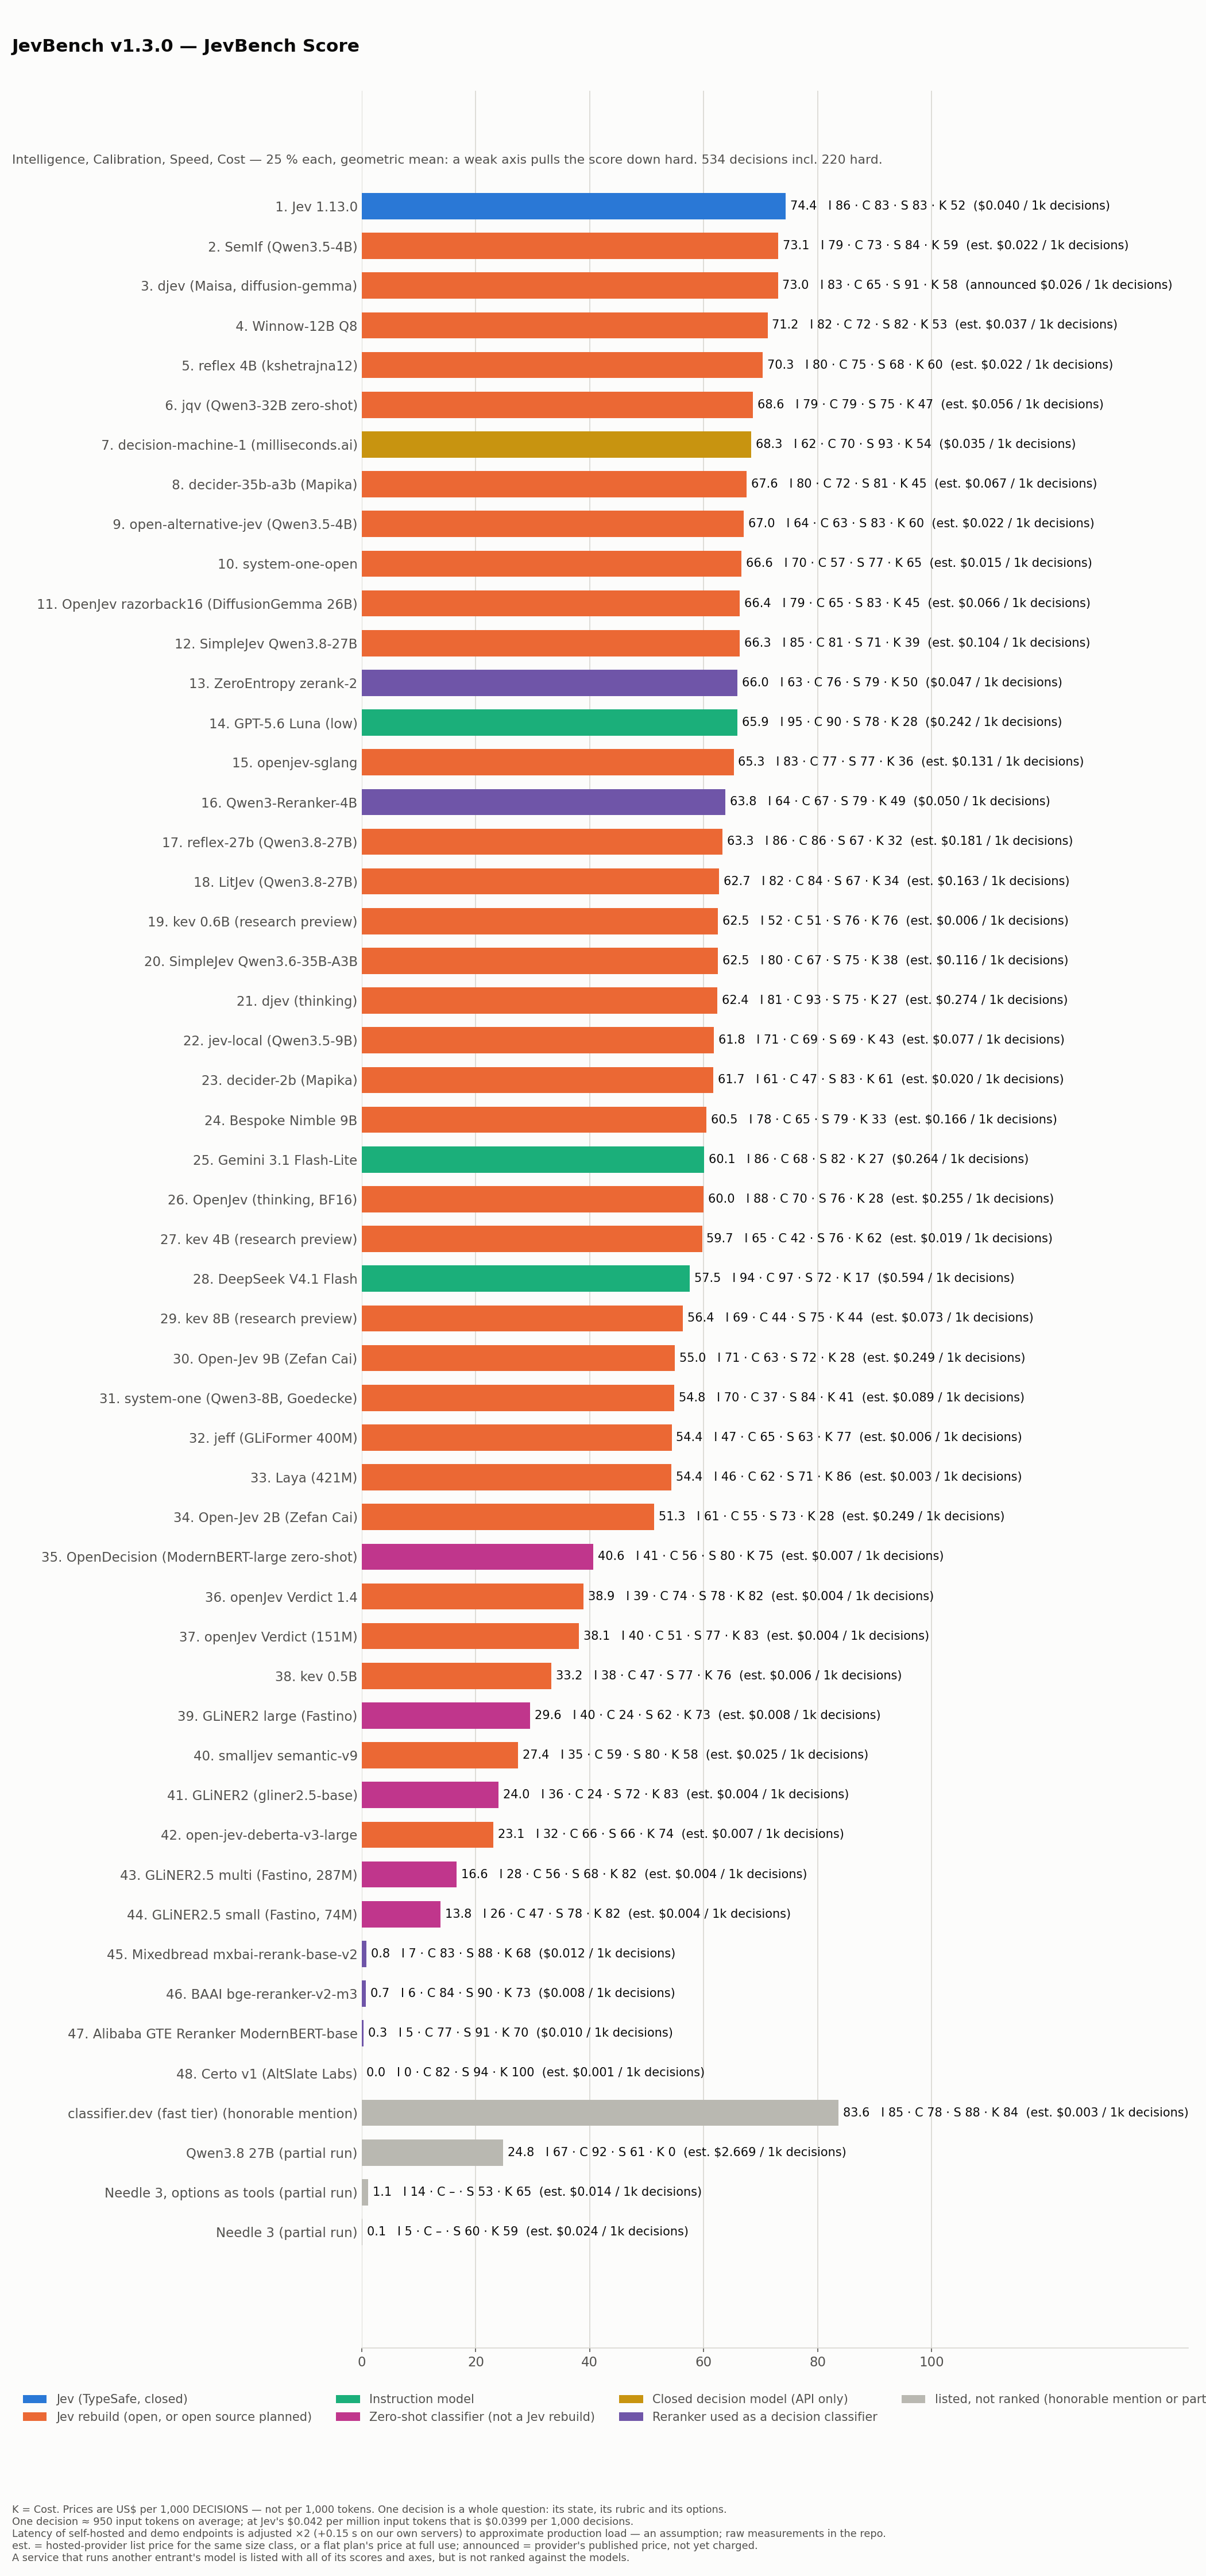
JevBench by Benchmark Heaven: benchmark and leaderboard for AI decision models, measuring typed decision accuracy, calibration, latency and cost.
The definitive benchmark for AI agents on OpenClaw. 45 tasks across 4 tiers. Powered by MyClaw.ai
开源劳动者AI研究与评测项目:建设劳动知识、公开评测基准与共同治理机制|Open worker-centered AI research and evaluation project.
AI Stupid Level — independent, continuous LLM benchmarks (coding, reasoning, tool use), drift detection and a benchmark-driven Smart Router. Web app source; methodology public, test tasks private.
🤖 A curated list of resources for testing AI agents - frameworks, methodologies, benchmarks, tools, and best practices for ensuring reliable, safe, and effective autonomous AI systems
llmBench is a high-depth benchmarking tool designed to measure the raw performance of local LLM runtimes (Ollama, llama.cpp) while providing deep hardware intelligence.
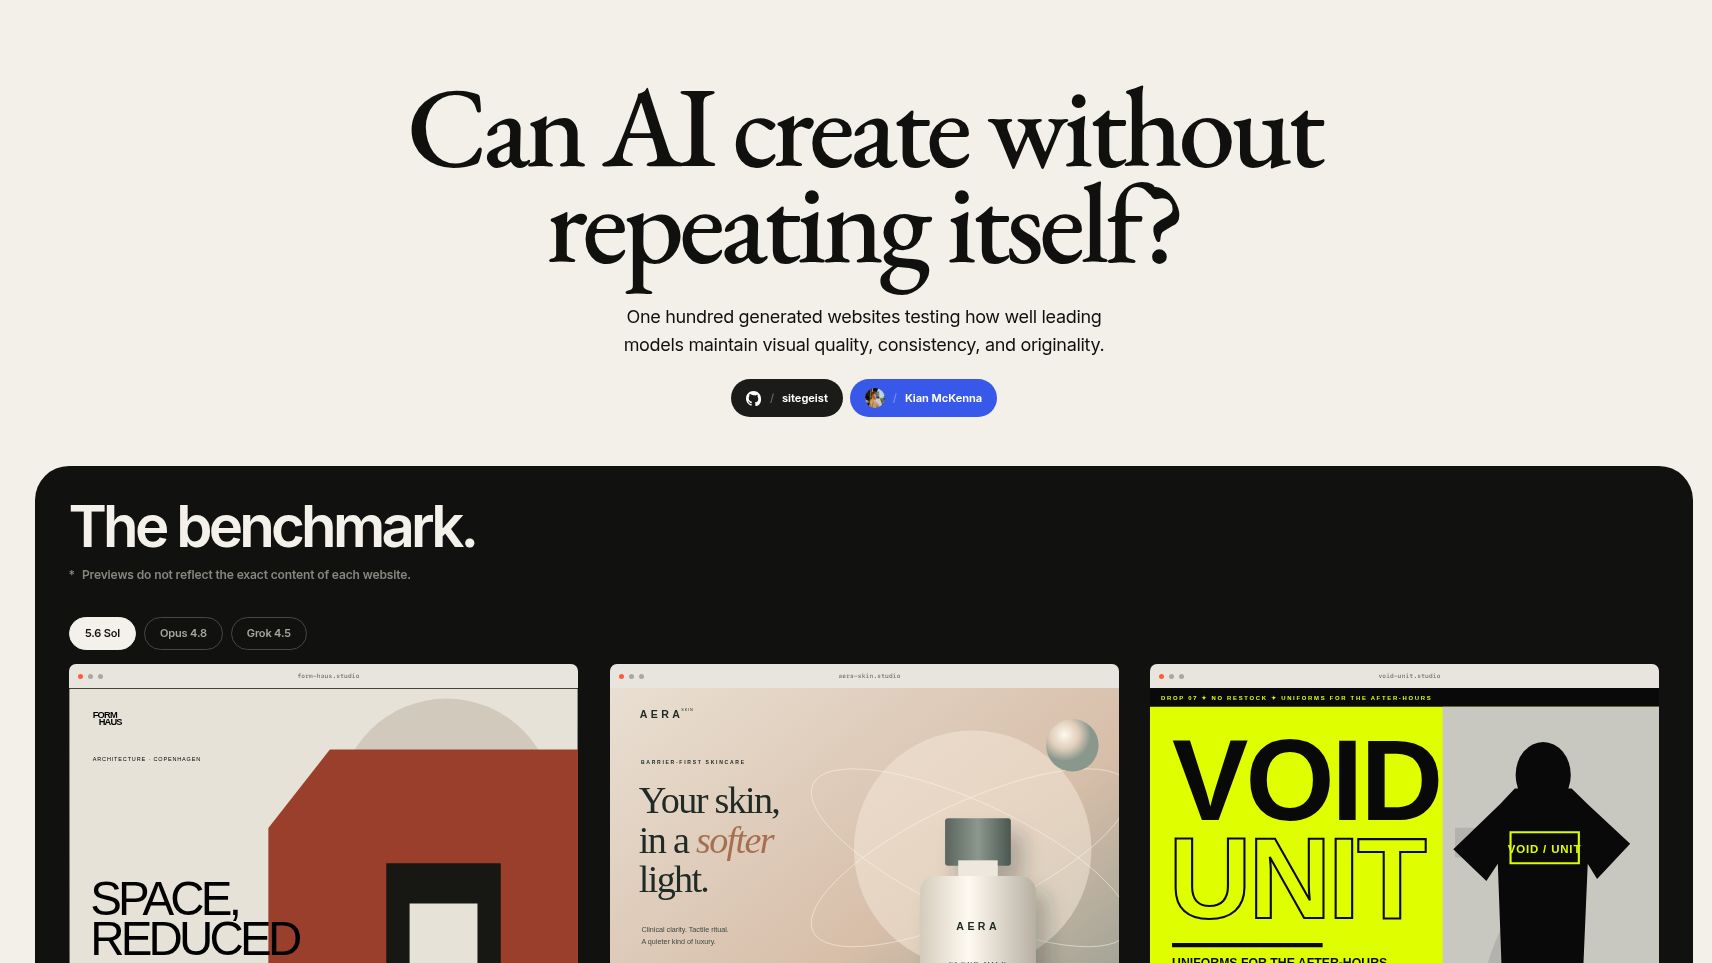
A visual benchmark testing whether leading coding agents repeat the same design patterns across 100 neutral website briefs.
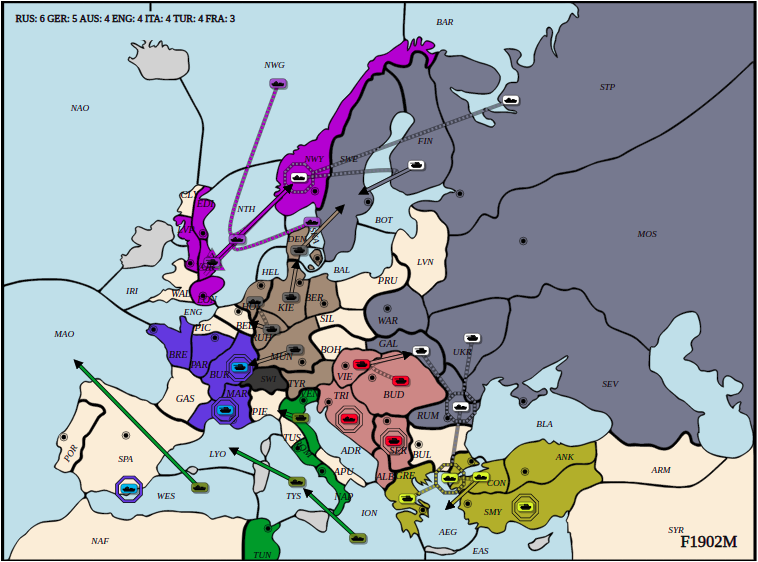
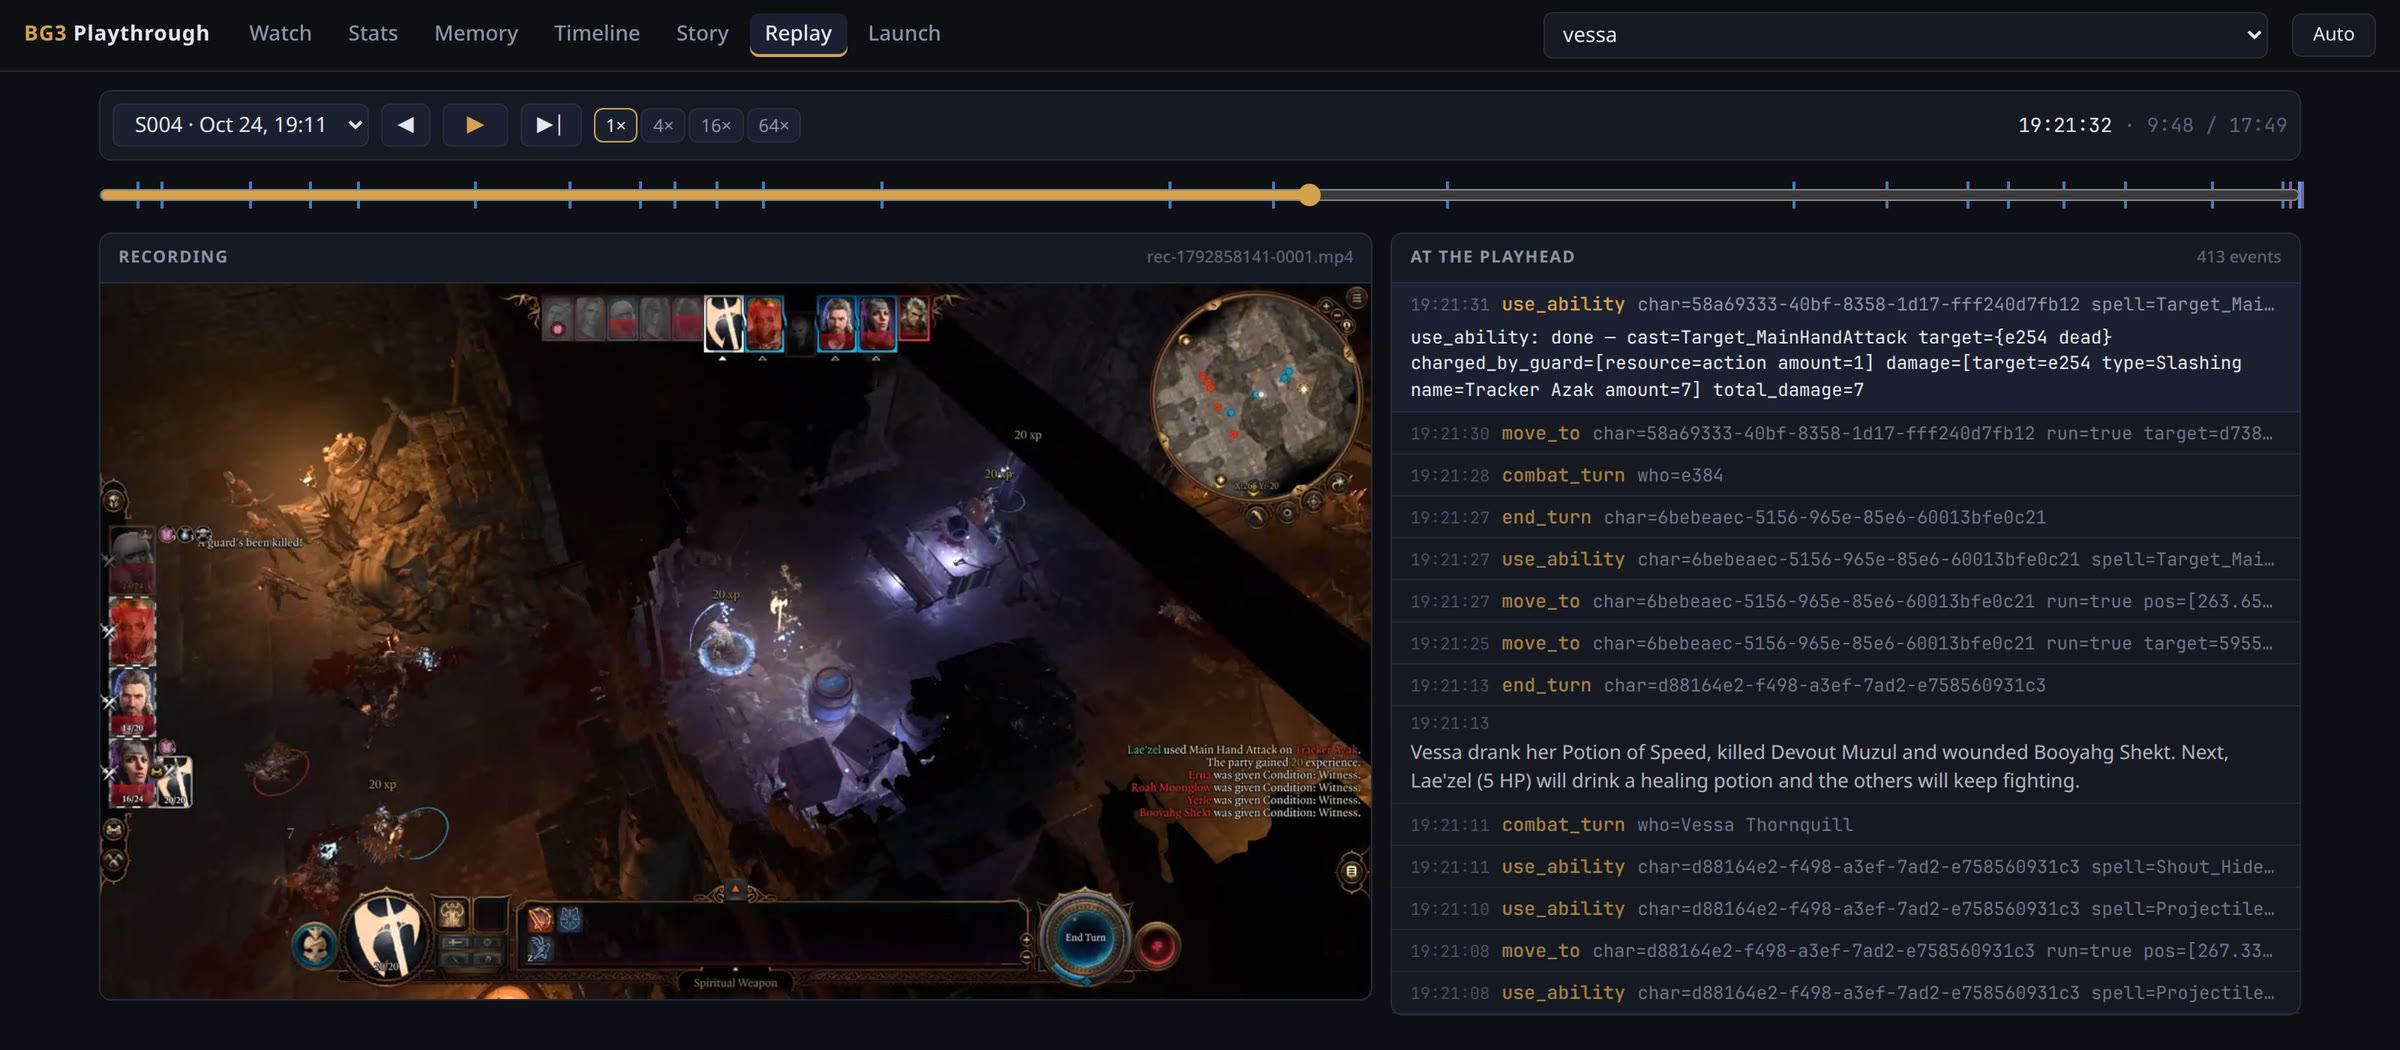
An AI agent plays Baldur's Gate 3 on Linux through a Lua mod and an MCP server, seeing only what a player sees. Includes a model benchmark and a playthrough app.
📊 Daily auto-updated snapshots of all Arena AI (LMSYS Chatbot Arena) leaderboards — LLM, Vision, Code, Video, Image & more. Structured JSON with historical tracking.
Benchmarking and evaluation resources for trust, robustness, and reliability analysis in graph-based AI systems.
Benchmark abierto en español de modelos de IA para negocios y agentes, con juez independiente (Phi-4). Calidad, costo, velocidad, contexto largo, trabajo agéntico y fuga de credenciales, cada uno por separado. Calculadora interactiva con tus propios pesos.
MindTrial: Evaluate and compare AI language models (LLMs) on text-based tasks with optional file/image attachments and tool use. Supports multiple providers (OpenAI, Google, Anthropic, DeepSeek, Mistral AI, xAI, Alibaba, Moonshot AI, OpenRouter), custom tasks in YAML, and HTML/CSV/JSON reports.
中国创作者给全球 AI 出的一场真实大考 | A searchable index of Bilibili AI Infinite Arena videos.
This repository contains the results and code for the MLPerf™ Storage v2.0 benchmark.
Open Cyber LLM Arena | A transparent, crowdsourced benchmarking platform for evaluating Large Language Models (LLMs) on cybersecurity tasks.
亚里 · Kimi K3.1 Pro 实测:四道前端题的提示词和作品(对比 GPT-6 Astra、Claude Opus 5.5、DeepSeek 1017)
Forecasting bot for the Metaculus FutureEval tournaments and MiniBench, running on Claude Code headless
AI 大模型第三方权威排行榜聚合:LMArena、Artificial Analysis、LiveCodeBench、SuperCLUE、HF Open LLM。无后端纯静态站,GitHub Actions 每日自动抓取更新,含升降箭头/性价比象限/历史趋势。 | Independent AI model leaderboard aggregator - zero-backend static site, auto-updated daily.
Measured AI coding-session benchmarks with regional API-price snapshots, sanitized run data and a static model-cost comparison site.