ai-evaluation

Open repos and models their makers tagged ai-evaluation, most starred first. The same for everyone.

Developer toolsRepo

iFixAi

Independent Auditing of AI Agents. Run by human or the agent itself, to answer the most crucial question in the AI Agent Economy. Is the agent doing what is supposed to do? With iFixAi you can have this answer in less than 120 seconds.

  • 46k
  • Python
  • Apache-2.0
  • 24 h ago
ifixai-aiTake it
Developer toolsRepo

agent-replay

agent-replay is a 100% local, SQLite-powered CLI tool for time-travel debugging AI agents that lets you replay execution traces, diff behavioral changes, fork runs to test fixes, and run AI-powered evaluations or safety guardrails to eliminate hallucinations and production failures.

  • 15
  • TypeScript
  • MIT
  • 2 mo ago
clay-goodTake it
AI on my own machineRepo

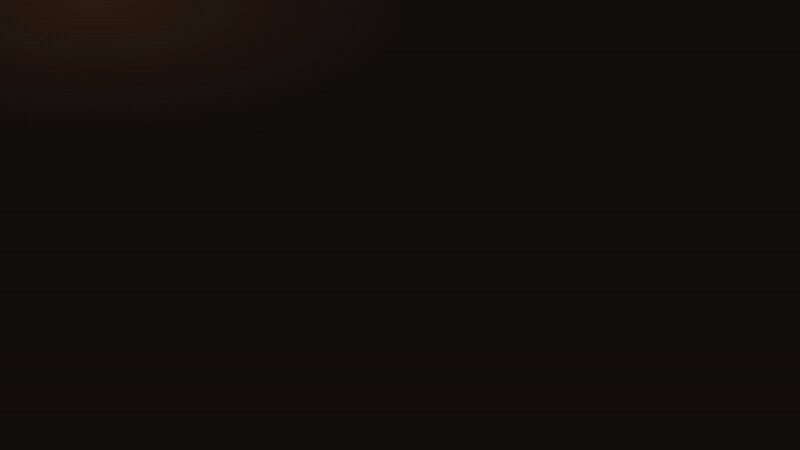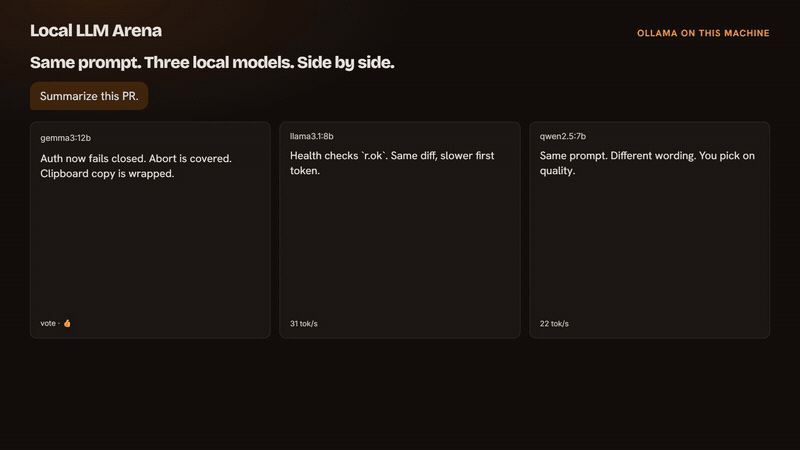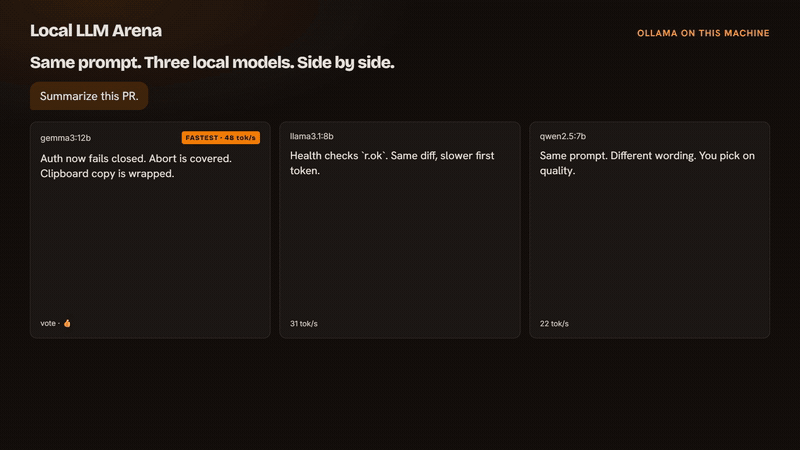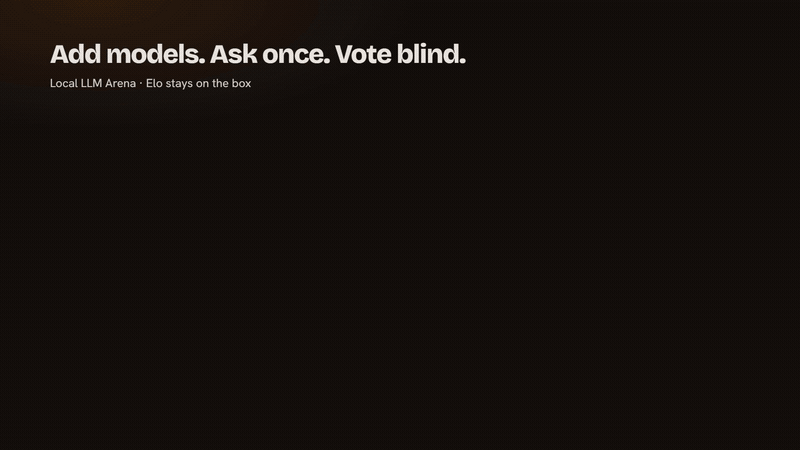
Local-LLM-Arena

Privacy-first local AI model comparison platform with blind evaluation, per-model hyperparameters, and multi-configuration testing. Compare 2-6 models side-by-side through Ollama with zero cloud dependencies.

  • 10
  • TypeScript
  • MIT
  • 6 wk ago
sammy995Take it
Language and translationRepo

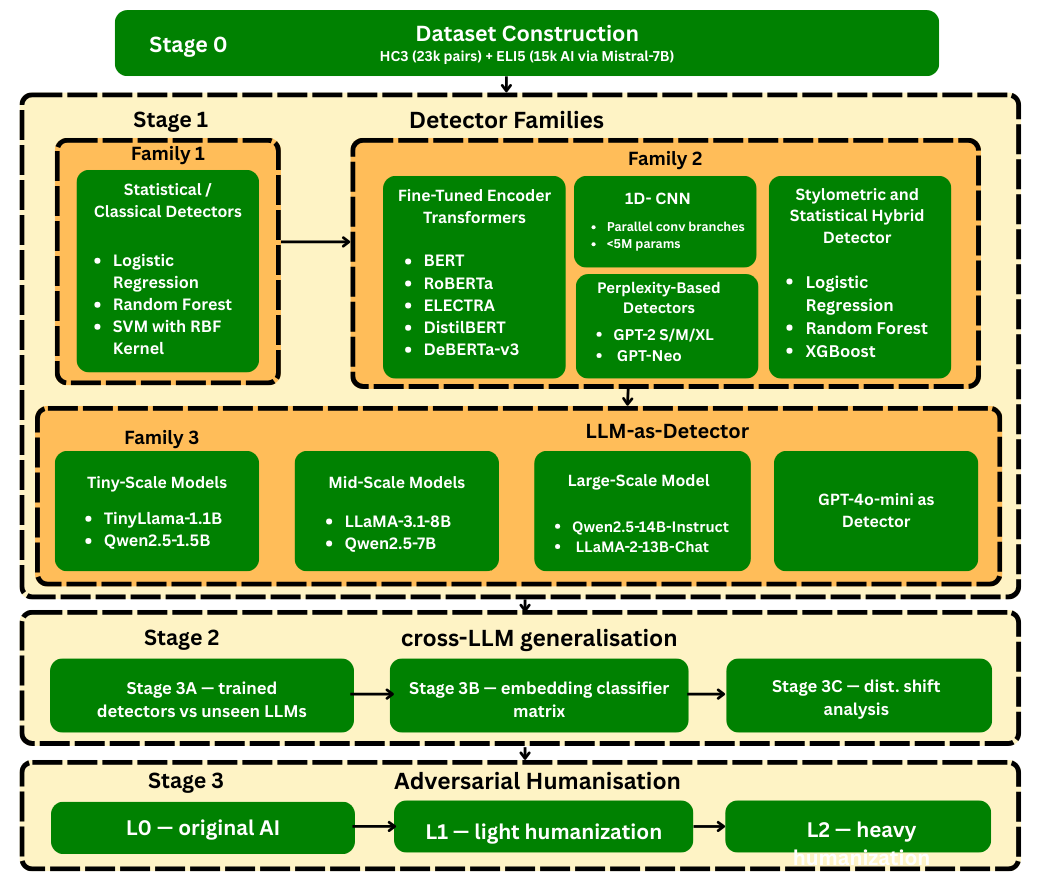
Detecting-the-Machine-A-Comprehensive-Benchmark-of-AI-Generated-Text-Detectors-Across-Architectures

This project aims to address this gap by conducting a systematic, controlled study of human versus LLM-generated text detectability using paired question–answer datasets. Rather than proposing a novel detection architecture, the focus is on analyzing detection robustness, failure modes, and the impact of adversarial humanization strategies.

  • 8
  • Jupyter Notebook
  • MIT
  • 8 mo ago
MadsDoodleTake it
Search GitHub and Hugging Face for ai-evaluation

Get , open it once and sign in. Then come back here and press the button again.