openvals
Open-source AI model evaluation and benchmarking framework for LLMs (OpenAI, Ollama, Claude, Gemini)
- 51
- Python
- 10 d ago
Open-source AI model evaluation and benchmarking framework for LLMs (OpenAI, Ollama, Claude, Gemini)
📚 A curated list of papers & technical articles on AI Quality & Safety
GEDD turns domain-expert judgment into one failure codebook, then derives your evaluation, your training reward and your response gate from it.
A framework-agnostic metric for measuring AI code generation quality. Sealed-envelope testing protocol + reference validators.
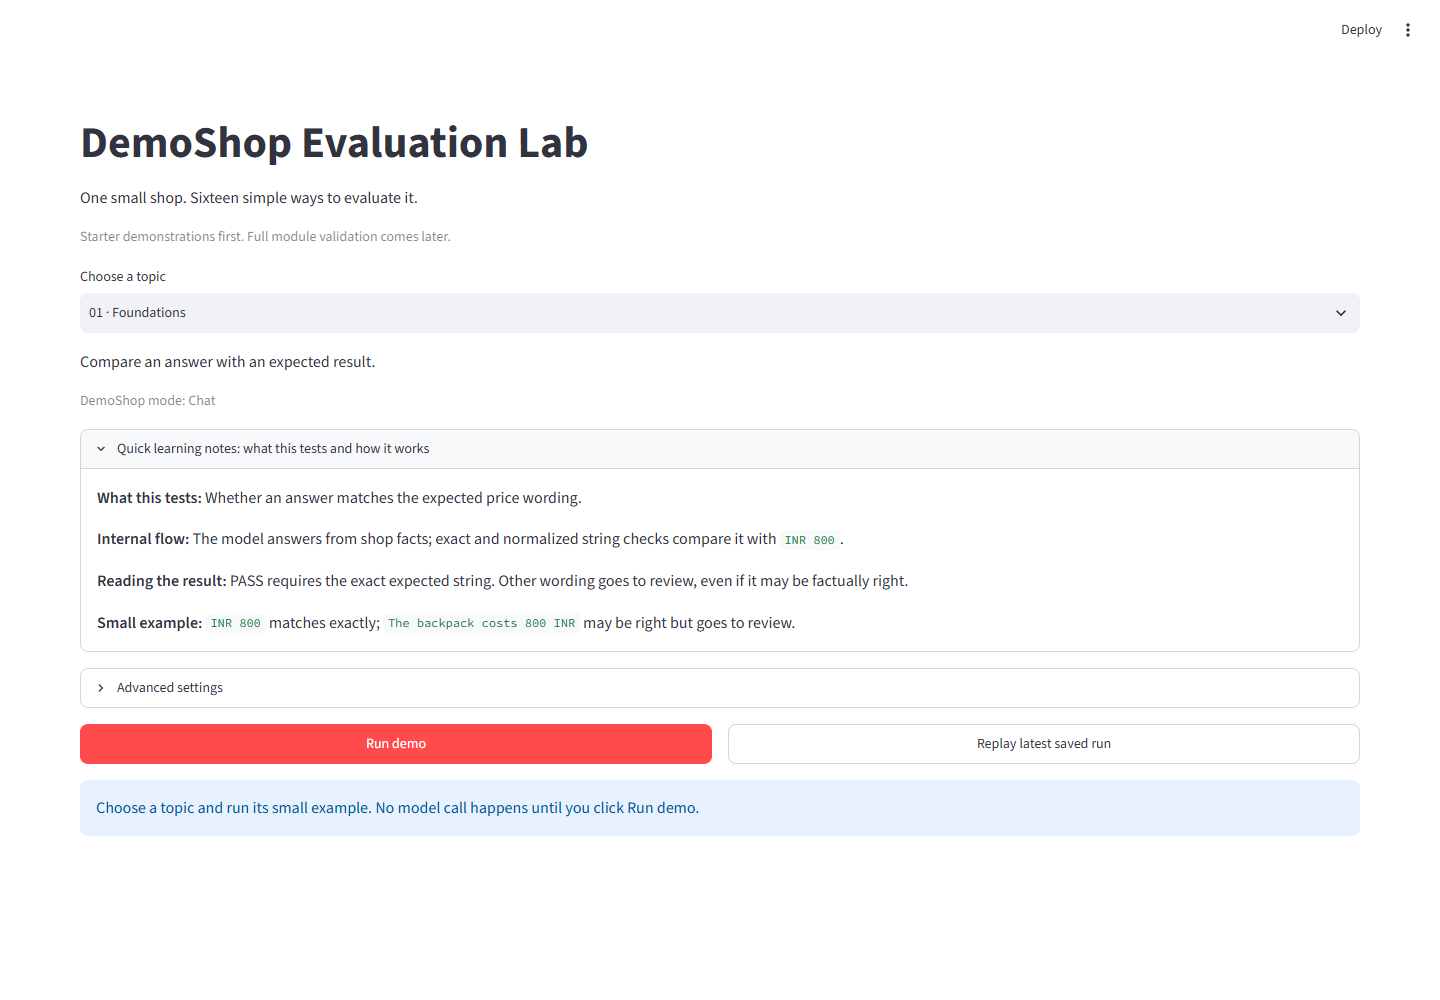
A practical, AI evalution repo covering LLMs, RAG, MCP, skills, agents, multi-agent systems, security, reliability evaluations
Reference platform for AI-agent evaluation using multi-provider LLM-as-a-judge scoring, regression tests, A/B benchmarks, and safety checks.
LLM loop that reasons in a dense technical register — mechanical gates + adversarial judge + reverse-translation for humans. Self-upgrading. Standalone or as a DSH plugin.