rm-accel
ai-rm L1: accelerator discovery and AcceleratorProfile publishing for GPUs and NPUs (FuriosaAI RNGD, Rebellions ATOM), plus a vLLM-compatible API
- 1
- Python
- BSD-3-Clause
- 5 wk ago
ai-rm L1: accelerator discovery and AcceleratorProfile publishing for GPUs and NPUs (FuriosaAI RNGD, Rebellions ATOM), plus a vLLM-compatible API
Content-addressed store for model weights and accelerator-compiled artifacts on Kubernetes + llm-d
Feasibility study: switching NPU compiled graphs (sequence length, batch) while the weights stay loaded — ATOM and RNGD
Heterogeneous AI resource integration for Kubernetes + llm-d, with Optimus Prime and FASOP as engine consolidation targets.
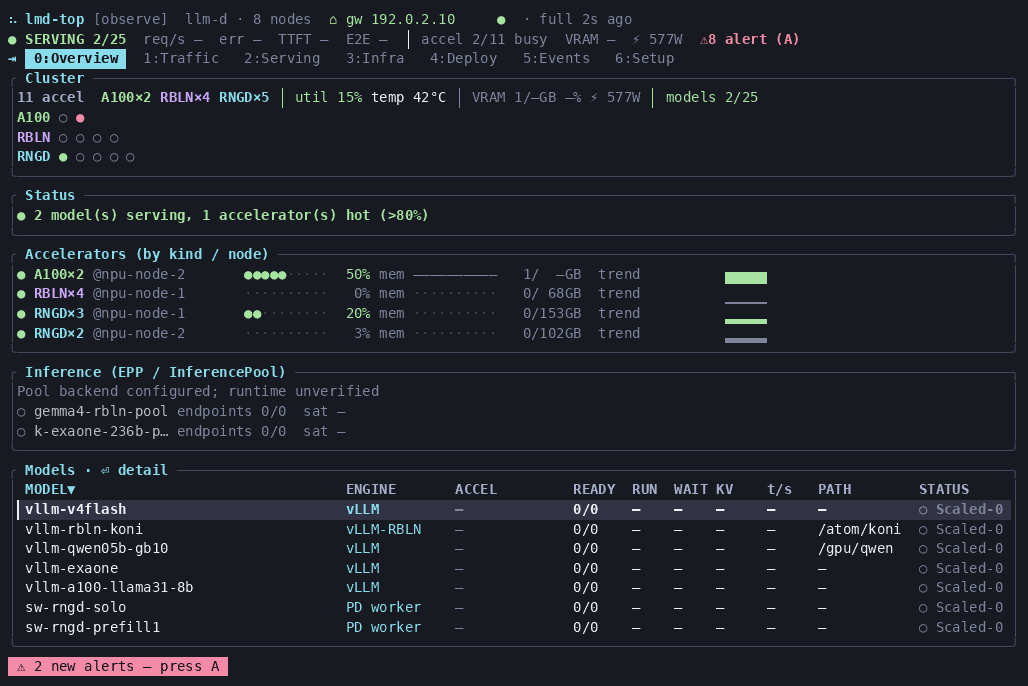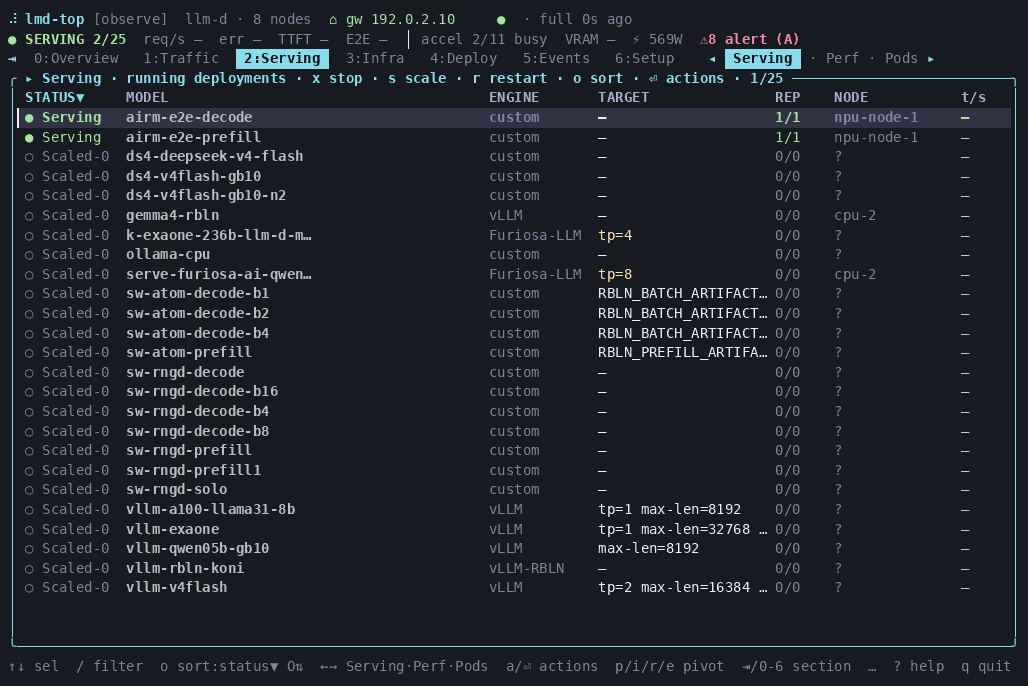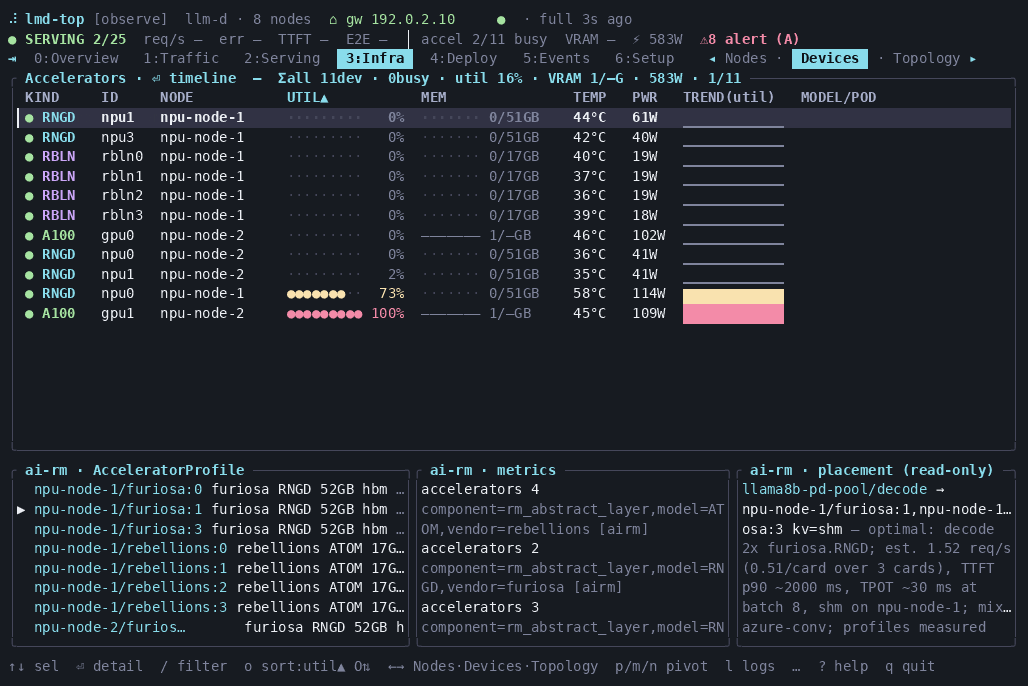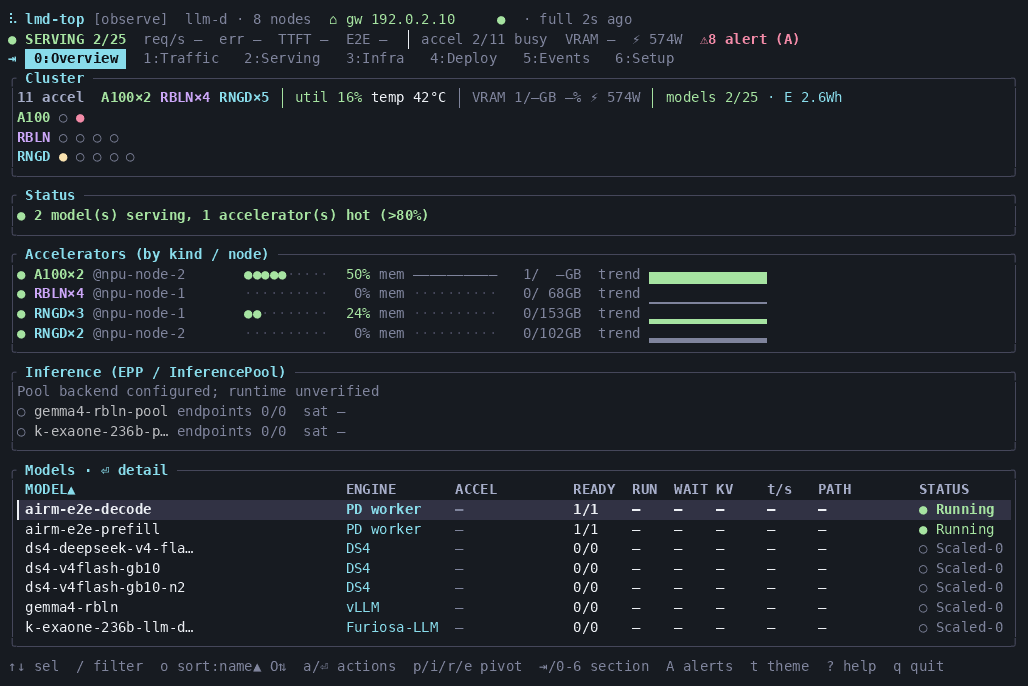
Terminal UI for observing and operating heterogeneous Kubernetes + llm-d clusters
Contracts that connect ai-rm components: accelerators, memory tiers, KV transport, placement, metrics (protocol v0.1)
PD-disaggregated serving across Furiosa RNGD (prefill) and Rebellions ATOM (decode) as llm-d pods
K8s + llm-d heterogeneous cluster (A100, RNGD, ATOM, CPU): manifests, EPP, model store, monitoring
Completion-fenced same-host heterogeneous NPU KV transport (RNGD -> ATOM), llm-d stage integration
LoRA / full fine-tuning on inference-only RNGD NPU (npu-lora), compared against A100
RNGD MoE expert offloading (hot experts on NPU HBM, cold experts on host CPU)