vllm
A high-throughput and memory-efficient inference and serving engine for LLMs
- 97k
- Python
- Apache-2.0
- 43 min ago
A high-throughput and memory-efficient inference and serving engine for LLMs
Ray is an AI compute engine. Ray consists of a core distributed runtime and a set of AI Libraries for accelerating ML workloads.
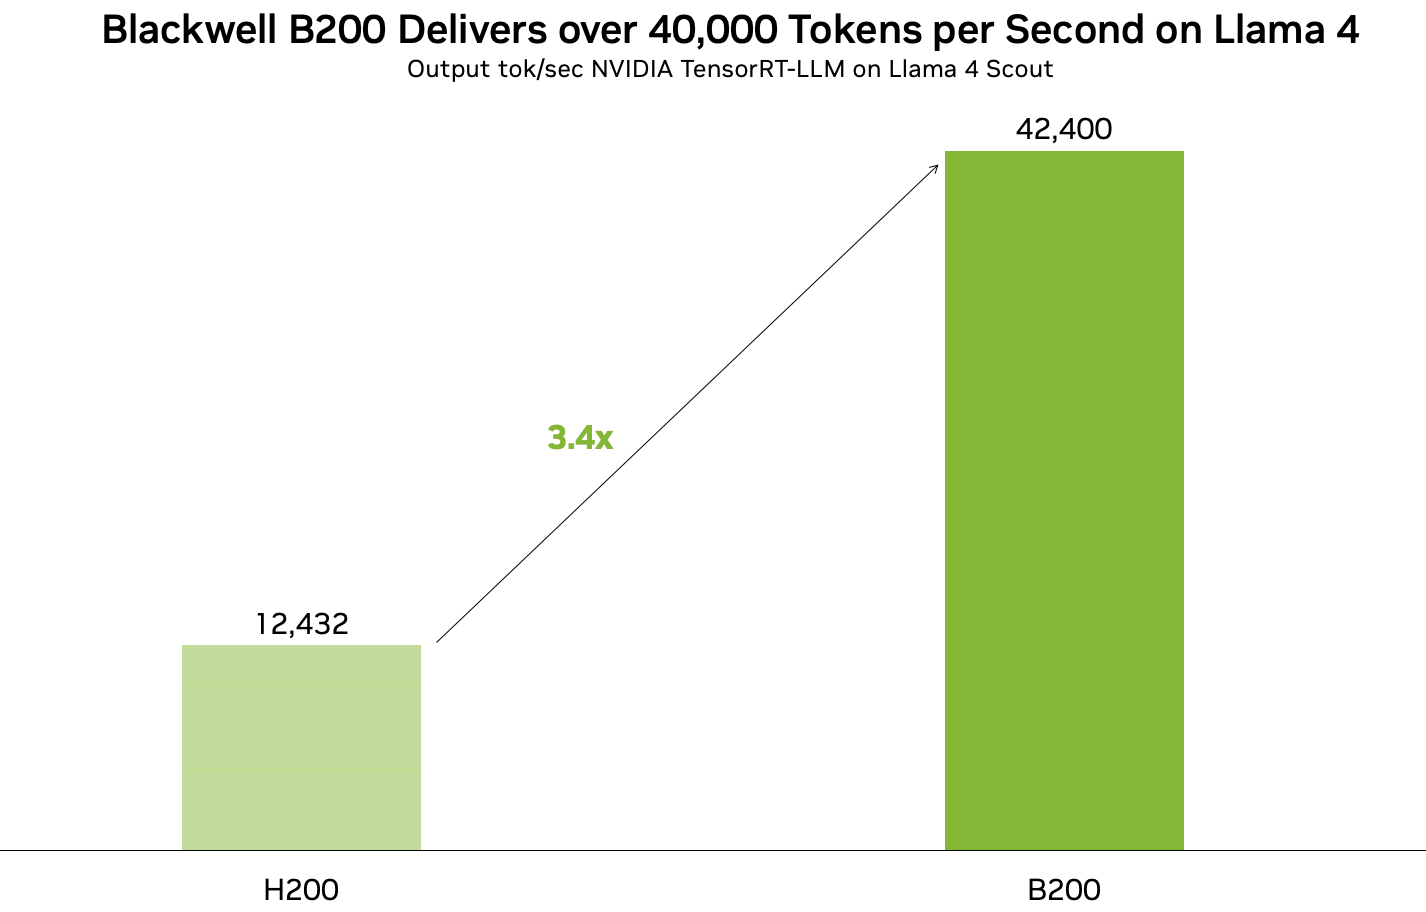
TensorRT LLM provides users with an easy-to-use Python API to define Large Language Models (LLMs) and supports state-of-the-art optimizations to perform inference efficiently on NVIDIA GPUs. TensorRT LLM also contains components to create Python and C++ runtimes that orchestrate the inference execution in a performant way.
Run any open-source LLMs, such as DeepSeek and Llama, as OpenAI compatible API endpoint in the cloud.
The AI Compute Platform for frontier teams. SkyPilot turns fragmented AI compute into one AI supercomputer, so frontier AI teams build custom intelligence faster.
The easiest way to serve AI apps and models - Build Model Inference APIs, Job queues, LLM apps, Multi-model pipelines, and more!
《深入理解 AI Infra:量化分析与系统设计》(李博杰 著)开源书稿:从硬件约束和模型架构出发,量化推导 LLM 推理与训练系统设计。含全书正文、PDF、配套计算工具与实验
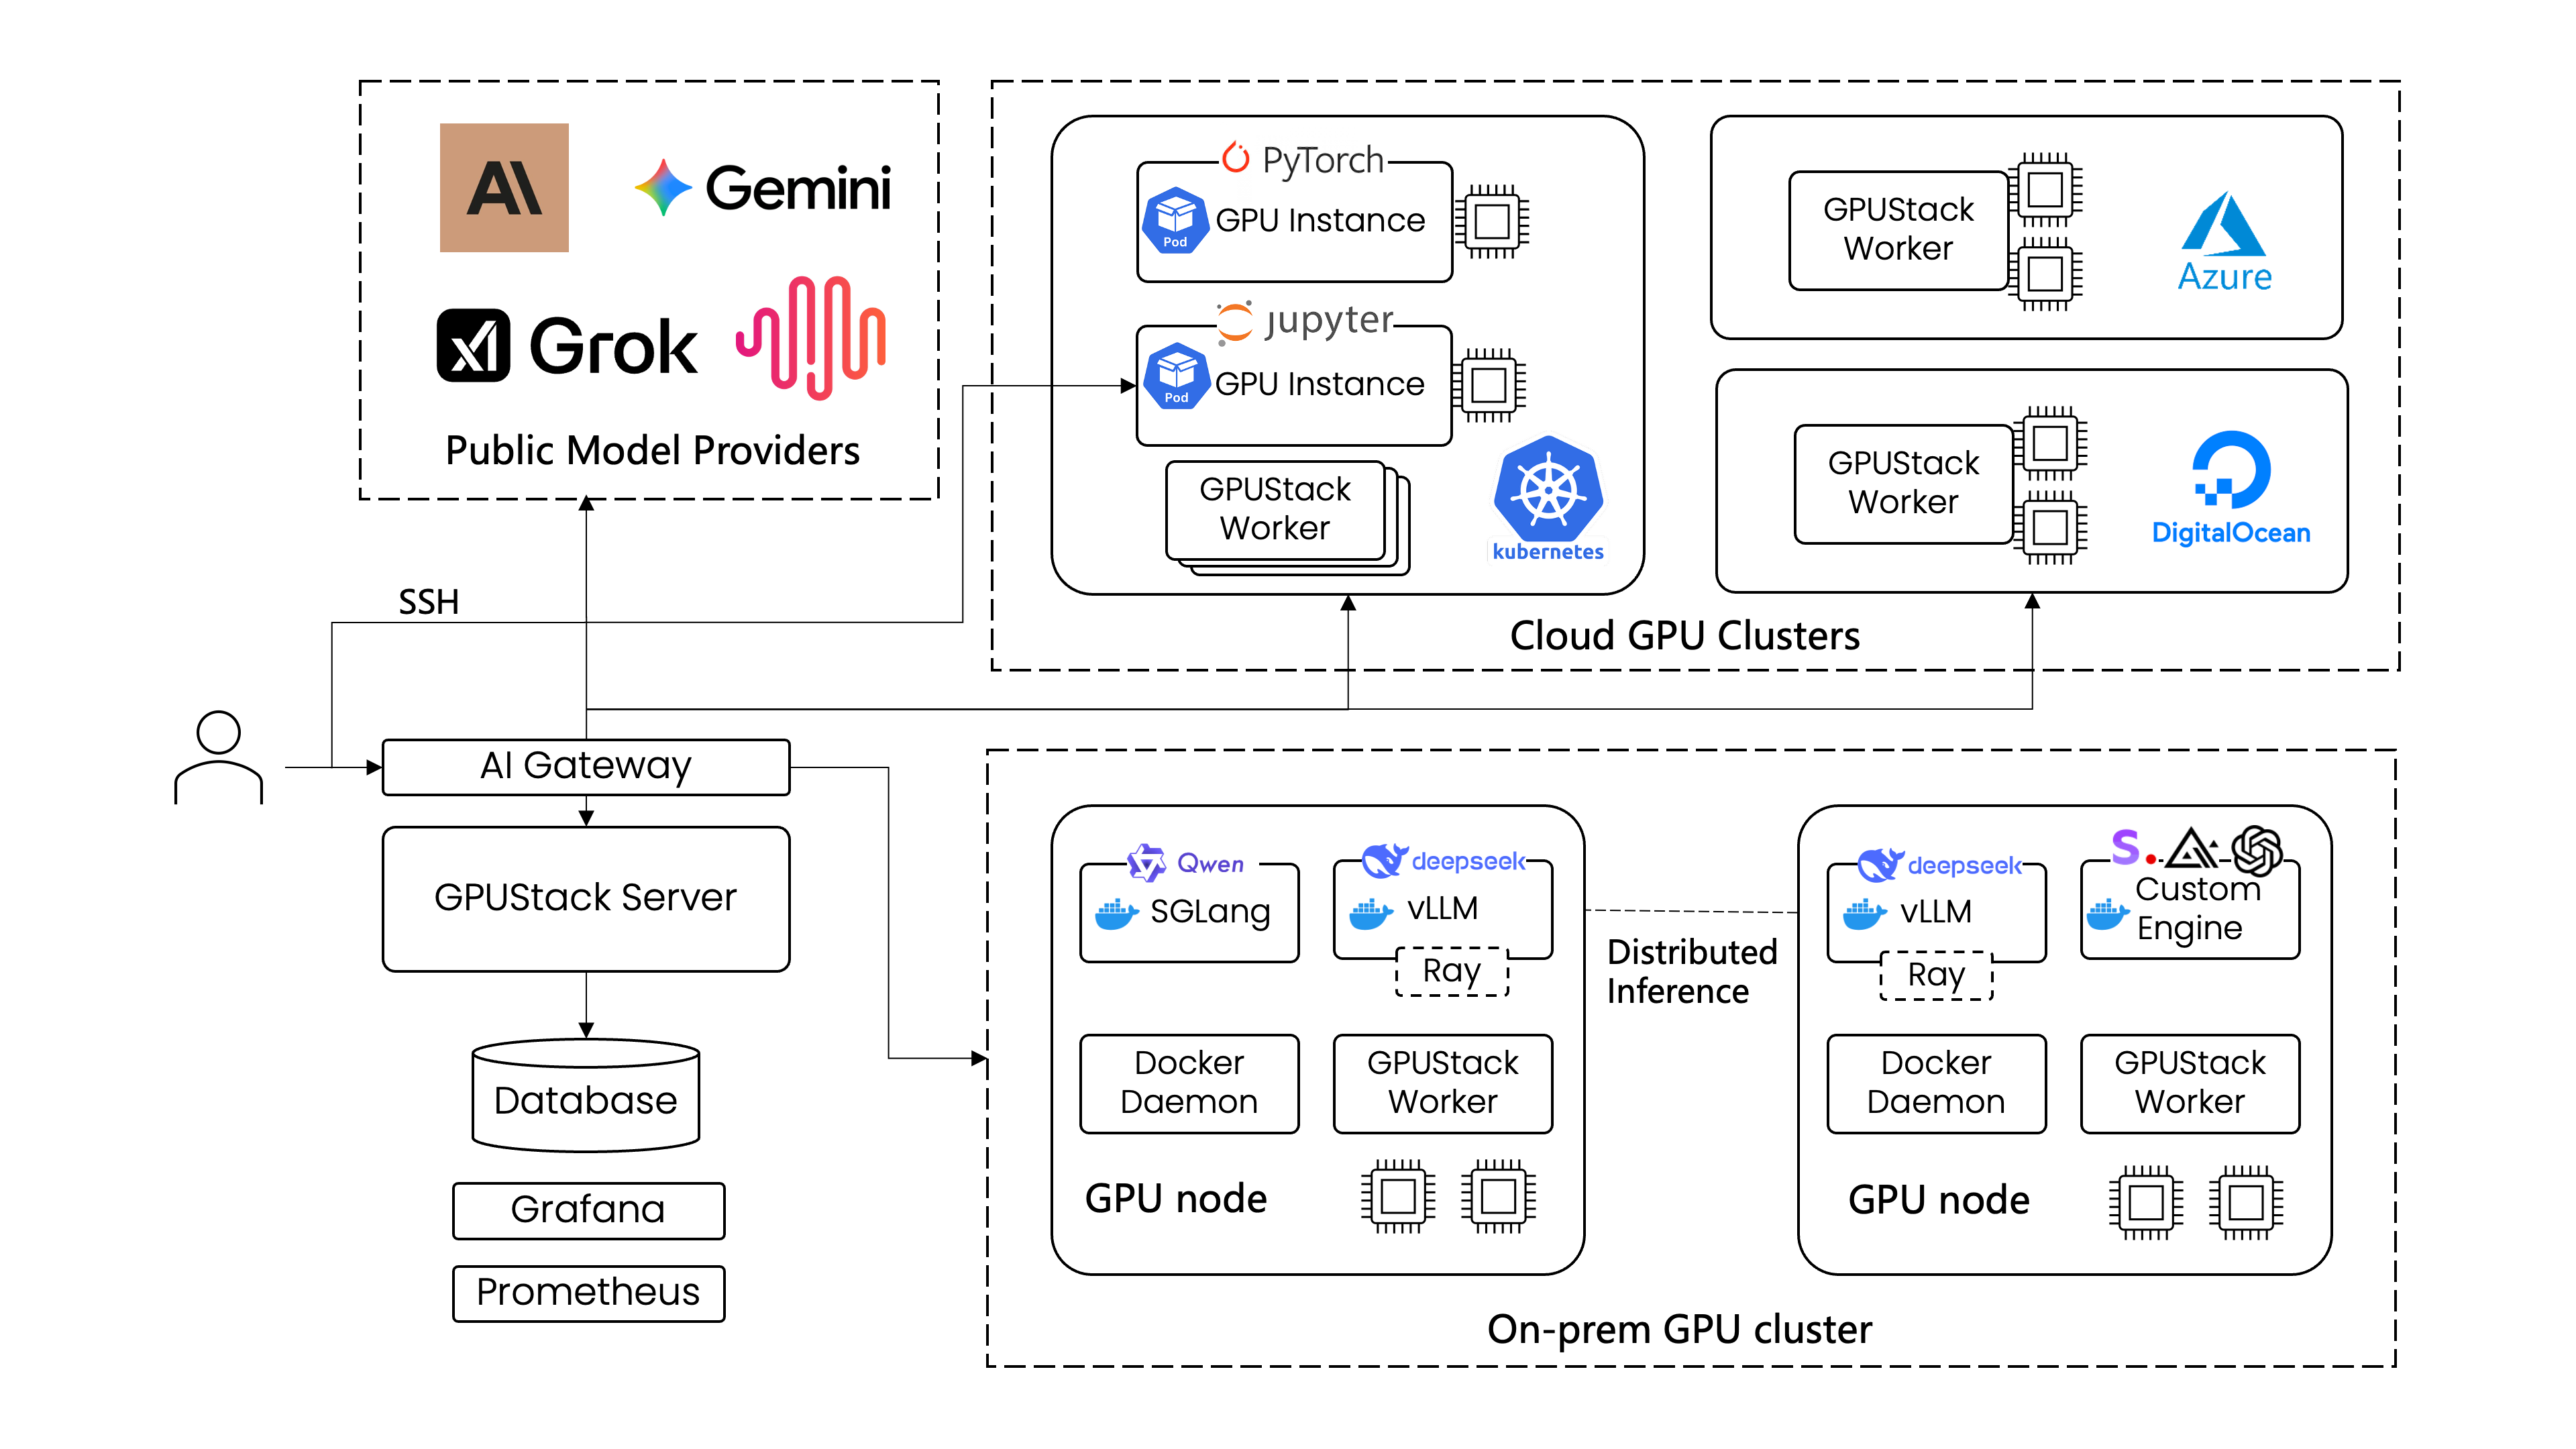
A GPU cluster manager for high-performance AI model serving (vLLM, SGLang) and on-demand SSH-accessible GPU instances.
High-performance Inference and Deployment Toolkit for LLMs and VLMs based on PaddlePaddle
Superduper: End-to-end framework for building custom AI applications and agents.
Open Source AI Accelerator Research Platform Standard / 开源推理研究平台
The open LLM inference engine for AWS Trainium: NKI megakernels, 1M-token context, OpenAI-compatible API. By RunAnywhere.
RTP-LLM: Alibaba's high-performance LLM inference engine for diverse applications.
Local inference that behaves like a frontier API: Qwen3.8-Flash-Next on AMD Strix Halo plus small NPU models, over the OpenAI and Anthropic APIs on one port.
A throughput-oriented high-performance serving framework for LLMs
A high-performance ML model serving framework, offers dynamic batching and CPU/GPU pipelines to fully exploit your compute machine
A highly optimized LLM inference acceleration engine for Llama and its variants.
Frontier-class open models on a free Kaggle TPU v5e-8: GLM-5.3-Flash 320B MoE (~165 tok/s, our own JAX engine) and Qwen3.8-27B bf16 (~130 tok/s), 262k context, prefix caching. Works with Claude Code, Codex, opencode and pi.
Pure Rust + CUDA LLM inference engine — no PyTorch, OpenAI-compatible, serves Qwen3 to Kimi-K2
LLM (Large Language Model) FineTuning
The production framework for Predictive and Generative AI. Serve any model as an API in one line, with OpenAI/Anthropic/Ollama-compatible endpoints, a built-in chat UI, and native MCP.
A ChatGPT(GPT-3.5) & GPT-4 Workload Trace to Optimize LLM Serving Systems
Community registry of LLM serving-path traps that produce confidently wrong measurements: templates, tool parsers, reasoning fields, quant kernel paths, CUDA toolchains, KV allocation, eval harnesses, versioning. Symptom-first, with the check that catches each.
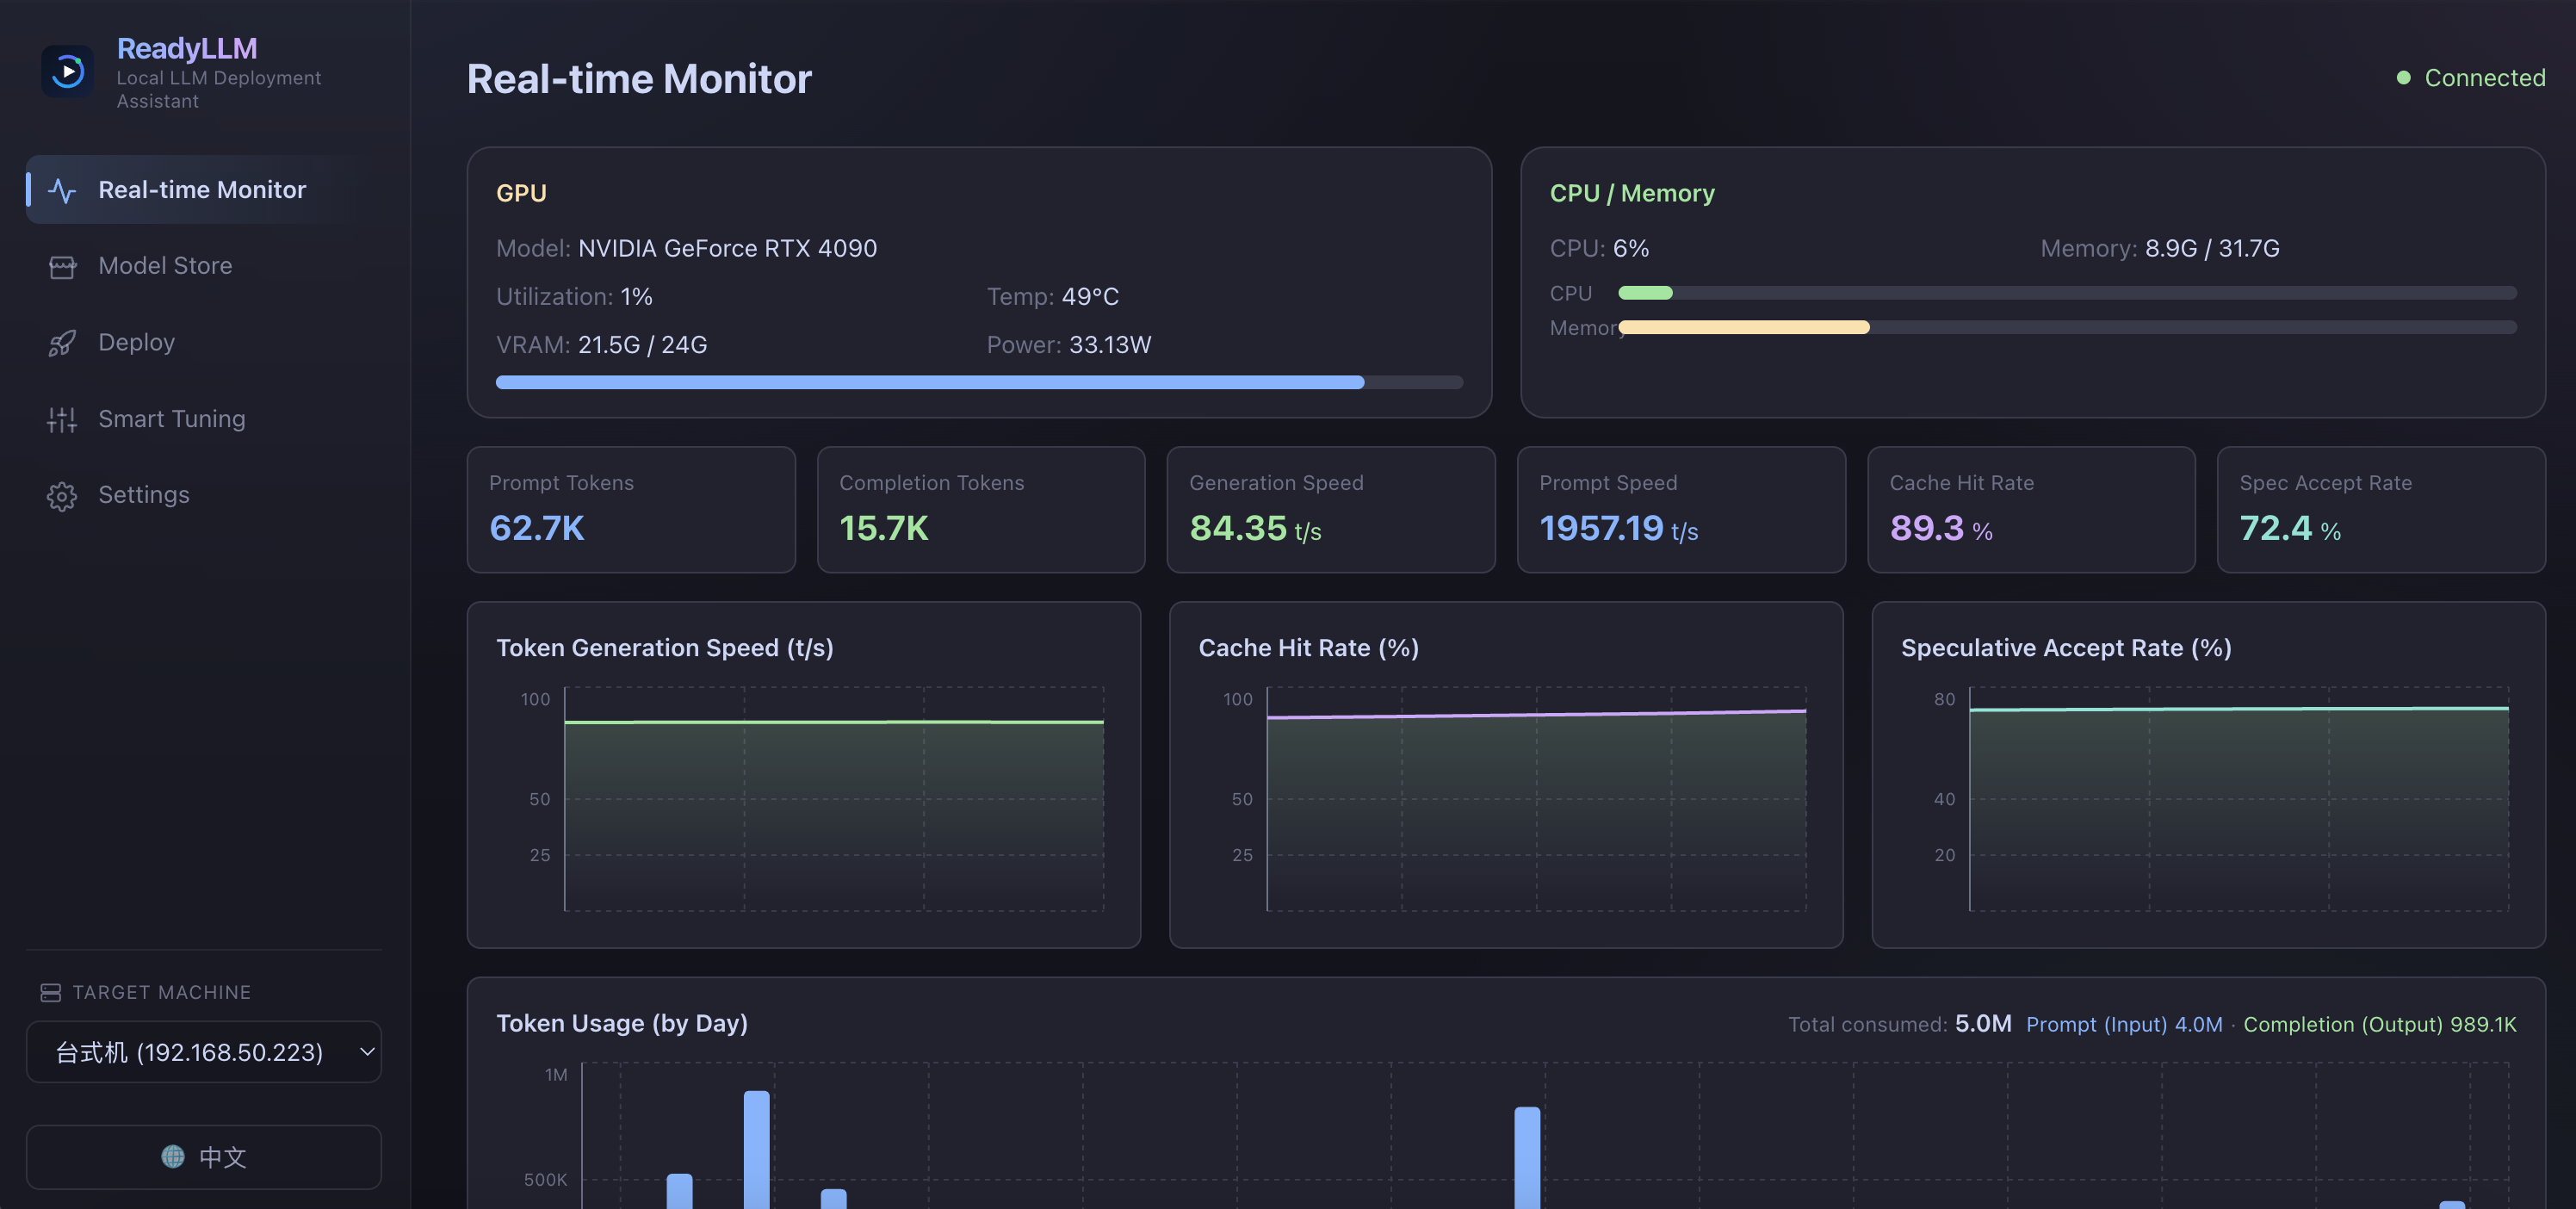
Deploy, monitor, and tune LLM through a visual interface — plus image / video generation on top of ComfyUI.
Native Windows vLLM 0.33.0 (Python 3.13/CUDA 13.0), plus a Python 3.14/CUDA 13.2 build; older versions on the Releases page. PyTorch 2.14, FlashAttention/Rust, OpenAI serving, 10 KV formats, Multi-TurboQuant, experimental CPU/NVMe KV offload. No WSL or Docker.
EmbeddedLLM: API server for Embedded Device Deployment. Currently support CUDA/OpenVINO/IpexLLM/DirectML/CPU
Serving Qwen3.8-27B-FP8 on a single DGX Spark (GB10): 7.88 to 58.5 tok/s single-stream from decode strategy alone, weights untouched. Speculative decoding and prefix caching benchmarked, plus DFlash 2 — the only Qwen3.8-27B build that can serve it under vLLM.
DGX Spark / GB10 vLLM Docker stack for large-model serving, presets, patches, and validation notes.
Runs in the browser on Hugging Face
Runs in the browser on Hugging Face
Runs in the browser on Hugging Face
Runs in the browser on Hugging Face
Runs in the browser on Hugging Face