Fun-ASR
Fun-ASR speech recognition models, with native Hugging Face Transformers support for Fun-ASR-Nano and separate FunASR, vLLM and llama.cpp deployment paths.
- 1.6k
- C
- Apache-2.0
- 2 d ago
Fun-ASR speech recognition models, with native Hugging Face Transformers support for Fun-ASR-Nano and separate FunASR, vLLM and llama.cpp deployment paths.
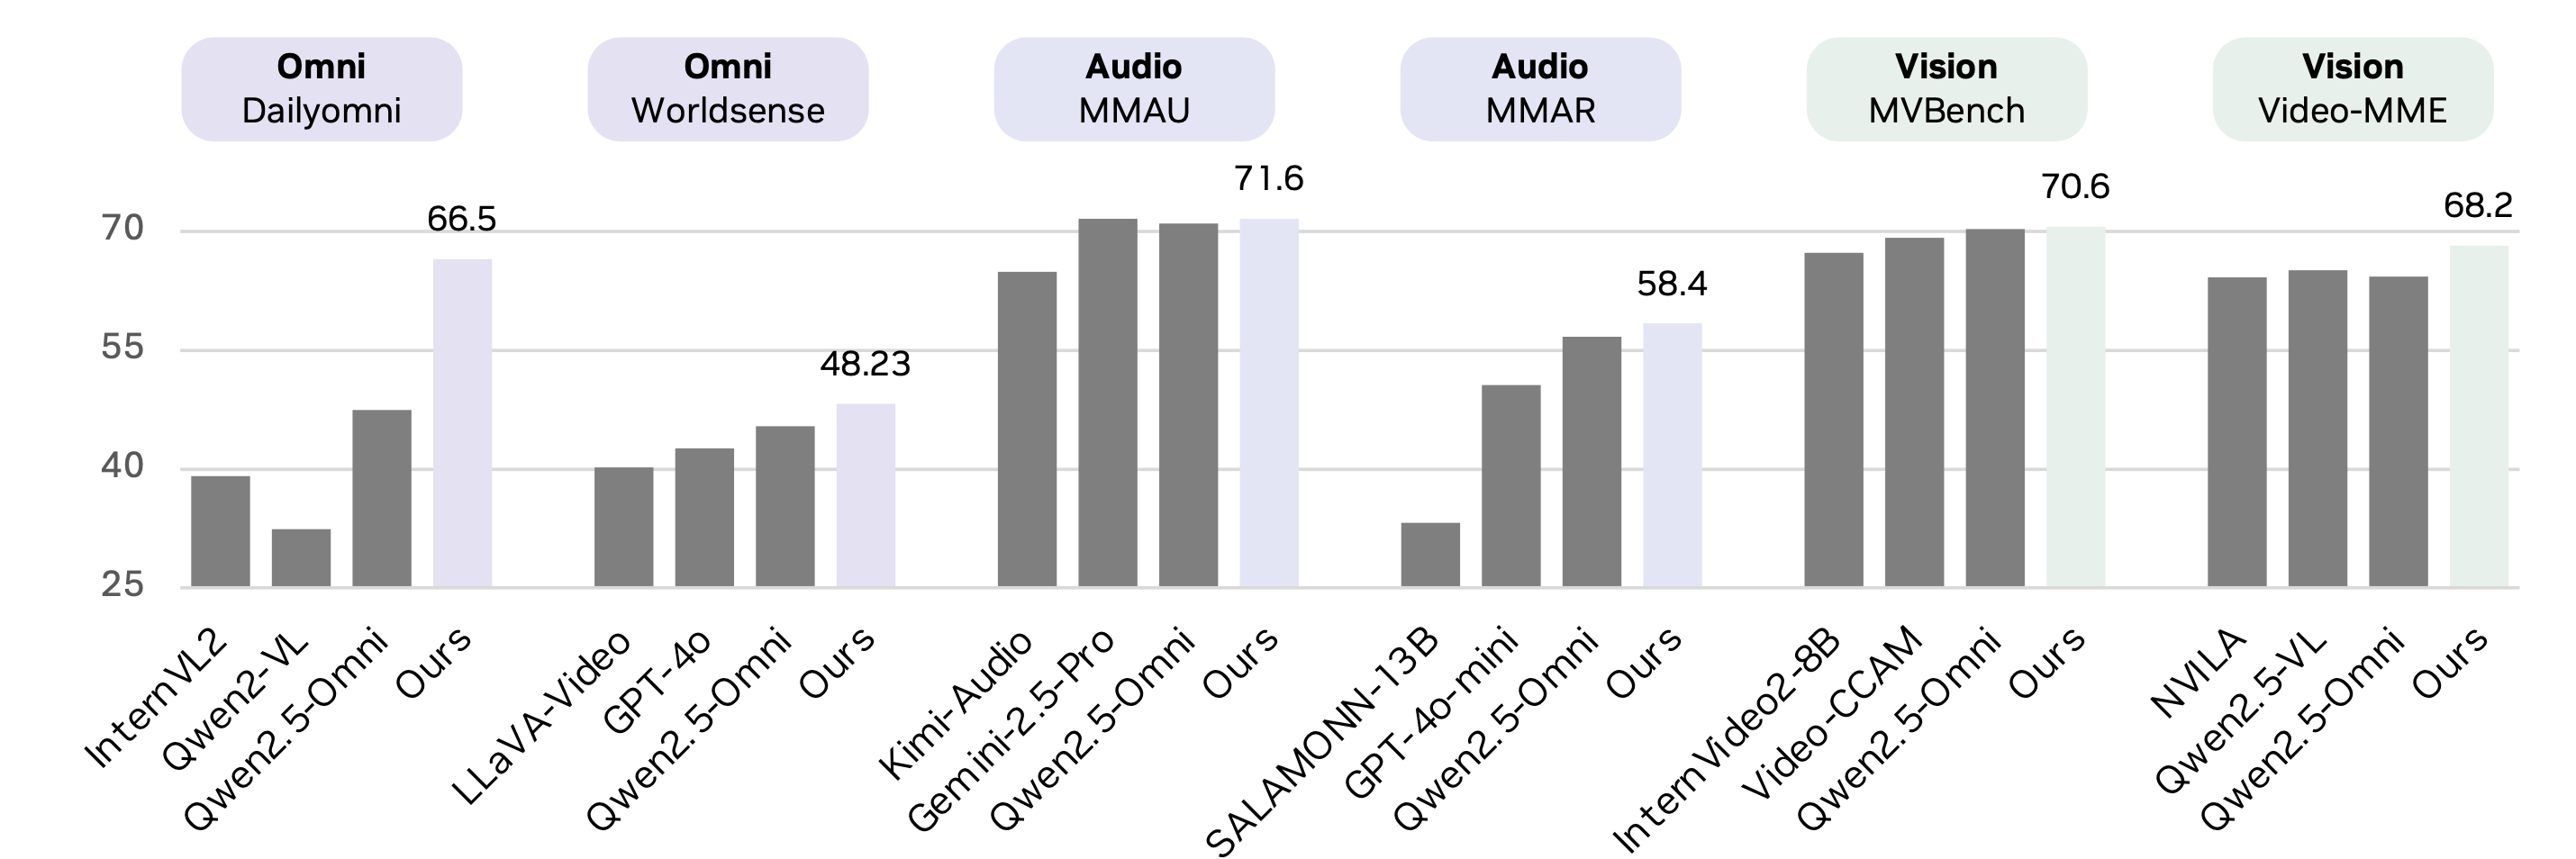
OmniVinci is an omni-modal LLM for joint understanding of vision, audio, and language.
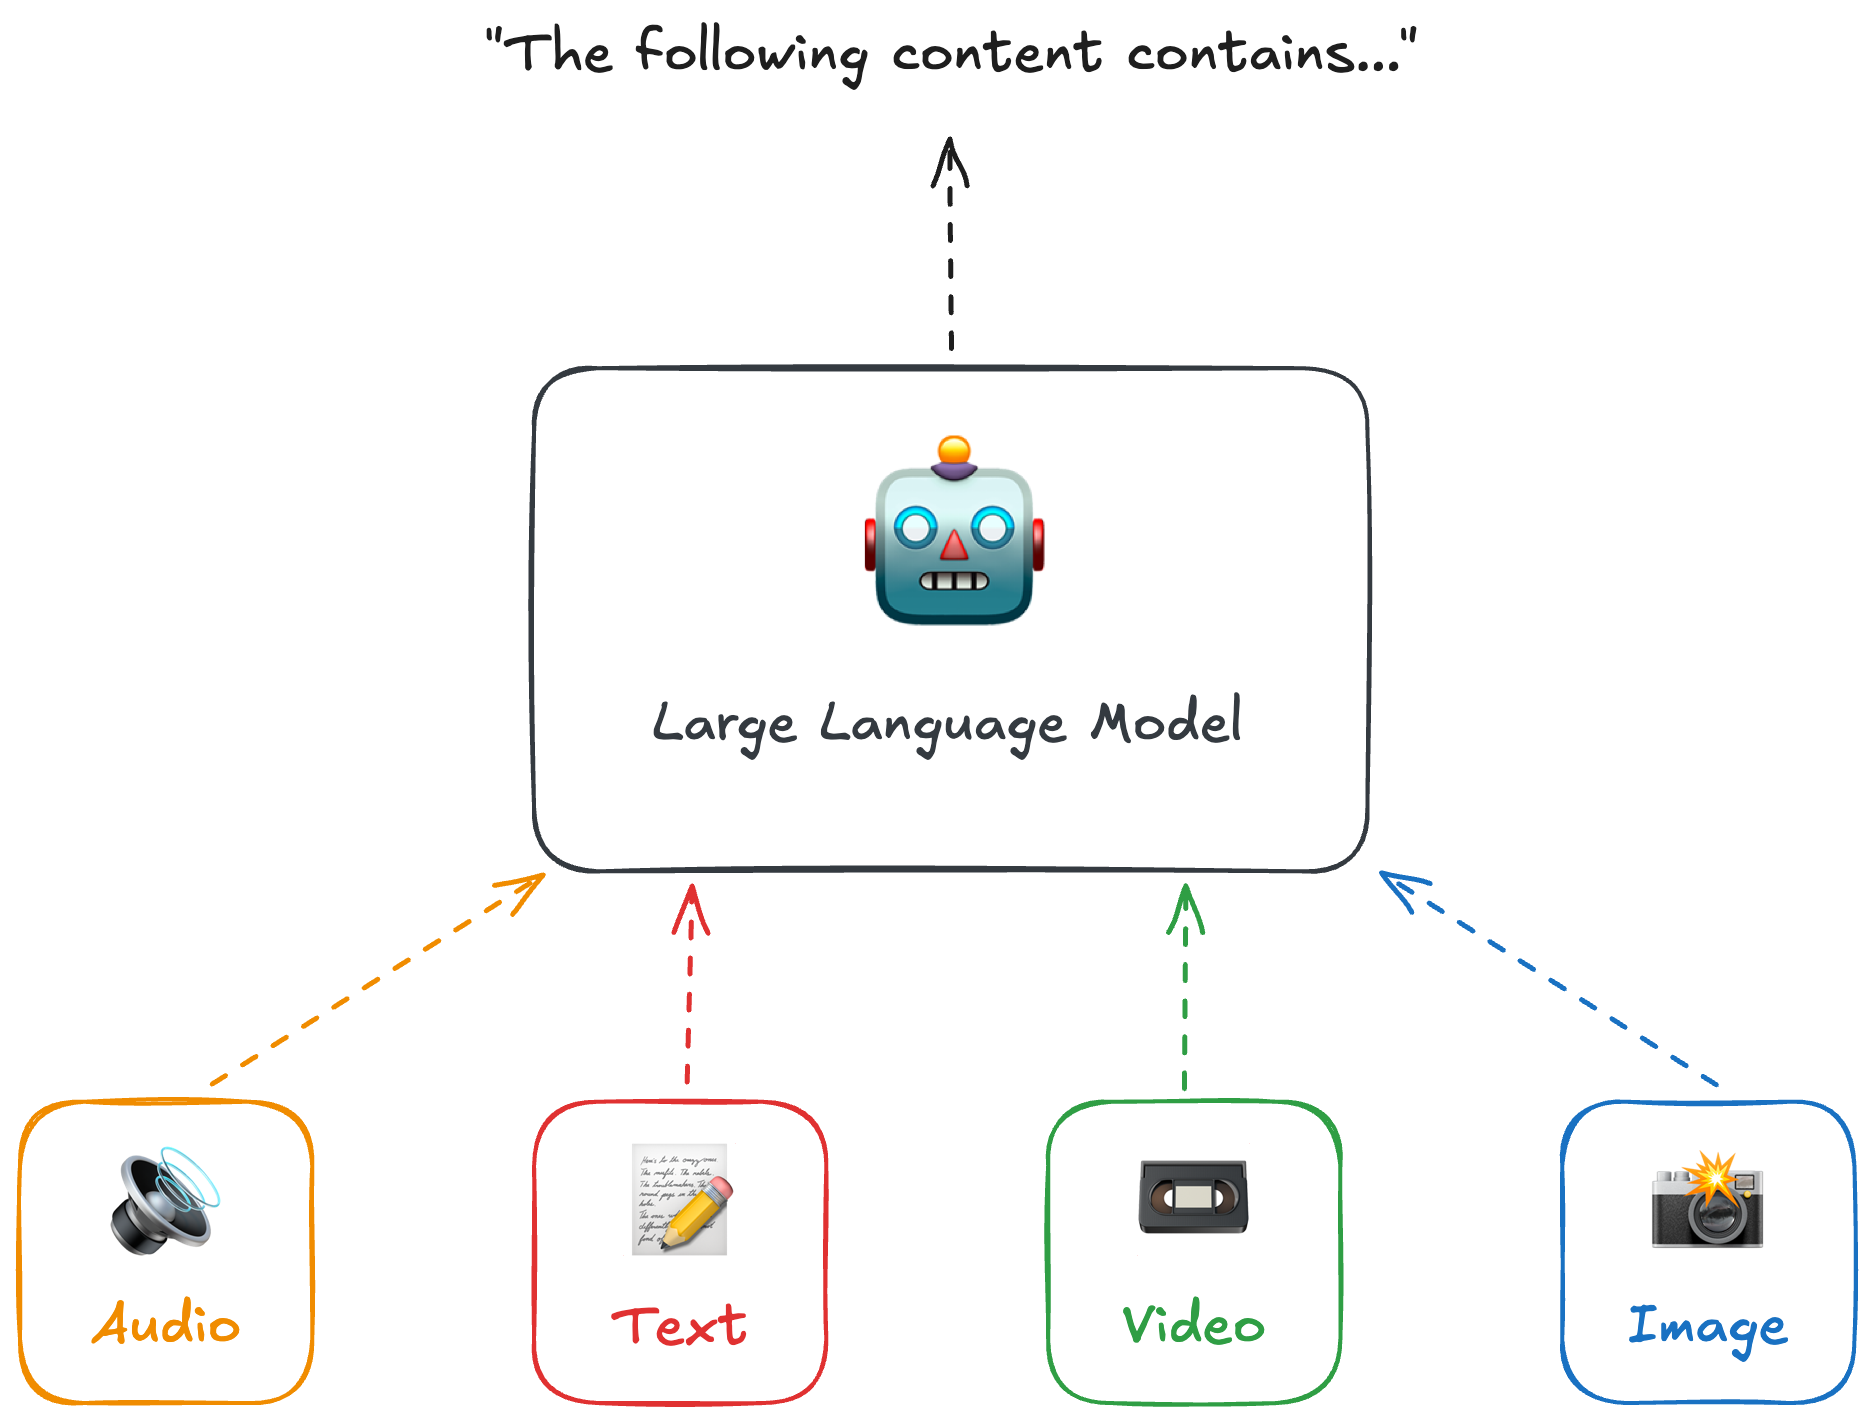
Outlining and demonstrating how language models are able to understand image, video, and text content.
Streaming speech language model plumbing: audio frames, turns, conversation schemas, batching, and adapters.