FunASR
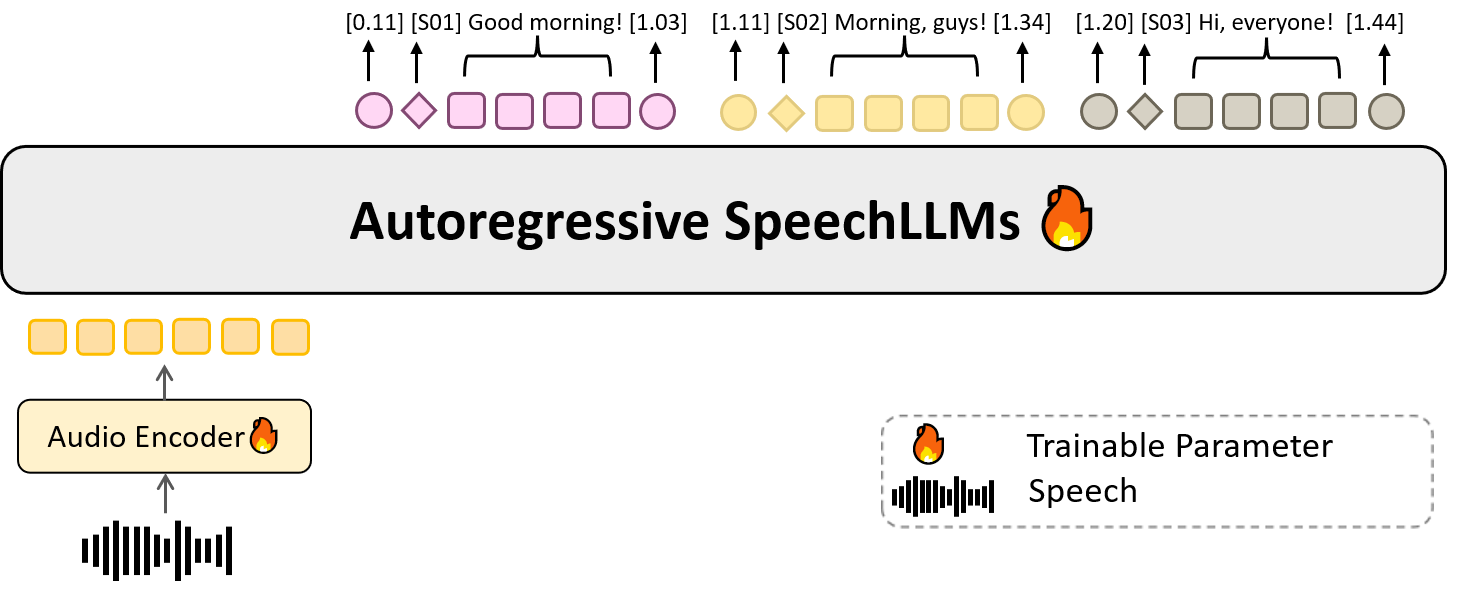
Open-source speech recognition toolkit for training, inference, streaming ASR, VAD, punctuation, speaker diarization pipelines, and OpenAI-compatible/MCP serving.
- 21k
- Python
- MIT
- 5 h ago
Open-source speech recognition toolkit for training, inference, streaming ASR, VAD, punctuation, speaker diarization pipelines, and OpenAI-compatible/MCP serving.
Real-time, local speech-to-text with streaming ASR, speaker diarization, translation, and OpenAI/Deepgram-compatible APIs.
Download video and audio from 1000+ sites, transcribe locally with speaker labels, and summarize, translate, or chat with your media using your preferred AI provider.
Neural building blocks for speaker diarization: speech activity detection, speaker change detection, overlapped speech detection, speaker embedding
Automatic Speech Recognition with Speaker Diarization based on OpenAI Whisper
Automatic speech recognition model, used with pyannote-audio.
Frontier CoreML audio models in your apps — text-to-speech, speech-to-text, voice activity detection, and speaker diarization. In Swift, powered by SOTA open source.
Automatic speech recognition model, used with nemo.
Automatic speech recognition model, used with pyannote-audio.
Whisper & Faster-Whisper standalone executables for those who don't want to bother with Python.
A Repository for Single- and Multi-modal Speaker Verification, Speaker Recognition and Speaker Diarization
Multilingual Automatic Speech Recognition with word-level timestamps and confidence
A 0.9B model for long-form transcription in 50+ languages with speaker diarization, timestamps, and acoustic event awareness
A curated list of awesome Speaker Diarization papers, libraries, datasets, and other resources.
Fun-ASR speech recognition models, with native Hugging Face Transformers support for Fun-ASR-Nano and separate FunASR, vLLM and llama.cpp deployment paths.
Automatic speech recognition model, used with pyannote-audio.
Gated access
AI speech toolkit for Apple Silicon — ASR, TTS, speech-to-speech, VAD, and diarization powered by MLX and CoreML
turnkey self-hosted offline transcription and diarization service with llm summary
一站式全自动字幕生成软件,下载、转录、翻译、压制全流程覆盖,无需人工介入 / One-stop automated subtitle generator. Handles downloading, transcription, translation, and hardcoding—zero human intervention required.
Record meetings on Omarchy: mic and computer audio as two tracks, transcribed on your own machine, with speakers, chapters and a player.
Voice AI runtime. Local first transcription, speaker diarization, TTS, and voice cloning with an OpenAI compatible API.
audio.cpp with a full-task WebUI - pure C++ audio-model inference engine powered by ggml. TTS, ASR/STT, VAD, voice conversion, speaker diarization, music generation. No Python dependency.
Open-source AI meeting notes for Mac. Records mic + system audio with no bot, transcribes on-device or via OpenAI / Deepgram / Groq, identifies speakers offline, and writes summaries that fuse your notes with the transcript. Ask your notes and get cited answers. Tauri 2 + Rust + Swift.
very fast speech-to-text, diarization, streaming (even in CPU) with NVIDIA Parakeet in Rust
Free offline AI video dubbing studio for Windows — voice cloning, translation, subtitles & on-screen-text localization. 100% local, one native .exe, zero Python.
Speechlib is a library that unifies speaker diarization, transcription and speaker recognition in a single pipeline to create transcripts for audio conversations with actual speaker names and time tags. This library also contains audio preprocessor functions.
On-device meeting transcriber for macOS — auto-records Teams/Zoom/Webex, transcribes & separates speakers locally. No cloud. Open-source alternative to Otter/Granola/Fireflies.
Speech, voices, stories, audiobooks, dubbing and transcription, made on your Mac. Free and open source.
Free Windows desktop app for AI video translation, subtitles and dubbing, with local CPU/GPU models, voice cloning, batch processing and video downloads.
Automatic speech recognition model, used with pyannote-audio.
Free, on-device AI dictation and meeting notes for macOS. Sub-second dictation with Parakeet and Whisper on Apple Silicon, plus optional AI polish. EnviousMeet (Beta): record calls with no bot, get who-said-what transcripts and AI summaries on your Mac. No account, no subscription, open source. Your audio never leaves your Mac.
Free, open-source meeting notes app for Mac: records Zoom, Meet and Teams without a bot, transcribes on-device (whisper.cpp + Breeze ASR 25), identifies speakers, and writes timestamped notes with your own Claude or ChatGPT. 拾音
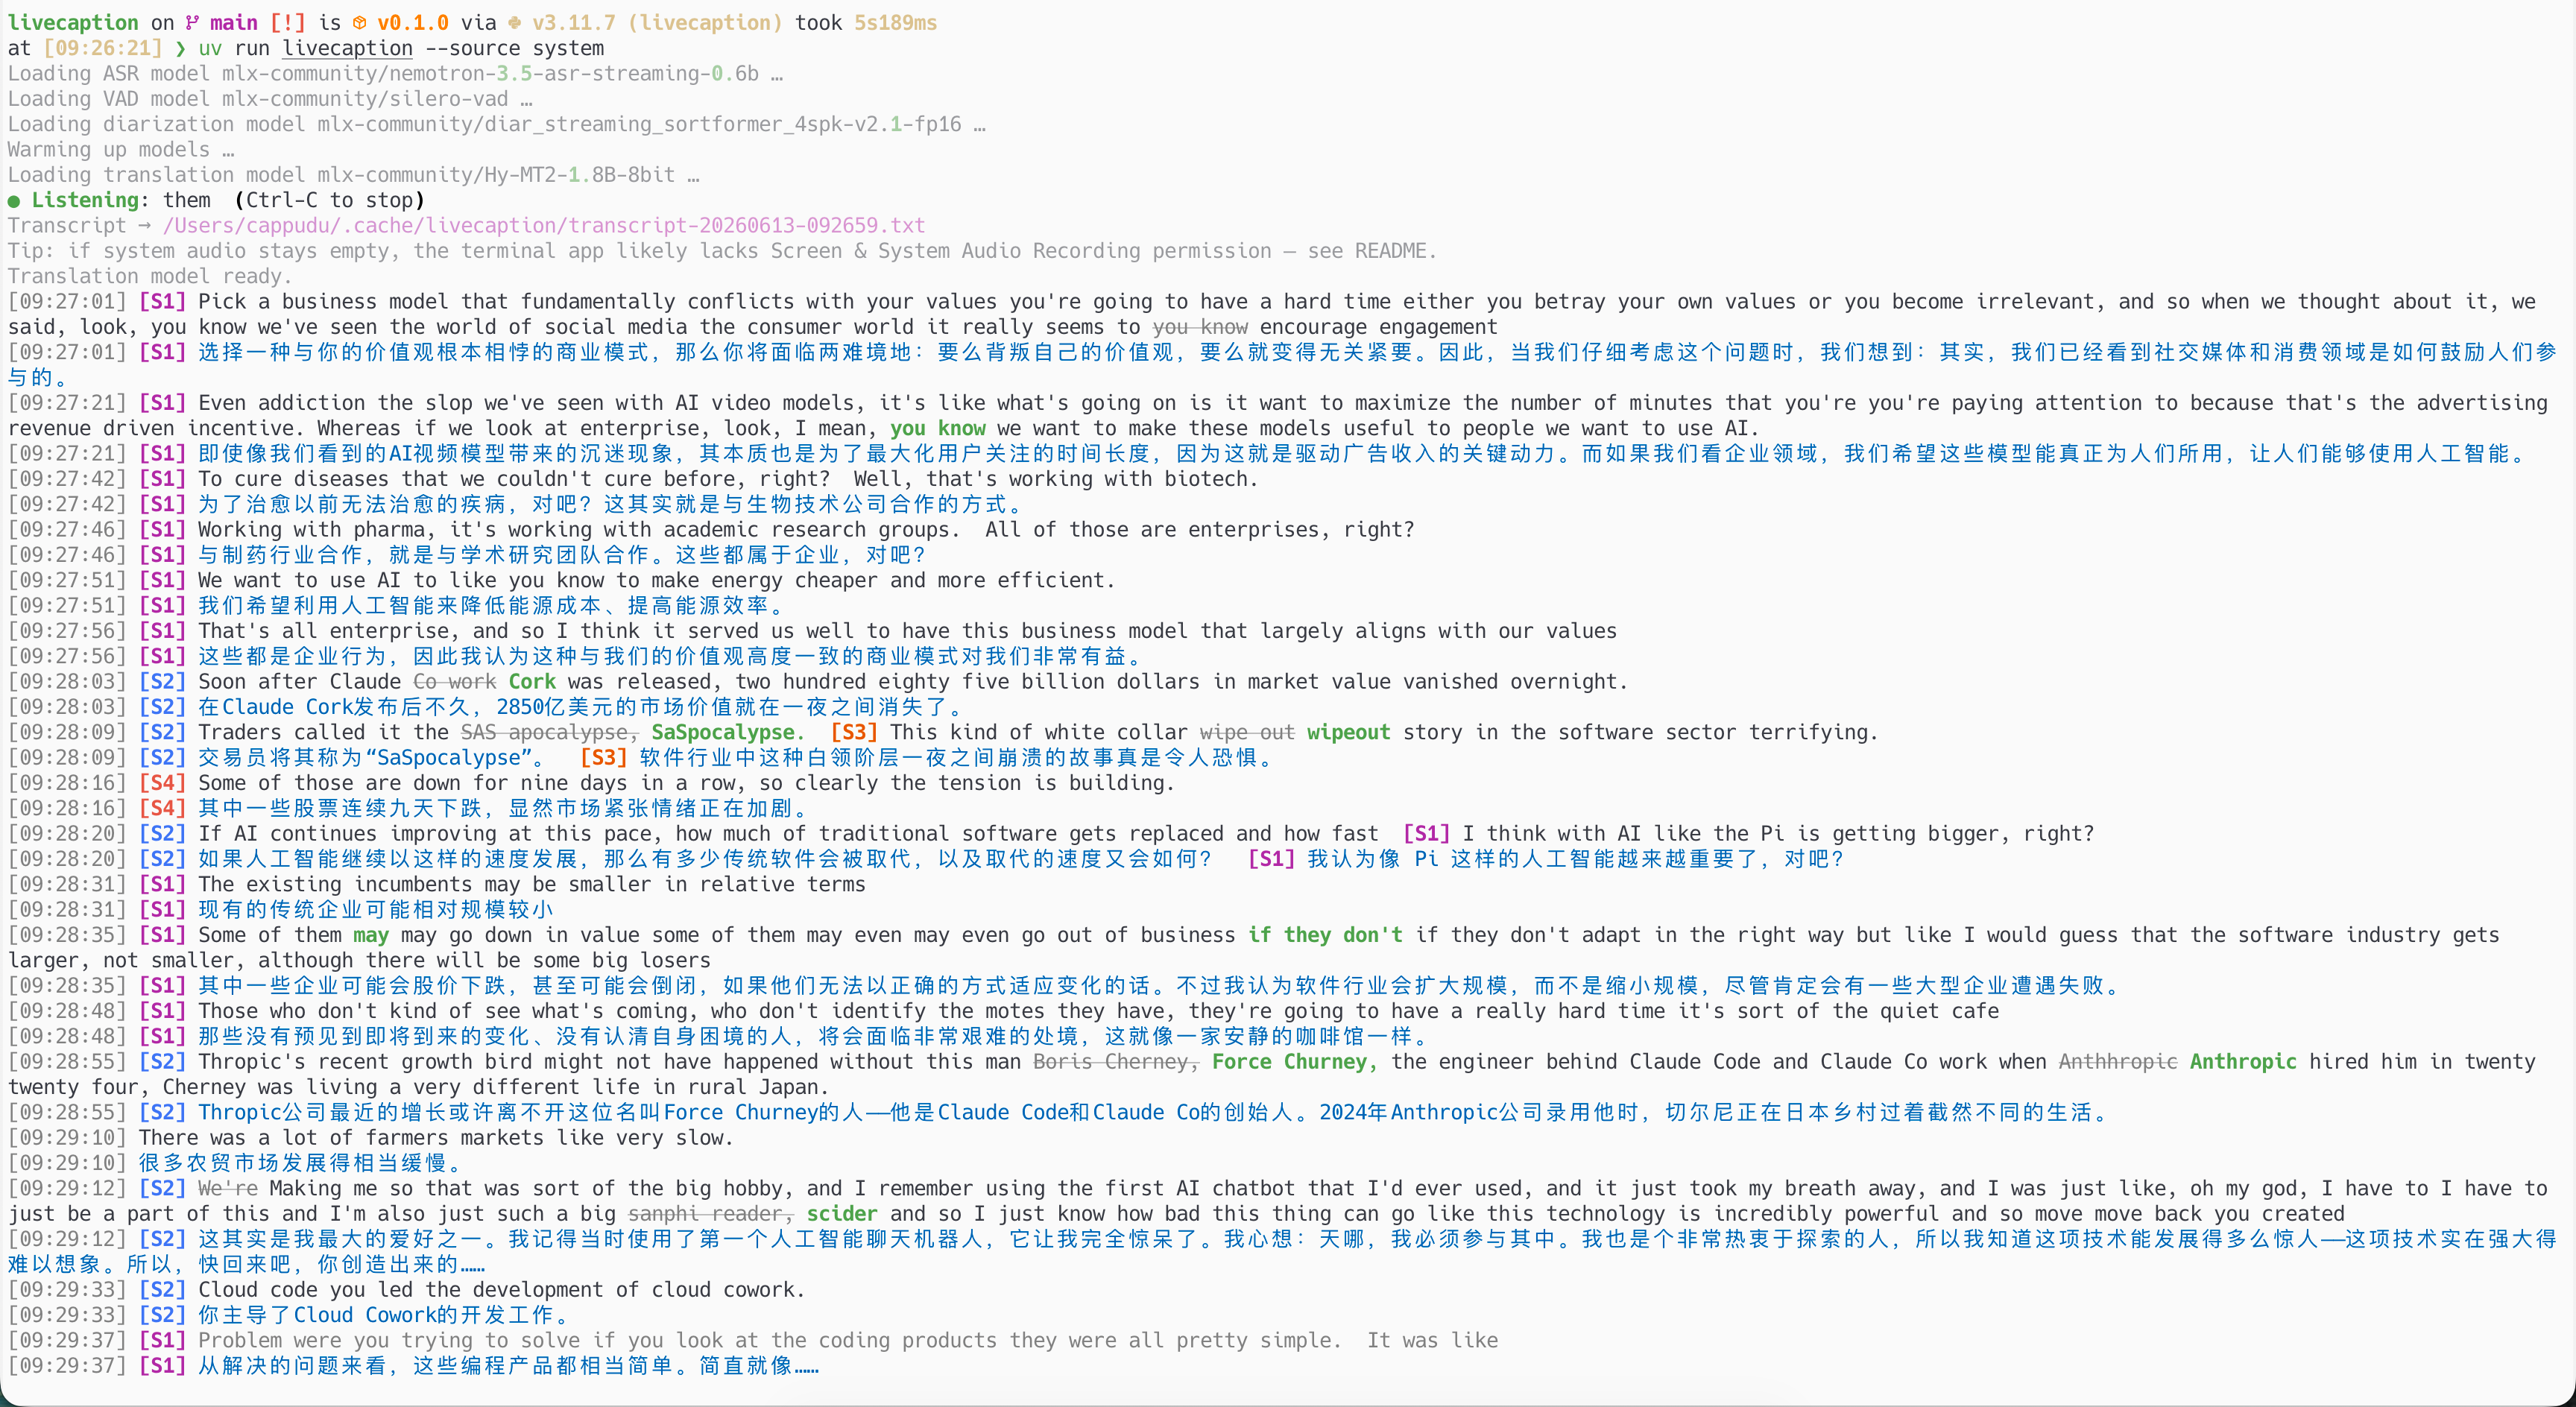
Real-time on-device speech transcription + translation for macOS (Apple Silicon). Streaming ASR, speaker diarization, and live English→Chinese translation on Apple GPU/MLX — terminal CLI, no UI, no cloud.
Automatic speech recognition model, used with nemo.
Automatic speech recognition model, used with nemo.
A mental-model-first field guide to Audio AI — from raw waveforms to production voice systems. Covers ASR, TTS, audio classification, Transformer architectures (CTC/Seq2Seq), fine-tuning, and real-world pipelines like voice assistants and meeting transcription. Bilingual (EN/FA).
ScribeCrate: open-source, self-hosted Whisper speech-to-text server powered by faster-whisper. OpenAI-compatible transcription and English translation APIs, speaker diarization, JSON/SRT/VTT output, SSE streaming, offline operation with cached models, and Docker deployment on CPU (amd64/arm64) or NVIDIA CUDA (amd64).
On-device VAD / streaming STT / TTS / diarization in C++17 (ONNX + LiteRT) with a voice-agent pipeline. Linux, Windows, Android.
Automatic speech recognition model, used with nemo.
Provide Gradio custom components to make the diarization-based audio labeling process easier and faster.
Speaker diarization, fully in your browser
Runs in the browser on Hugging Face