r0b0bench
Specification for a reproducible, provenance-bound multi-lane LLM benchmark suite.
- 11
- Python
- MIT
- 5 wk ago
Specification for a reproducible, provenance-bound multi-lane LLM benchmark suite.
Think only when the tool call looks unsure: confidence-gated reasoning for small local models. Code, BFCL results and paper.
Deterministic no-float Math Court MCP clients for agent builders. Bind affine.earth. Integers sealed. Floats refused. Server is not in this git.
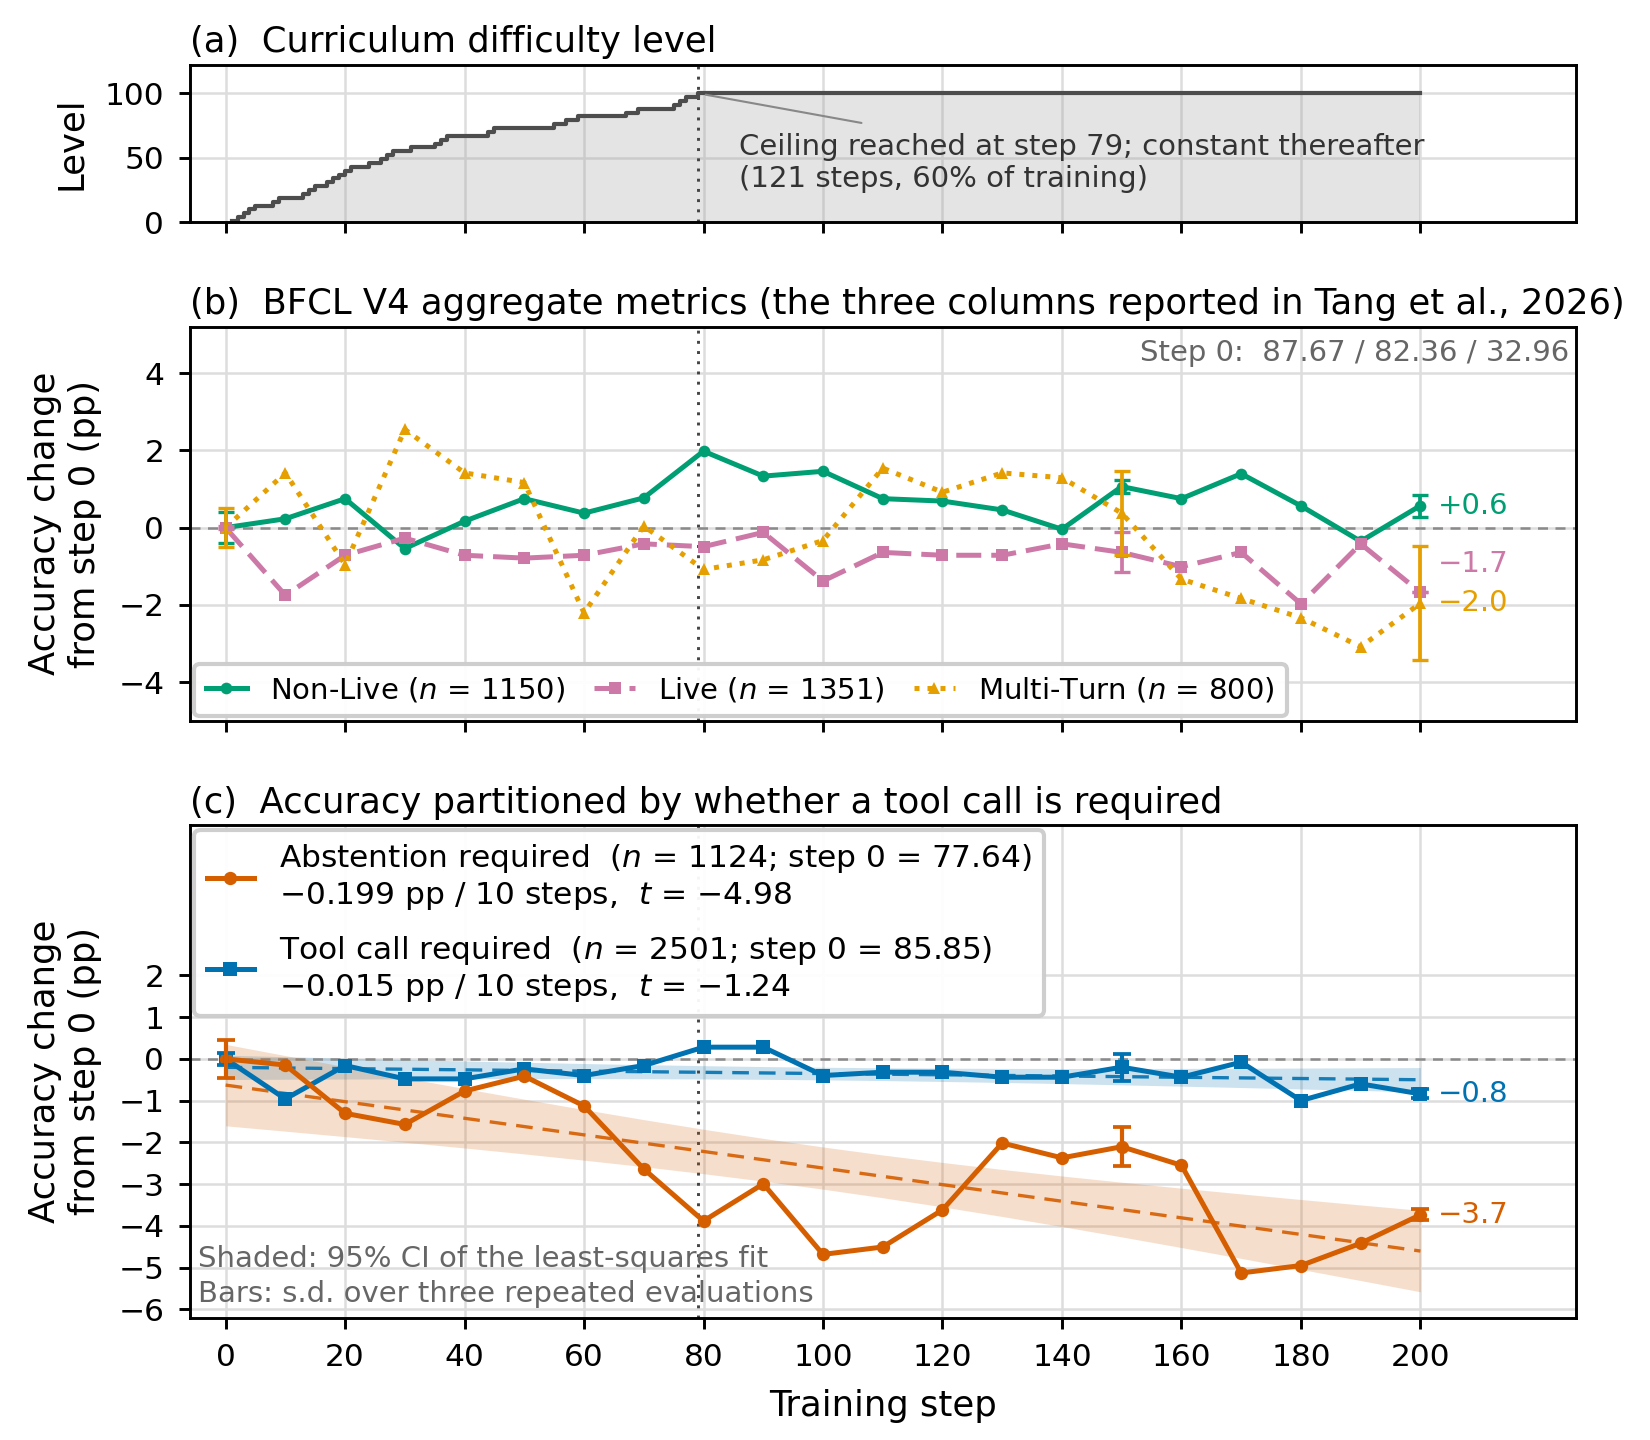
What 200 steps of fully simulated multi-turn tool-use RL do to a 4B policy: every 10th checkpoint scored on BFCL v4, with the pipeline that produced the measurement.
Public benchmark harnesses and reproducible evaluations from PixelSpaceAI
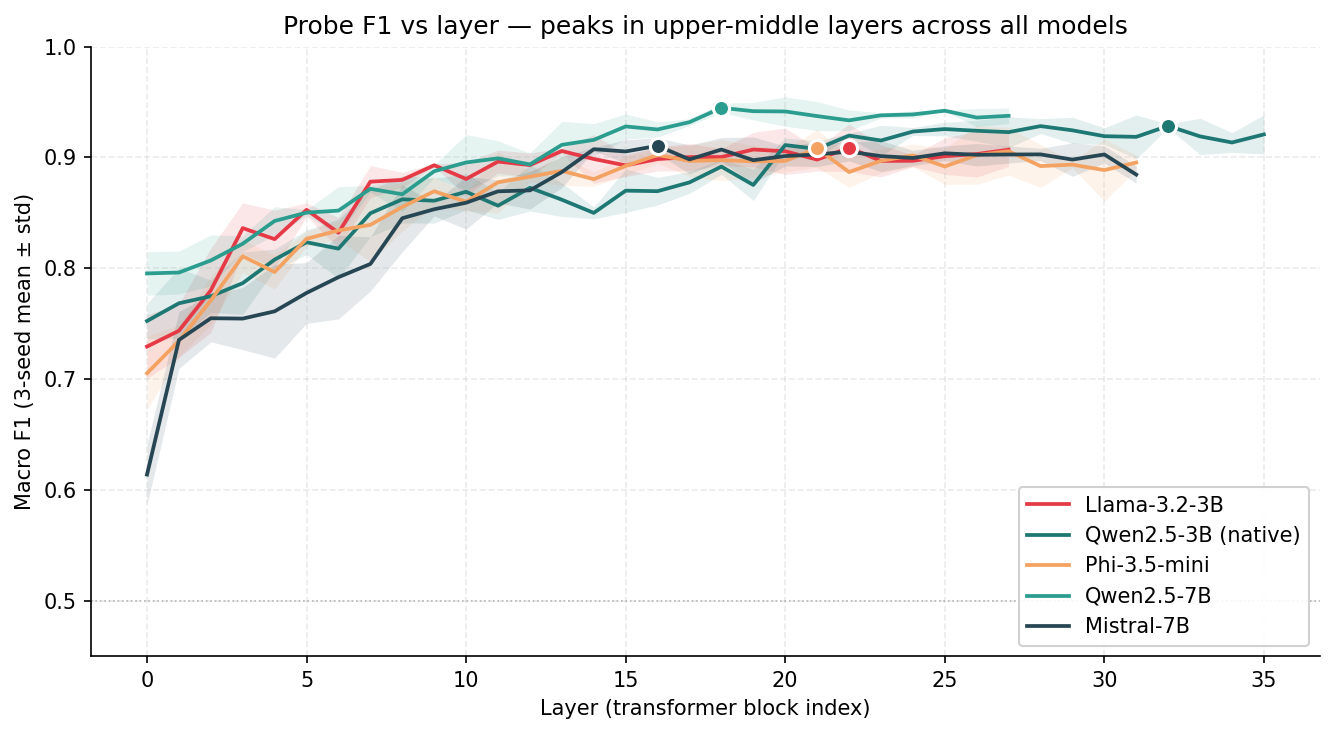
Pre-generation tool-call gating via linear probes on LLM hidden states. F1 ≈ 0.91–0.94 on BFCL v4, 14–22× faster than full generation. Cross-architecture transfer across Llama / Qwen / Phi / Mistral (3B–7B) with ≥96% retention.
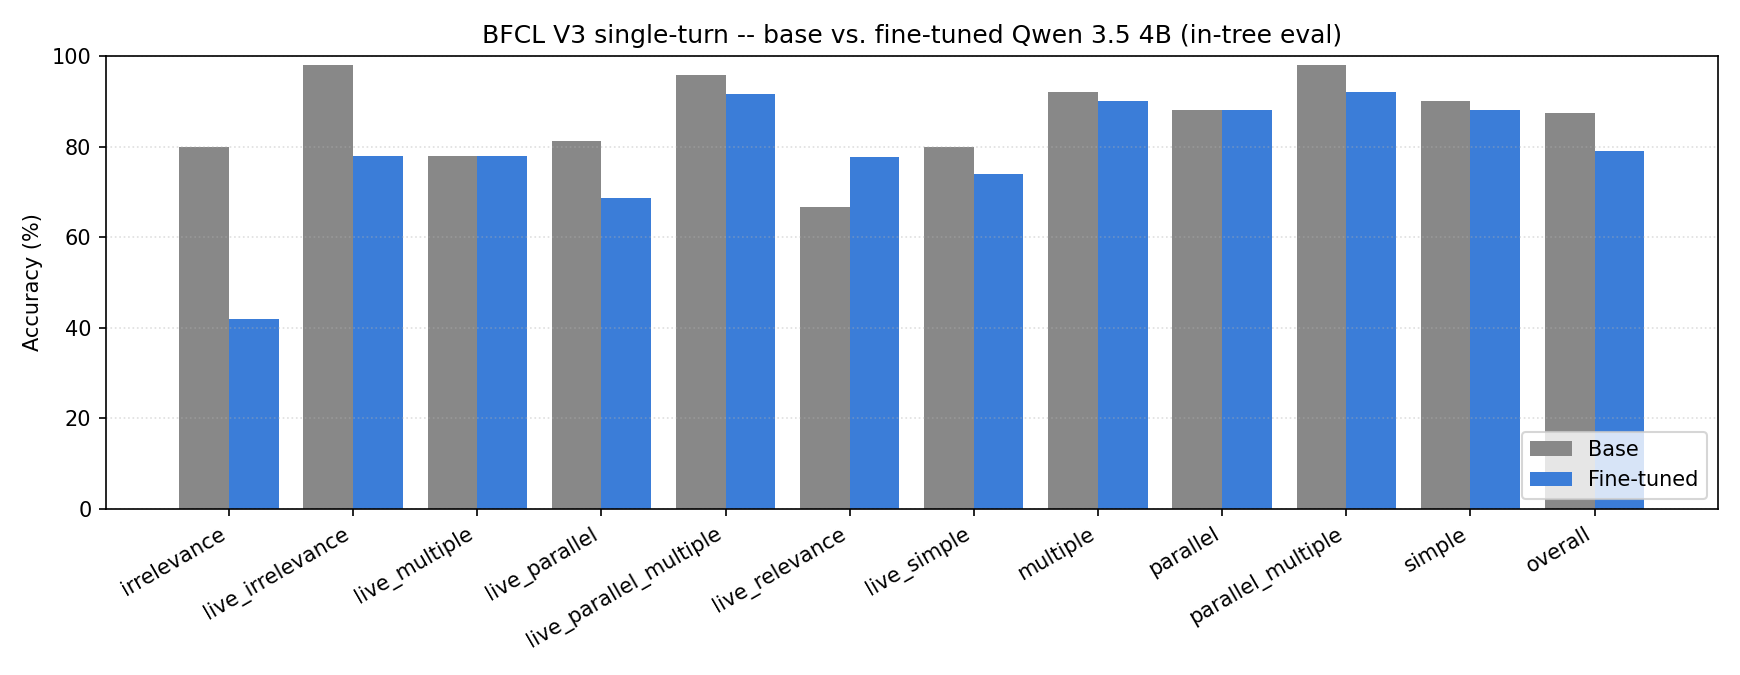
A bf16 LoRA fine-tune of Qwen 3.5 4B for function calling on xLAM. v1.0 ships below the BFCL gate with full per-category failure analysis.
Reproducible LoRA SFT of Qwen3-4B-Base for tool calling on 2x RTX 4090: assistant-only loss + selective special-token LoRA (810M to 66M trainable), 124k-sample pool, decontamination, 3 eval suites incl. BFCL v4 subset. Strict protocol success 1.8% -> 35.0%.
Canonical IR, schema validation, and deterministic delivery for function calls.
Reproducible LLM inference benchmarks (SGLang serving speed, BFCL tool calling) behind the posts on acostanza.com
ToolRL engineering reproduction: Qwen2.5-3B GRPO training, complete API-Bank and BFCL V3 benchmarks, protocol alignment and full-denominator audits.
大模型与 Agent 评测:复现 ToolMaze 论文的工具故障恢复评测、BFCL 函数调用评测、判分器可信度审计;配对检验与检验功效 | LLM & agent evaluation with statistical rigor
Self-hosted LLM evaluation lab: MMLU-Pro / BFCL / IFEval / LiveCodeBench / HumanEval+ runs on Tesla V100 and RTX 3090, llama.cpp serving (incl. Volta sm_70), patched API benchmark clients
Task-conditioned tail reliability for tool-using agents under equivalent interfaces
OpenEuroLLM snapshot of the Berkeley Function Calling Leaderboard evaluation harness and OLMo evaluation orchestration.
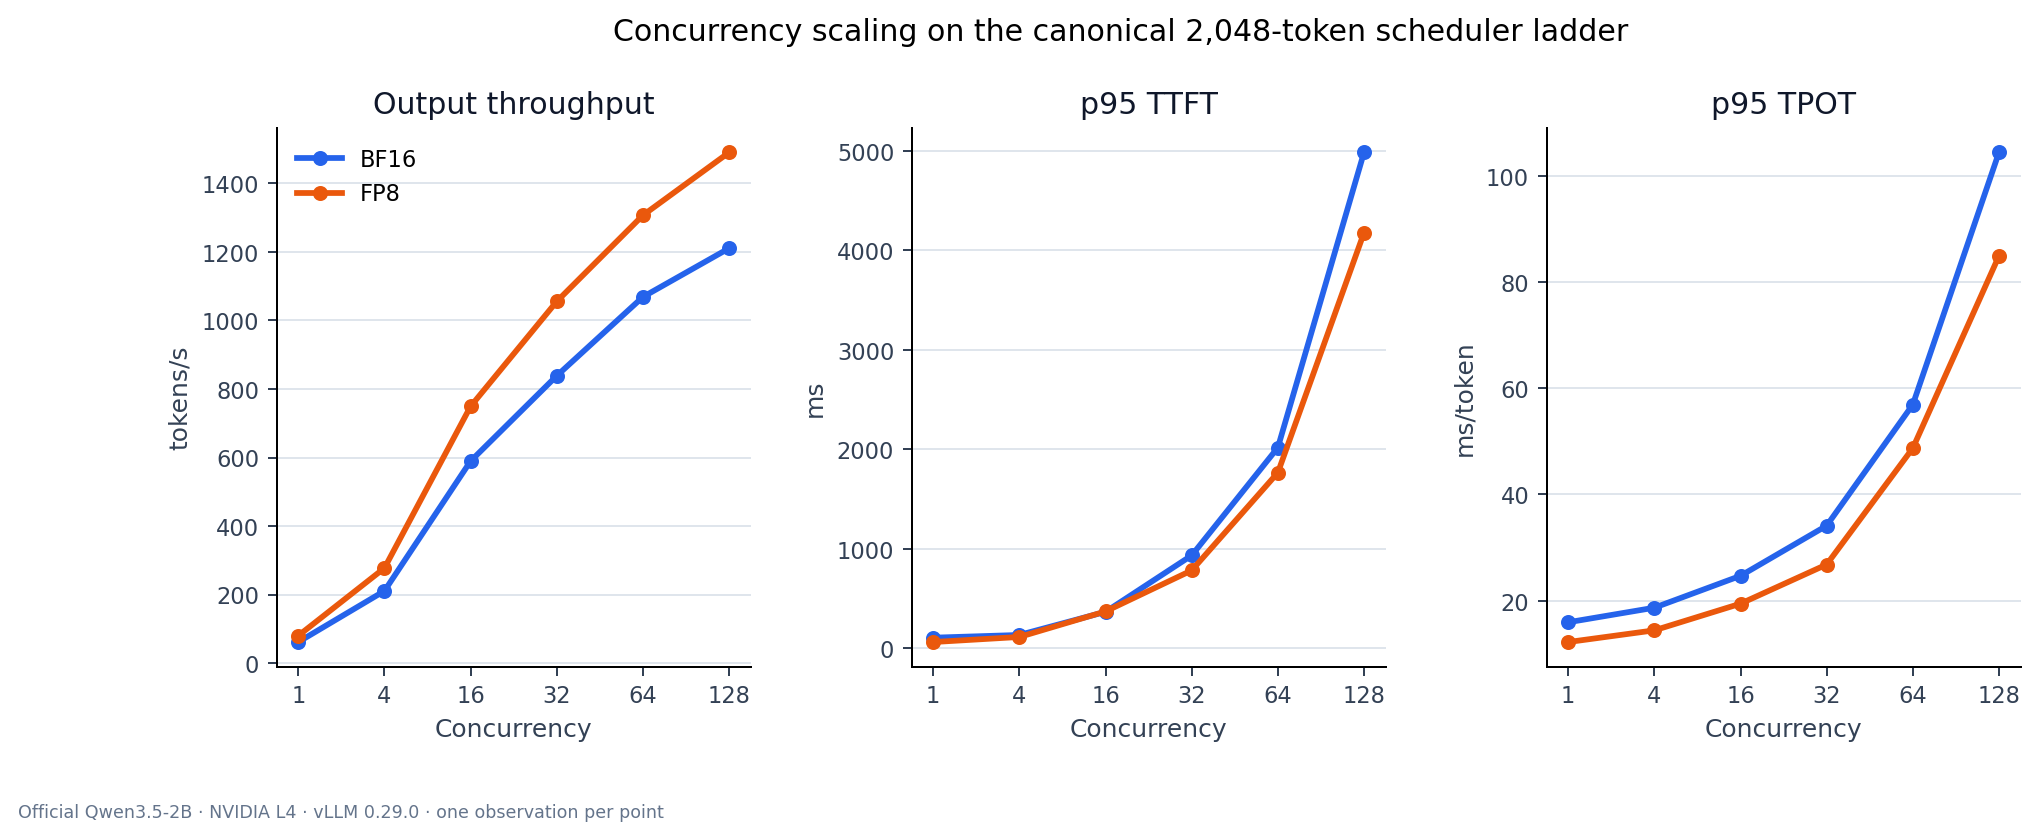
Post-training, BFCL evaluation, and single-L4 vLLM serving benchmarks for Qwen3.5-2B.