llm-evaluation

Open repos and models their makers tagged llm-evaluation, most starred first. The same for everyone.

Developer toolsRepo

iFixAi

Independent Auditing of AI Agents. Run by human or the agent itself, to answer the most crucial question in the AI Agent Economy. Is the agent doing what is supposed to do? With iFixAi you can have this answer in less than 120 seconds.

  • 46k
  • Python
  • Apache-2.0
  • 13 h ago
ifixai-aiTake it
AI on my own machineRepo

langfuse

🪢 Open source AI engineering platform: AI Gateway, agent observability, evals, and prompt/skill management, built on OpenTelemetry. One open platform for every AI call and every agent. Self-host or use Langfuse Cloud.

  • 38k
  • TypeScript
  • 10 h ago
langfuseTake it
AI agentsRepo

mlflow

The open source AI engineering platform for agents, LLMs, and ML models. MLflow enables teams of all sizes to debug, evaluate, monitor, and optimize production-quality AI applications while controlling costs and managing access to models and data.

  • 29k
  • Python
  • Apache-2.0
  • 2 d ago
mlflowTake it
AI on my own machineRepo

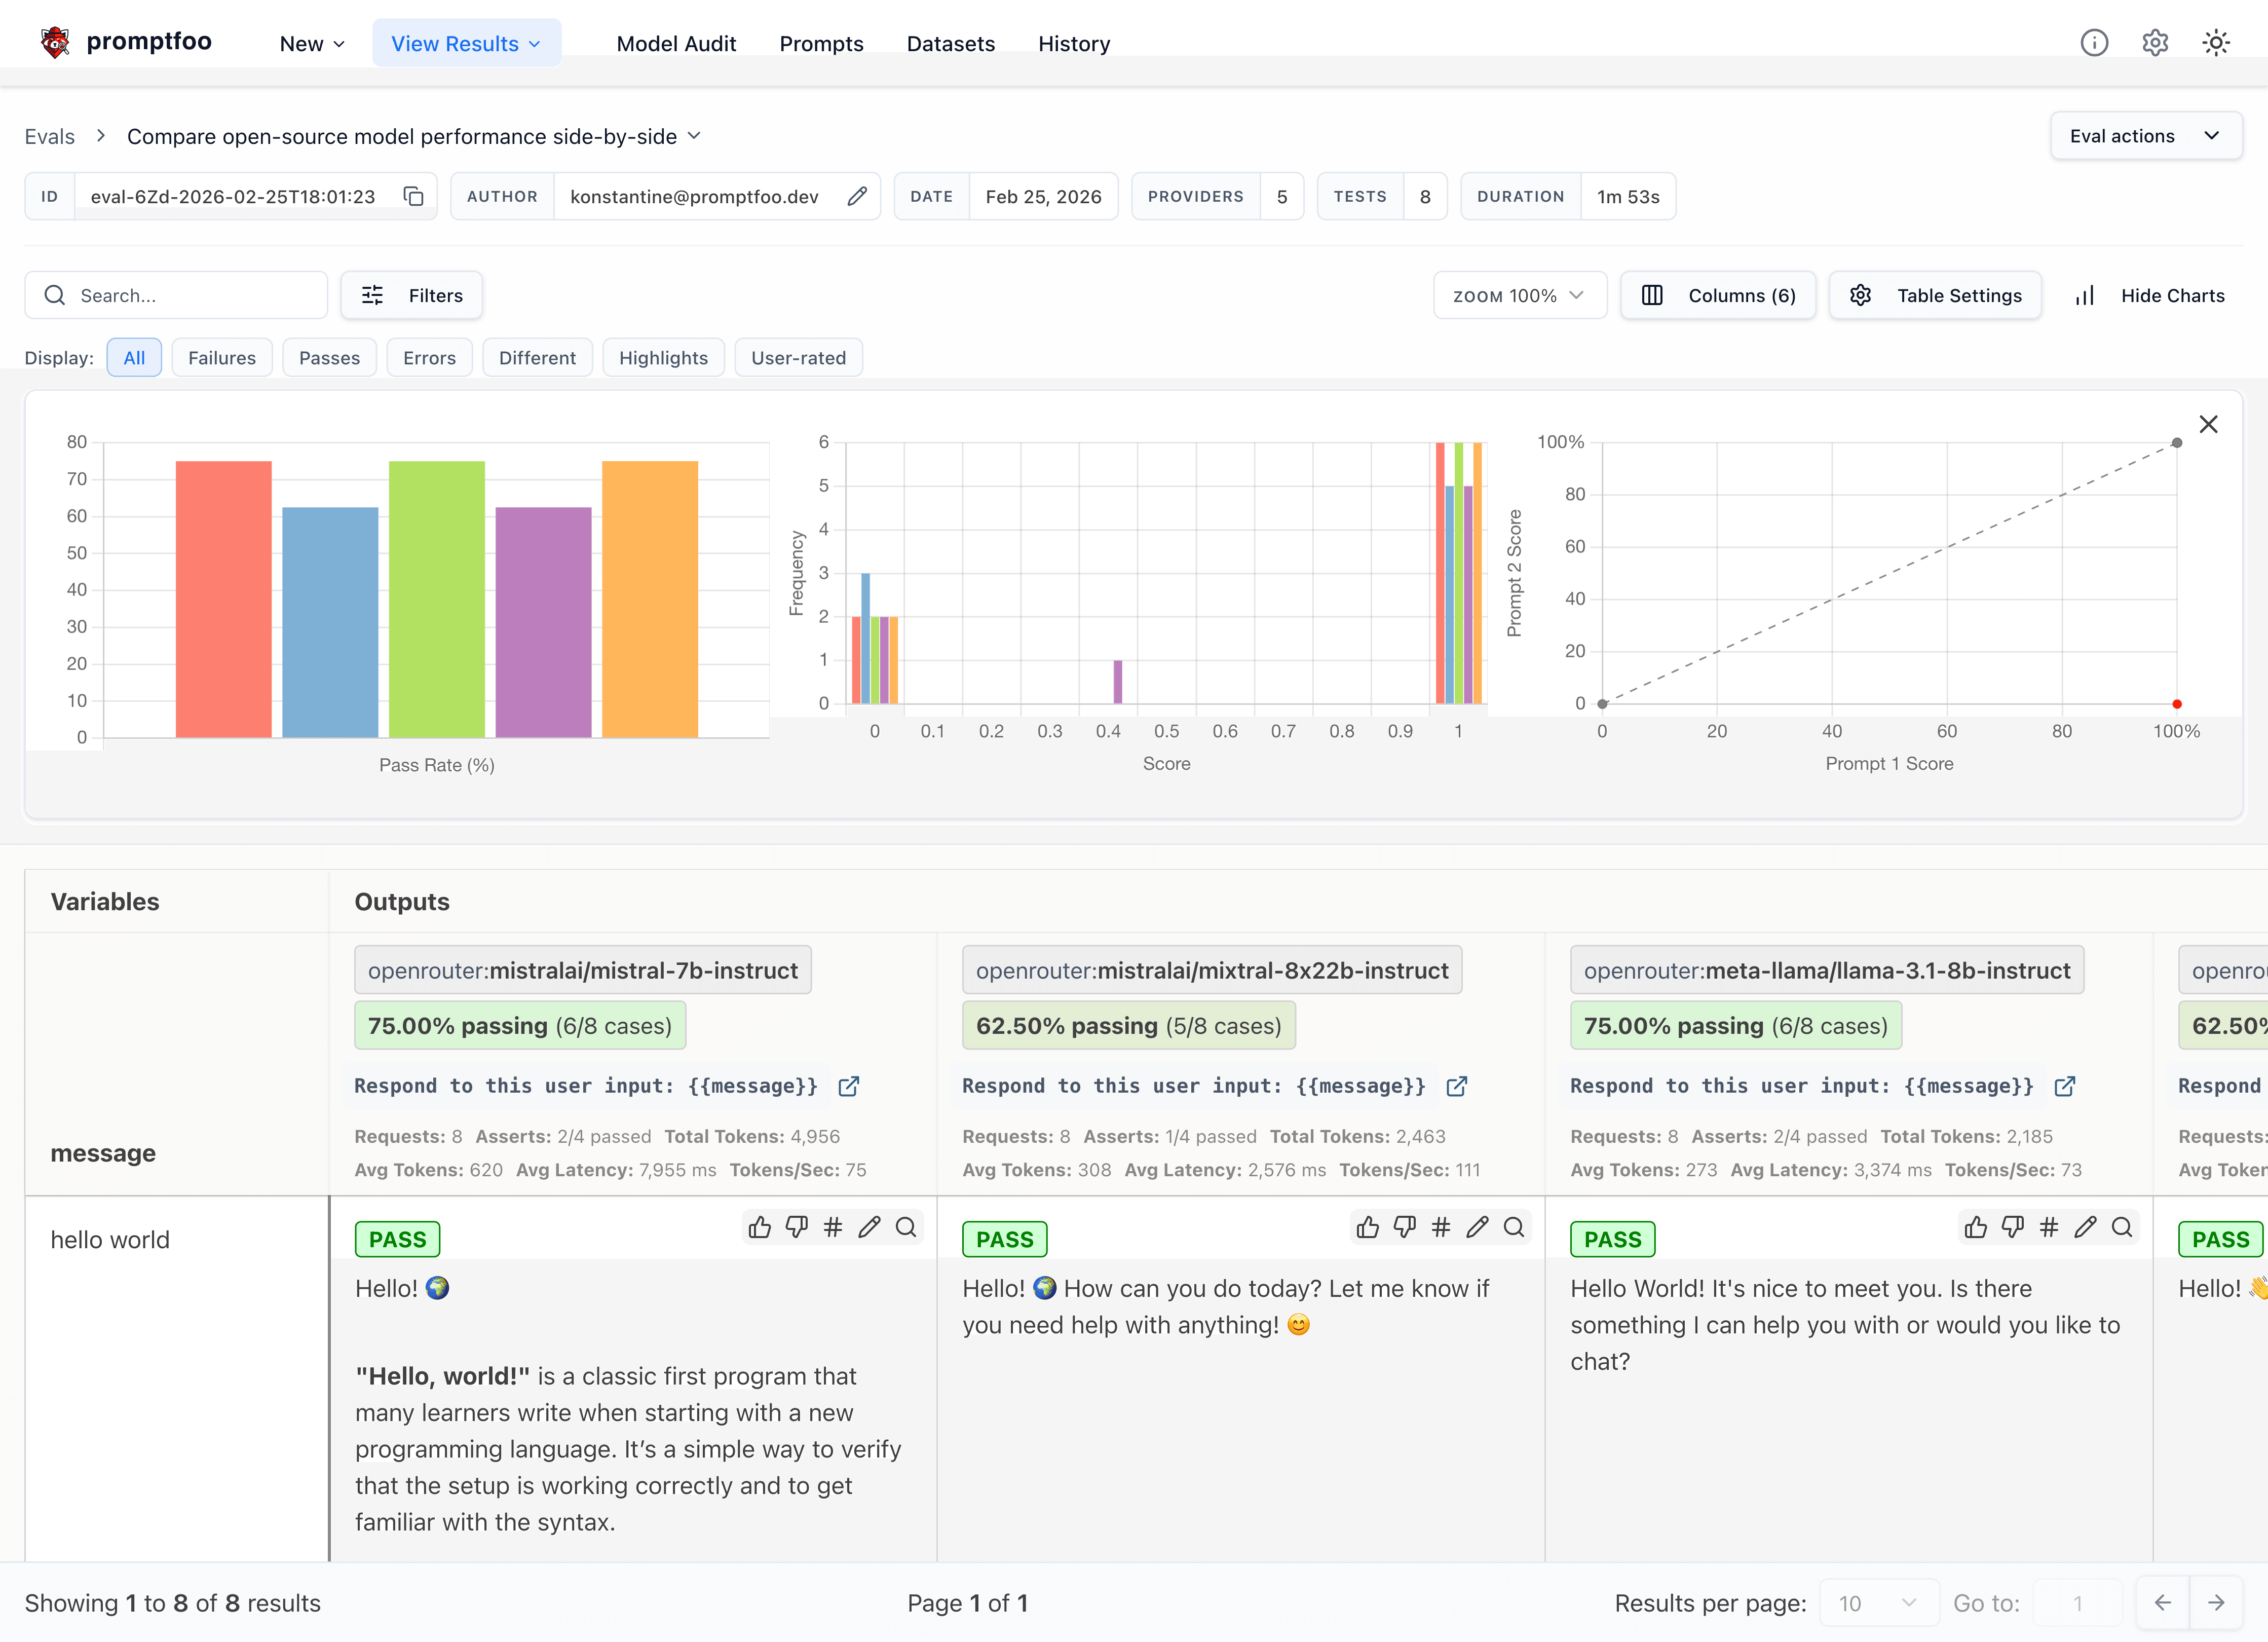
promptfoo

Test your prompts, agents, and RAGs. Red teaming/pentesting/vulnerability scanning for AI. Compare performance of GPT, Claude, Gemini, DeepSeek, and more. Simple declarative configs with command line and CI/CD integration. Used by OpenAI and Anthropic.

  • 28k
  • TypeScript
  • MIT
  • 1 h ago
promptfooTake it
AI on my own machineRepo

opik

Debug, evaluate, and monitor your LLM applications, RAG systems, and agentic workflows with comprehensive tracing, automated evaluations, and production-ready dashboards.

  • 23k
  • Java
  • Apache-2.0
  • 2 d ago
comet-mlTake it
AI agentsRepo

AI-Infra-Guard

A full-stack AI Red Teaming platform securing AI ecosystems via Agent Scan, Skills Scan, MCP scan, AI Infra scan and LLM jailbreak evaluation.

  • 7.6k
  • Python
  • Apache-2.0
  • 1 d ago
TencentTake it
GitHubRepo

chinese-llm-benchmark

非线智能 NoneLinear - ReLE评测:中文AI大模型能力评测(持续更新):目前已囊括374个大模型,覆盖chatgpt、gpt-5.4、谷歌gemini-3.1-pro、Claude-4.6、文心ERNIE-X1.1、ERNIE-5.0、qwen3.6-max、qwen3.6-plus、百川、讯飞星火、商汤senseChat等商用模型, 以及step3.5-flash、kimi-k2.6、ernie4.5、MiniMax-M2.7、deepseek-v4、Qwen3.6、llama4、智谱GLM-5.1、MiMo-V2、LongCat、gemma4、mistral等开源大模型。不仅提供排行榜,也提供规模超200万的大模型缺陷库!方便广大社区研究分析、改进大模型。

  • 6.5k
  • 23 h ago
jeinlee1991Take it
Developer toolsRepo

ouroboros

Agent OS: the agent gets smarter on its own. We just hold the line: Interview-gated, staged evaluation, budgeted evolution loop. MCP server, 14 runtimes: Claude Code, Codex CLI, Gemini CLI, OpenCode, Copilot, Kiro and more.

  • 6.4k
  • Python
  • MIT
  • 7 h ago
Q00Take it
AI agentsRepo

future-agi

Open-source, end-to-end platform for evaluating, observing, and improving LLM and AI agent applications. Tracing · Evals · Simulations · Datasets · Gateway · Guardrails. Self-hostable. Apache 2.0.

  • 2.3k
  • Python
  • Apache-2.0
  • 2 h ago
future-agiTake it
GitHubRepo

prompty

Prompty makes it easy to create, manage, debug, and evaluate LLM prompts for your AI applications. Prompty is an asset class and format for LLM prompts designed to enhance observability, understandability, and portability for developers.

  • 1.3k
  • Rust
  • MIT
  • 12 d ago
microsoftTake it
AI on my own machineRepo

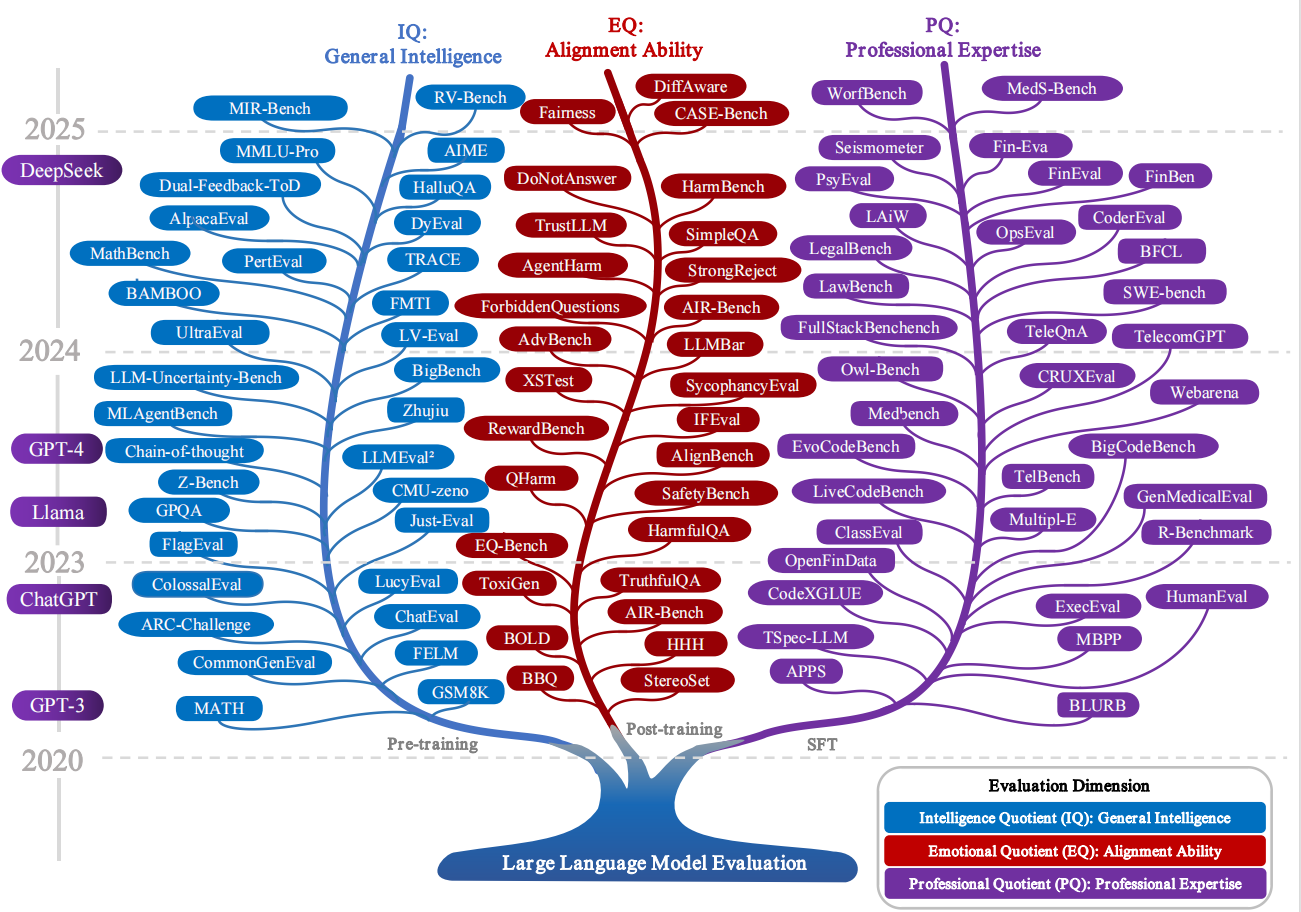
Awesome-LLM-Eval

Awesome-LLM-Eval: a curated list of tools, datasets/benchmark, demos, leaderboard, papers, docs and models, mainly for Evaluation on LLMs. 一个由工具、基准/数据、演示、排行榜和大模型等组成的精选列表,主要面向基础大模型评测,旨在探求生成式AI的技术边界.

  • 661
  • MIT
  • 12 mo ago
onejune2018Take it
AI on my own machineRepo

TrustLLM

[ICML 2024] TrustLLM: LLM trustworthiness evaluation across truthfulness, safety, fairness, robustness, privacy and ethics. Python/CLI toolkit for local models, compatible APIs and AI agent orchestration.

  • 635
  • Python
  • MIT
  • 7 wk ago
HowieHwongTake it
Search GitHub and Hugging Face for llm-evaluation

Get , open it once and sign in. Then come back here and press the button again.