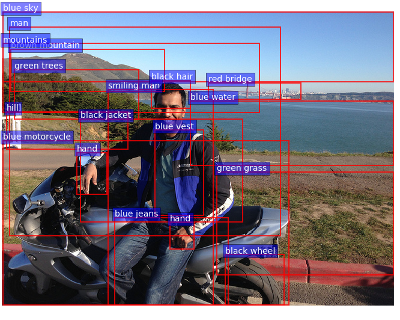
bottom-up-attention
Bottom-up attention model for image captioning and VQA, based on Faster R-CNN and Visual Genome
- 1.5k
- Jupyter Notebook
- MIT
- 4 y ago
Bottom-up attention model for image captioning and VQA, based on Faster R-CNN and Visual Genome
awesome grounding: A curated list of research papers in visual grounding
[CVPR 2020] Meshed-Memory Transformer for Image Captioning
This repository contains my solutions to the assignments for Stanford's CS231n "Convolutional Neural Networks for Visual Recognition" (Spring 2020).
Automatic image captioning model based on Caffe, using features from bottom-up attention.
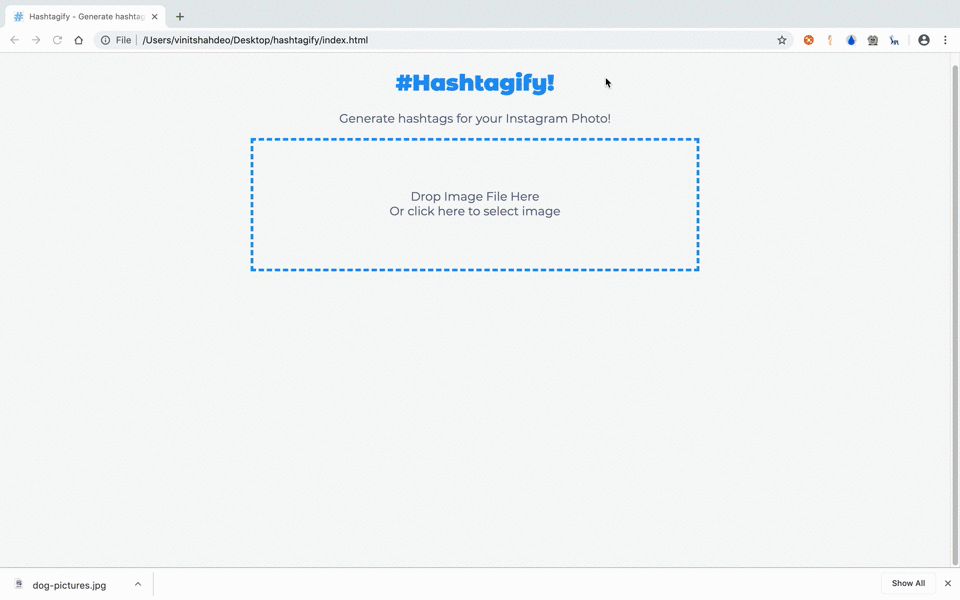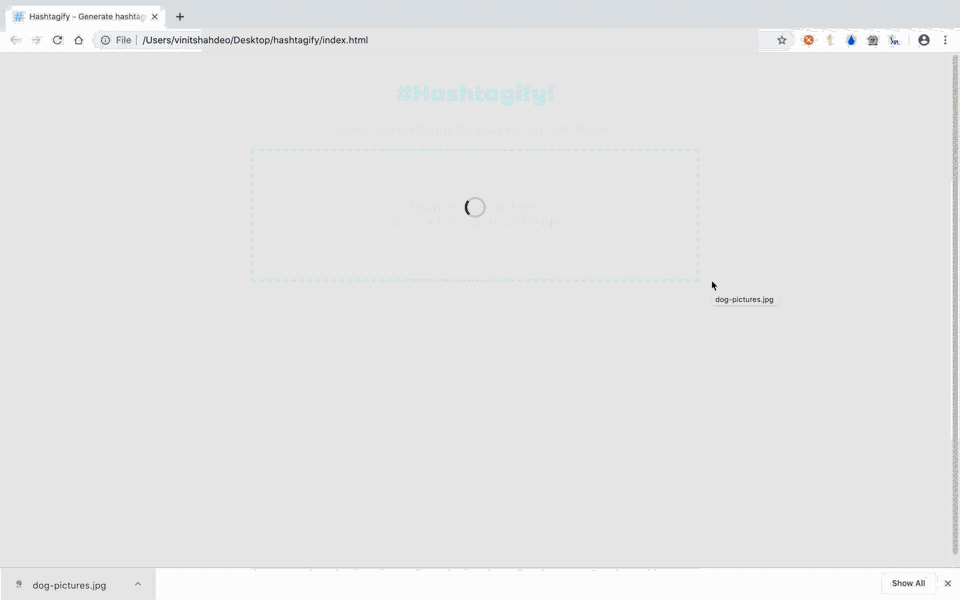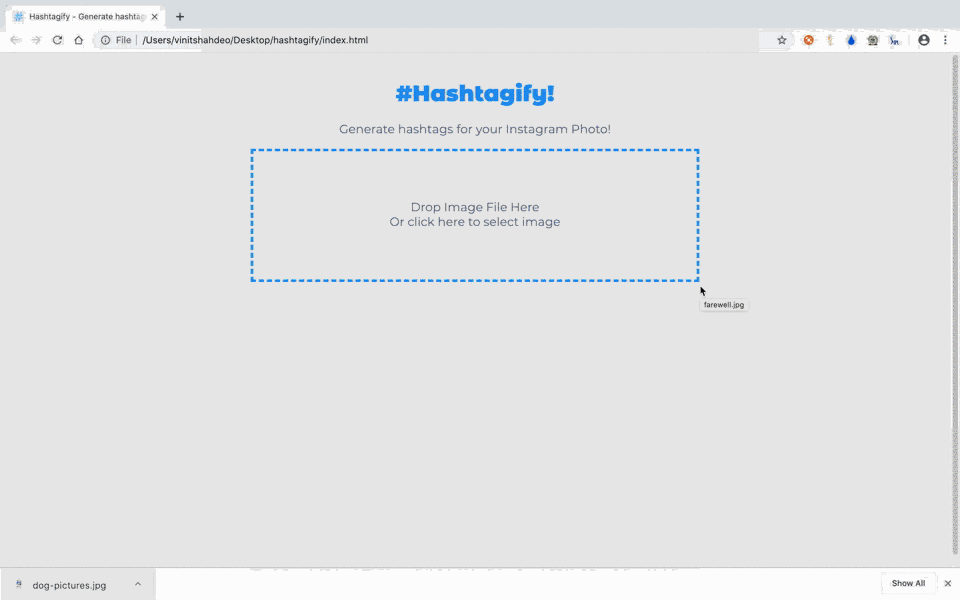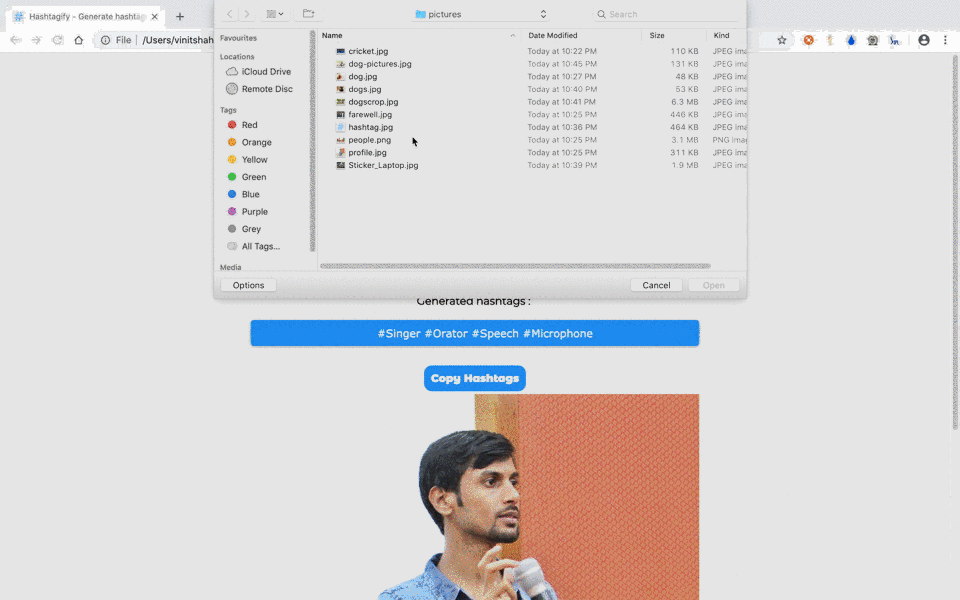
:camera_flash: Generates hashtags for Instagram posts. Upload your photo and it will suggest the relevant #hashtags for you. :label: :trollface:
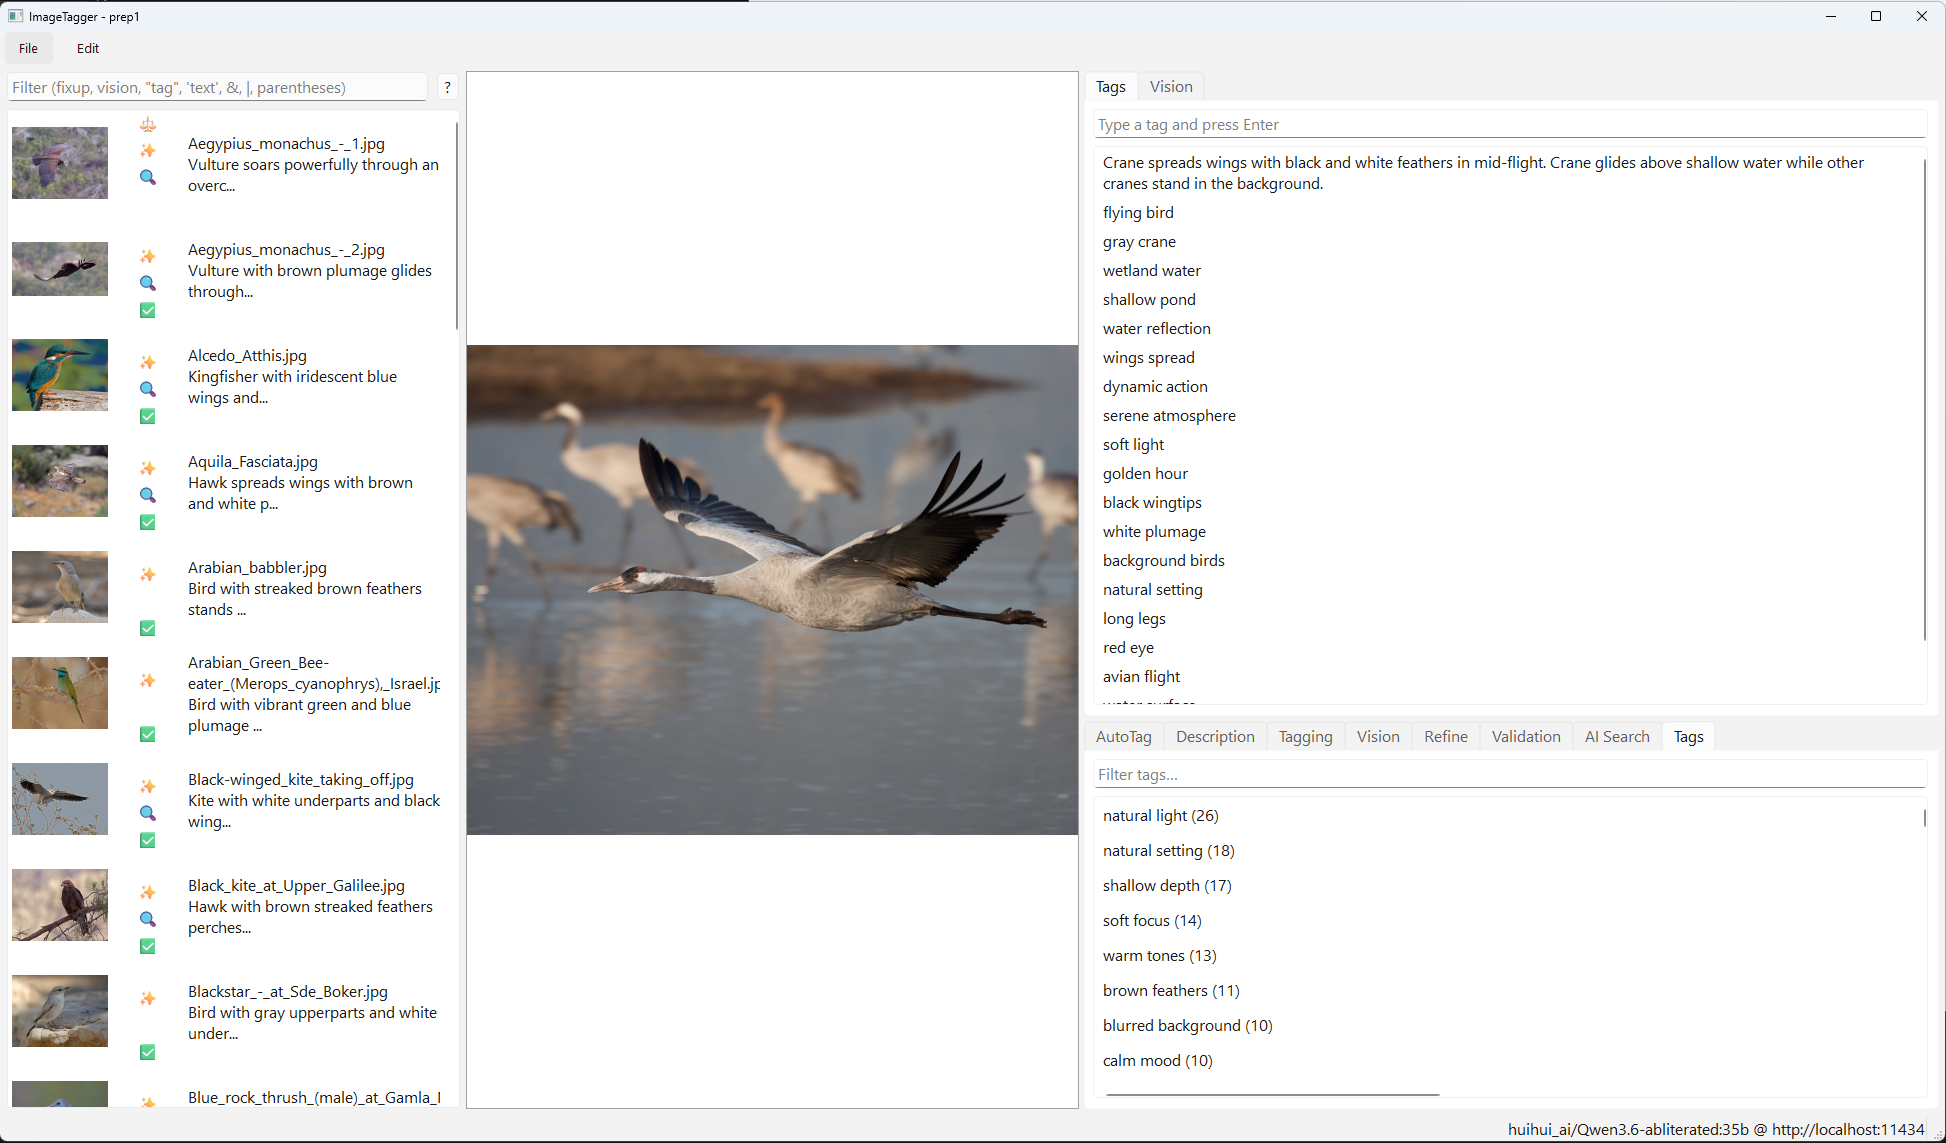
Desktop image library for photographers and creators. Search by content, face or the text in a picture, get help from local AI models to tag and organise your images. Connect ComfyUI to generate and edit pictures, and AI-toolkit to train LoRAs. Also runs as a headless server.
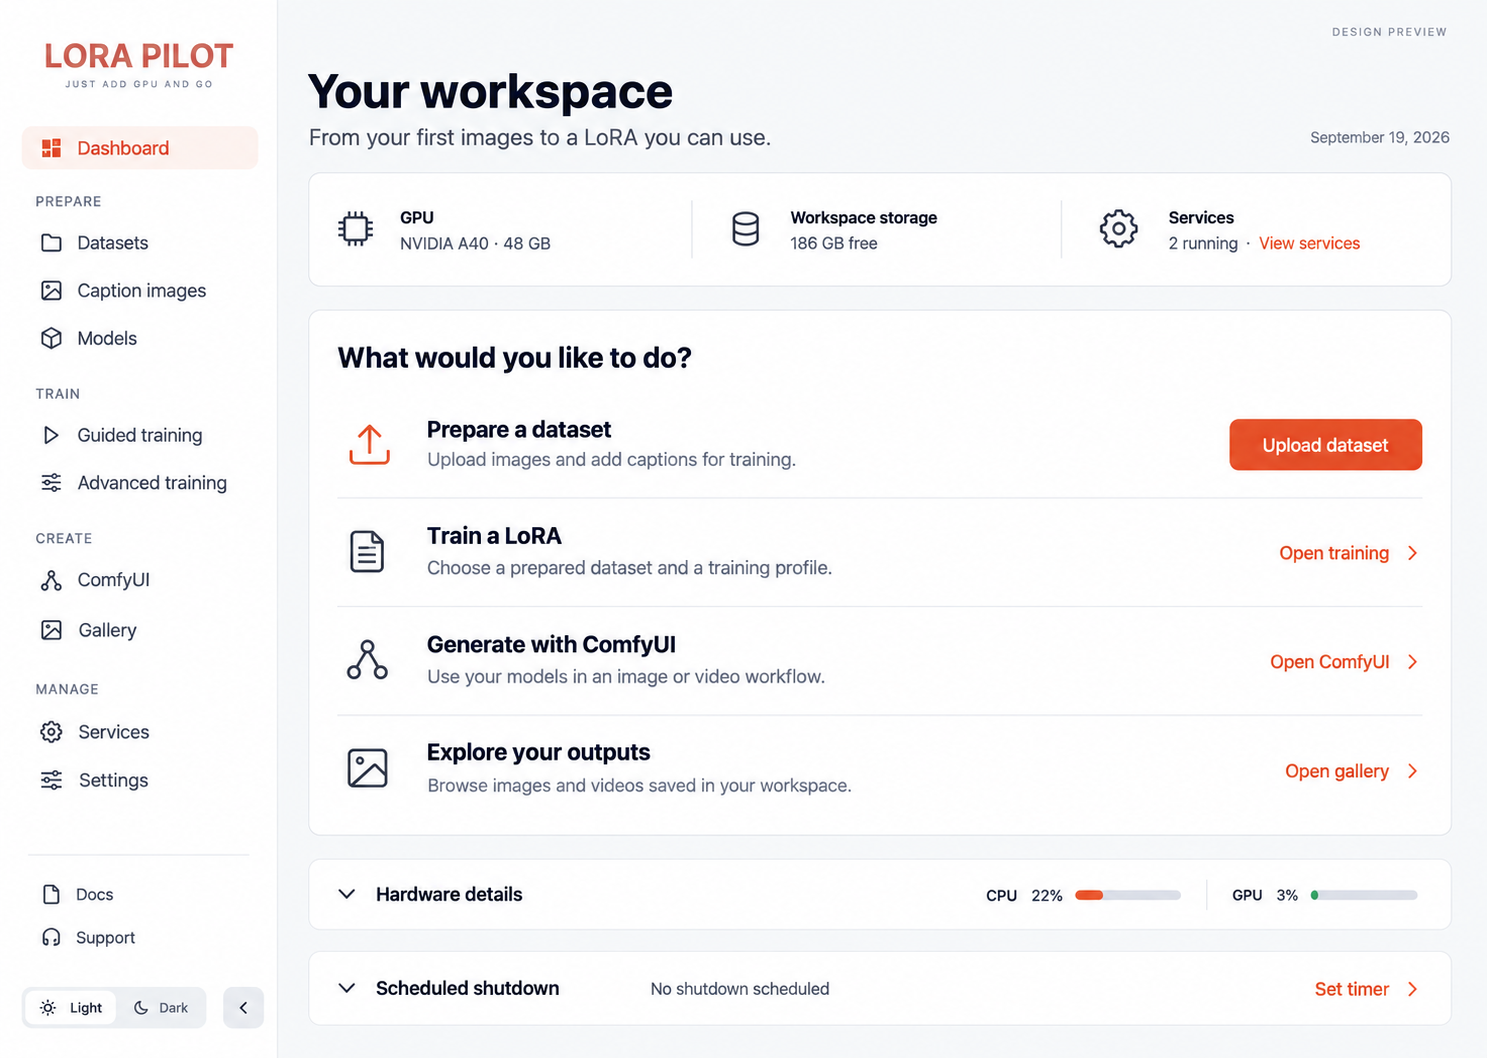
From dataset to trained LoRA to finished image or video. One browser workspace for your models, datasets, training, and generation. LoRA Pilot supports 50+ training model groups, with ComfyUI, Kohya, AI Toolkit, and Diffusion Pipe included. Run on your own GPU or RunPod, and connect AI agents through MCP.
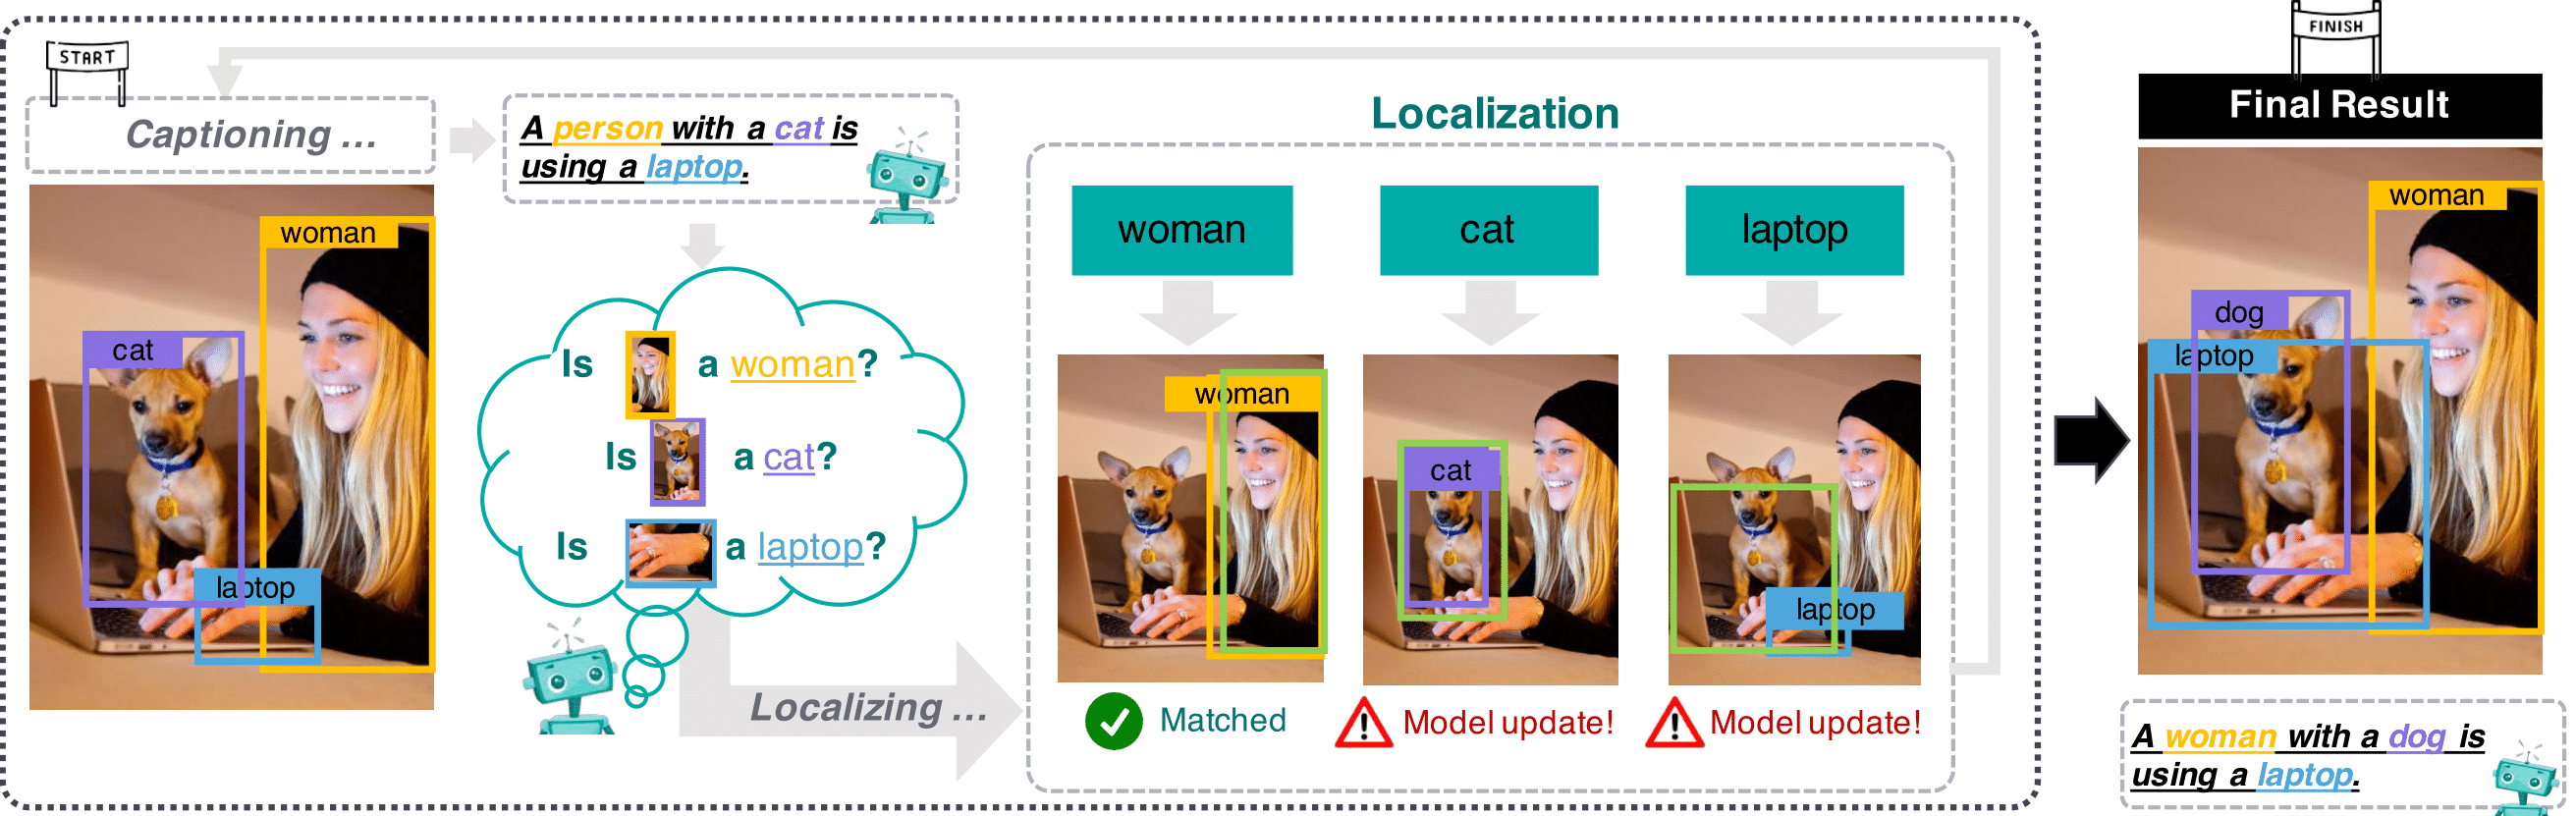
PyTorch code for: Learning to Generate Grounded Visual Captions without Localization Supervision
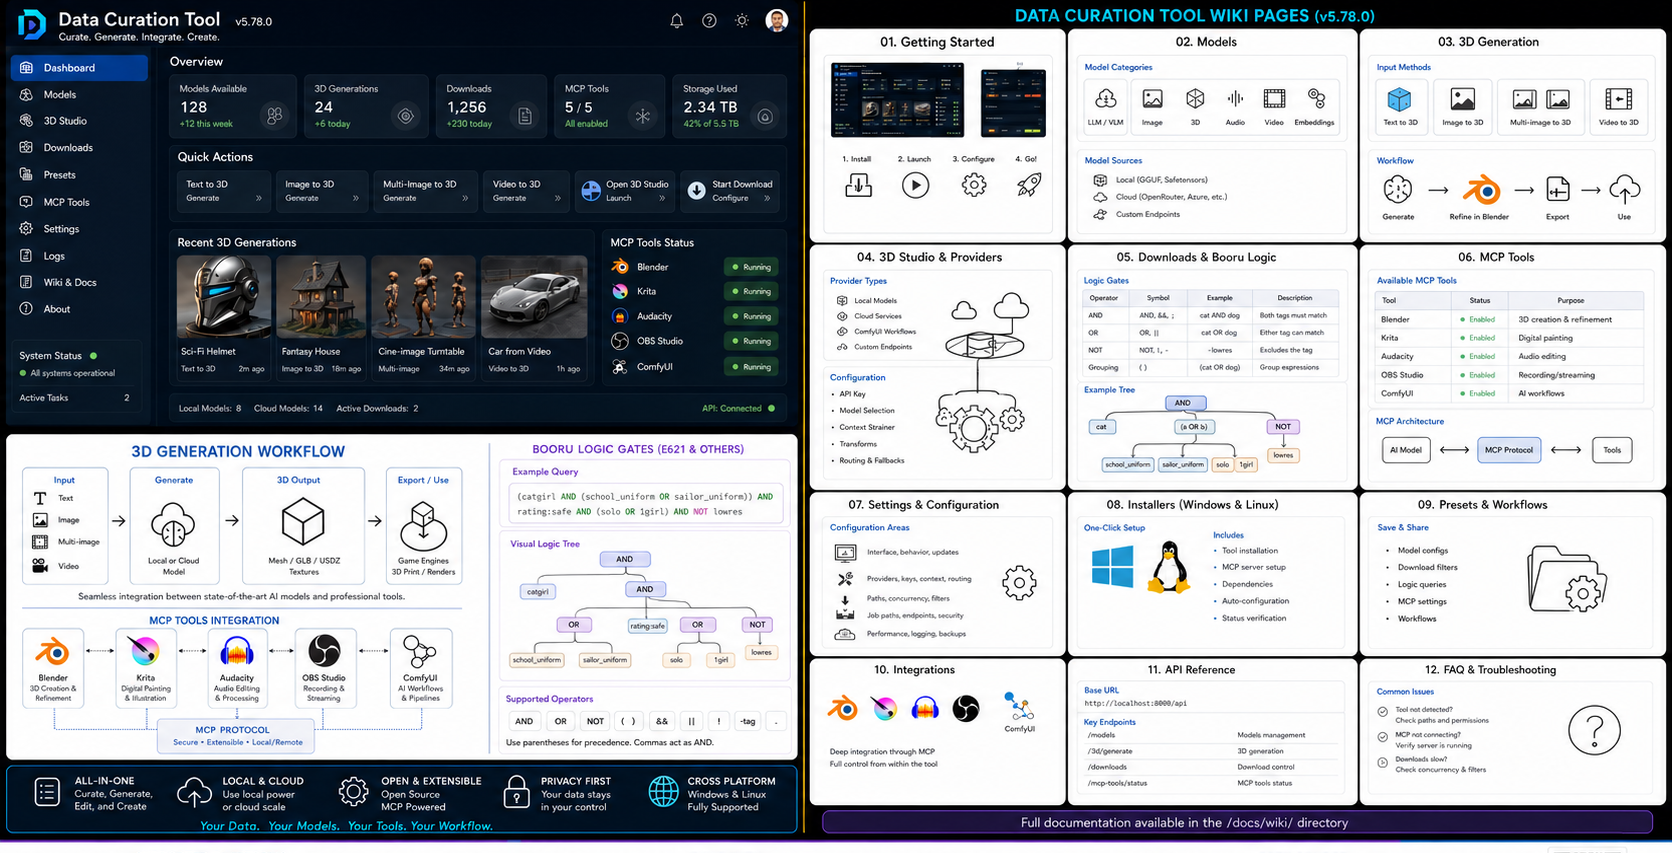
Data Curation Tool is a local-first dataset curation, tagging, model-management, downloader, 3D generation, media metadata, and tool-orchestration application. The current documentation set is stored in docs/wiki/
CLIP Interrogator, fully in HuggingFace Transformers 🤗, with LongCLIP & CLIP's own words and / or *your* own words!
Генерация описаний к изображениям с помощью различных архитектур нейронных сетей
Noise of Web (NoW) is a challenging noisy correspondence learning (NCL) benchmark containing 100K image-text pairs for robust image-text matching/retrieval models.
Aid for blinds. This AI will describe the surrounding, it will tell who is in front of him (if that person is a known person to AI using Facial Recognition) and it will also help him to know what is written (Optical Character Recognition)
Smart-I is an android application aimed at helping the visually impaired using artificial intelligence and cloud computing.
Tiny VLMs Lab is a Hugging Face Space and open-source project showcasing lightweight Vision-Language Models for image captioning, OCR, reasoning, and multimodal understanding. It offers a simple Gradio interface to upload images, query models, adjust generation settings, and export results in Markdown or PDF.
E-commerce fashion assistant with Chatgpt, Hugging Face, Ltree and Pgvector.
Examples in C#, Python, and HTTP for using the Reka Vision API to caption images and videos.