rtk
CLI proxy that reduces LLM token consumption by 60-90% on common dev commands. Single Rust binary, zero dependencies
- 87k
- Rust
- Apache-2.0
- 18 h ago
CLI proxy that reduces LLM token consumption by 60-90% on common dev commands. Single Rust binary, zero dependencies
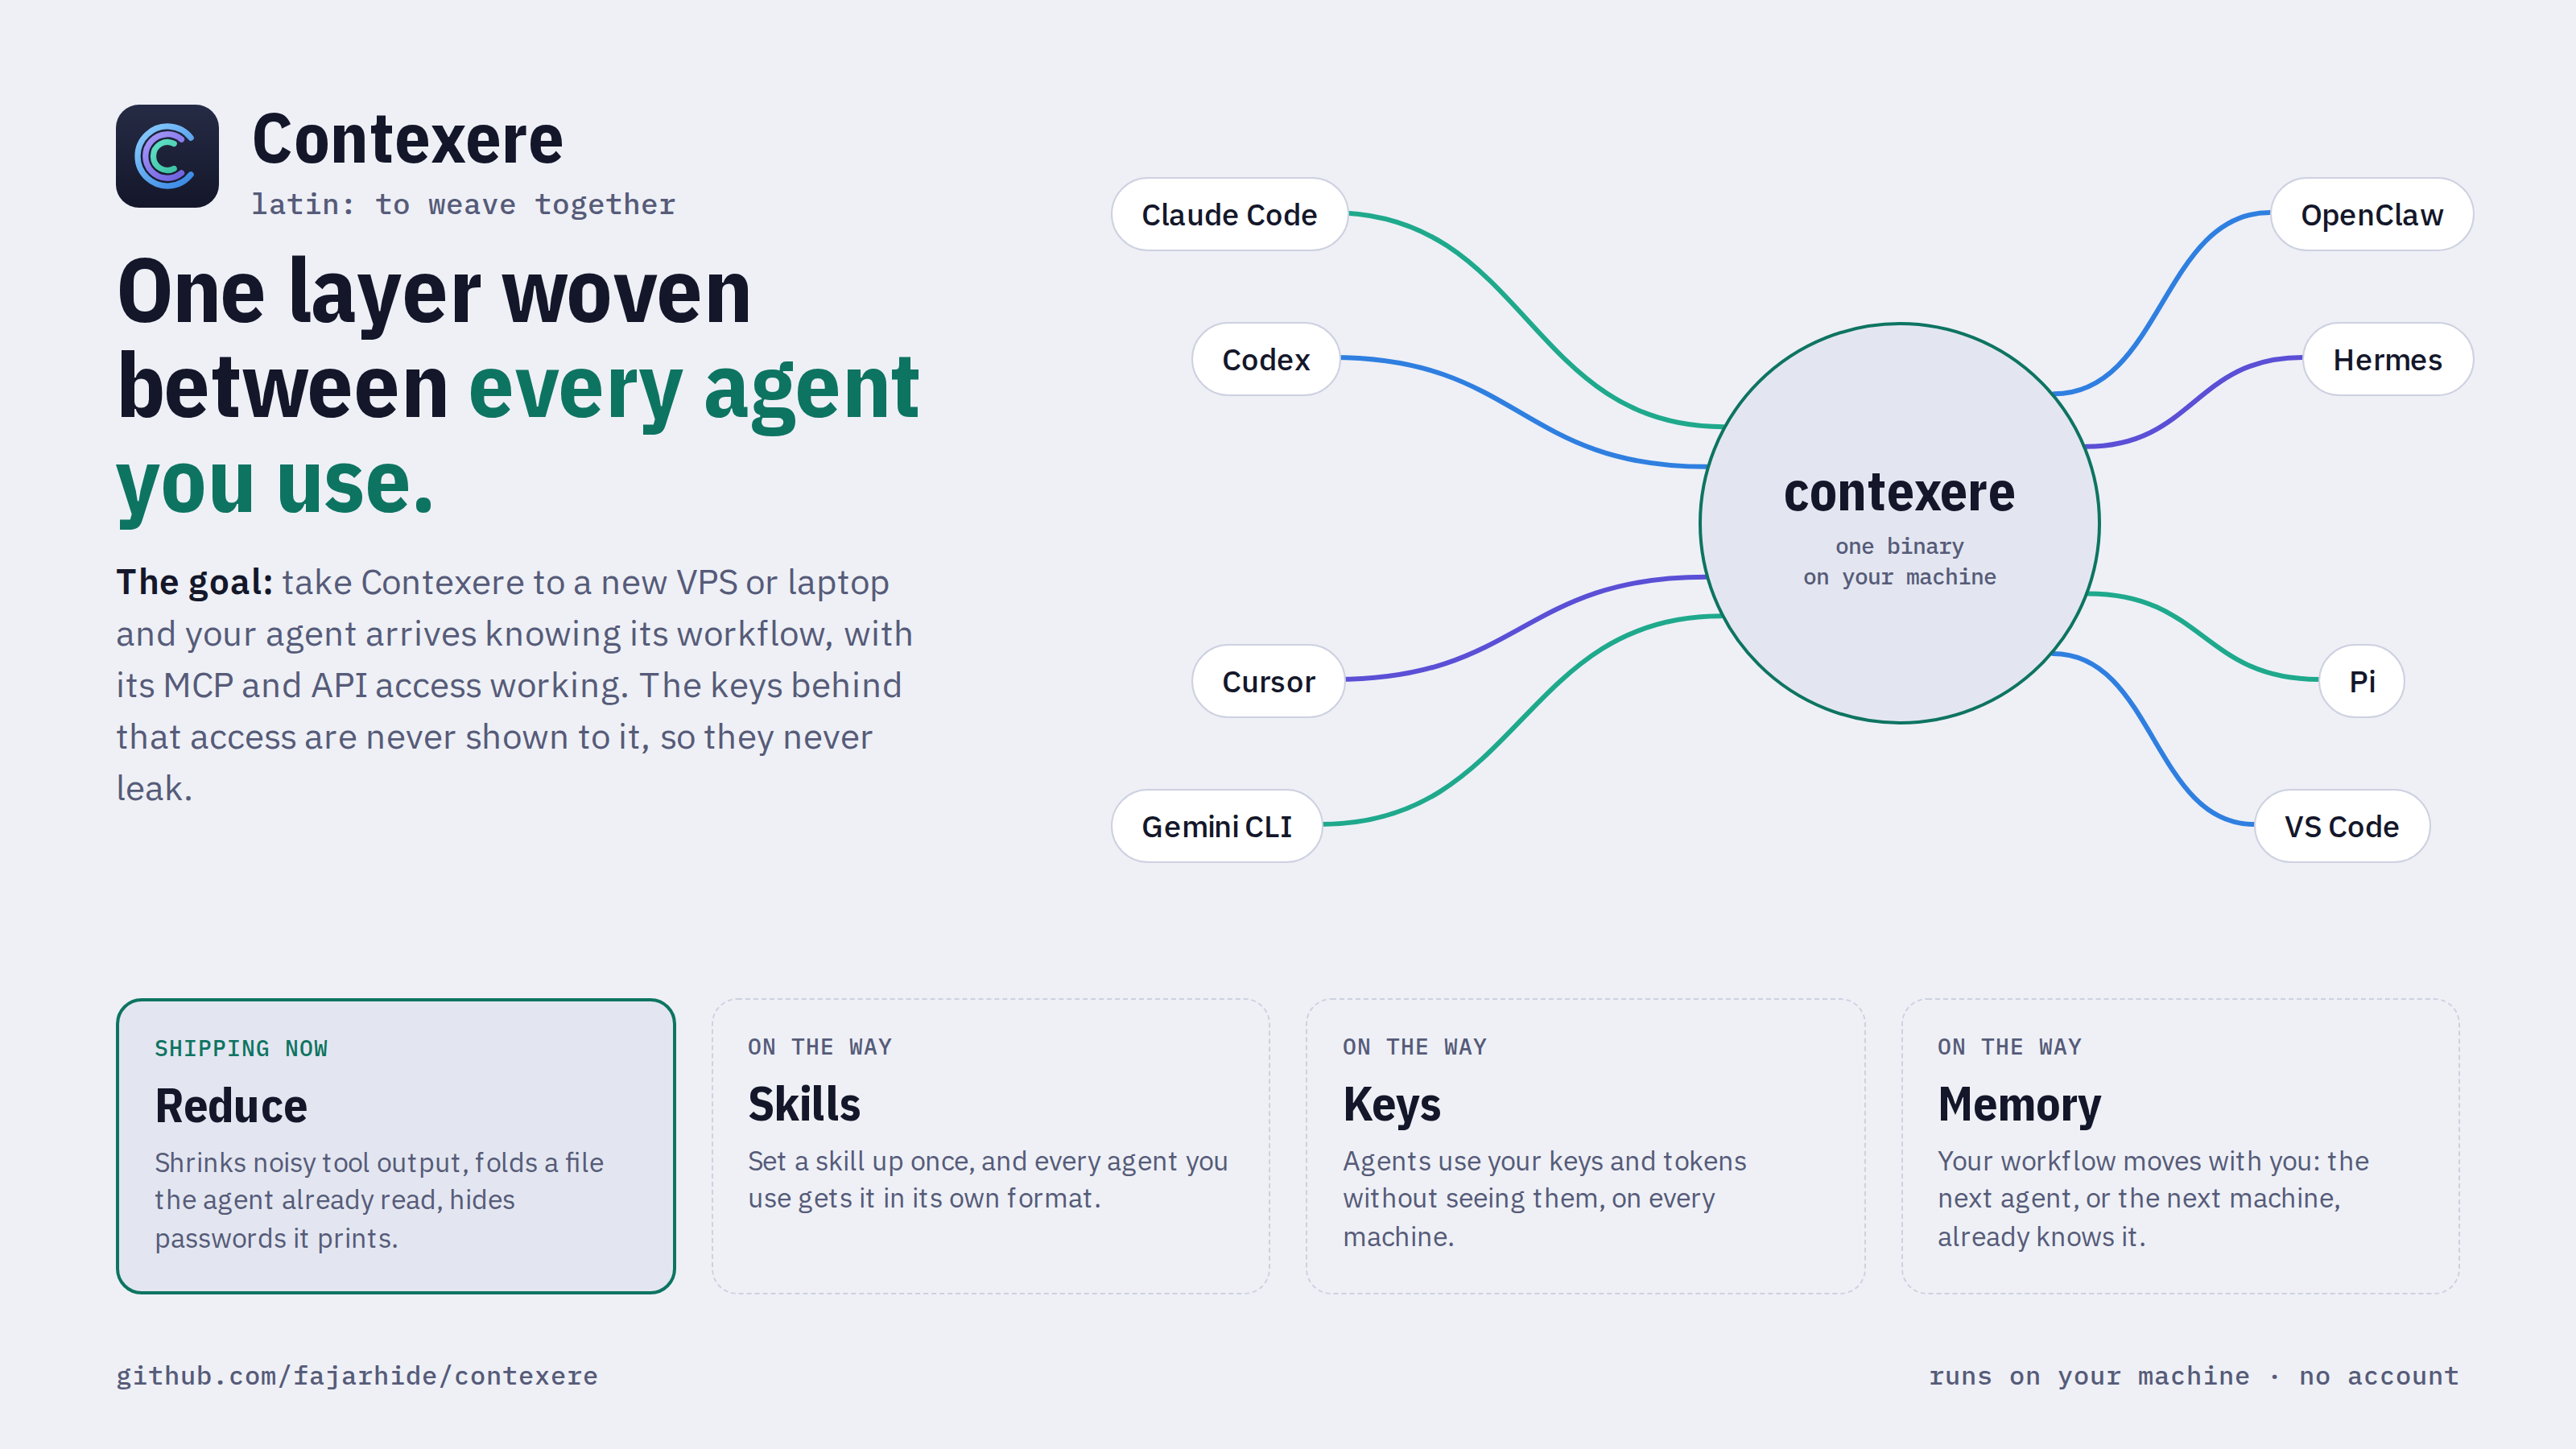
The one place for the skills, keys and memory of every agent you use. Formerly OMNI.
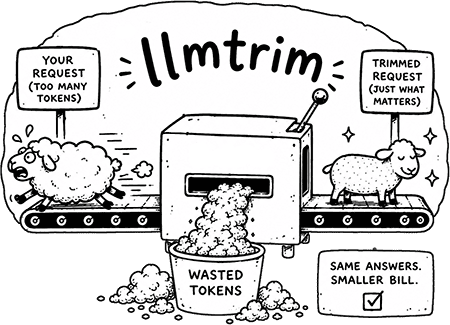
Local proxy that compresses your LLM API requests so you pay less, with no change to the answers. Trims wasted tokens from prompts, history, tool output, and code before they're sent: -31% input / -74% output, measured live. Any provider, no extra model calls. Also an MCP server and embeddable library (Rust, Python, Ruby, Kotlin, Swift, JS/TS).
Cut Claude Code token usage and cost with a one-line output style. Shorter replies than Concise on every Claude model: 29% fewer output tokens and 23% lower cost on Opus 5.5. Benchmarked.
Biological code organization system with 1,029+ production-ready snippets - 95% token reduction for Claude/GPT with AI-powered discovery & offline packs
You approve the plan. CodeBOT does the rest. Semi-autonomous multi-agent development: plan first, execute fully, report every change. Currently built for Copilot & Codex.
Text classification model, used with gguf.
Open-source AI agent efficiency platform: LLM-free context filter + early-exit supervisor cuts token costs ~30% with zero accuracy loss. Works with LangChain, AutoGen, CrewAI, LangGraph and Smolagents.
Replace per-row LLM calls with lightweight ML classifiers. 50-1000× cheaper, same accuracy.