pathway
Python ETL framework for stream processing, real-time analytics, LLM pipelines, and RAG.
- 62k
- Python
- 11 h ago
Python ETL framework for stream processing, real-time analytics, LLM pipelines, and RAG.
High-performance AI pipeline engine with a C++ core and 50+ Python-extensible nodes. Build, debug, and scale LLM workflows with 13+ model providers, 8+ vector databases, and agent orchestration, all from your IDE. Includes VS Code extension, TypeScript/Python SDKs, and Docker deployment.
Miller is like awk, sed, cut, join, and sort for name-indexed data such as CSV, TSV, and tabular JSON
A collection of handy Bash One-Liners and terminal tricks for data processing and Linux system maintenance.
[SIGMOD'27] Easy Data Preparation with latest LLMs-based Operators and Pipelines.
Unified querying, transformation, and modification of JSON, TOML, YAML, XML, INI, HCL, KDL and CSV.
Data processing for and with foundation models! 🍎 🍋 🌽 ➡️ ➡️🍸 🍹 🍷
A GPU-accelerated library containing highly optimized building blocks and an execution engine for data processing to accelerate deep learning training and inference applications.
A light-weight, flexible, and expressive statistical data testing library
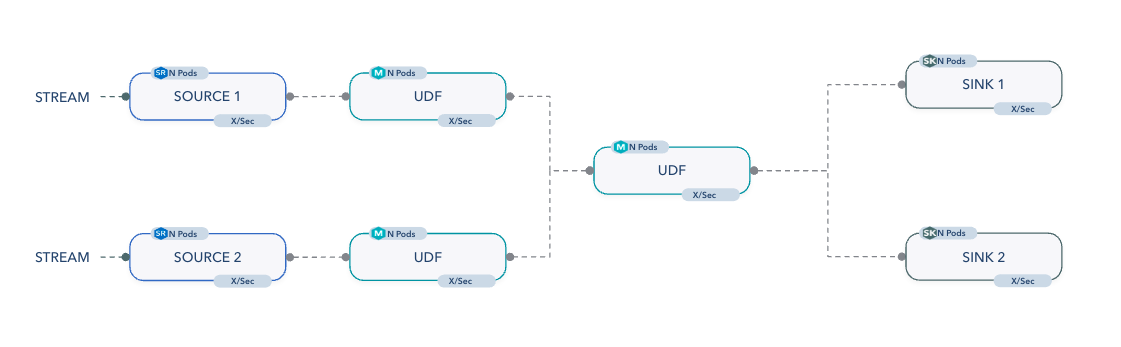
Kubernetes-native platform to run massively parallel data/streaming jobs
The Context Layer for unstructured data: typed, versioned datasets over S3, GCS, Azure
Concurrent and multi-stage data ingestion and data processing with Elixir
Toolkit for Machine Learning, Natural Language Processing, and Text Generation, in TensorFlow. This is part of the CASL project: http://casl-project.ai/
Machine Learning notebooks for refreshing concepts.
Lineage metadata API, artifacts streams, sandbox, API, and spaces for Polyaxon
MCP Server and CLI for Apache Spark History Server. Debug Spark applications from AI agents, scripts, or the terminal.
DeepStream Libraries offer CVCUDA, NvImageCodec, and PyNvVideoCodec modules as Python APIs for seamless integration into custom frameworks.
Read and write Excel (.xlsx, .xls), CSV, and ODS files in Java with one line of code. Annotation-based mapping, SAX streaming, built-in validation, 19 type converters, cell styling. A high-performance alternative to Apache POI.
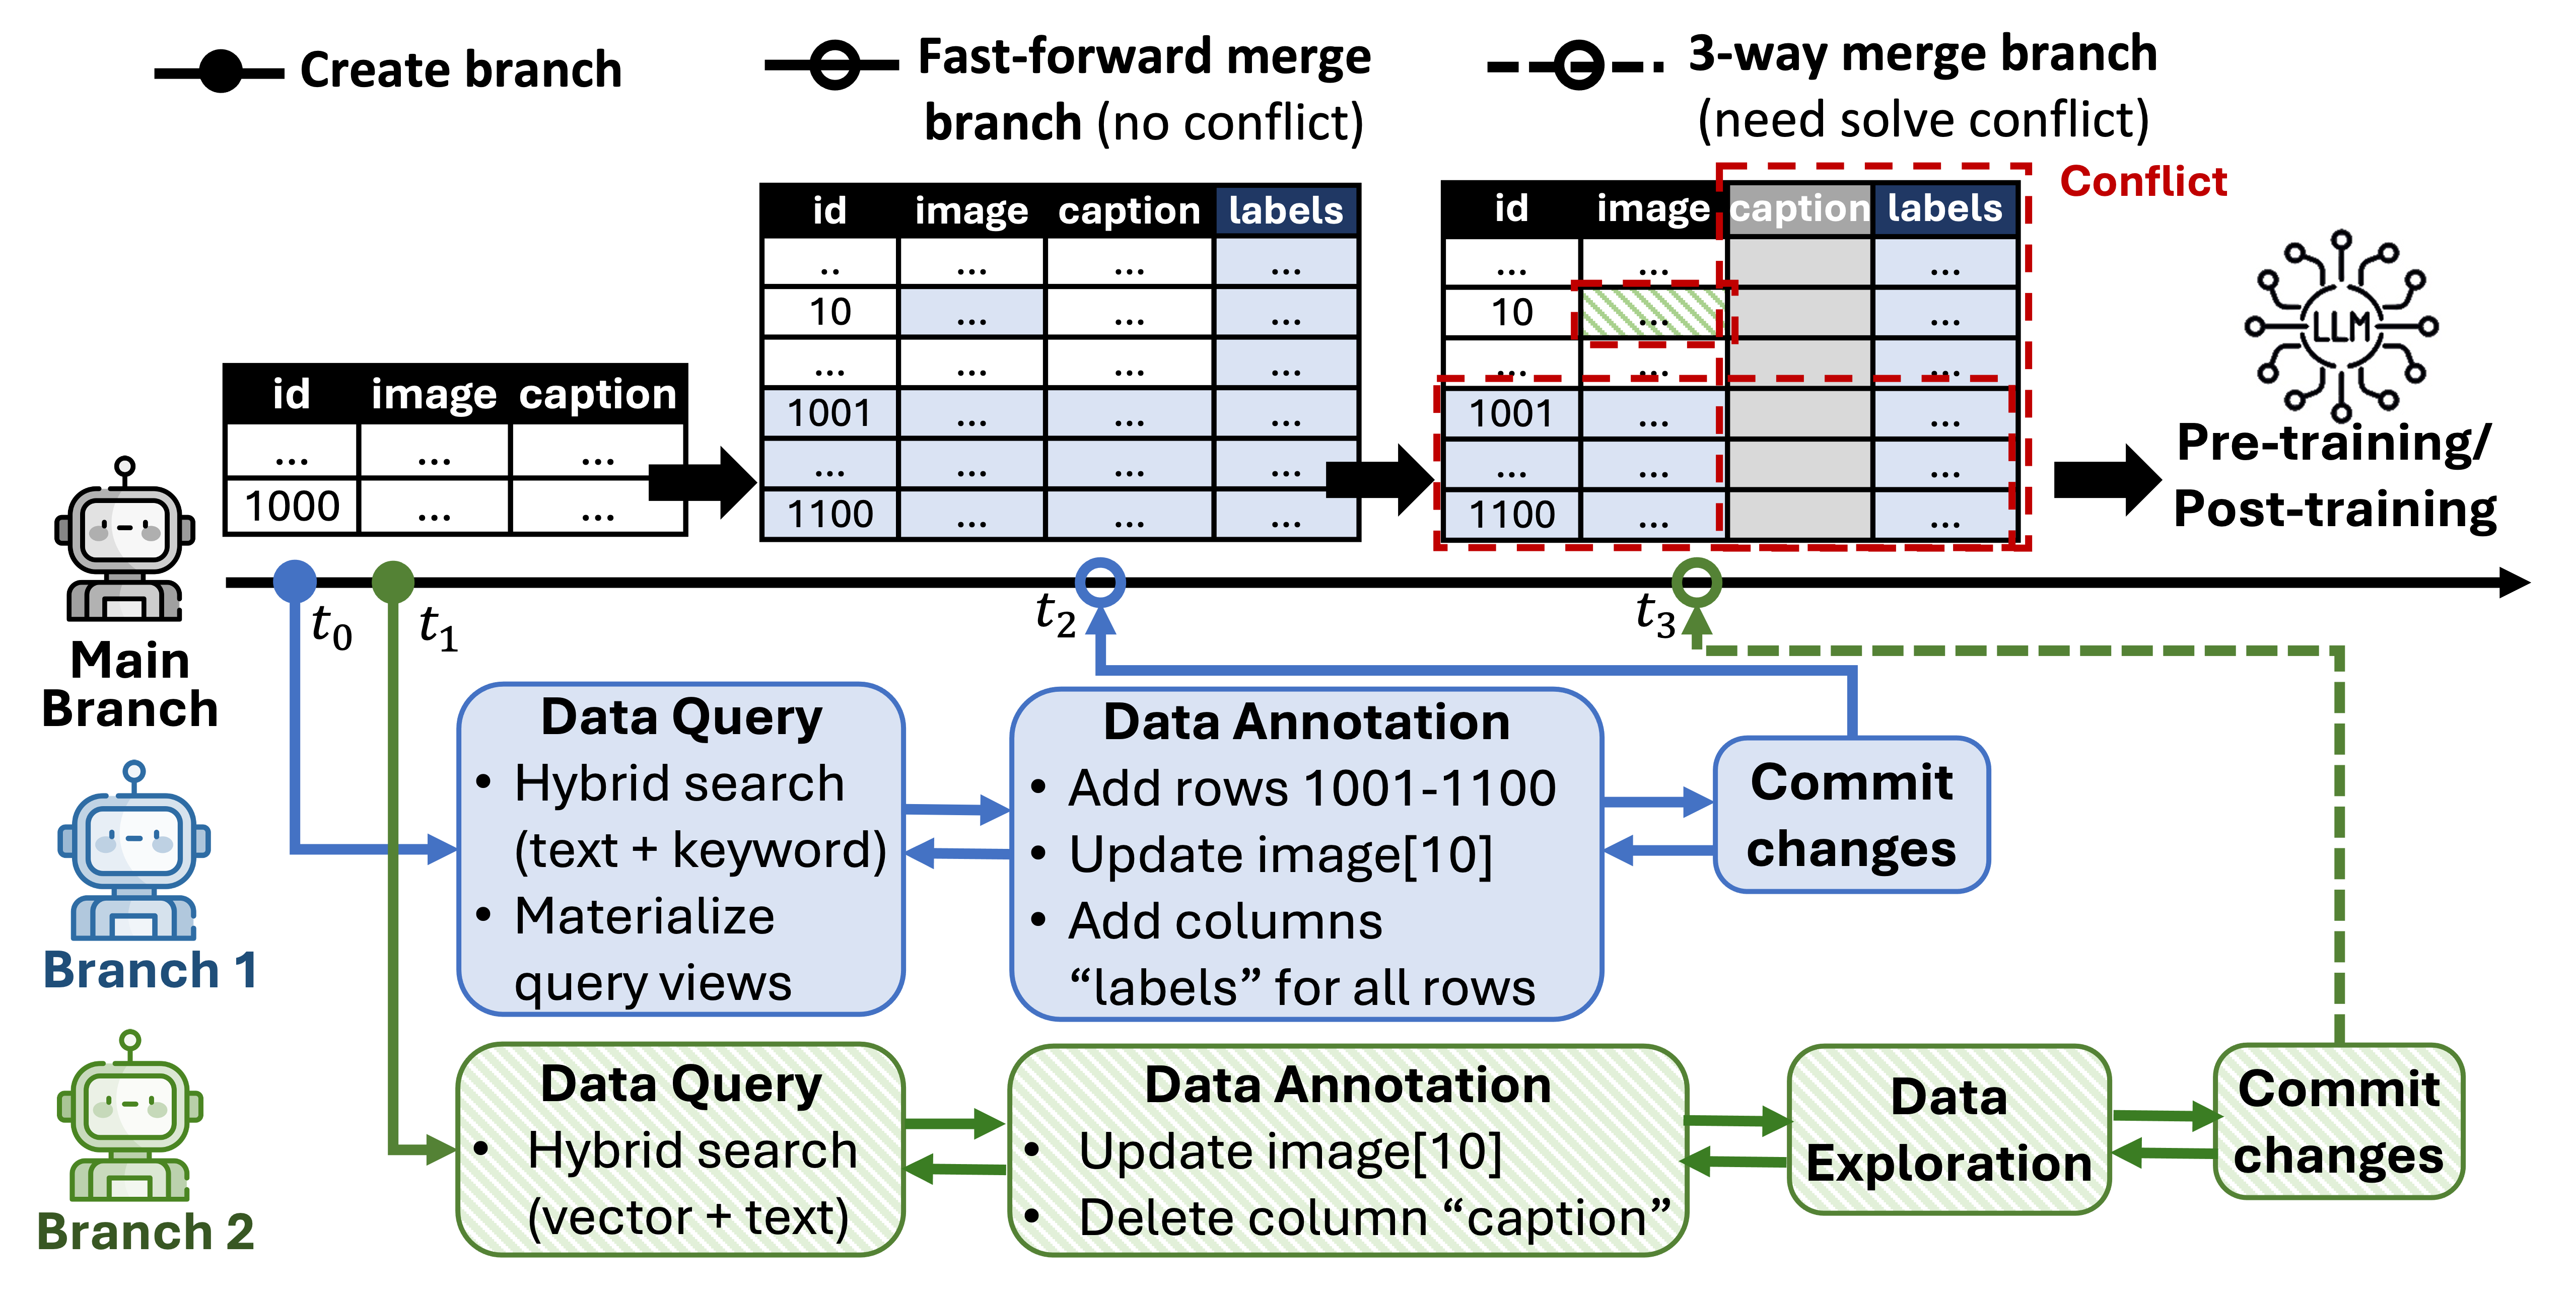
MULLER: A Multimodal Data Lake Format for Collaborative AI Data Workflows
🌐 OpenCrawl: An ethical, high-performance web crawler built for scale A powerful web crawling library that respects robots.txt and rate limits while leveraging Kafka for high-throughput data processing. Built with ethics and efficiency in mind.
This is a custom library for data processing, visualization and machine learning tools.
🤖This file provides an overview of the Python program for processing CSV data and creating new contact with Brevo API.
This repository contains materials for a training session on I/O performance.