airbyte
Open-source data movement for ELT pipelines and AI agents — from APIs, databases & files to warehouses, lakes, and AI applications. Both self-hosted and Cloud.
- 22k
- Python
- 1 d ago
Open-source data movement for ELT pipelines and AI agents — from APIs, databases & files to warehouses, lakes, and AI applications. Both self-hosted and Cloud.
Empowering Data Intelligence with Distributed SQL for Sharding, Scalability, and Security Across All Databases.
Change data capture for a variety of databases. Please log issues at https://github.com/debezium/dbz/issues.
Data processing for and with foundation models! 🍎 🍋 🌽 ➡️ ➡️🍸 🍹 🍷
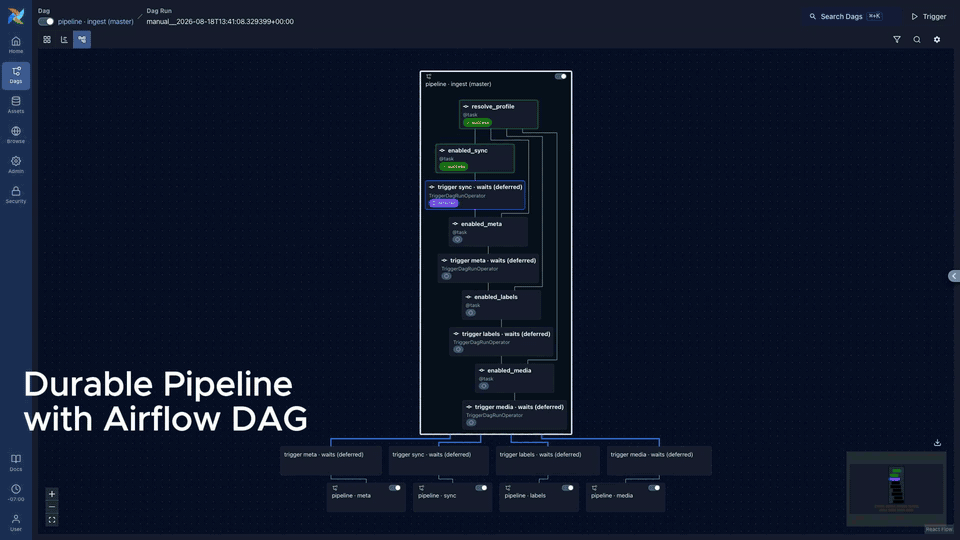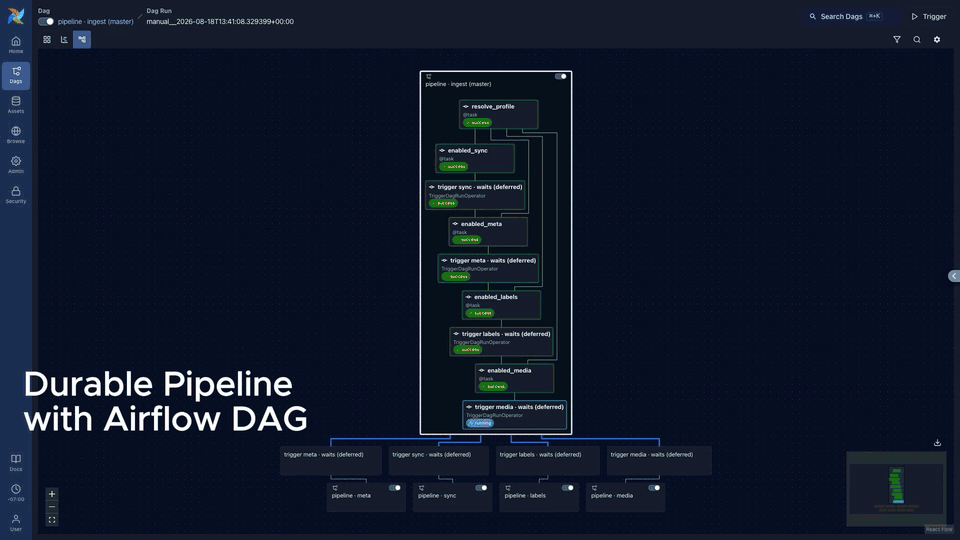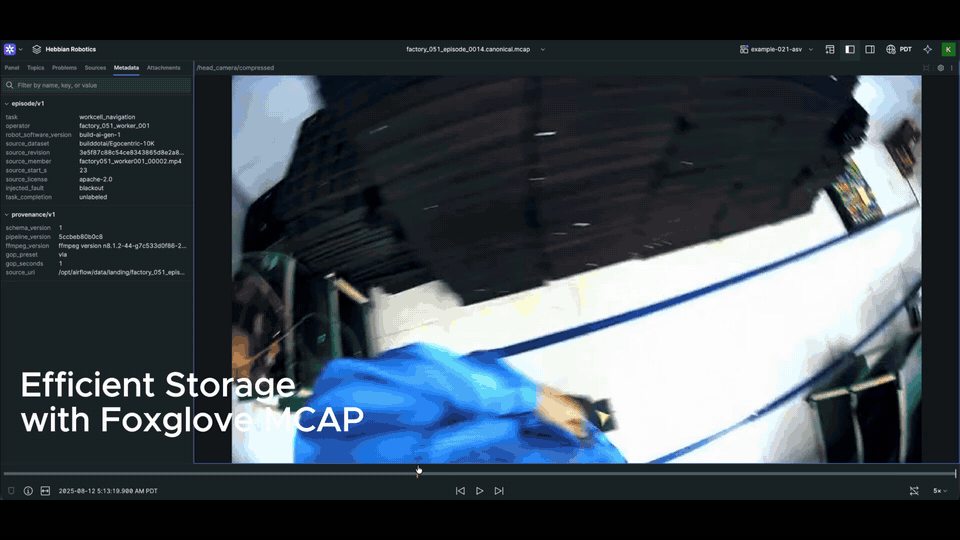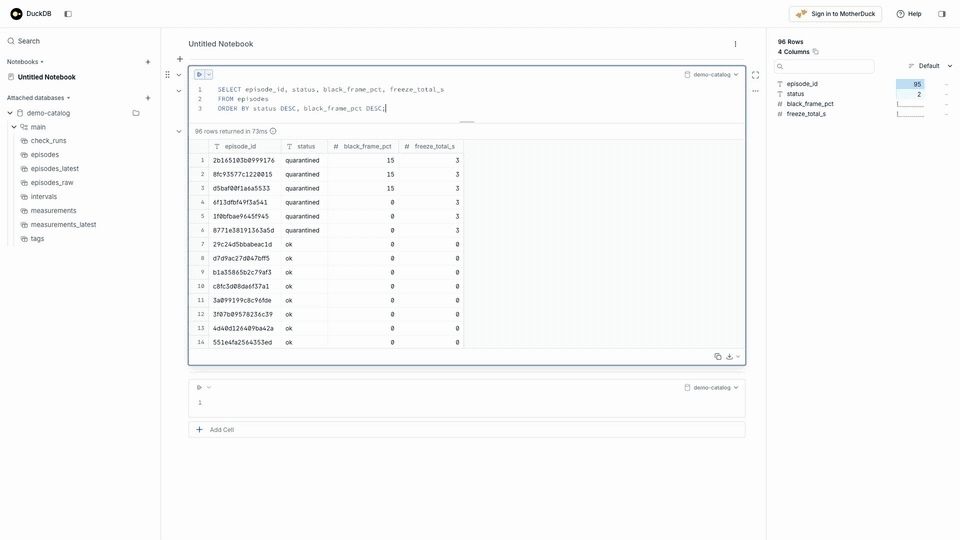
Self-hostable workflow orchestrator for teams whose main work isn't orchestration. Declarative YAML over your scripts, SSH commands, containers, etc; keep workflows separate from business logic. One binary, no database, runs on limited H/W resources. Alternative to Airflow / Cron / Job Scheduler.
ingestr is a CLI tool to copy data between any databases with a single command seamlessly.
Open-source inference server and production cluster for all the models your agent needs.
An open-source data logging library for machine learning models and data pipelines. 📚 Provides visibility into data quality & model performance over time. 🛡️ Supports privacy-preserving data collection, ensuring safety & robustness. 📈
The dbt-native data observability solution for data & analytics engineers. Monitor your data pipelines in minutes. Available as self-hosted or cloud service with premium features.
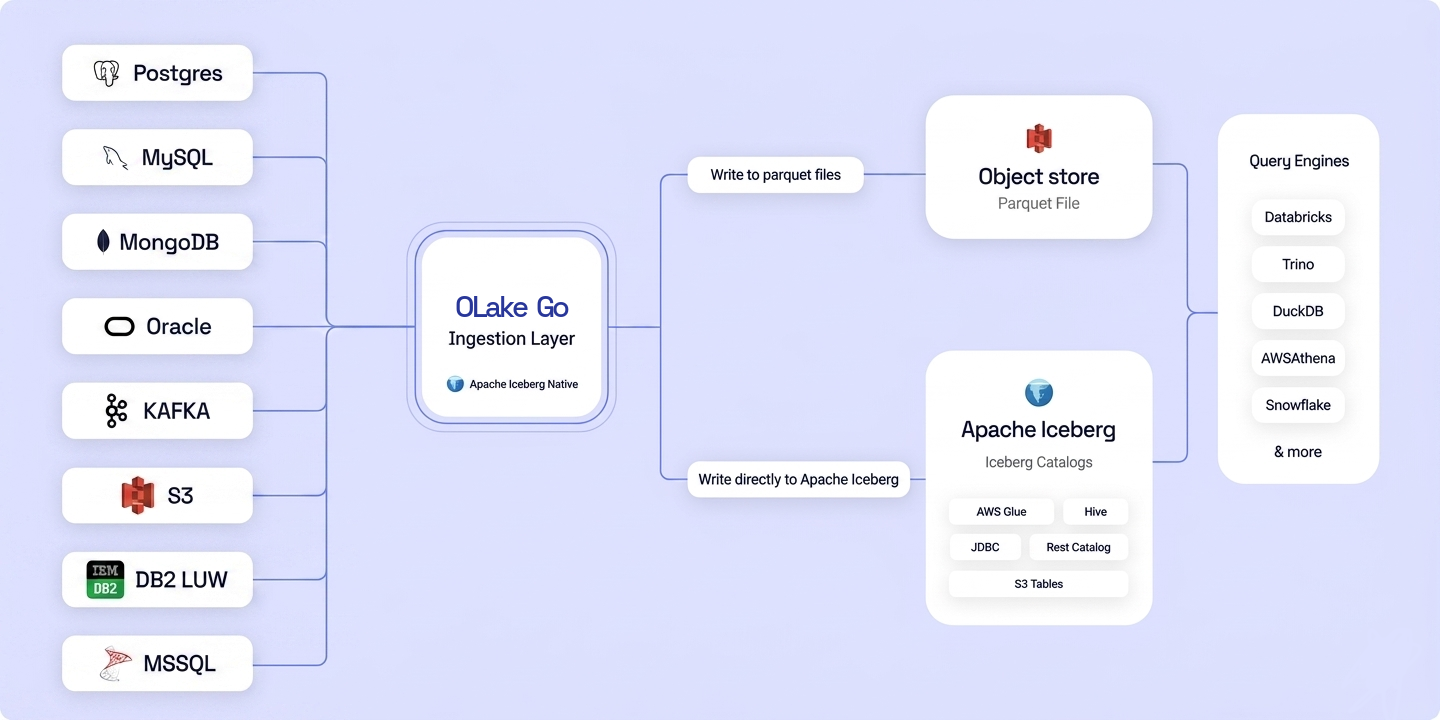
OLake Go: open-source replication from databases, Kafka and S3 to Apache Iceberg and Parquet. Sources: Postgres, MySQL, MongoDB, Oracle, MSSQL, DB2, Kafka, S3. Formerly datazip-inc/olake. Table maintenance lives in datazip-inc/olake-fusion.
🔥🔥🔥 Open source Reverse ETL - alternative to hightouch and census.
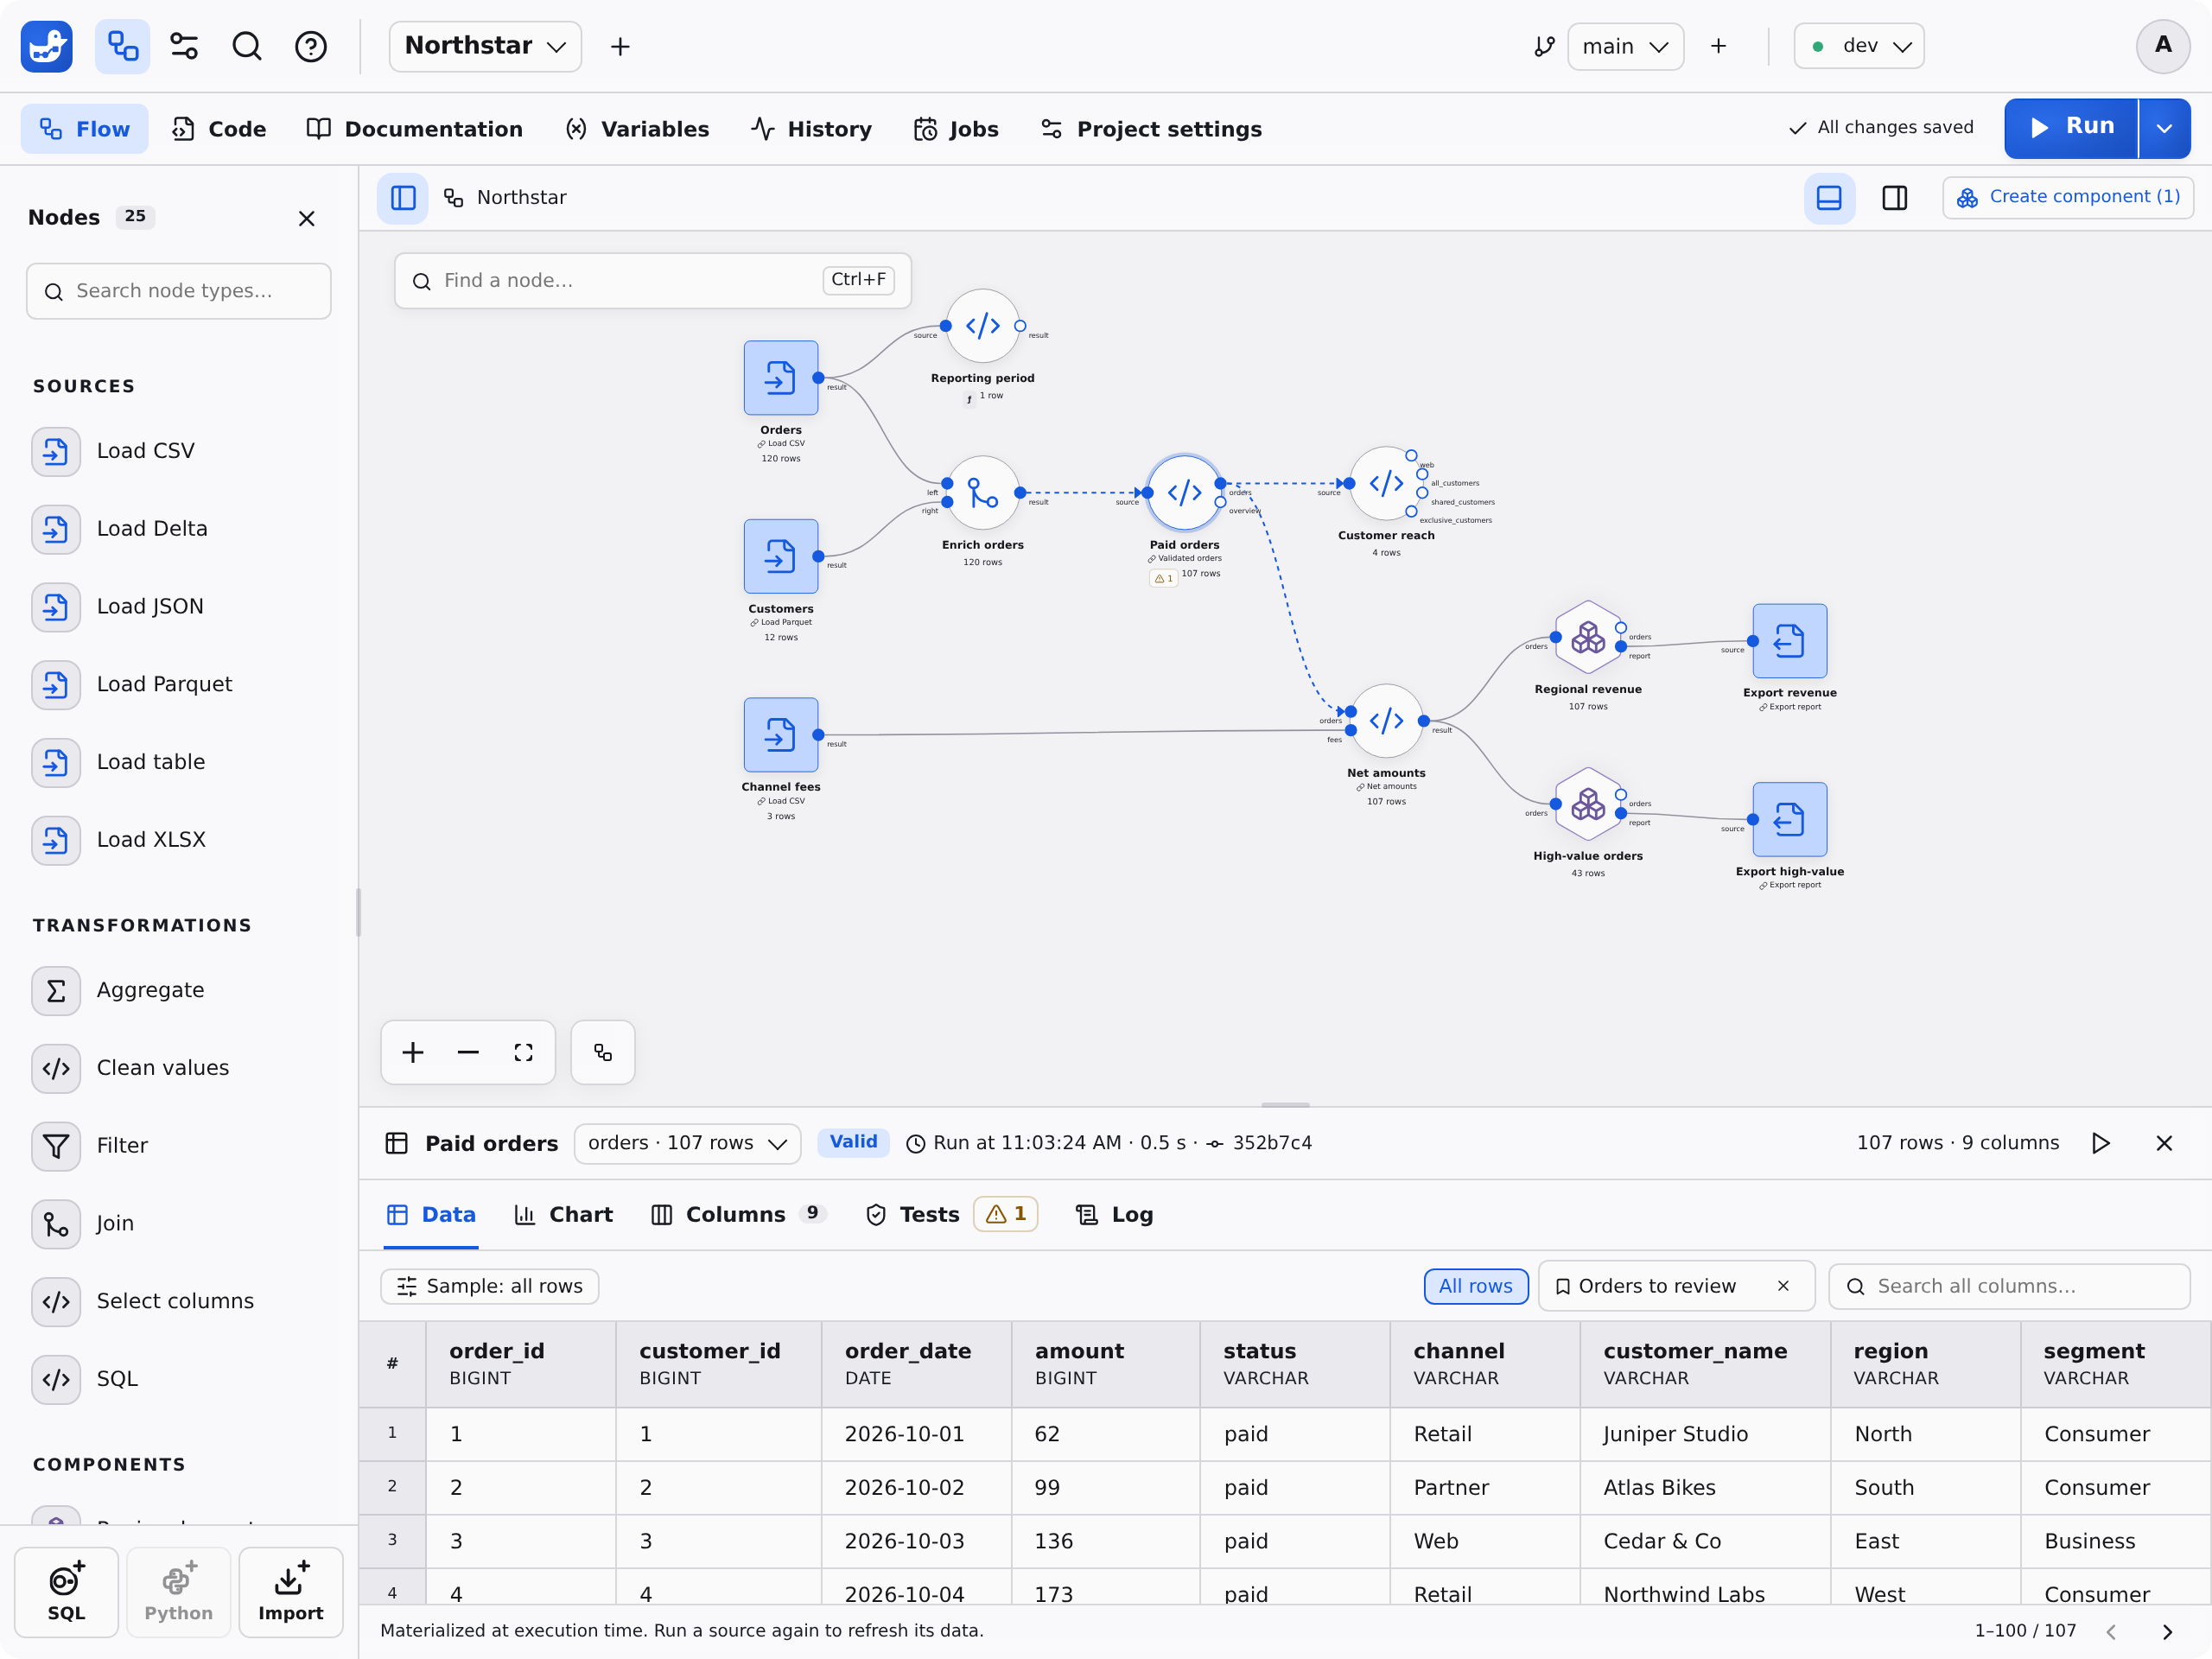
Open-source ETL/ELT you deploy on your own servers or cloud. Built on DuckDB: no-code/low-code visual pipelines or SQL, 446 components, dbt, CDC, data quality, reverse ETL, lineage, MCP for AI agents. No vendor cloud, no per-row billing.
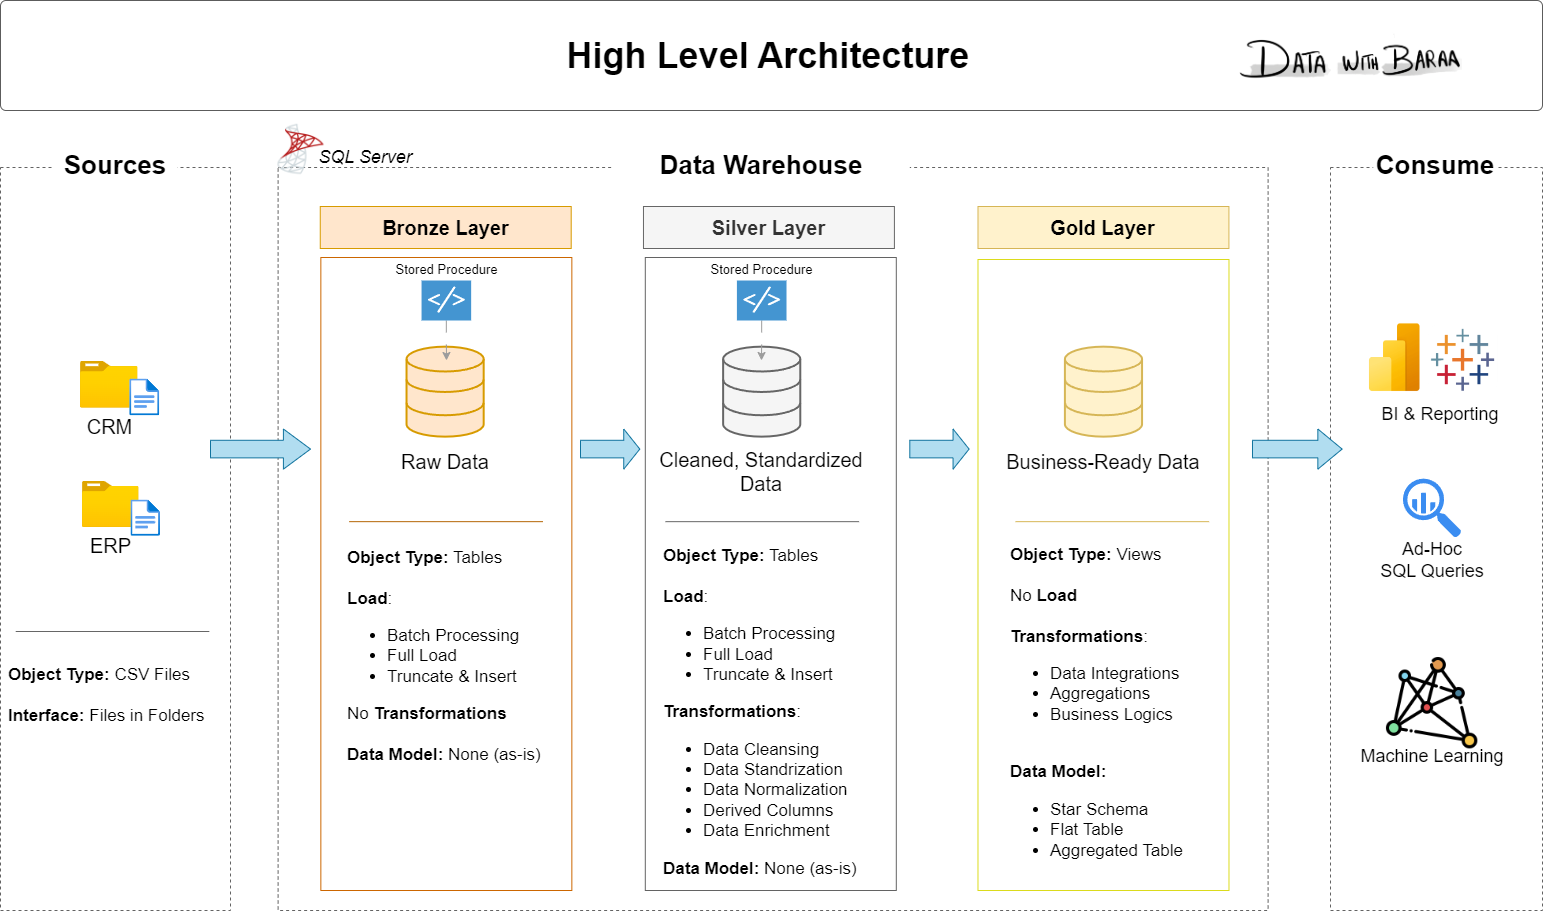
Build a data warehouse in SQL Server from two source systems, a CRM and an ERP, through bronze, silver and gold. The files and scripts of the free full project.
🌊 Continuously synchronize the systems where your data lives, to the systems where you _want_ it to live, by managing your data flows with Estuary. 🌊
Pythonic tool for orchestrating machine-learning/high performance/quantum-computing workflows in heterogeneous compute environments.
A curated list of open source tools used in analytics platforms and data engineering ecosystem
Conduit streams data between data stores. Kafka Connect replacement. No JVM required.
Augmentation pipeline for rendering synthetic paper printing, faxing, scanning and copy machine processes
Genblaze is an open source Python SDK for orchestrating generative AI media pipelines across video, audio, and image providers with built in provenance for every output.
A data lakehouse on Databricks with the medallion architecture: PySpark, Spark SQL, Delta Lake and Unity Catalog. The project of the free Databricks bootcamp.
DataMate is an enterprise-level data processing platform designed for model fine-tuning and RAG retrieval.
Pluggable data replication with checkpointing, batching, and integrity events
SDK for robotics teams to verify the quality of their data used for AI model training.