Sana
SANA & Sol: Efficient Generative Models and Full-Stack Training & Inference Engines for Image, Video, and World Modeling
- 9.9k
- Python
- Apache-2.0
- 5 d ago
SANA & Sol: Efficient Generative Models and Full-Stack Training & Inference Engines for Image, Video, and World Modeling
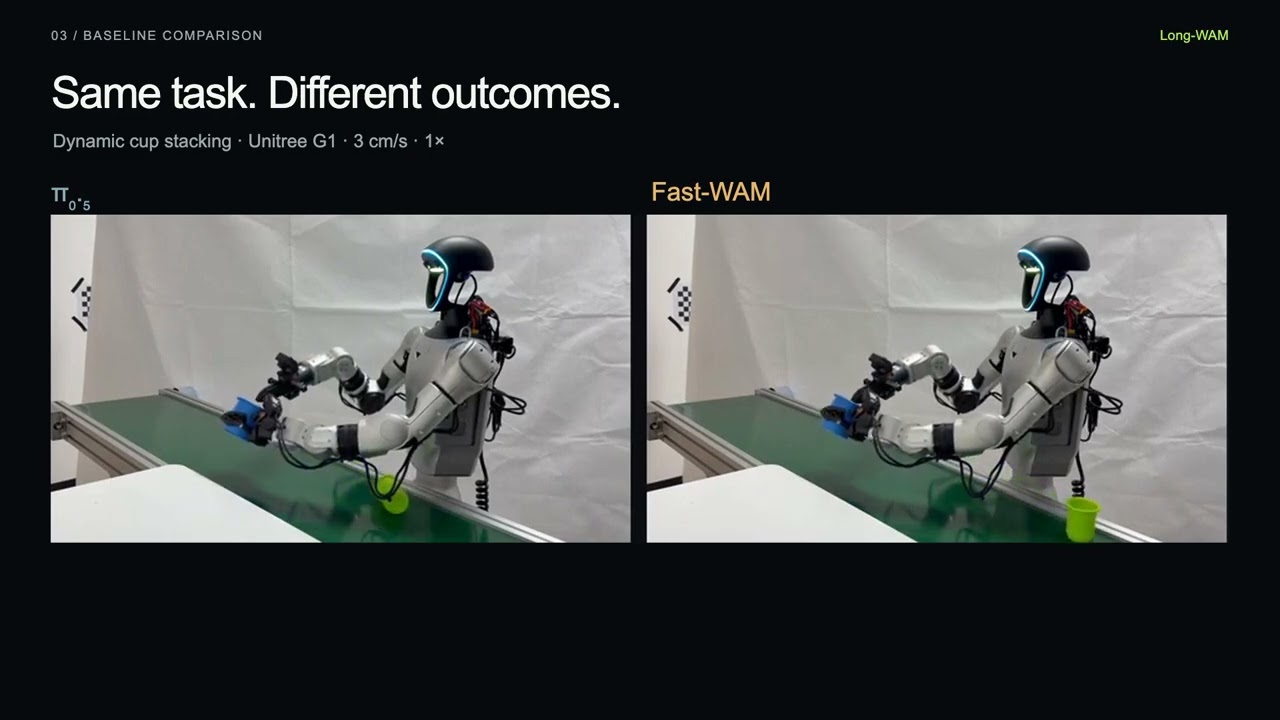
Long Video Gen / World Model / World Action Model (Embodied) Infrastructure
cuDNN Frontend is NVIDIA's modern, open-source entry point to the cuDNN library and a growing collection of high-performance open-source kernels.
Text to image model, used with diffusers.
Fully uncensored, capability-enhanced abliteration of Qwen3.6-27B. NVFP4 + z-lab DFlash speculative decoding (n=12) on the unified ghcr.io/aeon-7/aeon-vllm-ultimate:latest container, tuned for long-context draft acceptance on DGX Spark. 6 HF variants (BF16/NVFP4/MTP/MTP-XS), docker-compose, and QuickStart.
Image text to text model.
Image text to text model, used with transformers.
Gated access
Alzeo is an open-source installer that turns an NVIDIA DGX Spark, or any GB10 machine (ASUS, Dell, HP, Lenovo, MSI, GIGABYTE, Acer), into a private AI server in one command: measured model lanes, OpenAI and Anthropic APIs, and a local cockpit.
Image text to video model, used with diffusers.
Image text to text model, used with transformers.
Gated access
Strata fork: Qwen3.8-Flash-Next 125B MoE in NVFP4 on one RTX 20-50 card (12 GB+) and 64 GB of RAM or more. Setup installs our GPTQ quants (huihui abliterated, OrcaRouter) from Hugging Face. CPU experts on AVX-512 or AVX2 (+AVX-VNNI), all experts in RAM from 92 GB, a low-RAM mode below, vision, W4A8 prompts. Windows / CUDA 13.
Optimized SGLang runtime for Qwen3.8-27B FP8 with DFlash2 and Qwen3.8 Flash-Next NVFP4 with FR-Spec on one NVIDIA RTX PRO 6000 Blackwell 96 GB GPU (SM120): 524K context, HiCache and NIXL.
Bleeding-edge ComfyUI for NVIDIA DGX Spark (GB10/Blackwell/sm_121a). CUDA 13 + SageAttention v3 (sm_121a) + NVFP4 + 14 custom-node packs + Flux 2 Dev / LTX 2.3 22B / ACE-Step v1.5 XL Turbo pre-bundled with abliterated text-encoder paths.
Run large AI chat models privately on your own NVIDIA RTX 50 or RTX PRO graphics card. On one RTX 5090, Qwen3.8-27B writes about 70 words per second, 1.4x faster than vLLM. Even a model almost four times larger than the card's memory runs. Works with apps made for ChatGPT or Claude. Starts with one docker command.
Two-node DGX Spark/ASUS GX10 DeepSeek V4 Flash DSpark NVFP4 port for vLLM 0.25, with live dashboard and reproducible deployment.
TandemEngine: local inference that drafts and verifies its own tokens, behind an OpenAI-compatible API.
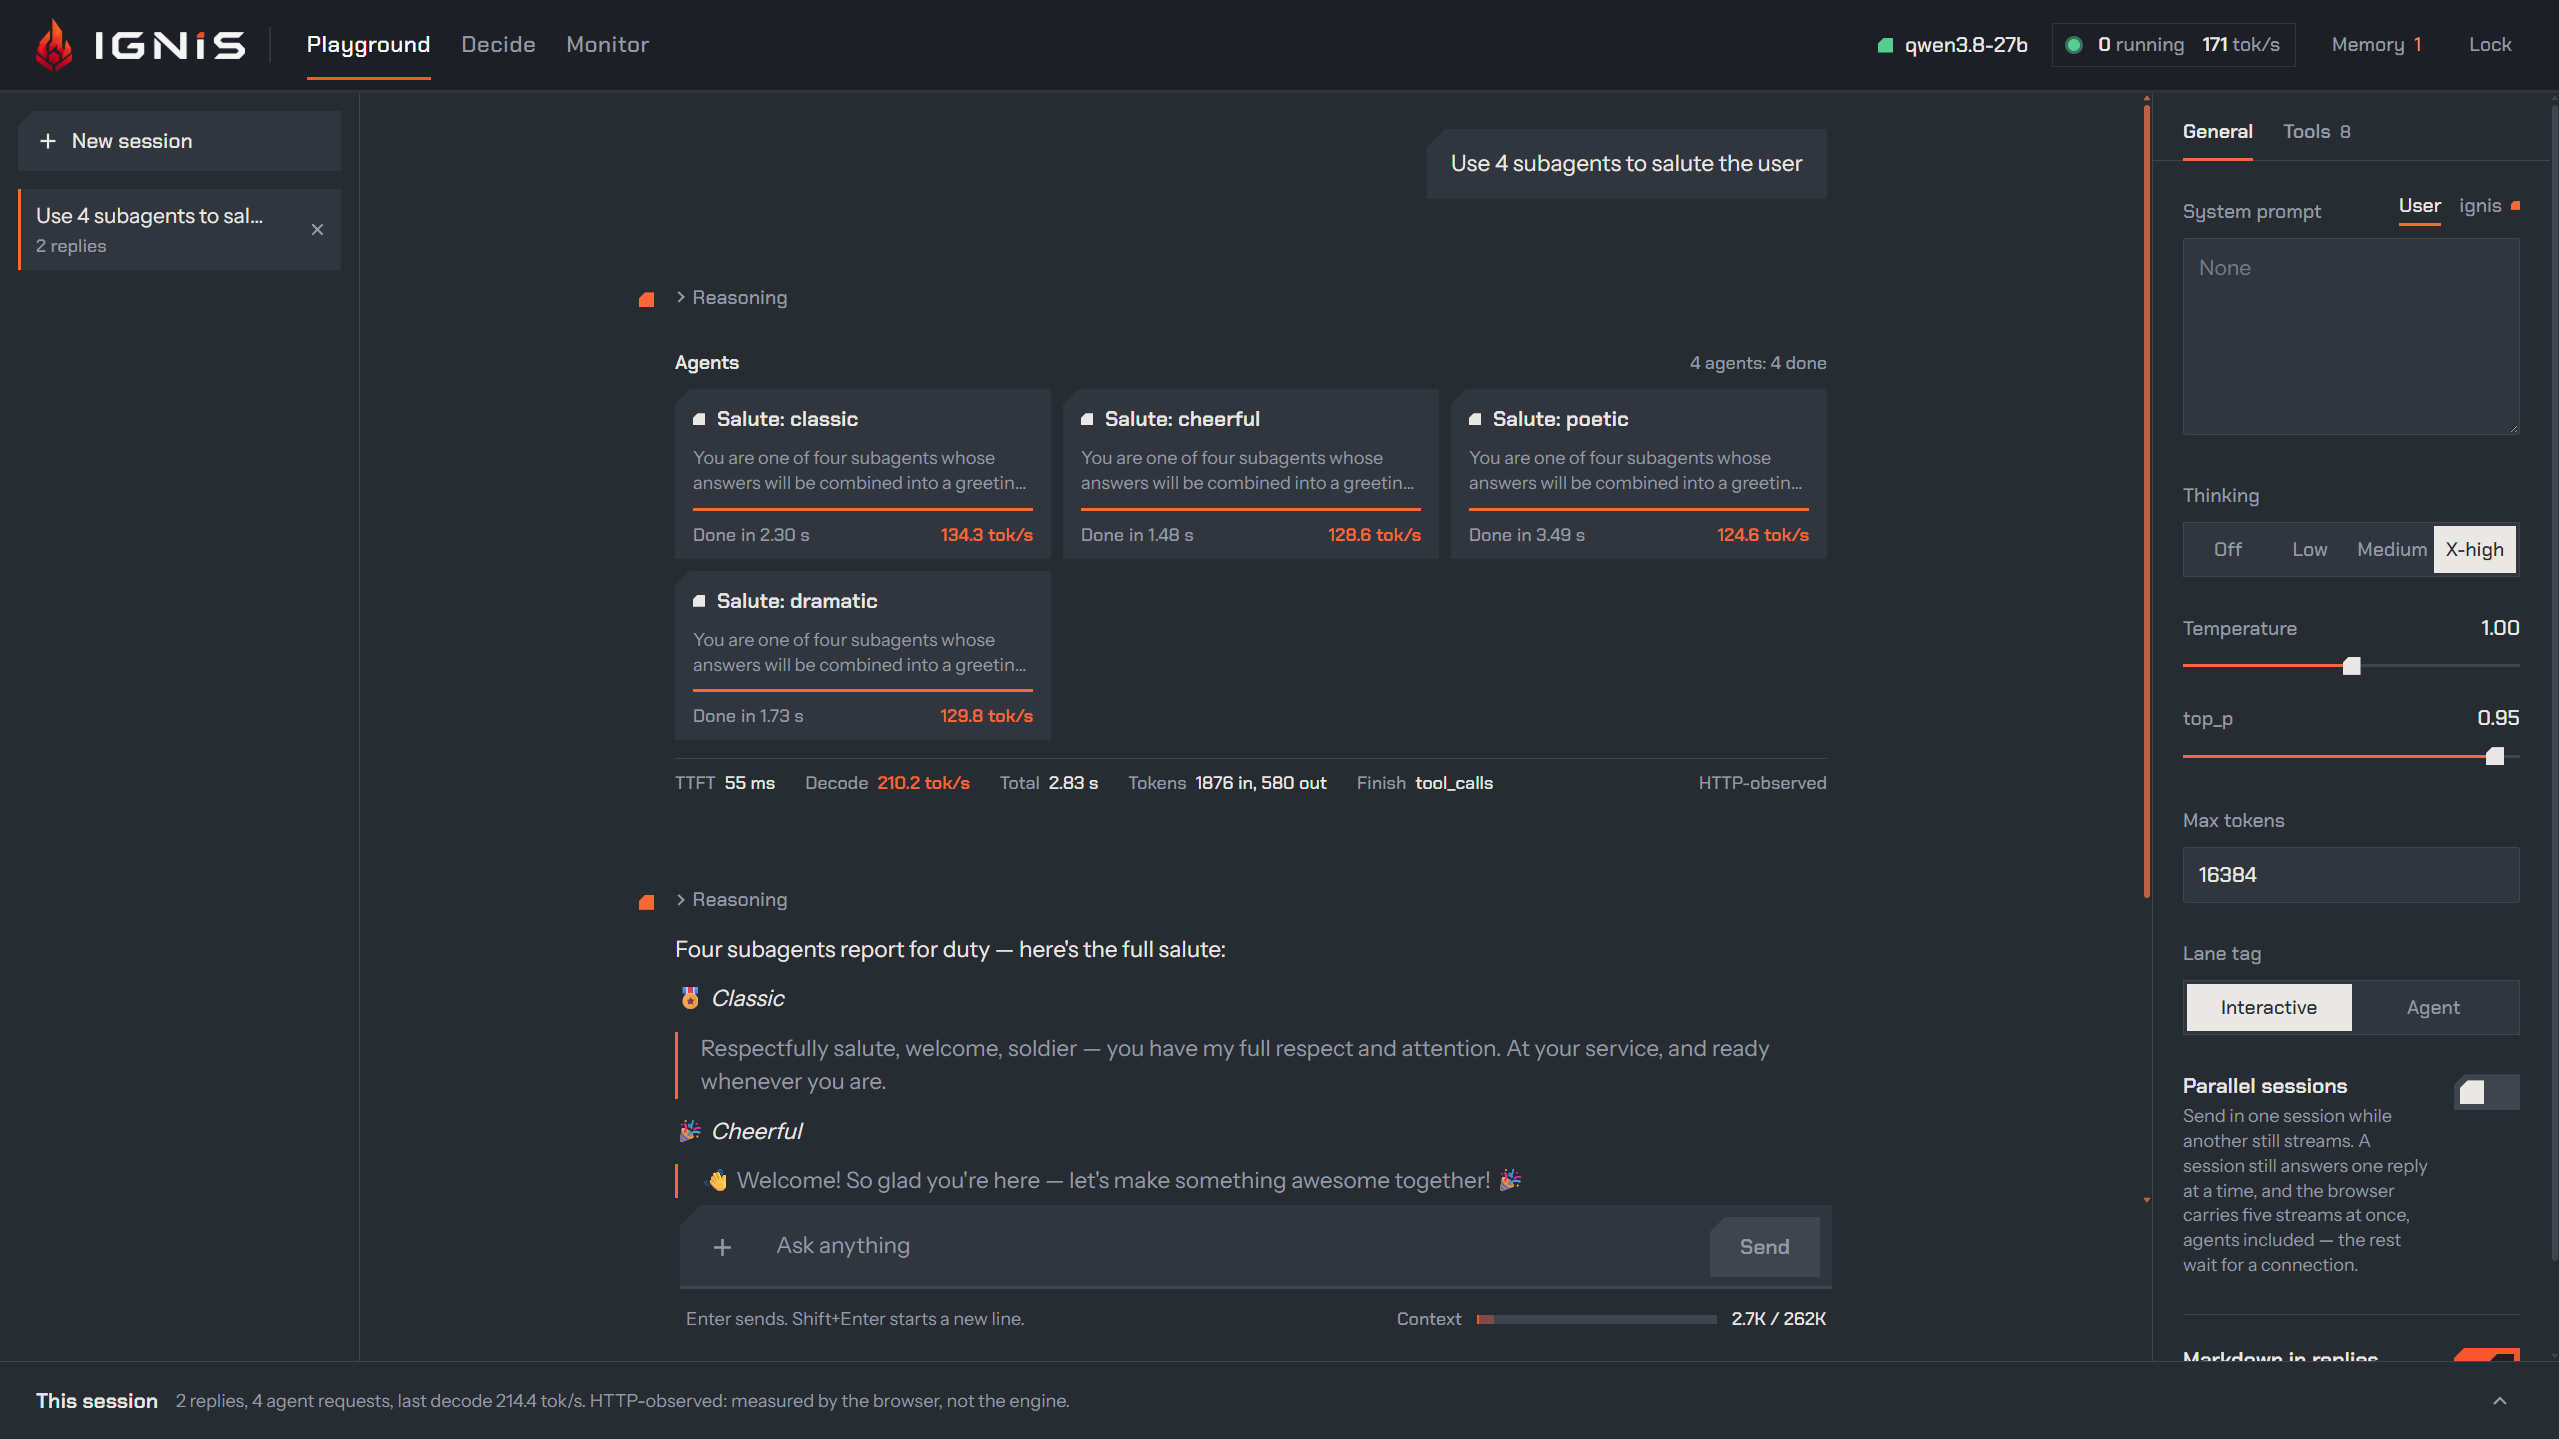
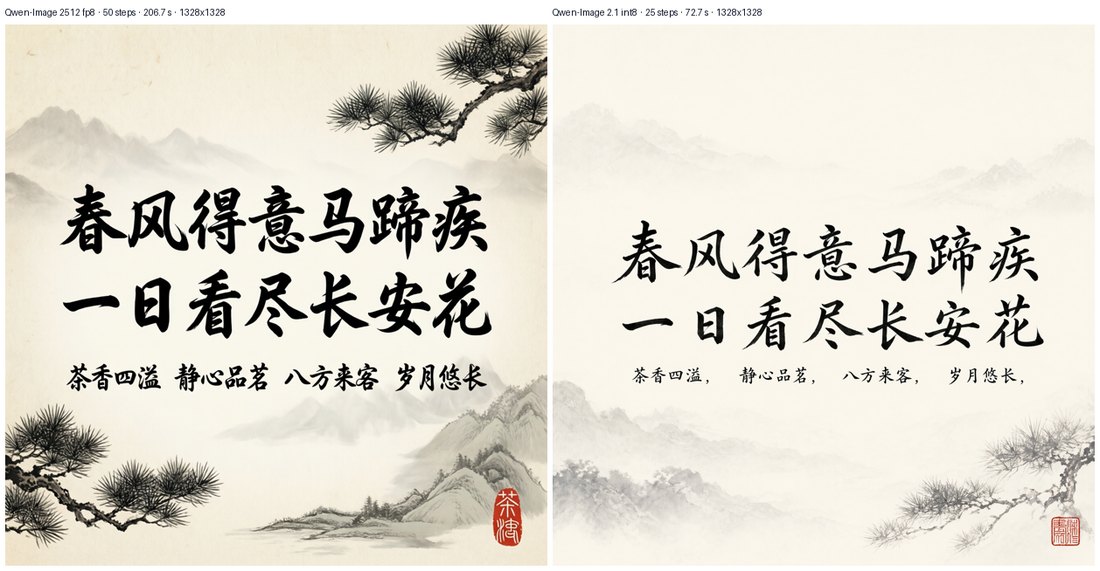
An inference engine for one NVIDIA RTX card, built for a coding agent and its subagents, and a companion that listens, reads and draws: Qwen3.8 27B and 125B Flash-Next MoE, Qwen-Image-2.1, Qwen3-ASR on the CPU. OpenAI-compatible API and Playground in one binary.
Ollama-compatible LLM server. Beats vllm by 40% on single stream decode, and by 20% on multi stream decode, and beats ollama by much 2-4x. Made possible with custom CUDA kernels, MTP, speculation and its own 3-bit builds. Uncensors models in one command. Windows and Linux, NVIDIA. Optimized to not eat up ram.
DFlash vLLM for DGX Spark — Plug & Play Block-Diffusion Speculative Decoding
Lynn 原生 LLM 推理引擎 · W4A8/NVFP4 量化 · 自写 CUDA/Triton kernel · MoE · 投机解码 | Lynn-native LLM inference engine for NVIDIA Blackwell
RTX 5090 Laptop (24GB) + ComfyUI: 12 model lines / 21 measured configs — MiniMax H3, Wan 2.2, Qwen-Image 2512, HunyuanVideo 1.5, FLUX.2 Klein, Z-Image-Turbo, LTX-Video, ACE-Step 1.5, YuE2, Stable Audio 3, Hunyuan3D 2.1, ERNIE-Image. A controlled A/B proves NVFP4 beats INT8. Bilingual 中文/English, licence-verified.
Run the AEON Bench suite on your own hardware: verified HuggingFace pull → serve → benchmark (text · agentic ×3 harnesses · vision · audio · arena · perf) → ed25519-signed attested submit.
Qwen3.8-27B on RTX 5090 Laptop 24GB — TWIN-TURBO NVFP4 (native llama.cpp) vs Coder390 Q3 LynnStyle (.ninfer + NInfer engine in WSL2/Docker): 86 tok/s decode, 262K context, C4 aggregate 228 tok/s. Every number a controlled measurement.
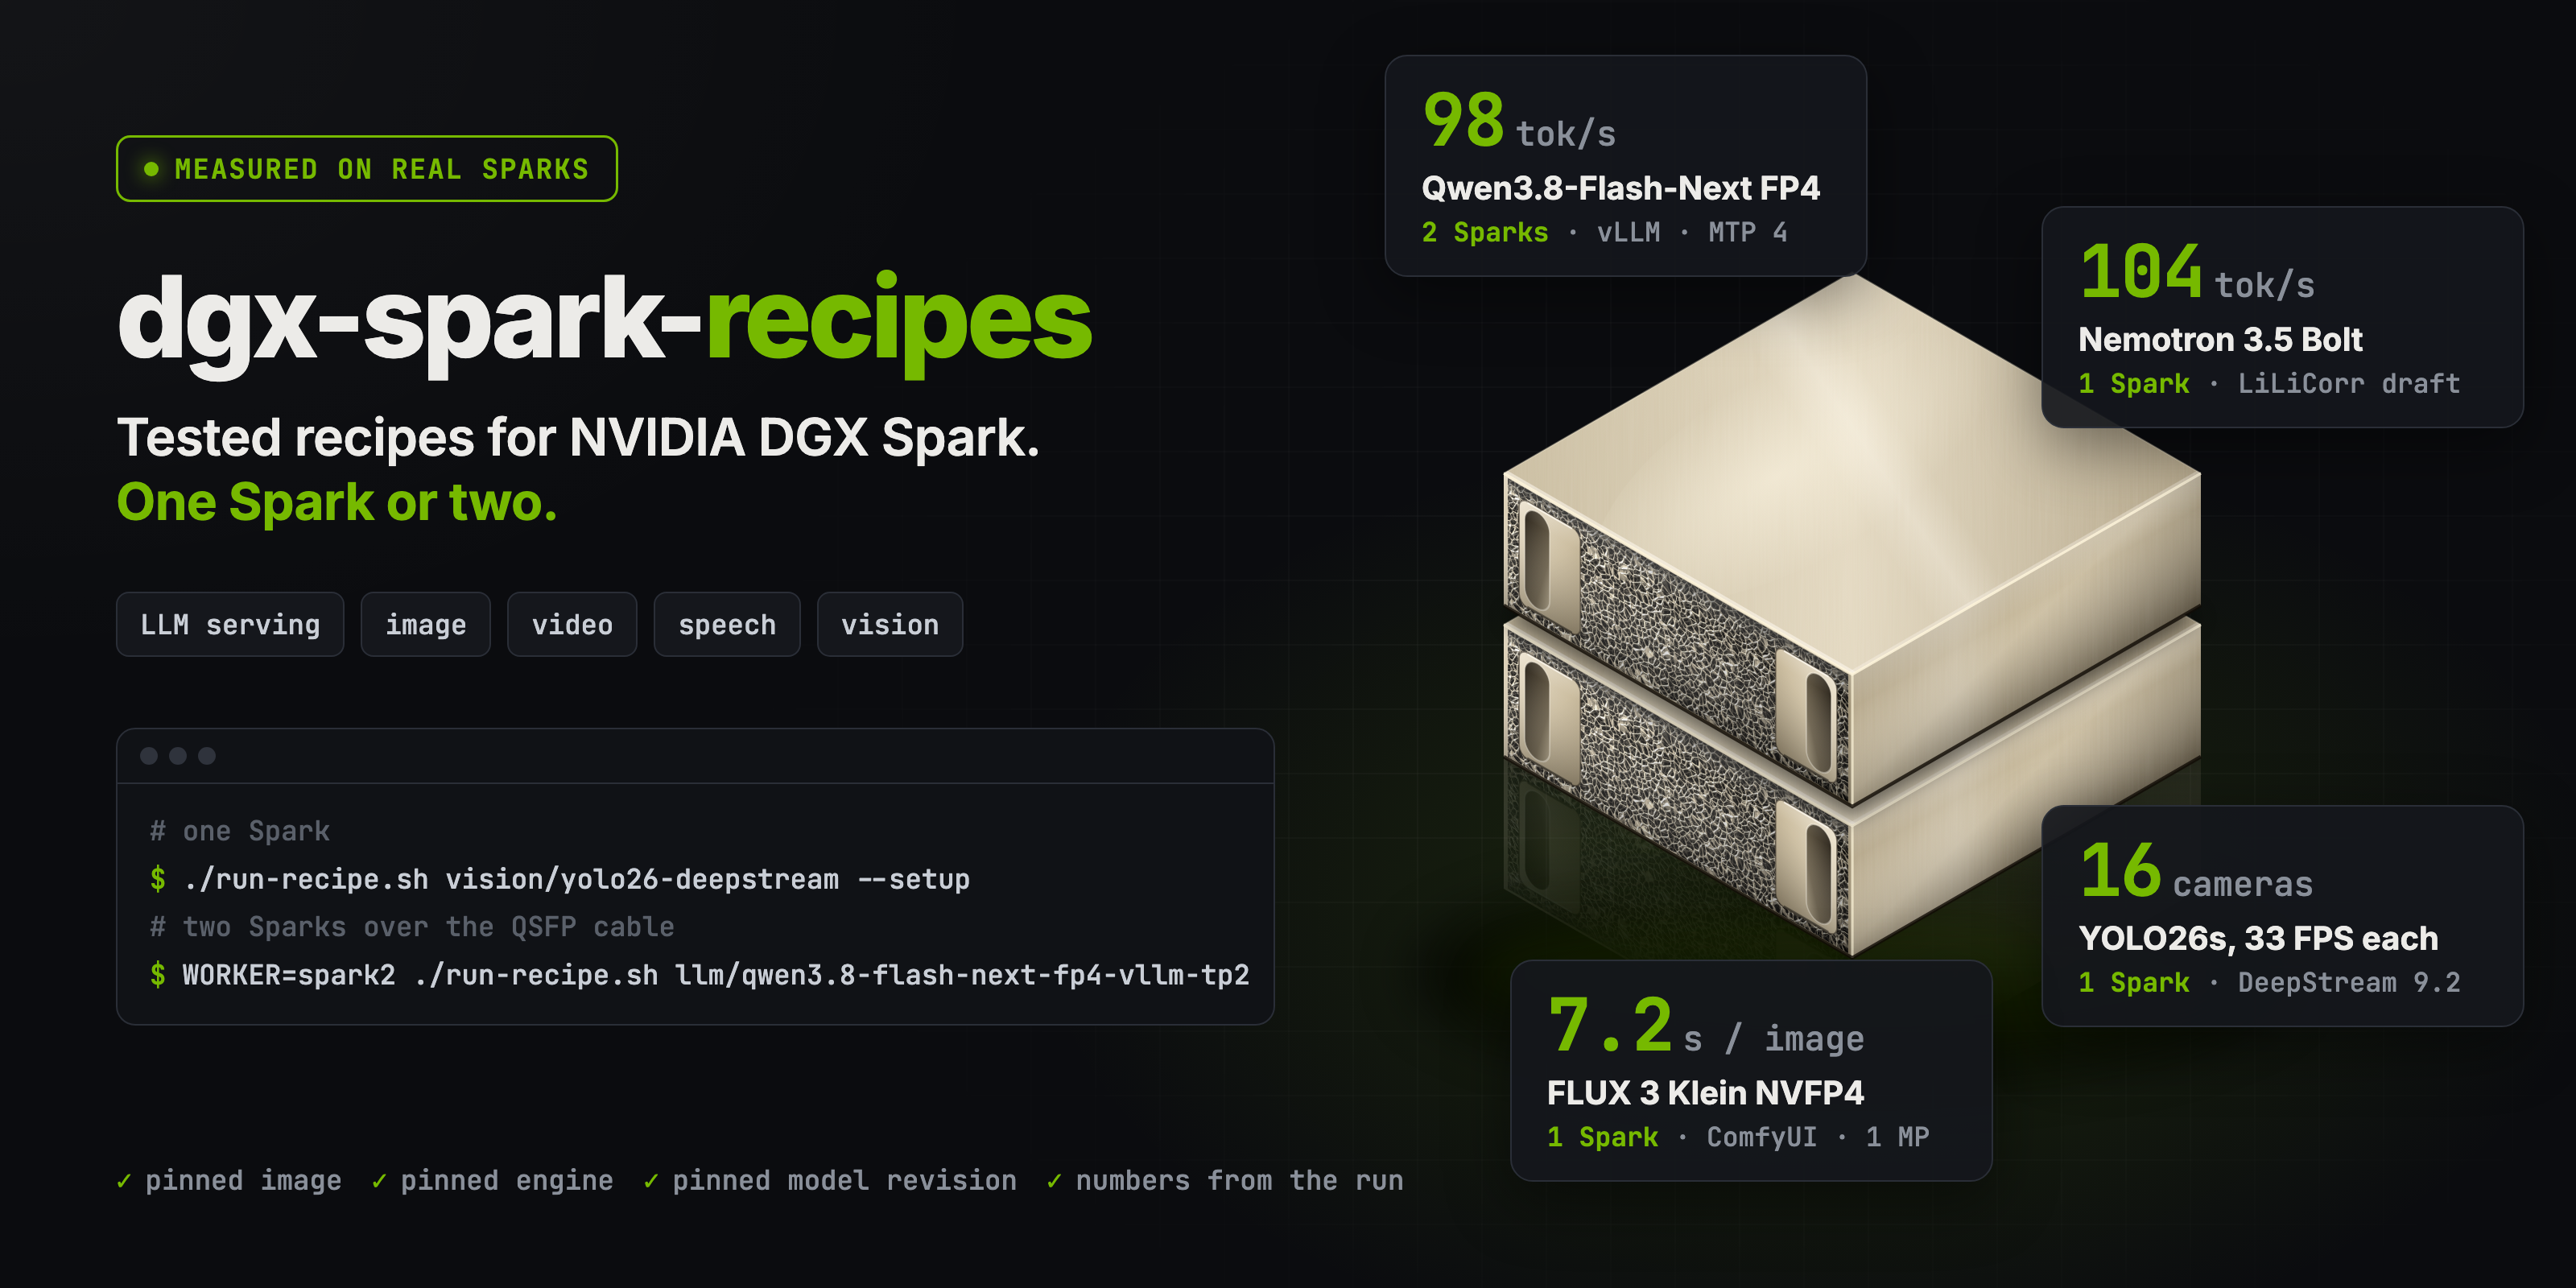
Measured recipes for the NVIDIA DGX Spark, on one or two Sparks: LLM serving, image, video and speech
LLM fine-tuning with LoRA + NVFP4/MXFP8 on NVIDIA DGX Spark (Blackwell GB10)
Reproducible recipe: serve abliterated Gemma-4-12B (gemma4_unified) at 50-118 tok/s on no-NVLink Blackwell (SM120) via vLLM nightly + ModelOpt FP8/NVFP4 + MTP spec-decode.
MiniMax H3 audio-video model on TensorFold NVFP4 kernels: a faster ComfyUI loader for one RTX 50-series GPU (2.3x stock at 20 steps, 81 s per 5 s 1344x768 video with Turbo + sparse attention on an RTX 5070 Ti)
GLM-5.2 on 4x DGX Spark with adaptive MTP K2/K4/K5, FULL CUDA graphs, DCP2, 520K context, and a downloadable ARM64 runtime image.
Lna-Lab production pipeline: GGUF -> modelopt-format NVFP4 + working MTP head for vLLM on RTX PRO 6000 Blackwell (SM120). Stages 2 (NVFP4) and 3 (MTP graft) are Lna-Lab originals; stage 1 (GGUF->bf16) reuses li-yifei/gguf-to-nvfp4.
Experimental DDTree-on-vLLM research track for Qwen3.6 AEON Ultimate on DGX Spark / GB10.
Patched vLLM container for Qwen3.5-122B-A10B NVFP4 on NVIDIA Jetson AGX Thor — qwen3_5_moe source build, RMSNormGated fix, Thor kernel selection, 18.9 tok/s single stream
Reproducible vLLM v0.30.0 build for Blackfrost's uncensored GLM-5.3-Flash on four DGX Sparks (TP4, NVFP4 attention, DFlash2)
AEON vLLM Ultimate RTX — vLLM 0.27.1 from source for RTX 5090 / Blackwell sm_120 / NVFP4. NOT for DGX Spark / GB10 / sm_121a.
EAGLE E4B speculative decoding drafter for Gemma 4 31B DECKARD HERETIC Uncensored NVFP4 — optimized for NVIDIA DGX Spark
The only deployed sparse FP4 GEMM on SM120: beats CUTLASS 80b on every shape, wins end-to-end request latency in 81 of 112 serving regimes vs dense NVFP4.
MiniMax M3 NVFP4 on 4x DGX Spark with NVIDIA DSpark, native multi-node vLLM TP=4, reasoning, and tool calling
Reproducible TP=2 deployment, container build, and experiment report for DeepSeek V4 Flash on two DGX Sparks
Guide for serving fine-tuned Qwen3.5-27B (dense, NVFP4) on DGX Spark via native vLLM. Includes critical config fixes for modelopt export_hf_checkpoint() that prevent silent FP32 dequantization.
Dual-runtime 128K agent recipe for one RTX 5090
Runs in the browser on Hugging Face