dino

dinov3-vitl16-pretrain-lvd1689m
Image feature extraction model, used with transformers.
- 2.7k
- 702k
- other
- 16 mo ago

detrex
detrex is a research platform for DETR-based object detection, segmentation, pose estimation and other visual recognition tasks.
- 2.3k
- Python
- Apache-2.0
- 15 mo ago

solo-learn
solo-learn: a library of self-supervised methods for visual representation learning powered by Pytorch Lightning
- 1.6k
- Python
- MIT
- 6 wk ago

dinov3-vitb16-pretrain-lvd1689m
Image feature extraction model, used with transformers.
Gated access
- 615
- 336k
- other
- 15 mo ago
dinov3-vits16-pretrain-lvd1689m
Image feature extraction model, used with transformers.
Gated access
- 525
- 168k
- other
- 15 mo ago

dino-vit-features
Official implementation for the paper "Deep ViT Features as Dense Visual Descriptors".
- 473
- Python
- MIT
- 4 y ago

dinov3-vit7b16-pretrain-lvd1689m
Image feature extraction model, used with transformers.
Gated access
- 333
- 7k
- other
- 15 mo ago
dinov3-vith16plus-pretrain-lvd1689m
Image feature extraction model, used with transformers.
Gated access
- 263
- 58k
- other
- 15 mo ago
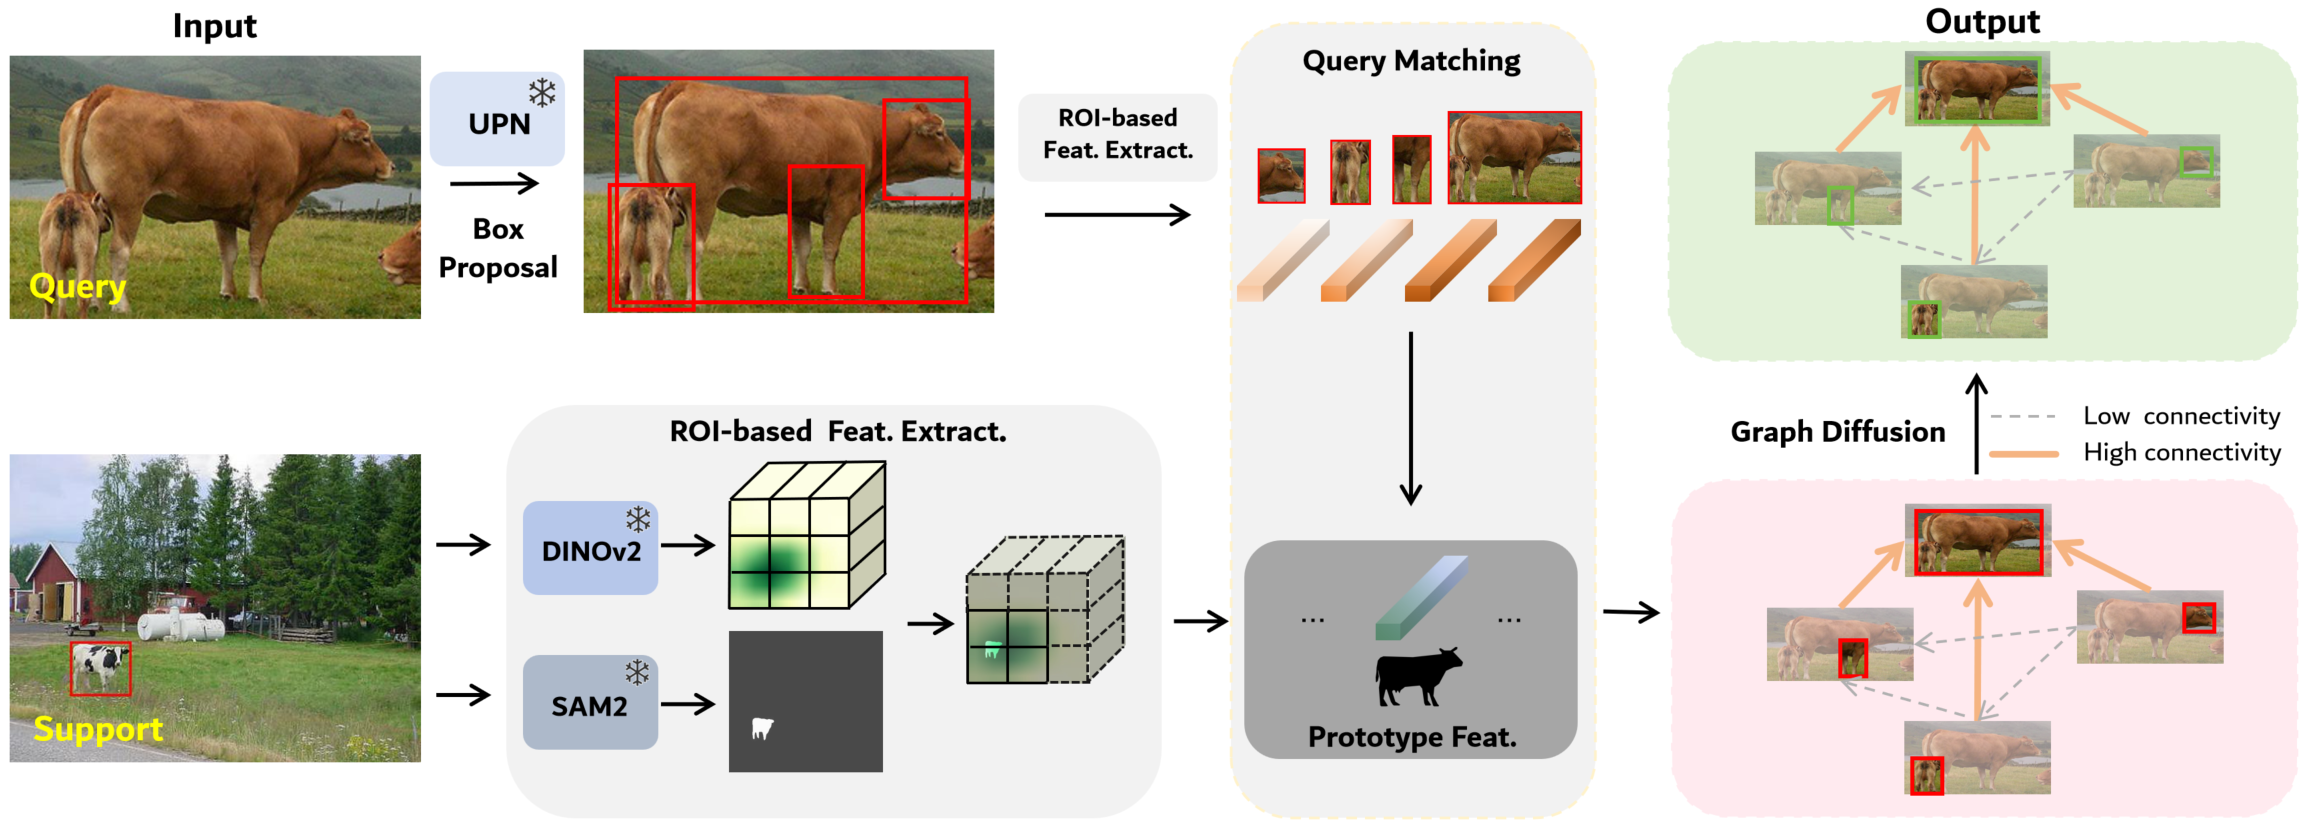
FSOD-VFM
[ICLR 2026] FSOD-VFM: Few-Shot Object Detection with Vision Foundation Models and Graph Diffusion
- 106
- Python
- Apache-2.0
- 6 mo ago

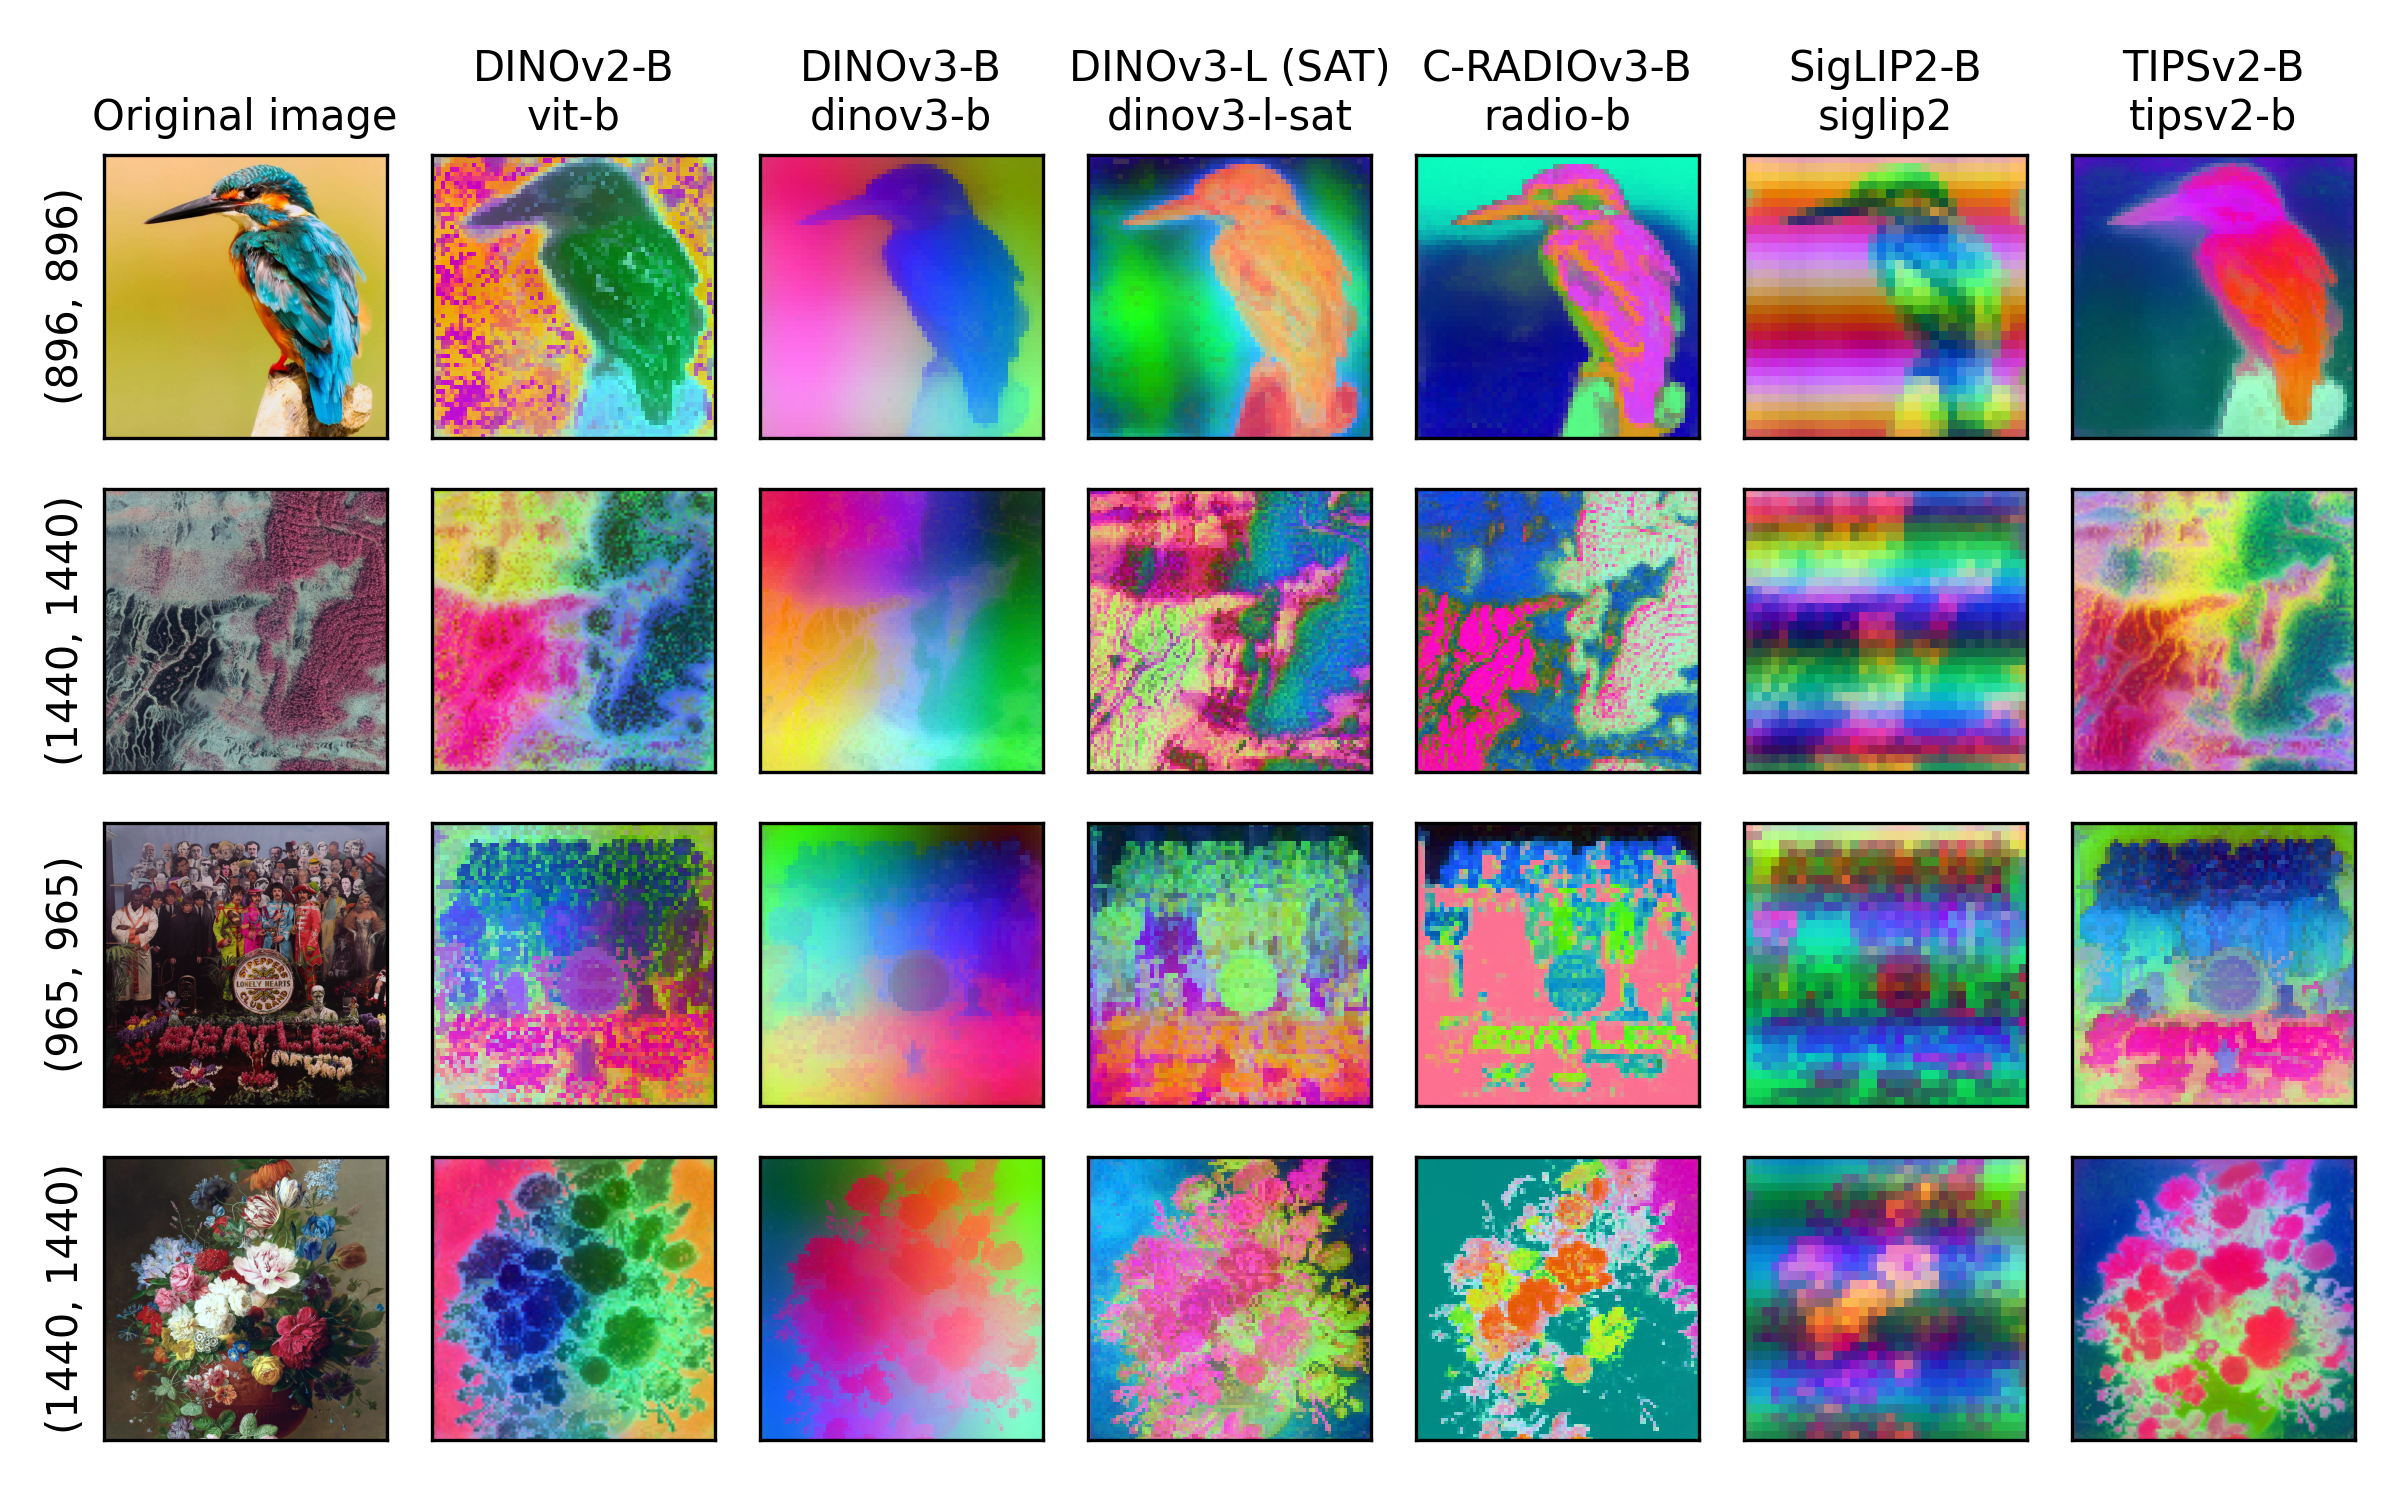
dinotool
Command-line tool for extracting DINO, CLIP, SigLIP2, TIPSv2, RADIO, features for images and videos
- 77
- Python
- Apache-2.0
- 5 mo ago


ida-pro-idb-database
many of ida pro idb database for game hacking and reverse analysis engineering.good luck.
- 36
- Python
- Apache-2.0
- 2 y ago


Vision-SSD
Easy-to-read implementation of self-supervised learning using vision transformer and knowledge distillation with no labels :smiley:
- 29
- Python
- 3 y ago

eyeBlinkedTREX
- 25
- Python
- 6 y ago

tiny-dino-vit
A from-scratch PyTorch implementation of a lightweight DINO-style self-supervised Vision Transformer, featuring multi-crop training, EMA teacher-student learning, optional RoPE positional encoding, and DINOv3-inspired Gram regularization.
- 4
- Python
- MIT
- 4 mo ago

dinov3-vitl16-pretrain-lvd1689m
Image feature extraction model, used with transformers.
- 19
- 489k
- other
- 11 mo ago
DINO-Style-Self-Supervised-Learning-from-Scratch
DINO self-supervised learning implementation and some experiments
- 1
- Jupyter Notebook
- 3 mo ago

dinov3-vits16-pretrain-lvd1689m
Image feature extraction model, used with transformers.
- 0
- 71
- other
- 7 wk ago
dinov3-vits16-pretrain-lvd1689m
Image feature extraction model, used with transformers.
- 0
- 315
- other
- 3 mo ago
Single Image DINO Patch Matcher and Cutout
Single-image DINOv3 co-segmentation by click
Runs in the browser on Hugging Face
- 0
- apache-2.0
- 7 mo ago