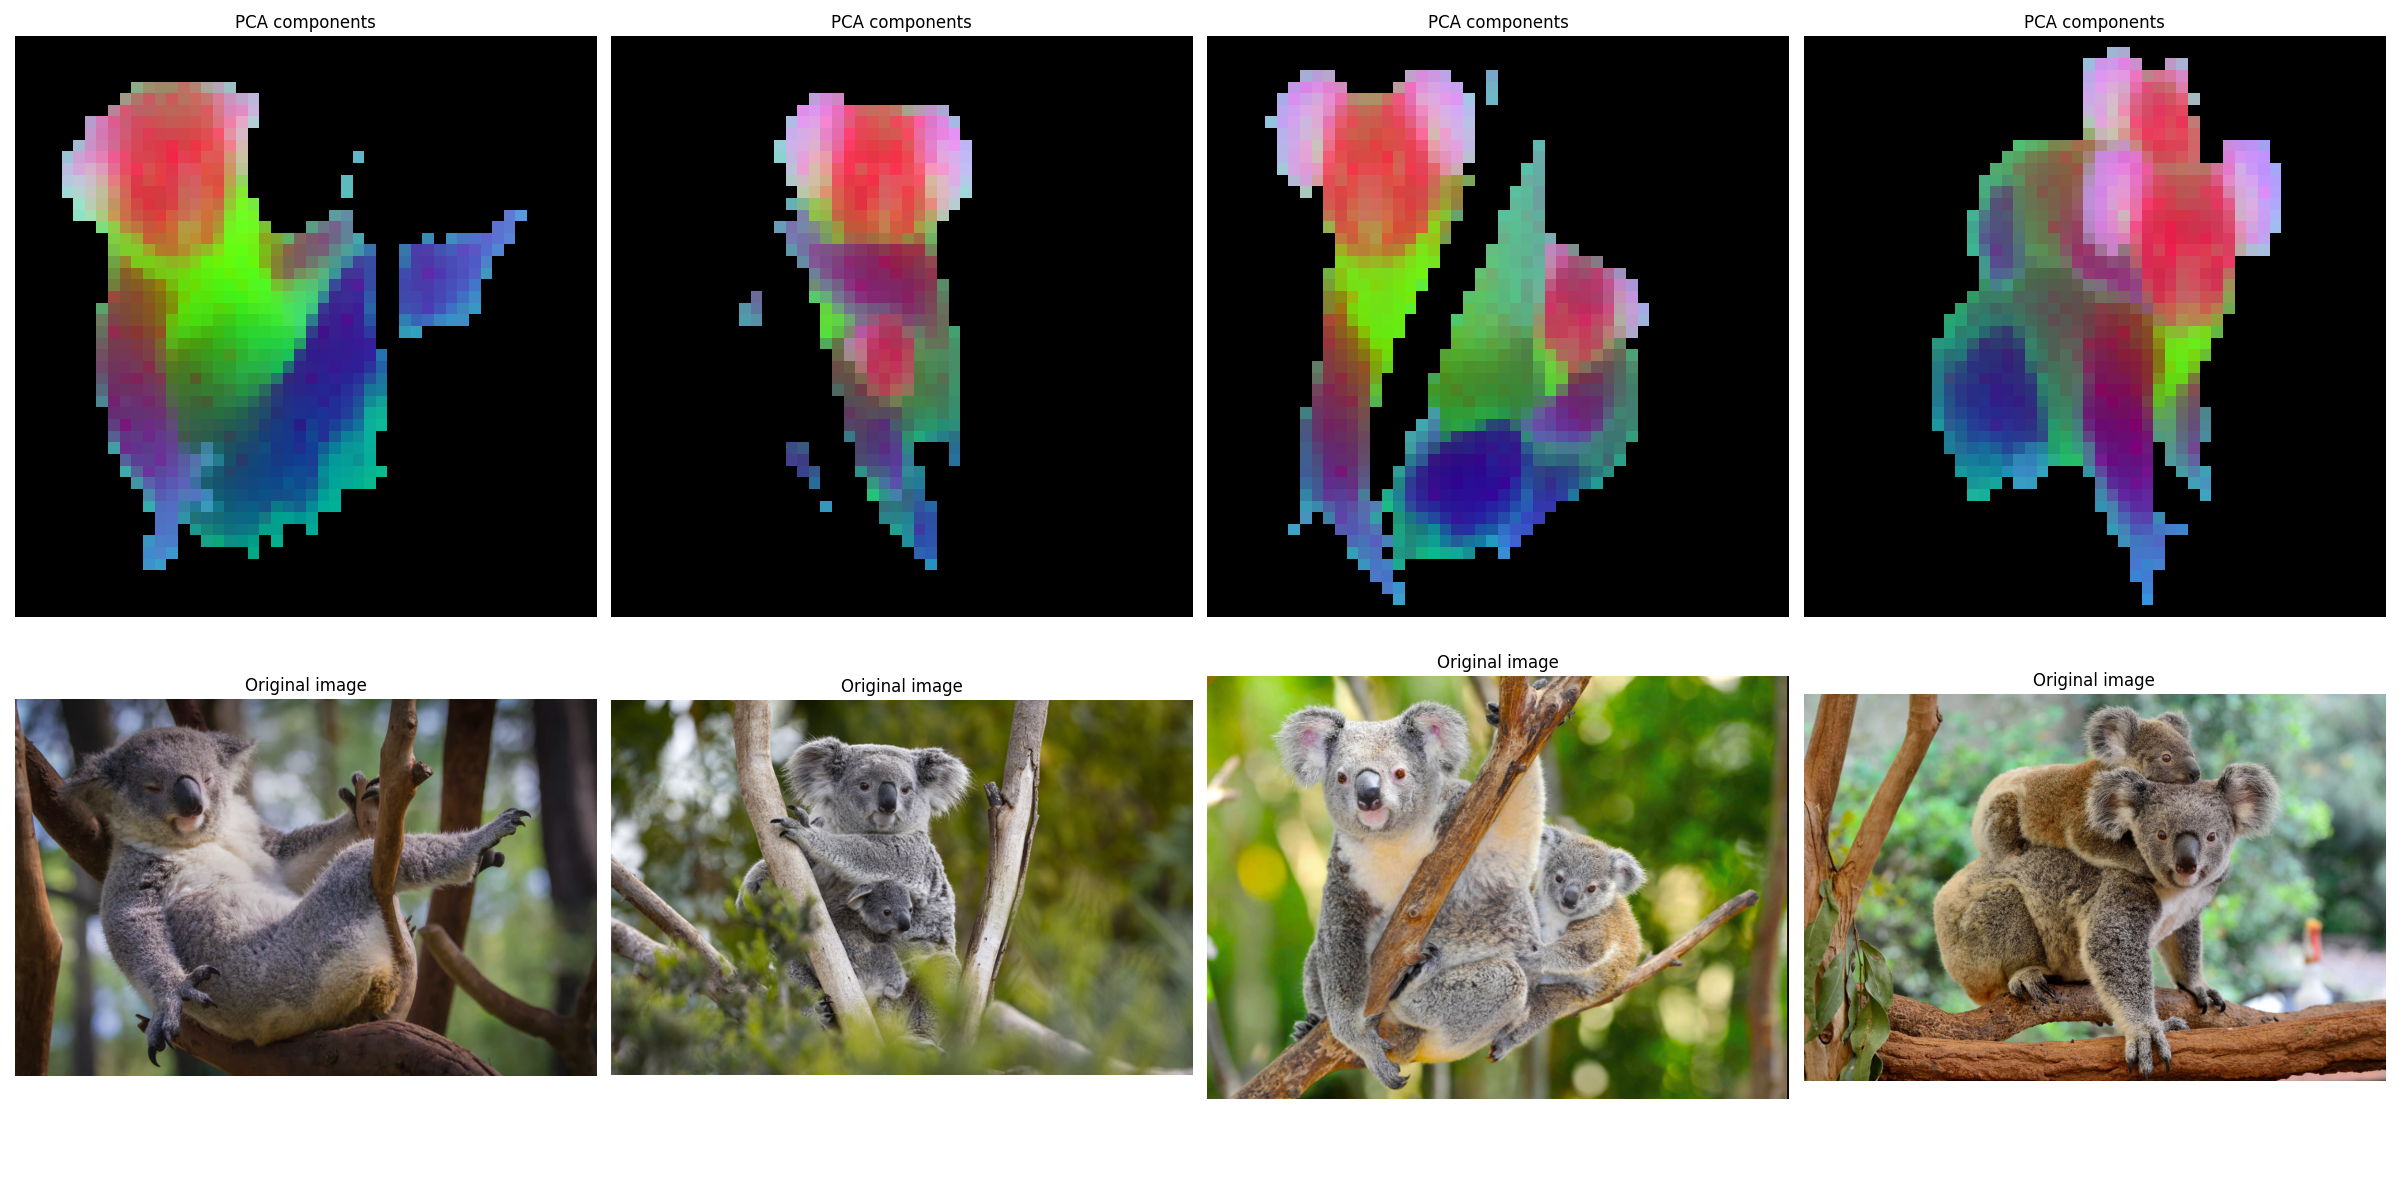
lightly-train
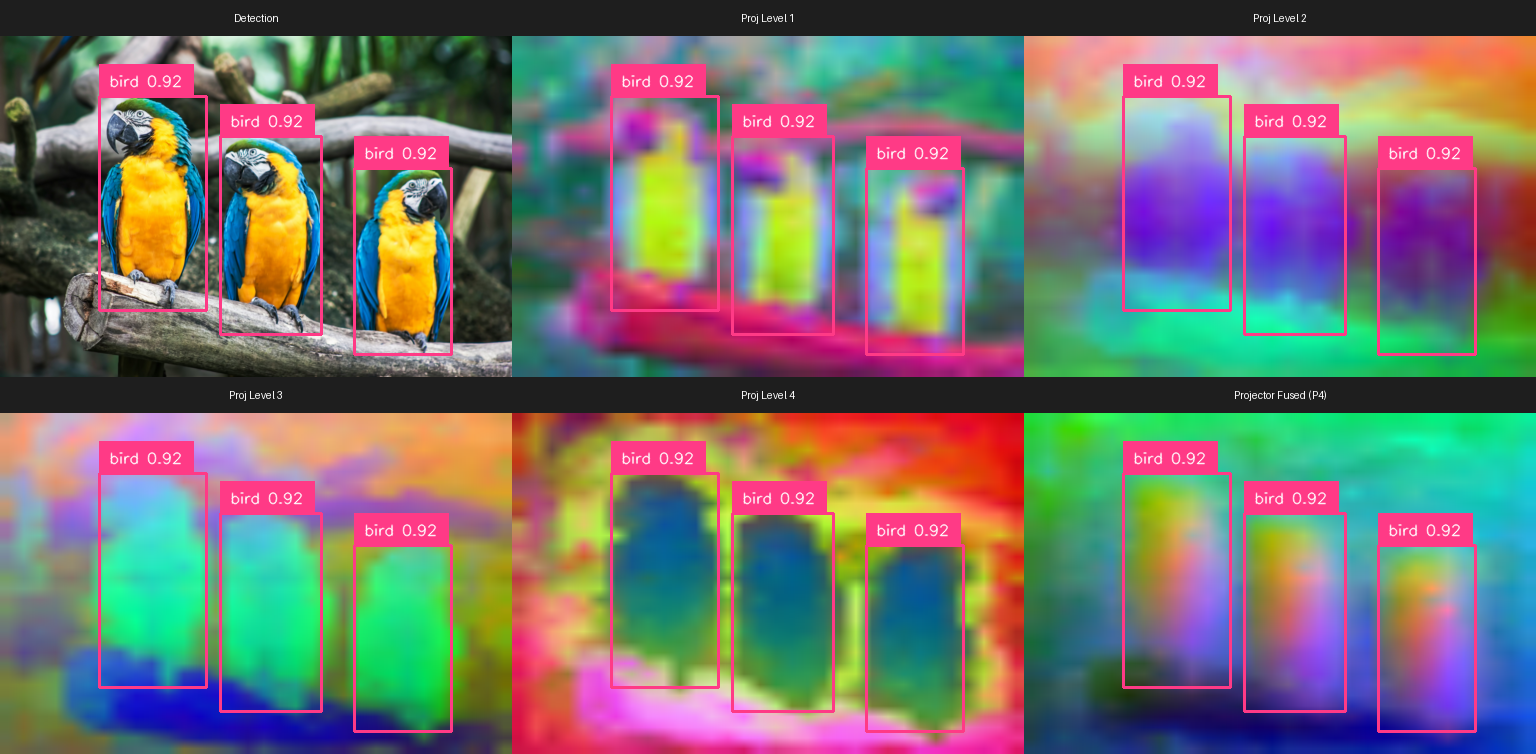
All-in-one training for vision models (YOLO, ViTs, RT-DETR, DINOv3): pretraining, fine-tuning, distillation.
- 1.7k
- Python
- AGPL-3.0
- 10 d ago
All-in-one training for vision models (YOLO, ViTs, RT-DETR, DINOv3): pretraining, fine-tuning, distillation.
Testing adaptation of the DINOv2/3 encoders for vision tasks with Low-Rank Adaptation (LoRA)
Unofficial implementation of the paper "The Chosen One: Consistent Characters in Text-to-Image Diffusion Models"
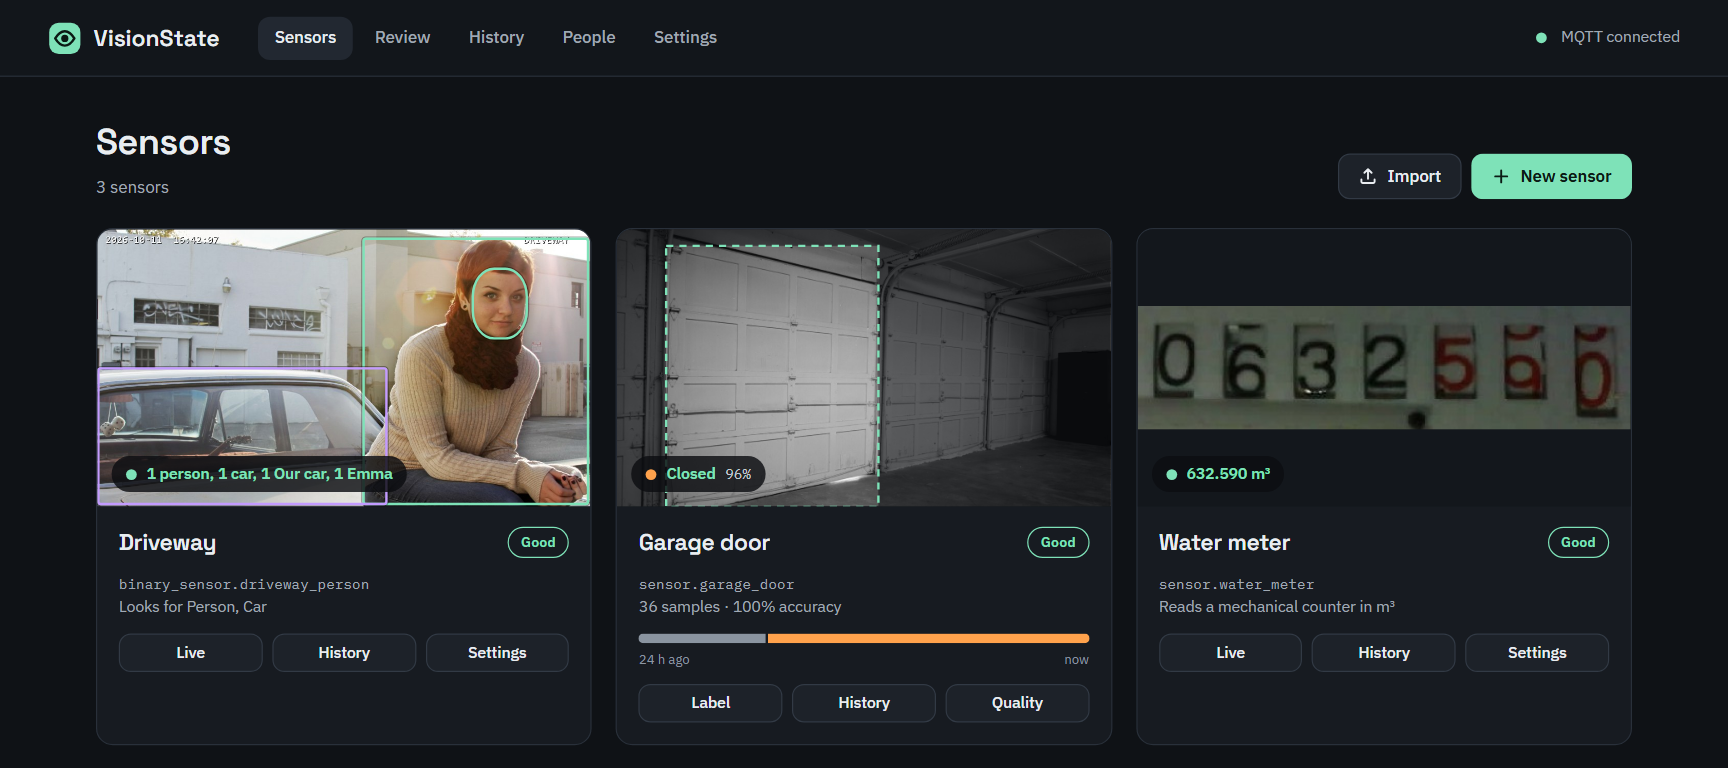
Turn your cameras into Home Assistant sensors with a local AI: garage door open/closed, people and cars, water, gas and power meters read by any camera or ESP32-CAM. 100% local, any CPU.
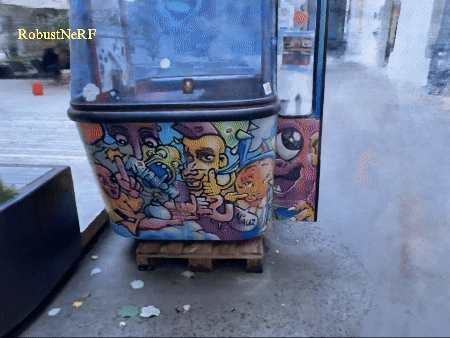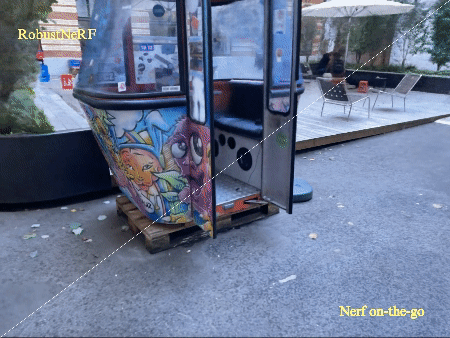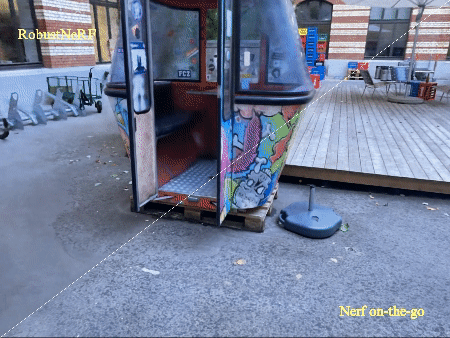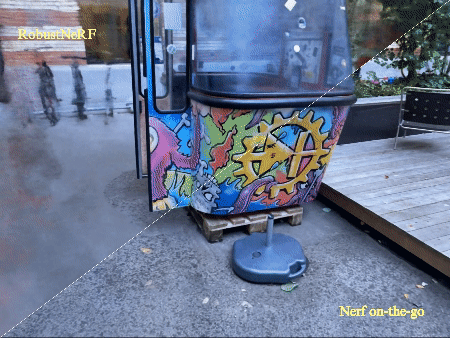
[CVPR'24] NeRF On-the-go: Exploiting Uncertainty for Distractor-free NeRFs in the Wild
Multi-modal AI-generated content detection: image, video, and audio. Benchmarks, training code (DINOv2, DINOv3, ReStraV, BreathNet), and evaluation pipeline for real vs. synthetic classification with calibration-aware metrics.
Unsupervised image clustering with modern deep embeddings (ConvNeXt, DINOv2, CLIP, faces) + K-Means. Sort a folder of images into clusters with one Python call or CLI.
Vision Foundation Models: SAM, ViT, CLIP, DINOv2, object detection, segmentation, and multimodal AI for computer vision.
Image feature extraction model, used with transformers.
Visualize what RF-DETR's backbone sees during inference.
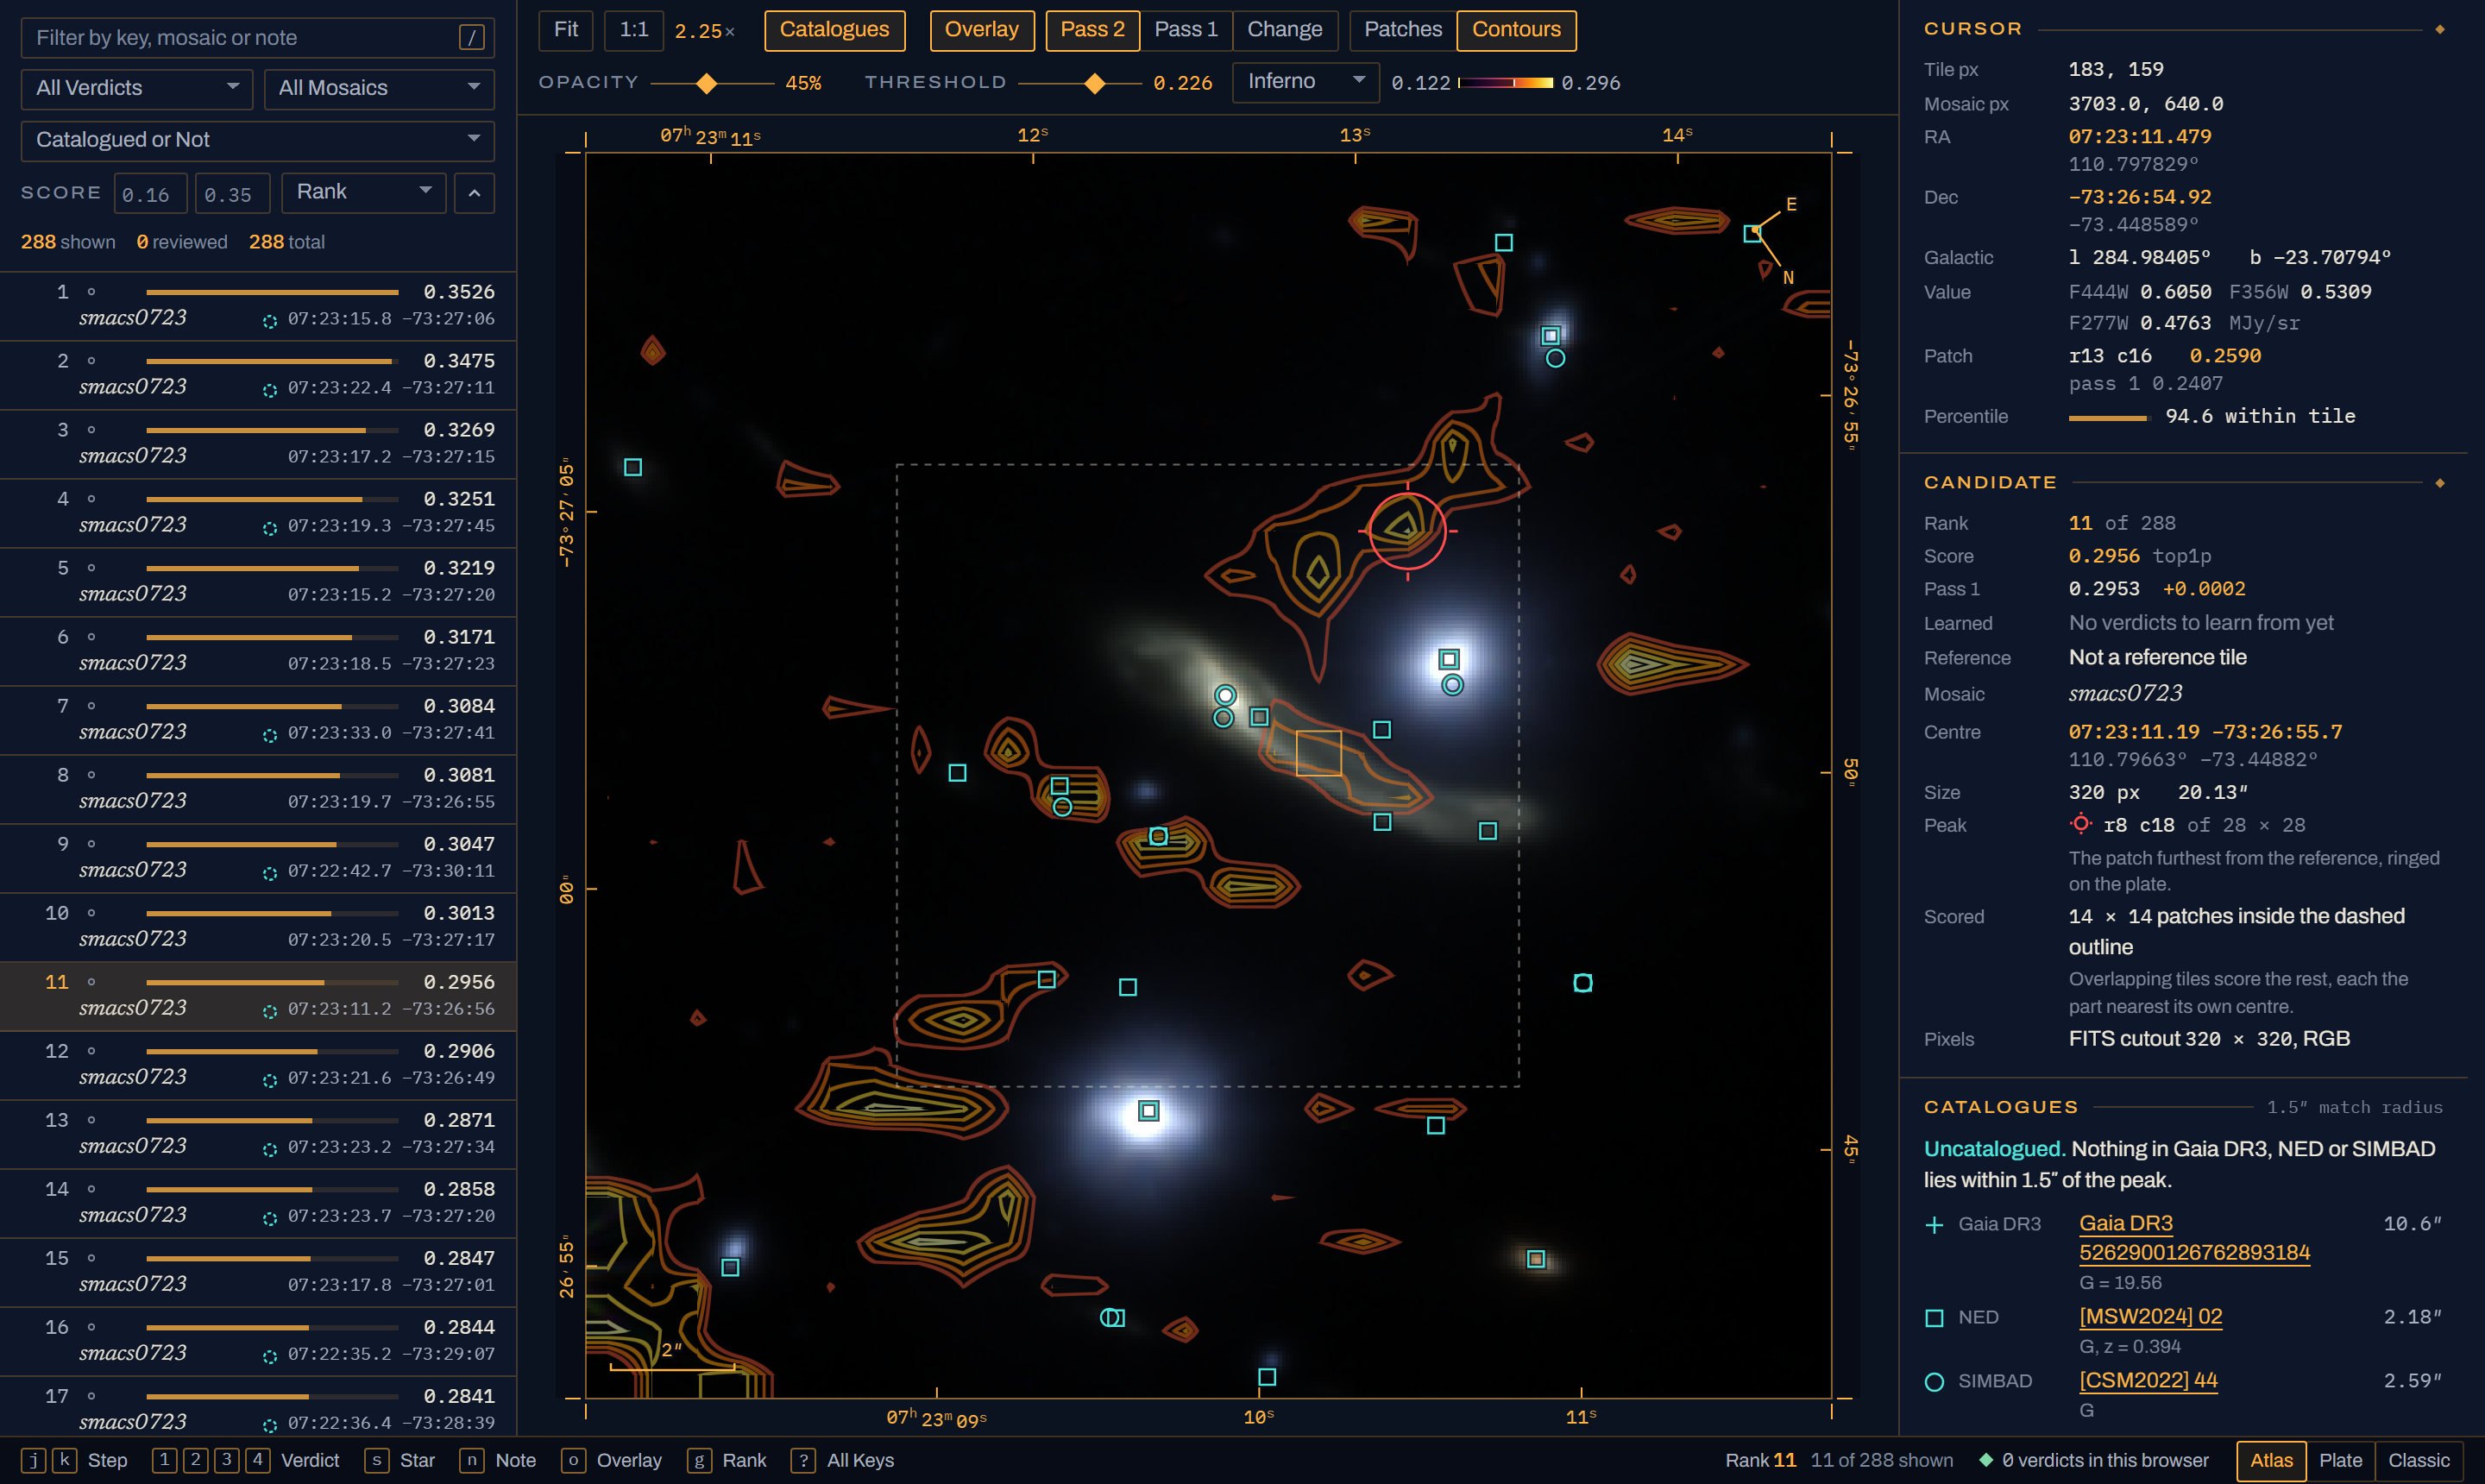
Unsupervised anomaly detection for James Webb Space Telescope images, with DINOv3 features and a web viewer for the ranked tiles
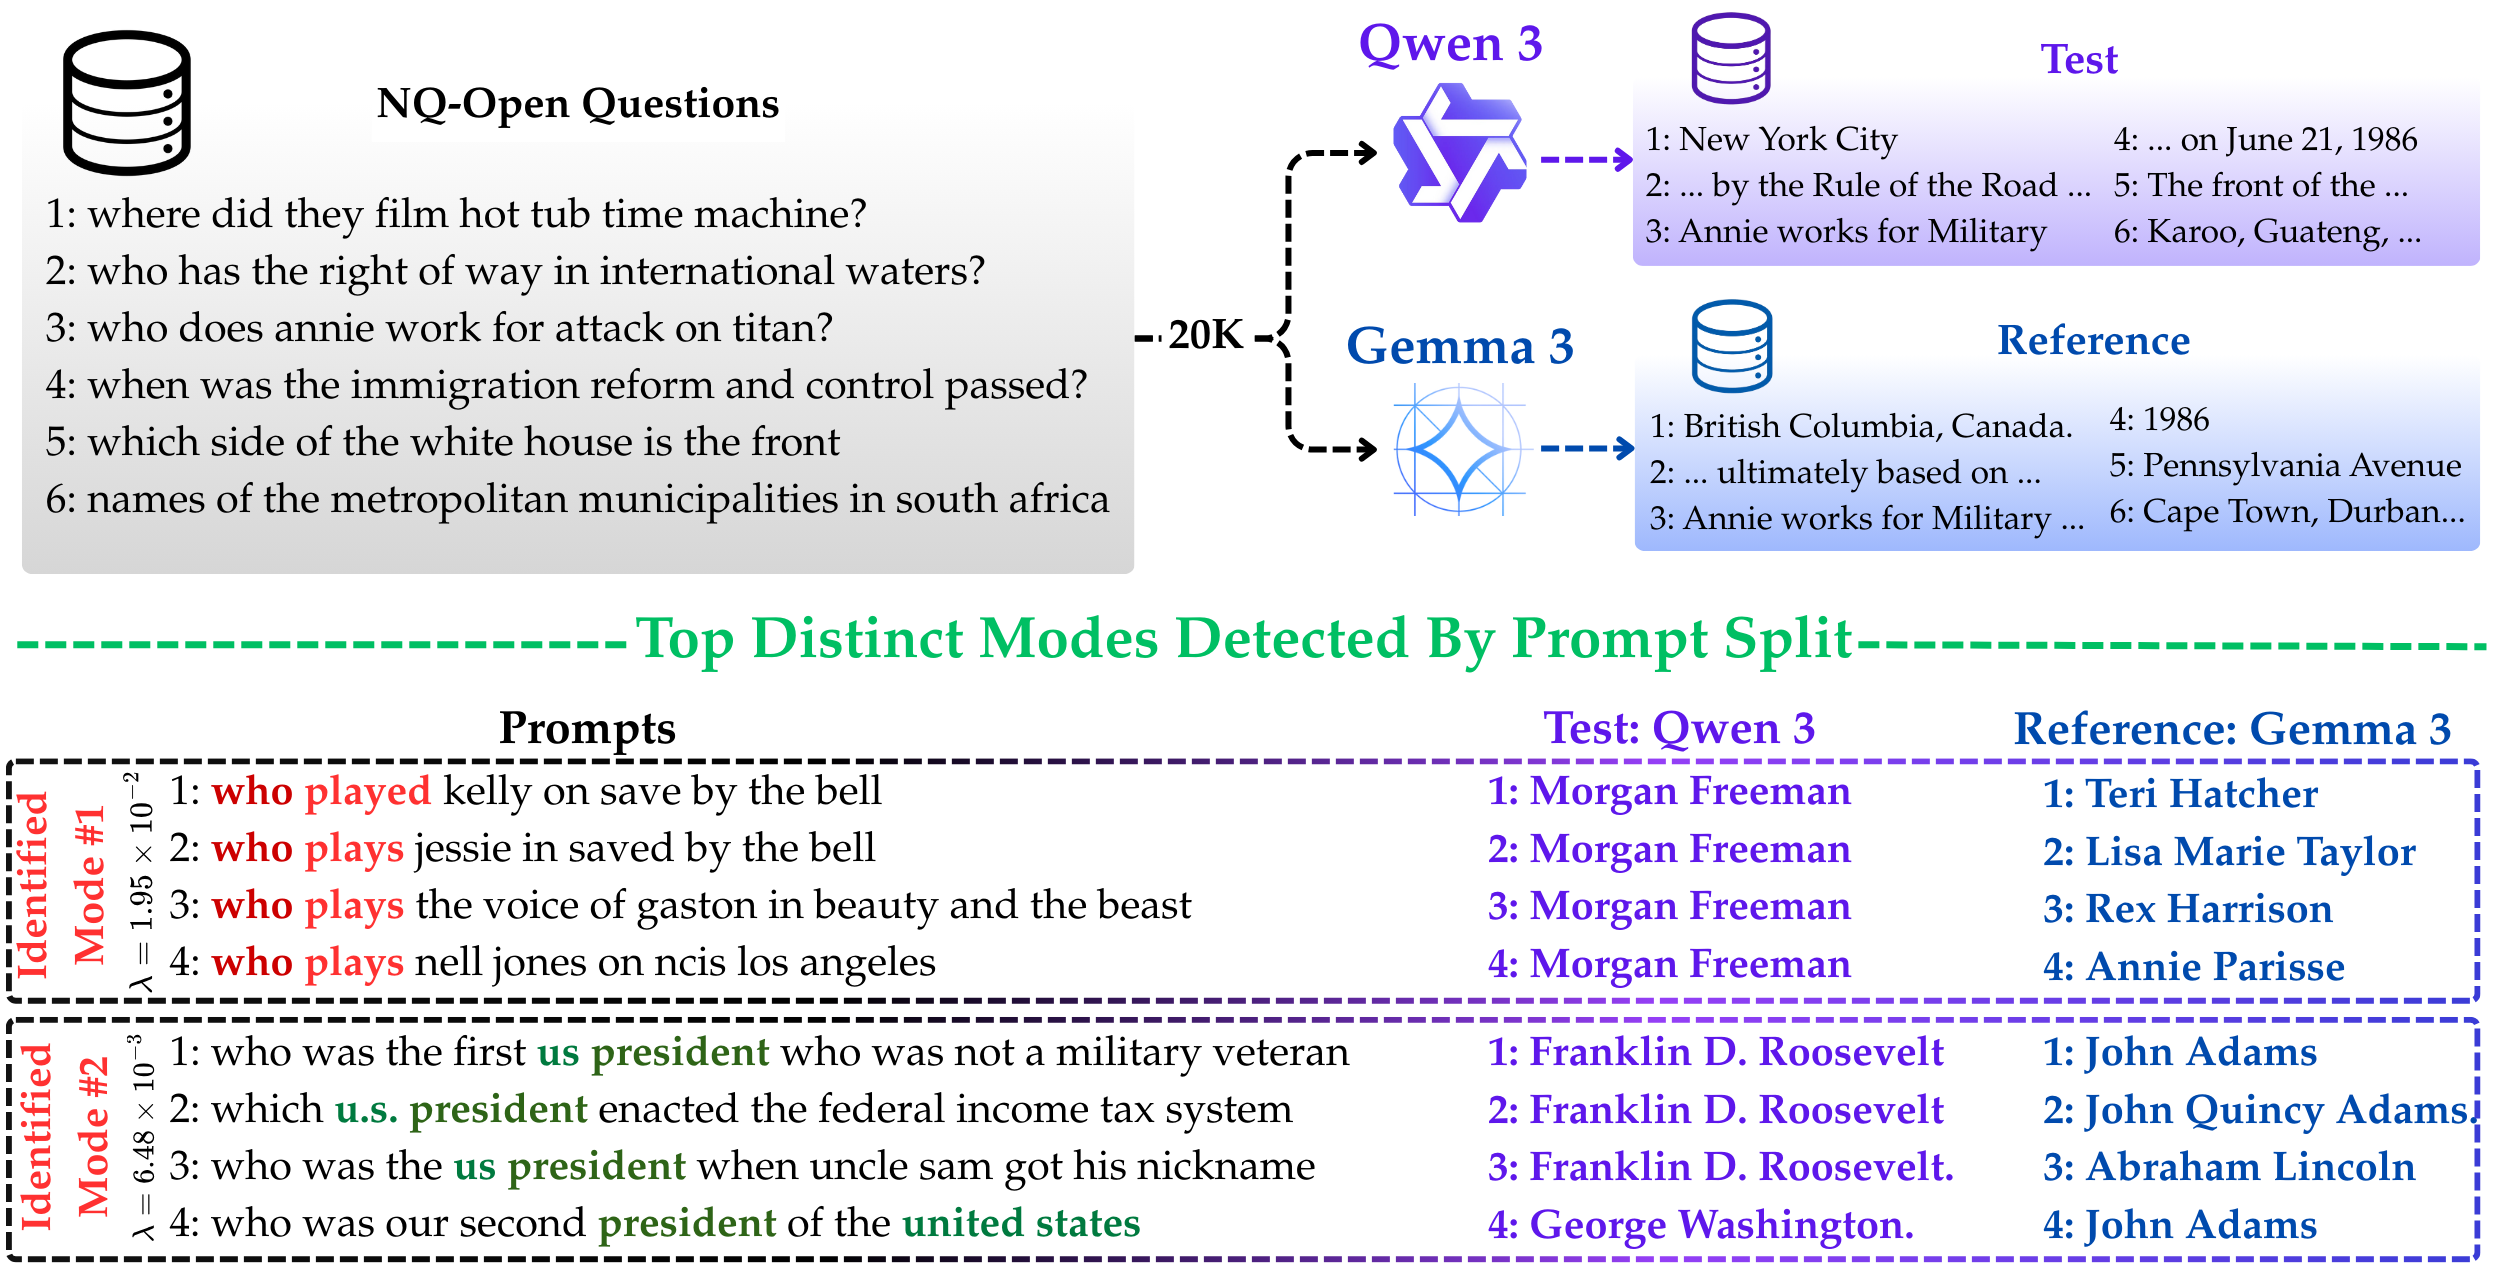
Official implementation of PromptSplit: kernel-based framework to detect prompt-level disagreements in generative models (text-to-image, LLMs). Identifies divergent prompt clusters via tensor embeddings & random projections for scalability.
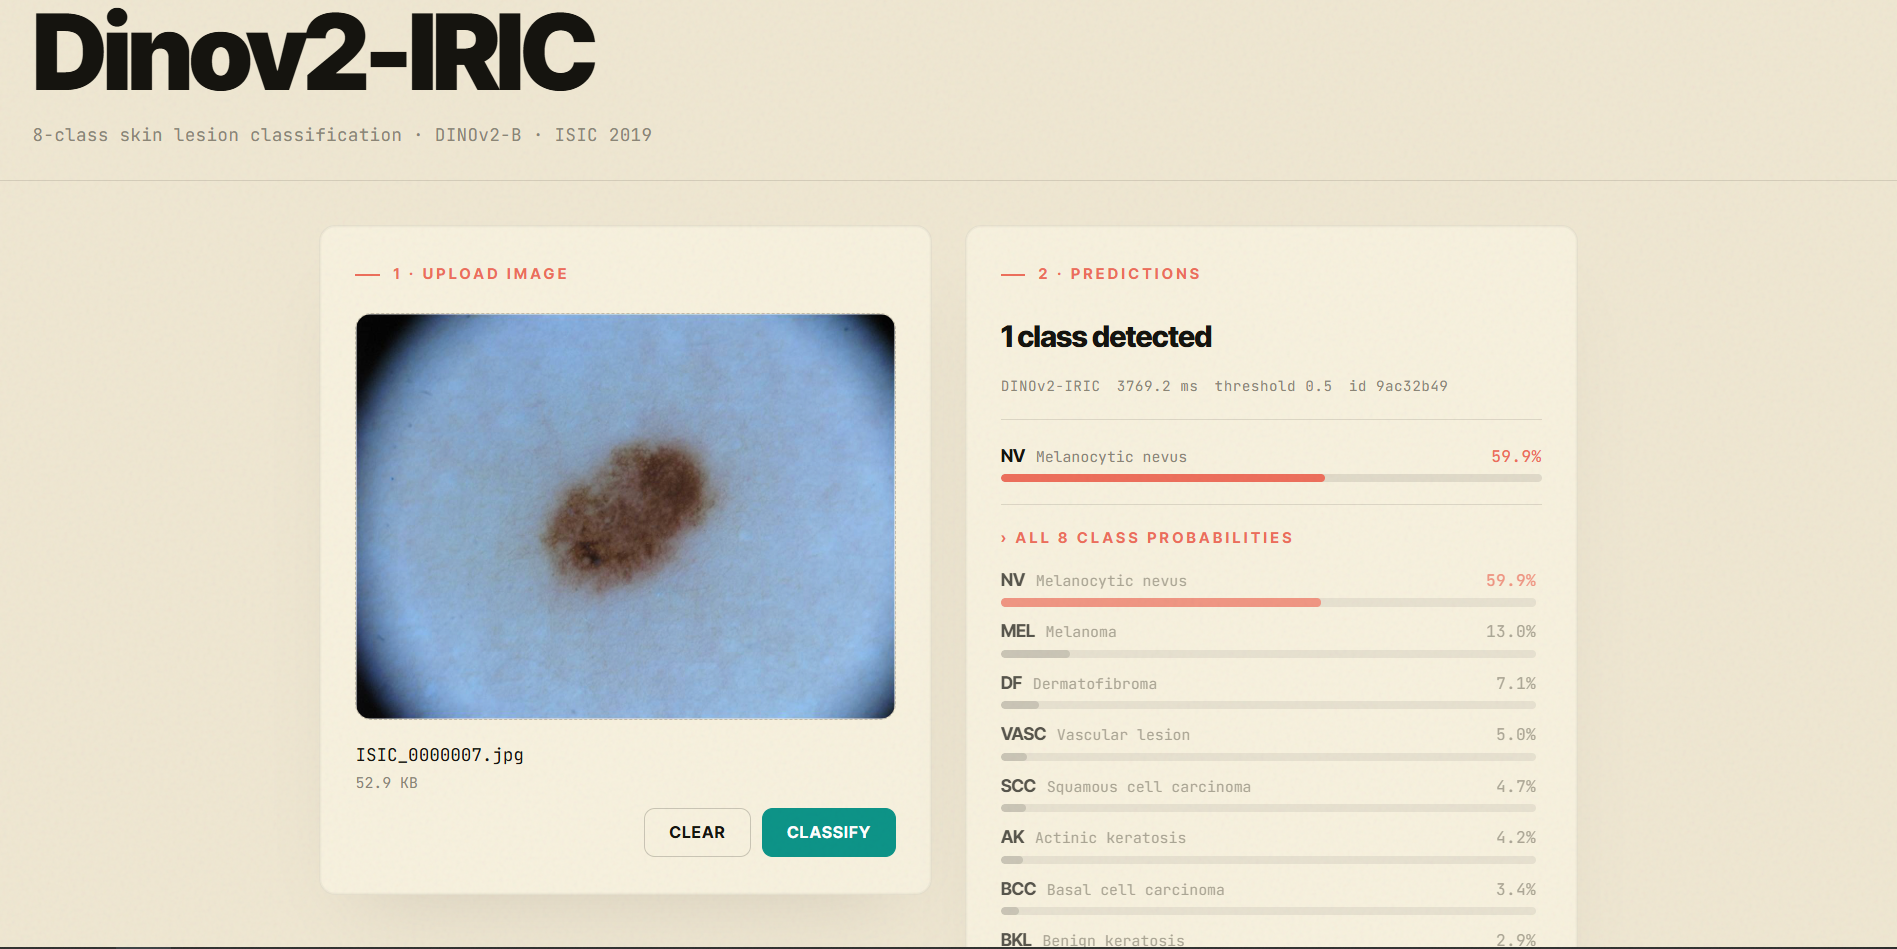
Skin lesion classification with a DINOv2-B backbone (86M params) on ISIC 2019 (8 classes). Self-contained Colab training script + FastAPI inference backend + React/TypeScript frontend. End-to-end, imbalance-aware, with Test-Time Augmentation.
High-throughput, resume-safe vision and video embedding pipelines for VLM datasets—26 pinned encoders, streaming Hugging Face ingestion, and Safetensors shard commits.
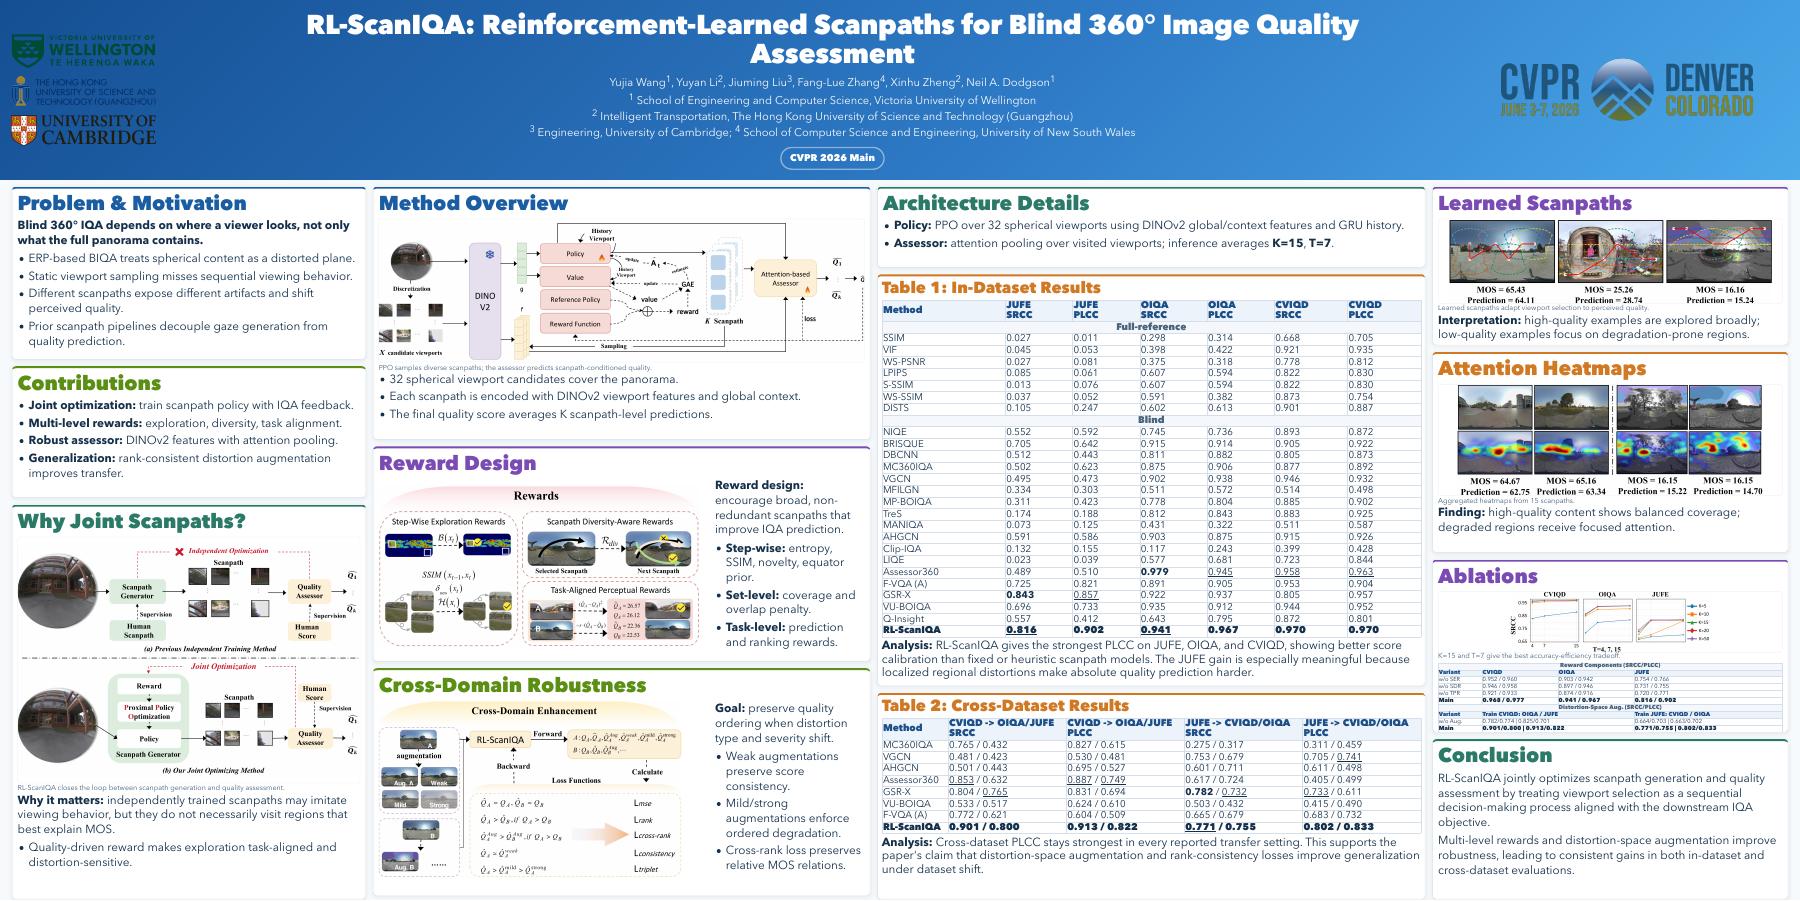
Official CVPR 2026 implementation of RL-ScanIQA for blind 360-degree image quality assessment (pp. 37401-37412).
A benchmarking pipeline for computer vision datasets on HuggingFace. Evaluates dataset quality across structural, embedding-based, and diversity metrics with UMAP visualizations of the embedding space. Designed to be task-agnostic across various vision datasets. Built for reproducible evaluation with SLURM support for GPU clusters.
Image classification model, used with transformers.
Feature Island Induction From a Semantically Rich Ocean. Not the title of a deeply philosophical book about representation.
Image classification model, used with transformers.
Vision Foundation Model for industrial anomaly detection using DINOv2-ViT-Base with LoRA adaptation. Optimized through 4-version experimental study on MVTec-AD2 dataset, achieving stable performance across all 7 categories (average AUC: 0.5626).