facex
Full face stack that runs entirely in the browser. Detection, 576-point 3D mesh, recognition, anti-spoof, smile — all WebAssembly, zero server. Apache 2.0.
- 351
- C
- Apache-2.0
- 6 mo ago
Full face stack that runs entirely in the browser. Detection, 576-point 3D mesh, recognition, anti-spoof, smile — all WebAssembly, zero server. Apache 2.0.
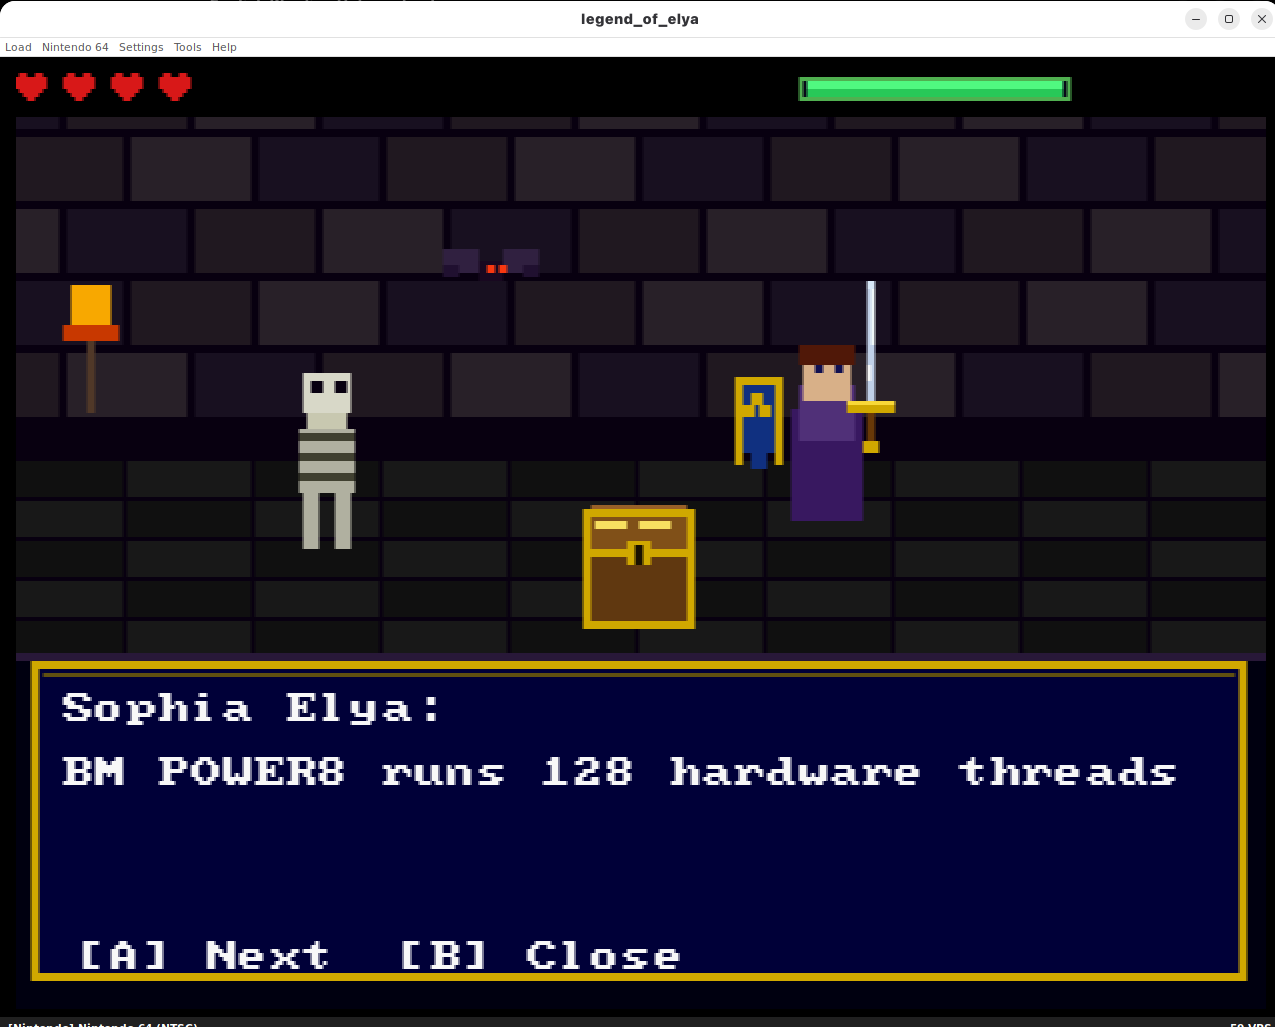
Legend of Elya — N64 game with a real 6.36M-parameter ternary transformer on the VR4300 MIPS III CPU. Zelda-style dungeon, AI NPCs, byte-level inference at 1.23 tok/s scalar / 2.19 tok/s on the RSP overlay (measured under ares, never on silicon). Built with libdragon.
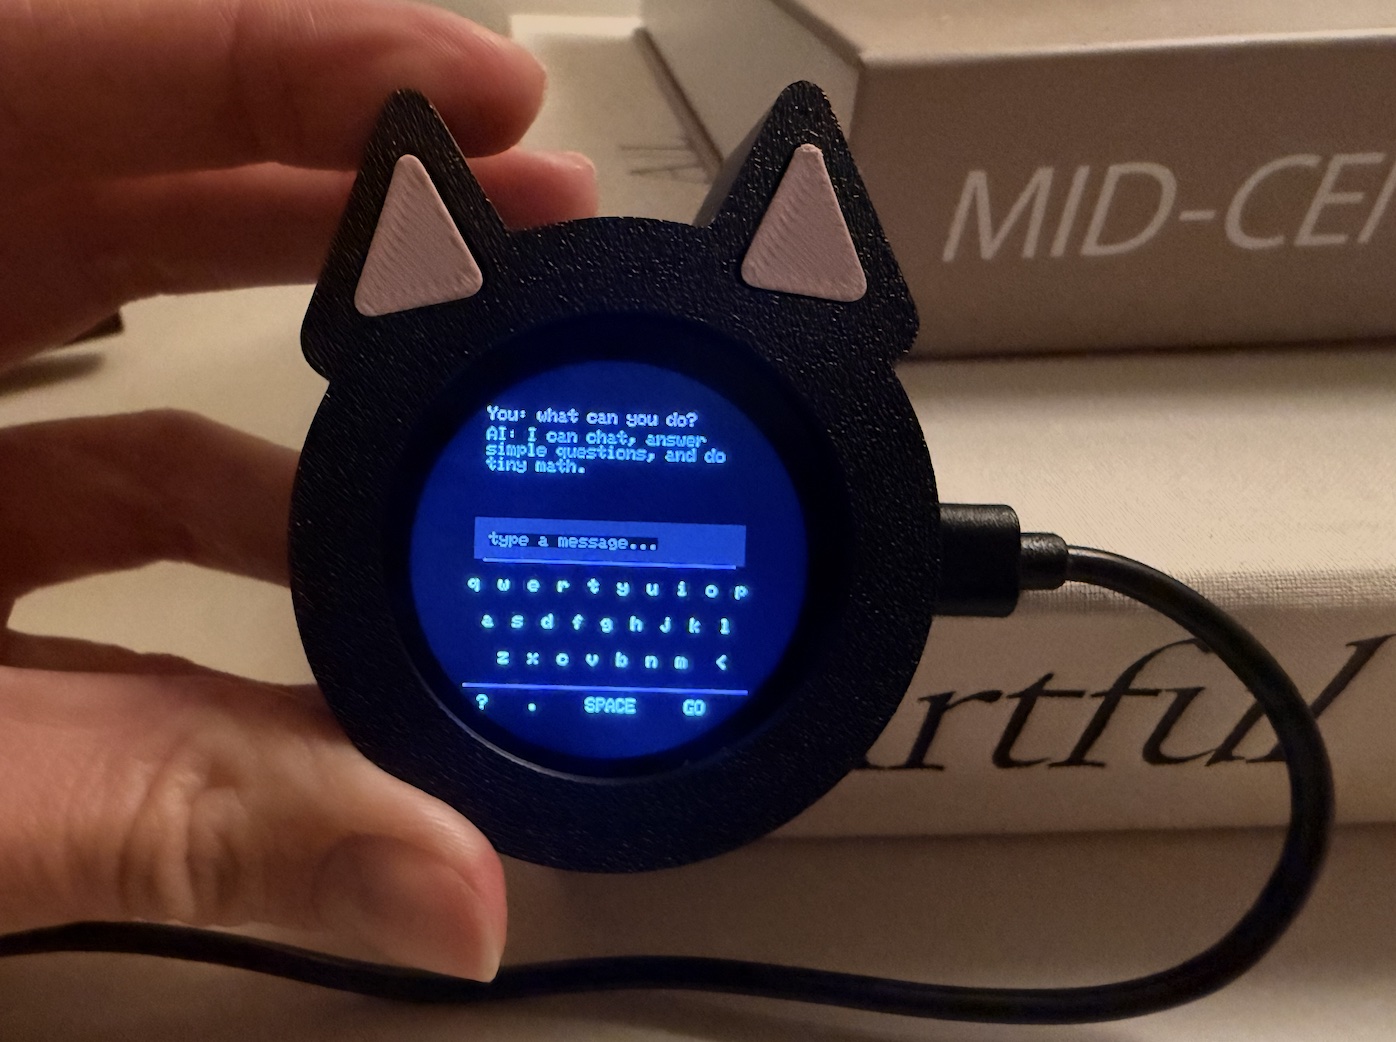
A language model trained from scratch and running offline on an ESP32-S3 with a touchscreen chat interface.
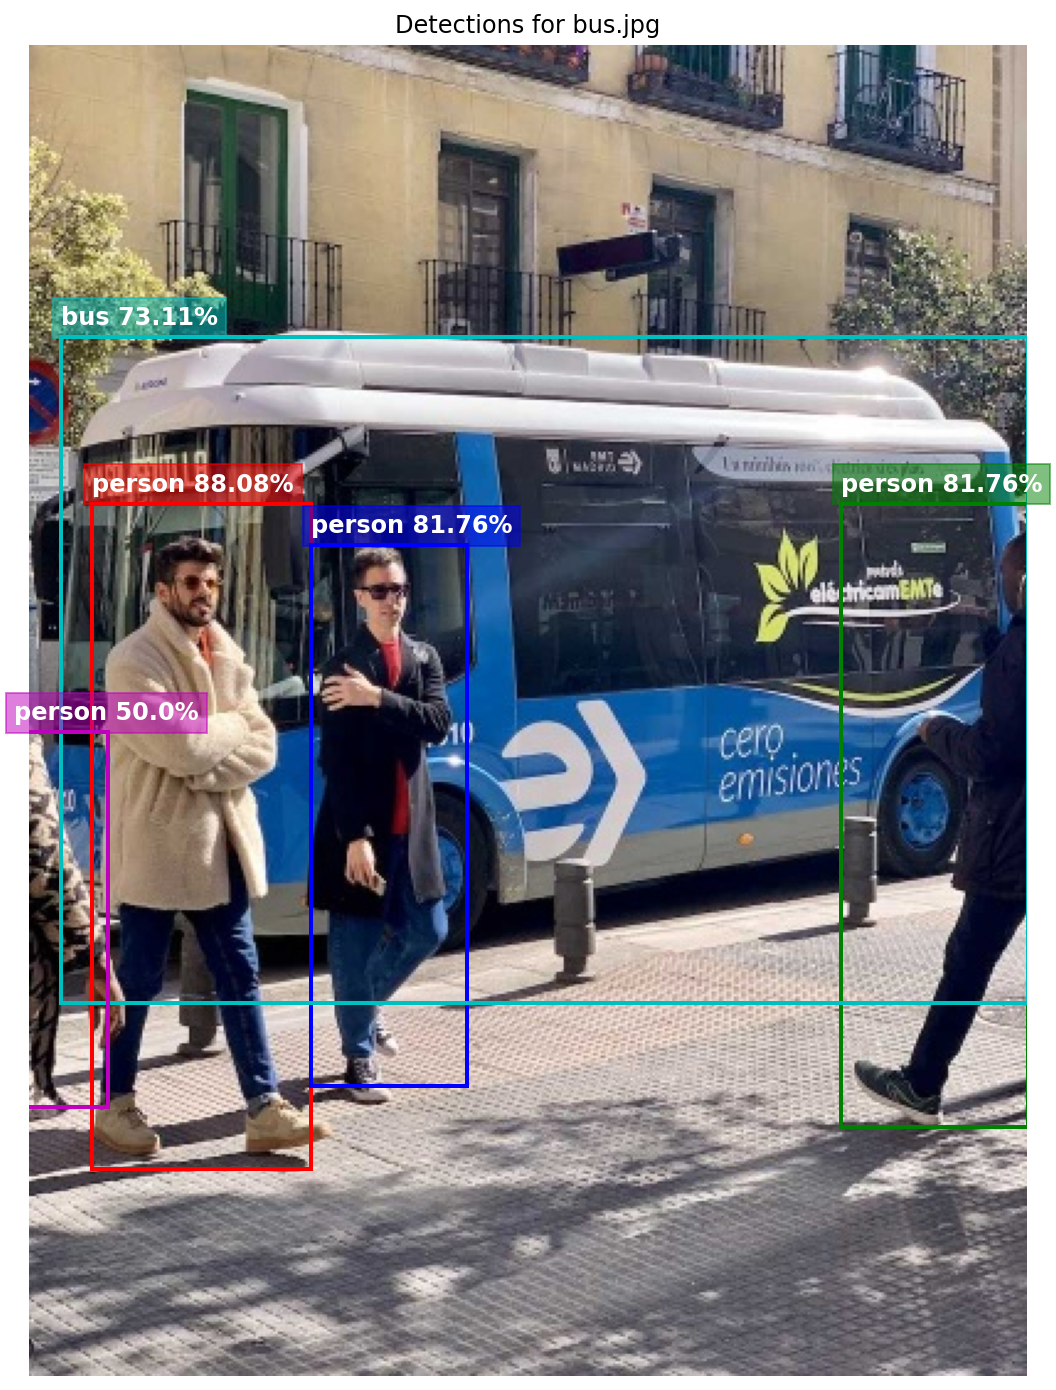
World's First NMS-Free YOLOv26n on ESP32-P4. Features end-to-end Int8 QAT and custom C++ optimizations achieving 30% faster inference than the official ESP-DL YOLOv11n (1.7s vs 2.4s).
RPI (Resonant Permutation Inference) — Zero-multiply text generation. 18K tok/s. 868 KB models. Standalone or as speculative draft engine for LLMs. Runs on N64, POWER8, x86, ARM.
Open-source Hardware AI agent. Single Rust binary for cameras, sensors, robots, and IoT fleets — orchestrated by AI agents with memory and real-time telemetry. Runs on Jetson, Raspberry Pi, any Linux.
AcousticsLab is a cross-platform framework for sound and vibration analysis.
Ultra-lightweight C++ inference engine for BitMamba-2 (1.58-bit SSM). Runs 1B models on consumer CPUs at 50+ tok/s using <700MB RAM. No heavy dependencies.
🔥 ACM Multimedia Asia 2023 (Tainan, Taiwan) – Grand Challenges
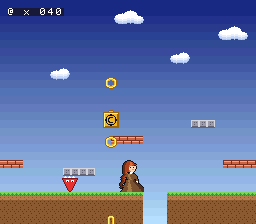
TinyML quantization result: on the SNES 65816, ternary beats int8 by 2.02x despite a free hardware multiply — because the cost is operand traffic, not arithmetic. A transformer LLM on 1990 silicon.
Auto-updated robotics, perception, autonomy and embedded engineering jobs, refreshed every 2 days. Top companies first. Free. By landed.
Ultra-low-power edge inference at its limit: a ternary transformer LLM on the NES 1.79 MHz 6502. 8-bit accumulator, exact cycle counts, 0.634 s/token, verified token-exact against a host reference.
Real-time SAM2 segmentation on edge devices - 40x faster C++ inference with ONNX Runtime for iOS/Android deployment
Real-time ear biometric recognition on STM32F407 with FreeRTOS - 95%+ accuracy, 120ms latency using PCA/LDA/DCVA on ARM Cortex-M4
HelixLM - a recurrent heterogeneous graph neural LLM combining biological neural column random wiring, hybrid attention, and Mamba-2 for hyperpersonalized and on-device AI.