WavTokenizer
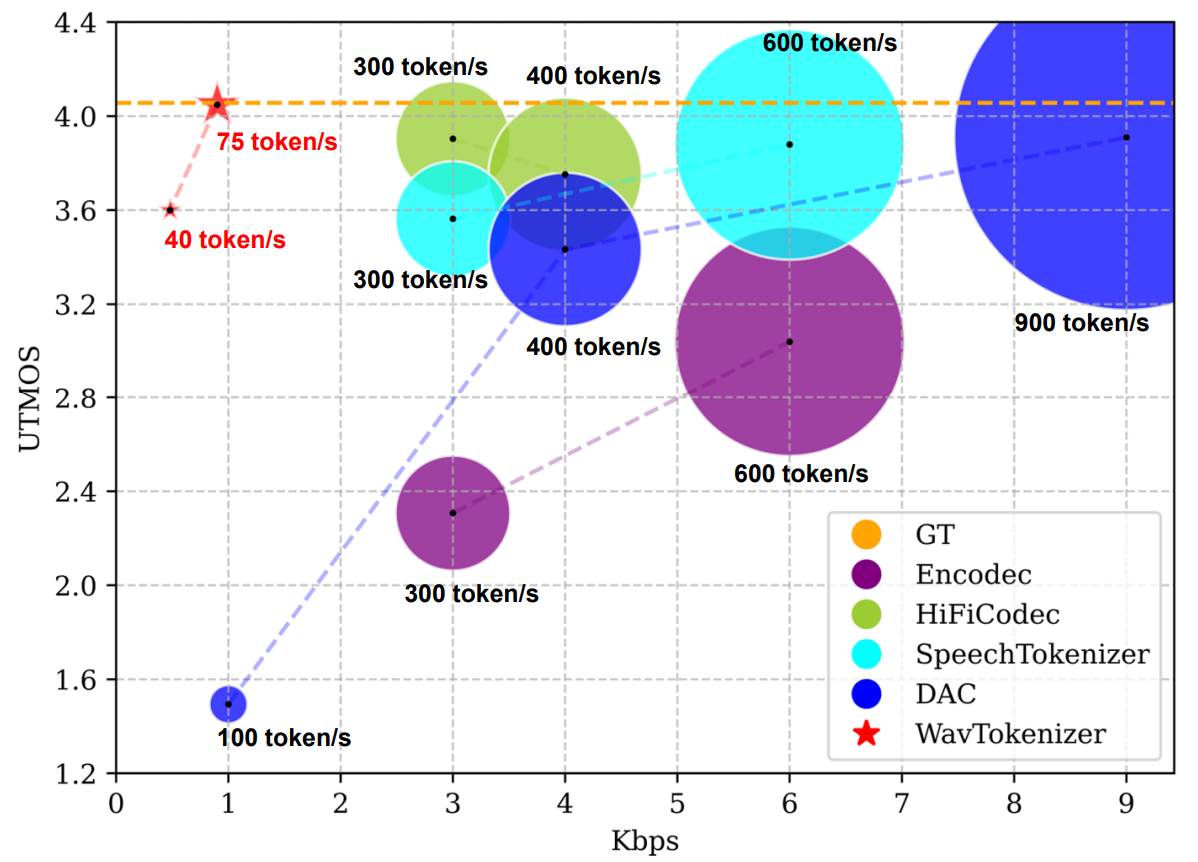
[ICLR 2025] SOTA discrete acoustic codec models with 40/75 tokens per second for audio language modeling
- 1.3k
- Python
- MIT
- 21 mo ago
[ICLR 2025] SOTA discrete acoustic codec models with 40/75 tokens per second for audio language modeling
FunCodec is a research-oriented toolkit for audio quantization and downstream applications, such as text-to-speech synthesis, music generation et.al.
Codebase for the paper 'EncodecMAE: Leveraging neural codecs for universal audio representation learning'


