pathway
Python ETL framework for stream processing, real-time analytics, LLM pipelines, and RAG.
- 62k
- Python
- 1 d ago
Python ETL framework for stream processing, real-time analytics, LLM pipelines, and RAG.
Apache Airflow - A platform to programmatically author, schedule, and monitor workflows
Orchestrate everything, everywhere. The open-source control plane for workflows across data, infrastructure, business processes and AI agents. Declarative YAML, event-driven, any language, Git-versioned, scalable to millions of executions.
Open-source data movement for ELT pipelines and AI agents — from APIs, databases & files to warehouses, lakes, and AI applications. Both self-hosted and Cloud.
An orchestration platform for the development, production, and observation of data assets.
🧙 Build, run, and manage data pipelines for integrating and transforming data.
Zero-ETL, infinite possibilities. Live query APIs, code & more with SQL. No DB required.
Data pipelines for cloud config and security data. Build cloud asset inventory, CSPM, FinOps, and vulnerability management solutions. Extract from AWS, Azure, GCP, and 70+ cloud and SaaS sources.
High-performance data engine for AI and multimodal workloads. Process images, audio, video, and structured data at any scale
pandas on AWS - Easy integration with Athena, Glue, Redshift, Timestream, Neptune, OpenSearch, QuickSight, Chime, CloudWatchLogs, DynamoDB, EMR, SecretManager, PostgreSQL, MySQL, SQLServer and S3 (Parquet, CSV, JSON and EXCEL).
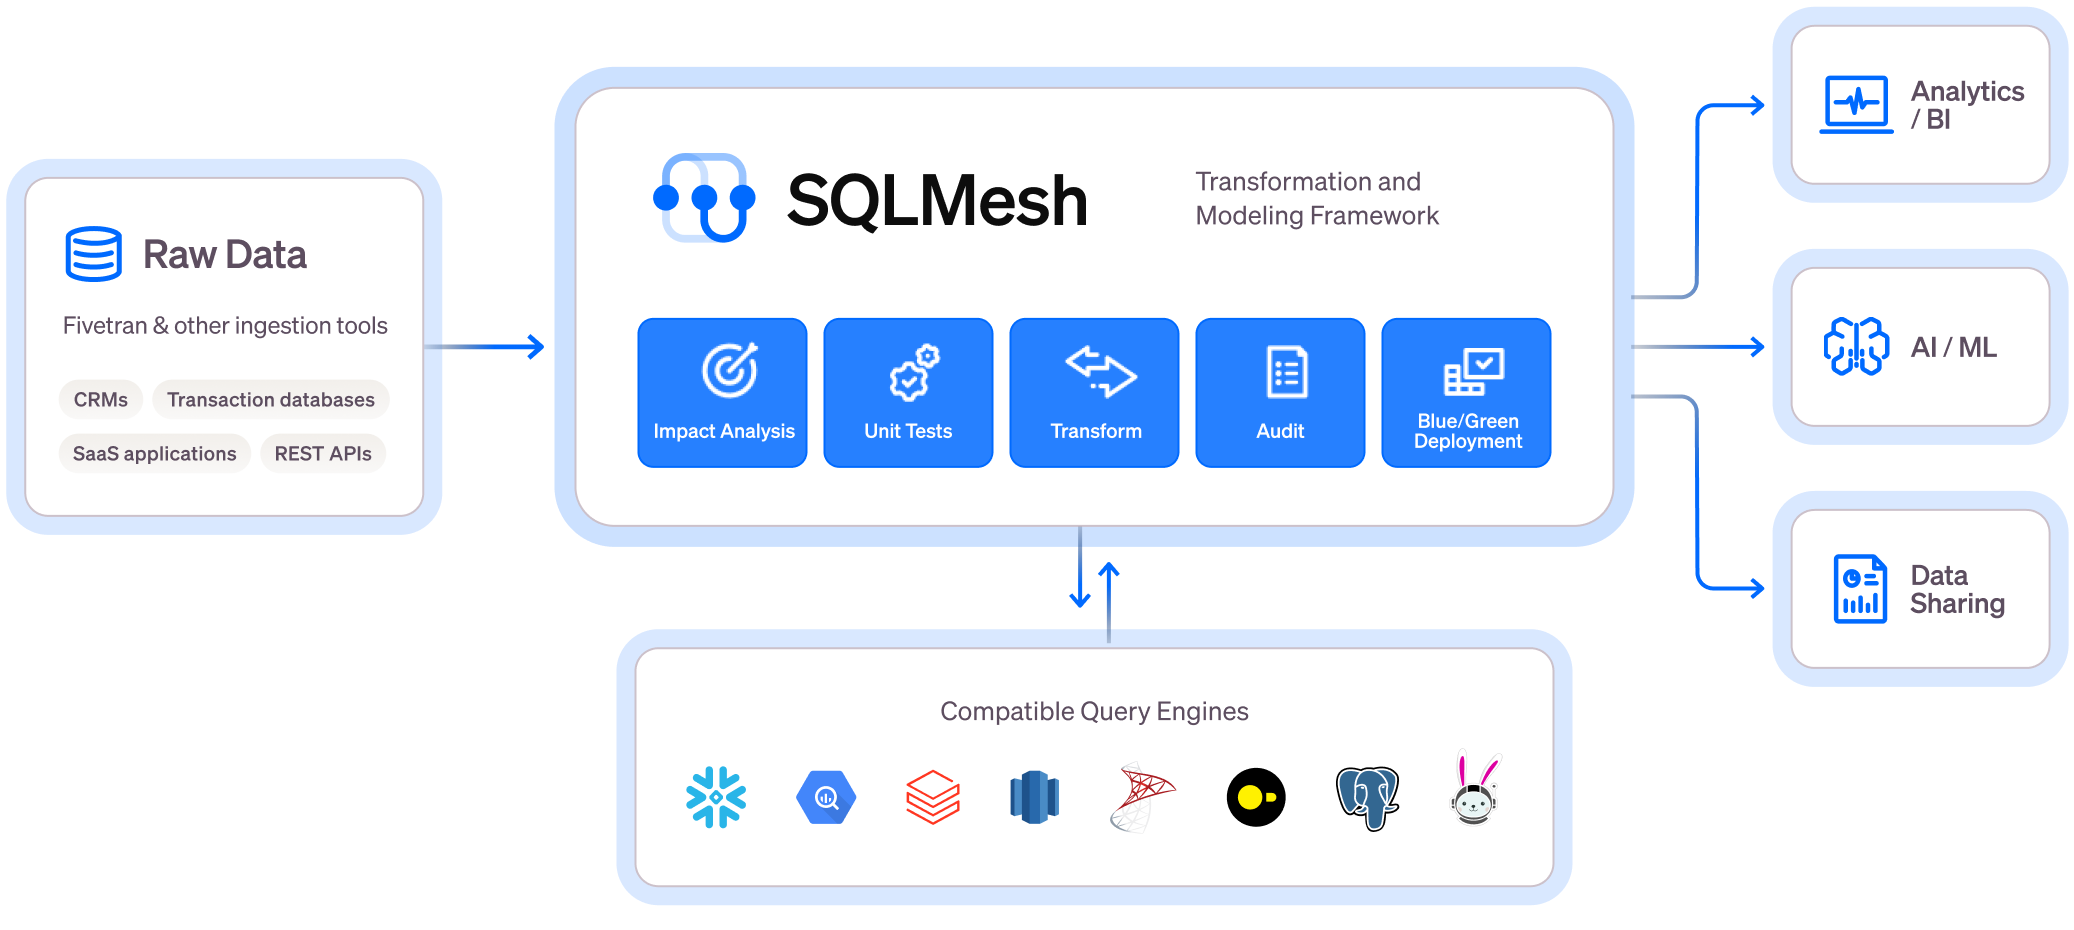
Scalable and efficient data transformation framework - backwards compatible with dbt.
Fast, Simple and a cost effective tool to replicate data from Postgres to Data Warehouses, Queues and Storage
Apache Hamilton helps data scientists and engineers define testable, modular, self-documenting dataflows, that encode lineage/tracing and metadata. Runs and scales everywhere python does.
Python scripts for ETL (extract, transform and load) jobs for Ethereum blocks, transactions, ERC20 / ERC721 tokens, transfers, receipts, logs, contracts, internal transactions. Data is available in Google BigQuery https://goo.gl/oY5BCQ
Apache DevLake is an open-source dev data platform to ingest, analyze, and visualize the fragmented data from DevOps tools, extracting insights for engineering excellence, developer experience, and community growth.
The fastest unified streaming SQL Engine in a single C++ binary. ⚡ Millisecond latency. 100+ GB/s throughput. Continuously compute stateful context from streams, logs, metrics, events, and CDC.
🔮 Instill Core is a full-stack AI infrastructure tool for data, model and pipeline orchestration, designed to streamline every aspect of building versatile AI-first applications
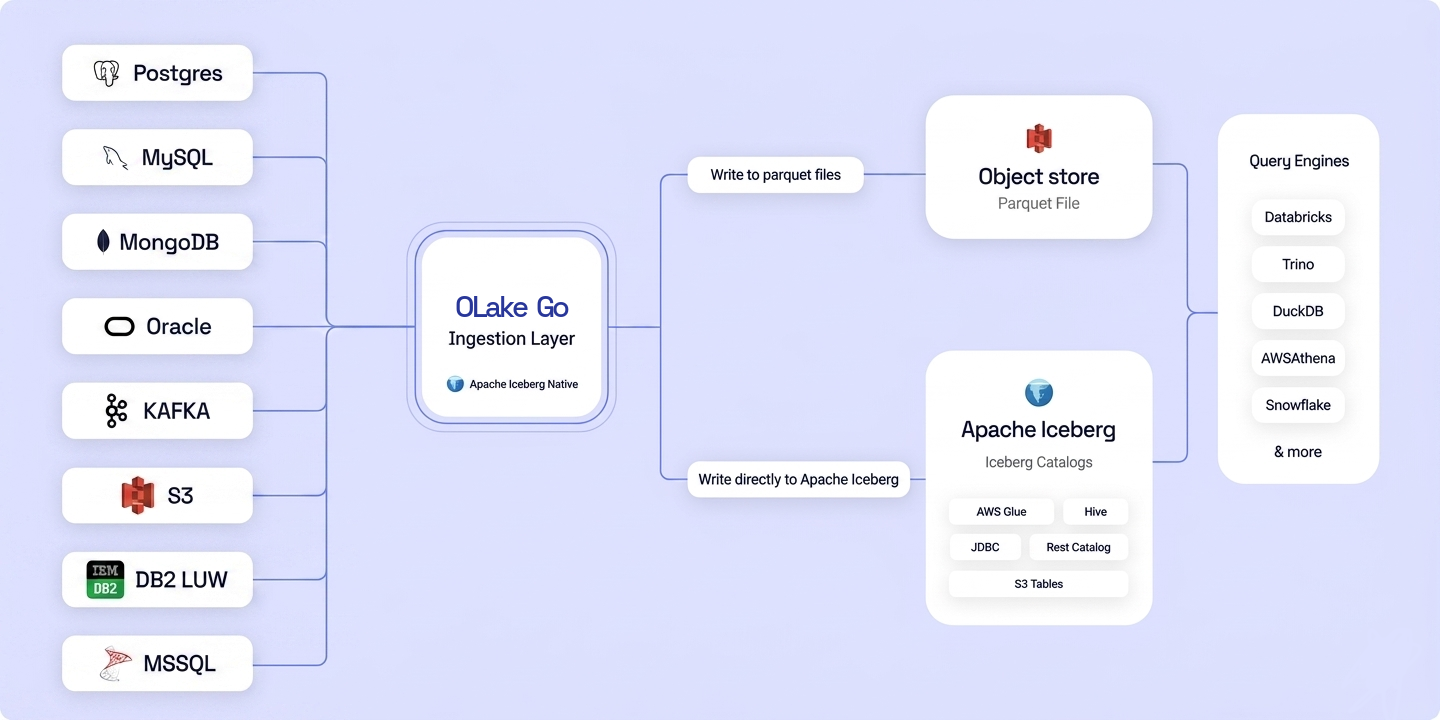
OLake Go: open-source replication from databases, Kafka and S3 to Apache Iceberg and Parquet. Sources: Postgres, MySQL, MongoDB, Oracle, MSSQL, DB2, Kafka, S3. Formerly datazip-inc/olake. Table maintenance lives in datazip-inc/olake-fusion.
A lightweight opinionated ETL framework, halfway between plain scripts and Apache Airflow
The best place to learn data engineering. Built and maintained by the data engineering community.
Fast and efficient unstructured data extraction. Written in Rust with bindings for many languages.
🔥🔥🔥 Open source Reverse ETL - alternative to hightouch and census.
Dozer is a real-time data movement tool that leverages CDC from various sources and moves data into various sinks.