evaluation-framework

Open repos and models their makers tagged evaluation-framework, most starred first. The same for everyone.

AI on my own machineRepo

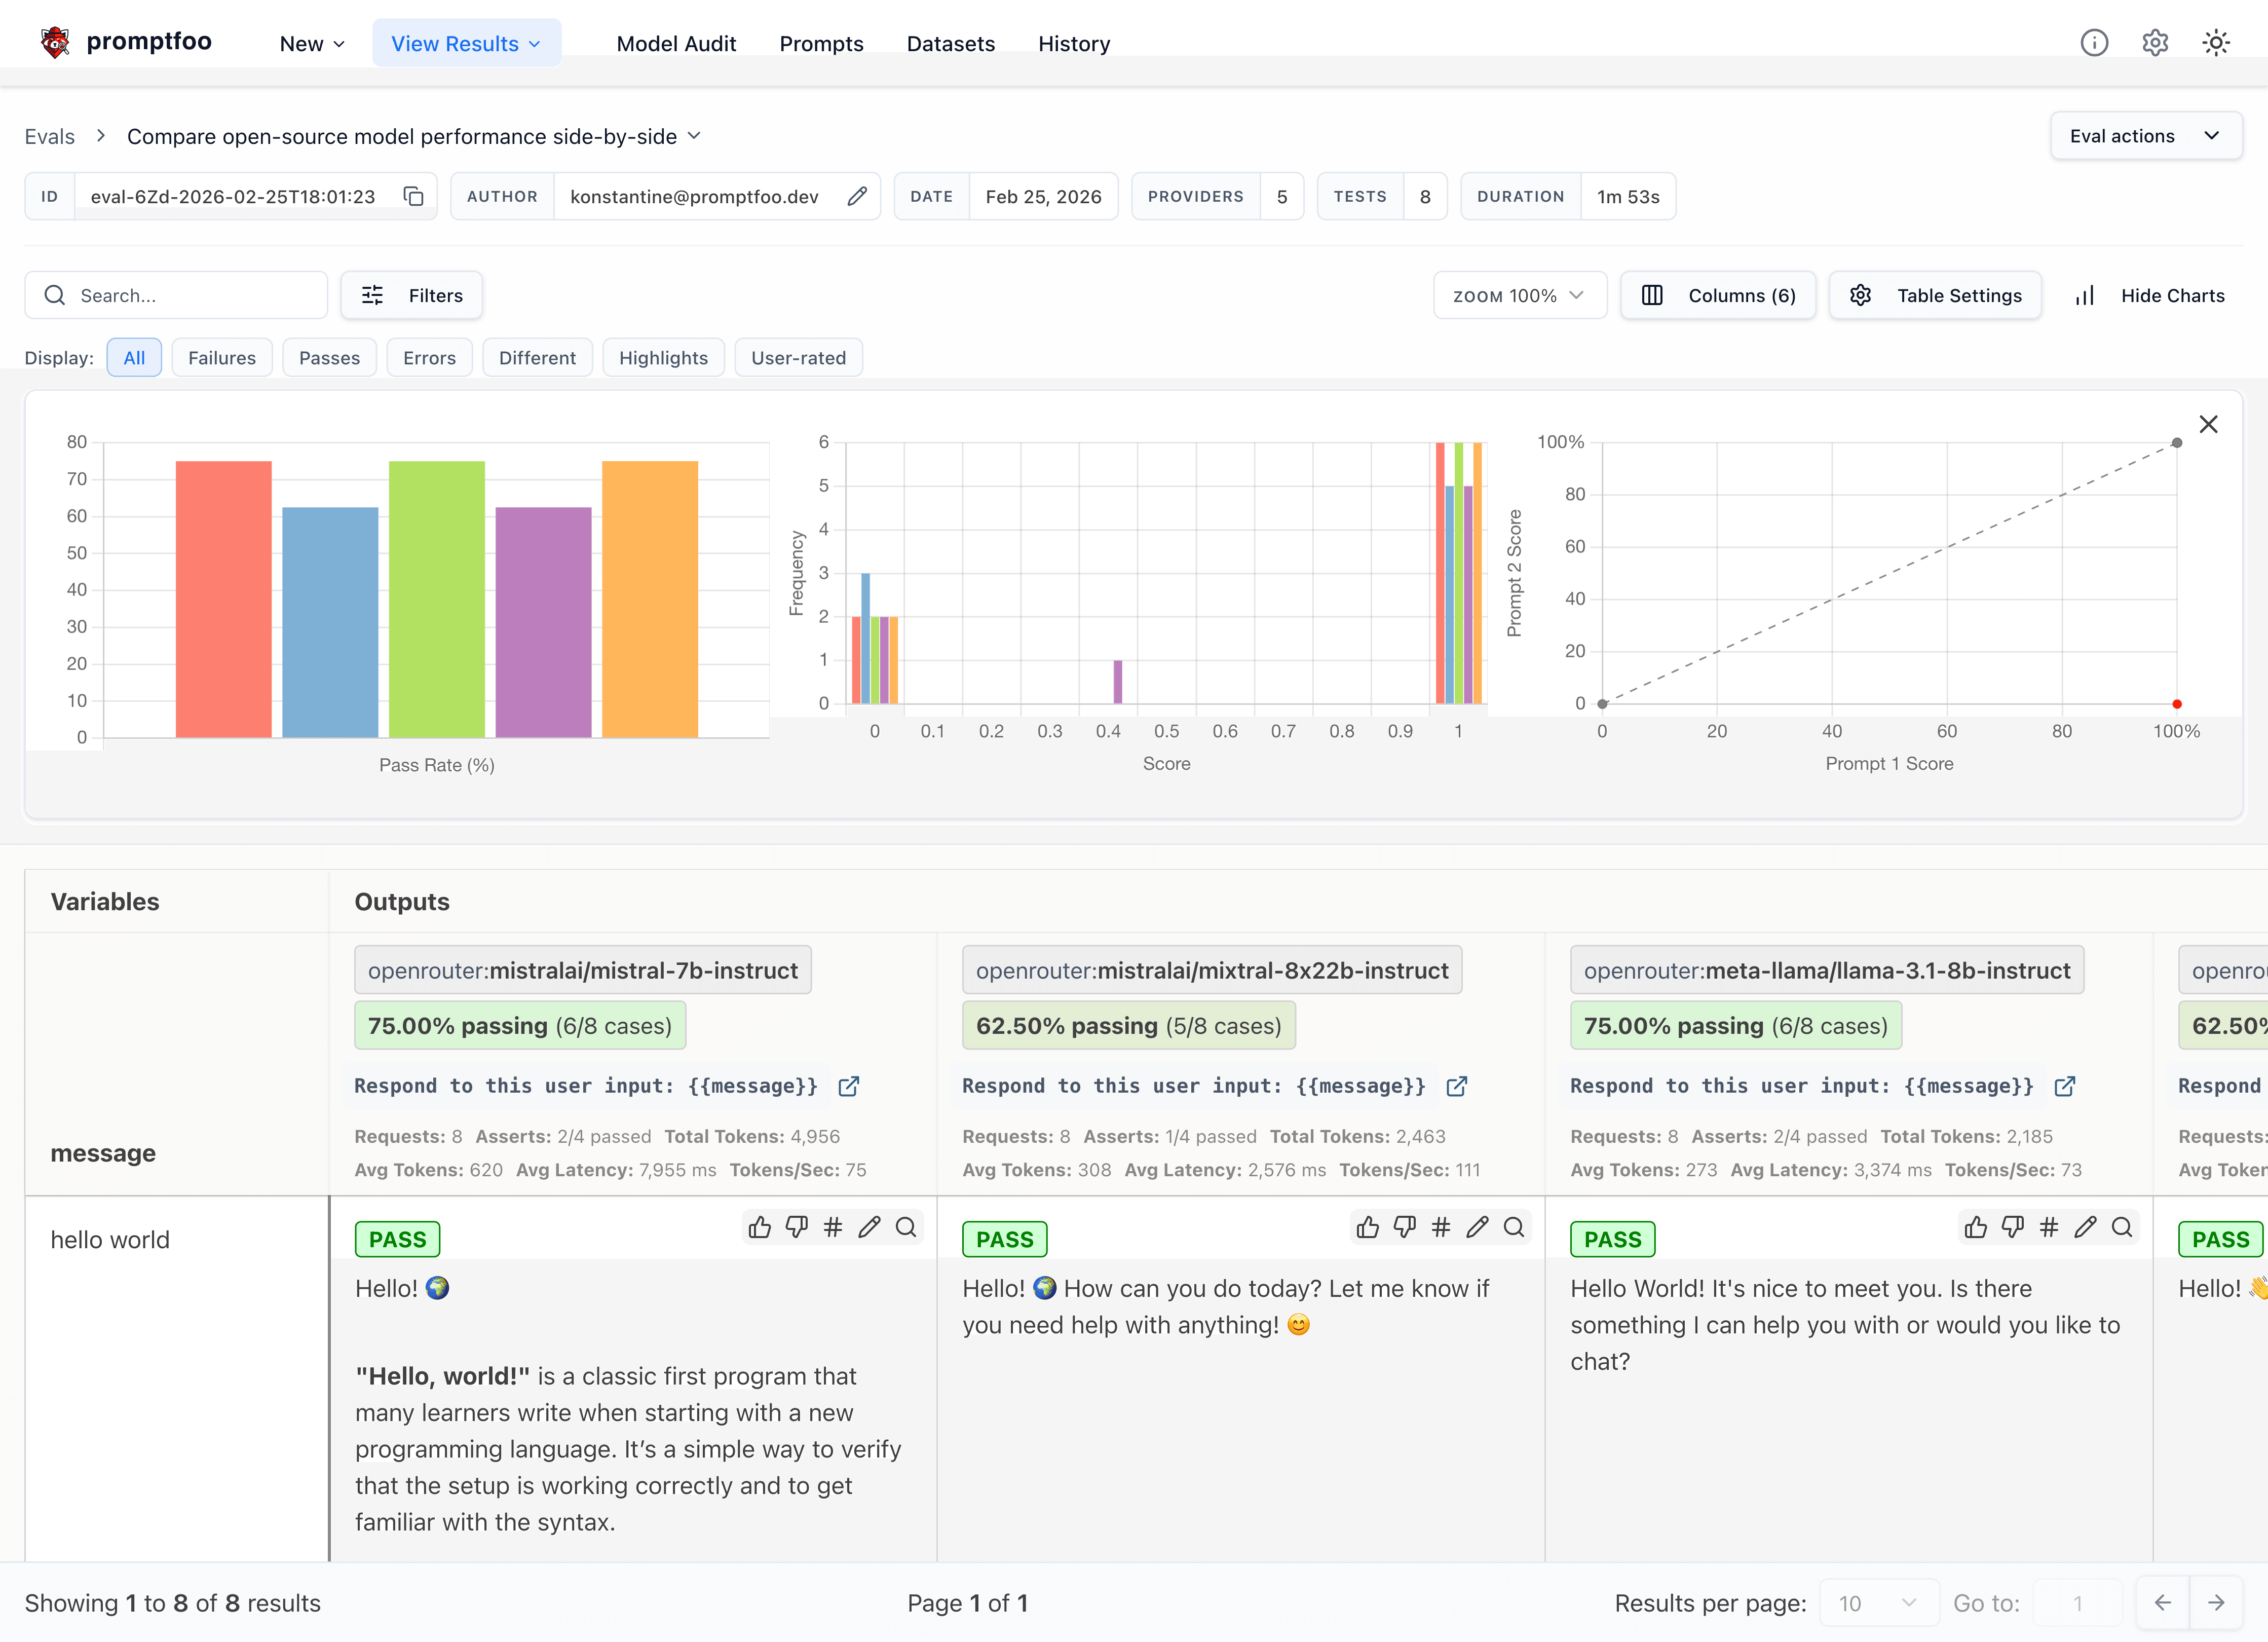
promptfoo

Test your prompts, agents, and RAGs. Red teaming/pentesting/vulnerability scanning for AI. Compare performance of GPT, Claude, Gemini, DeepSeek, and more. Simple declarative configs with command line and CI/CD integration. Used by OpenAI and Anthropic.

  • 27k
  • TypeScript
  • MIT
  • 27 min ago
promptfooTake it
AI on my own machineRepo

Kiln

Build, Evaluate, and Optimize AI Systems. Includes evals, RAG, agents, fine-tuning, synthetic data generation, dataset management, MCP, and more.

  • 5.3k
  • Python
  • 1 h ago
Kiln-AITake it
AI agentsRepo

future-agi

Open-source, end-to-end platform for evaluating, observing, and improving LLM and AI agent applications. Tracing · Evals · Simulations · Datasets · Gateway · Guardrails. Self-hostable. Apache 2.0.

  • 2.3k
  • Python
  • Apache-2.0
  • 2 h ago
future-agiTake it
AI agentsRepo

AgentLab

AgentLab: An open-source framework for developing, testing, and benchmarking web agents on diverse tasks, designed for scalability and reproducibility.

  • 667
  • Python
  • 6 wk ago
ServiceNowTake it
AI agentsRepo
uaef

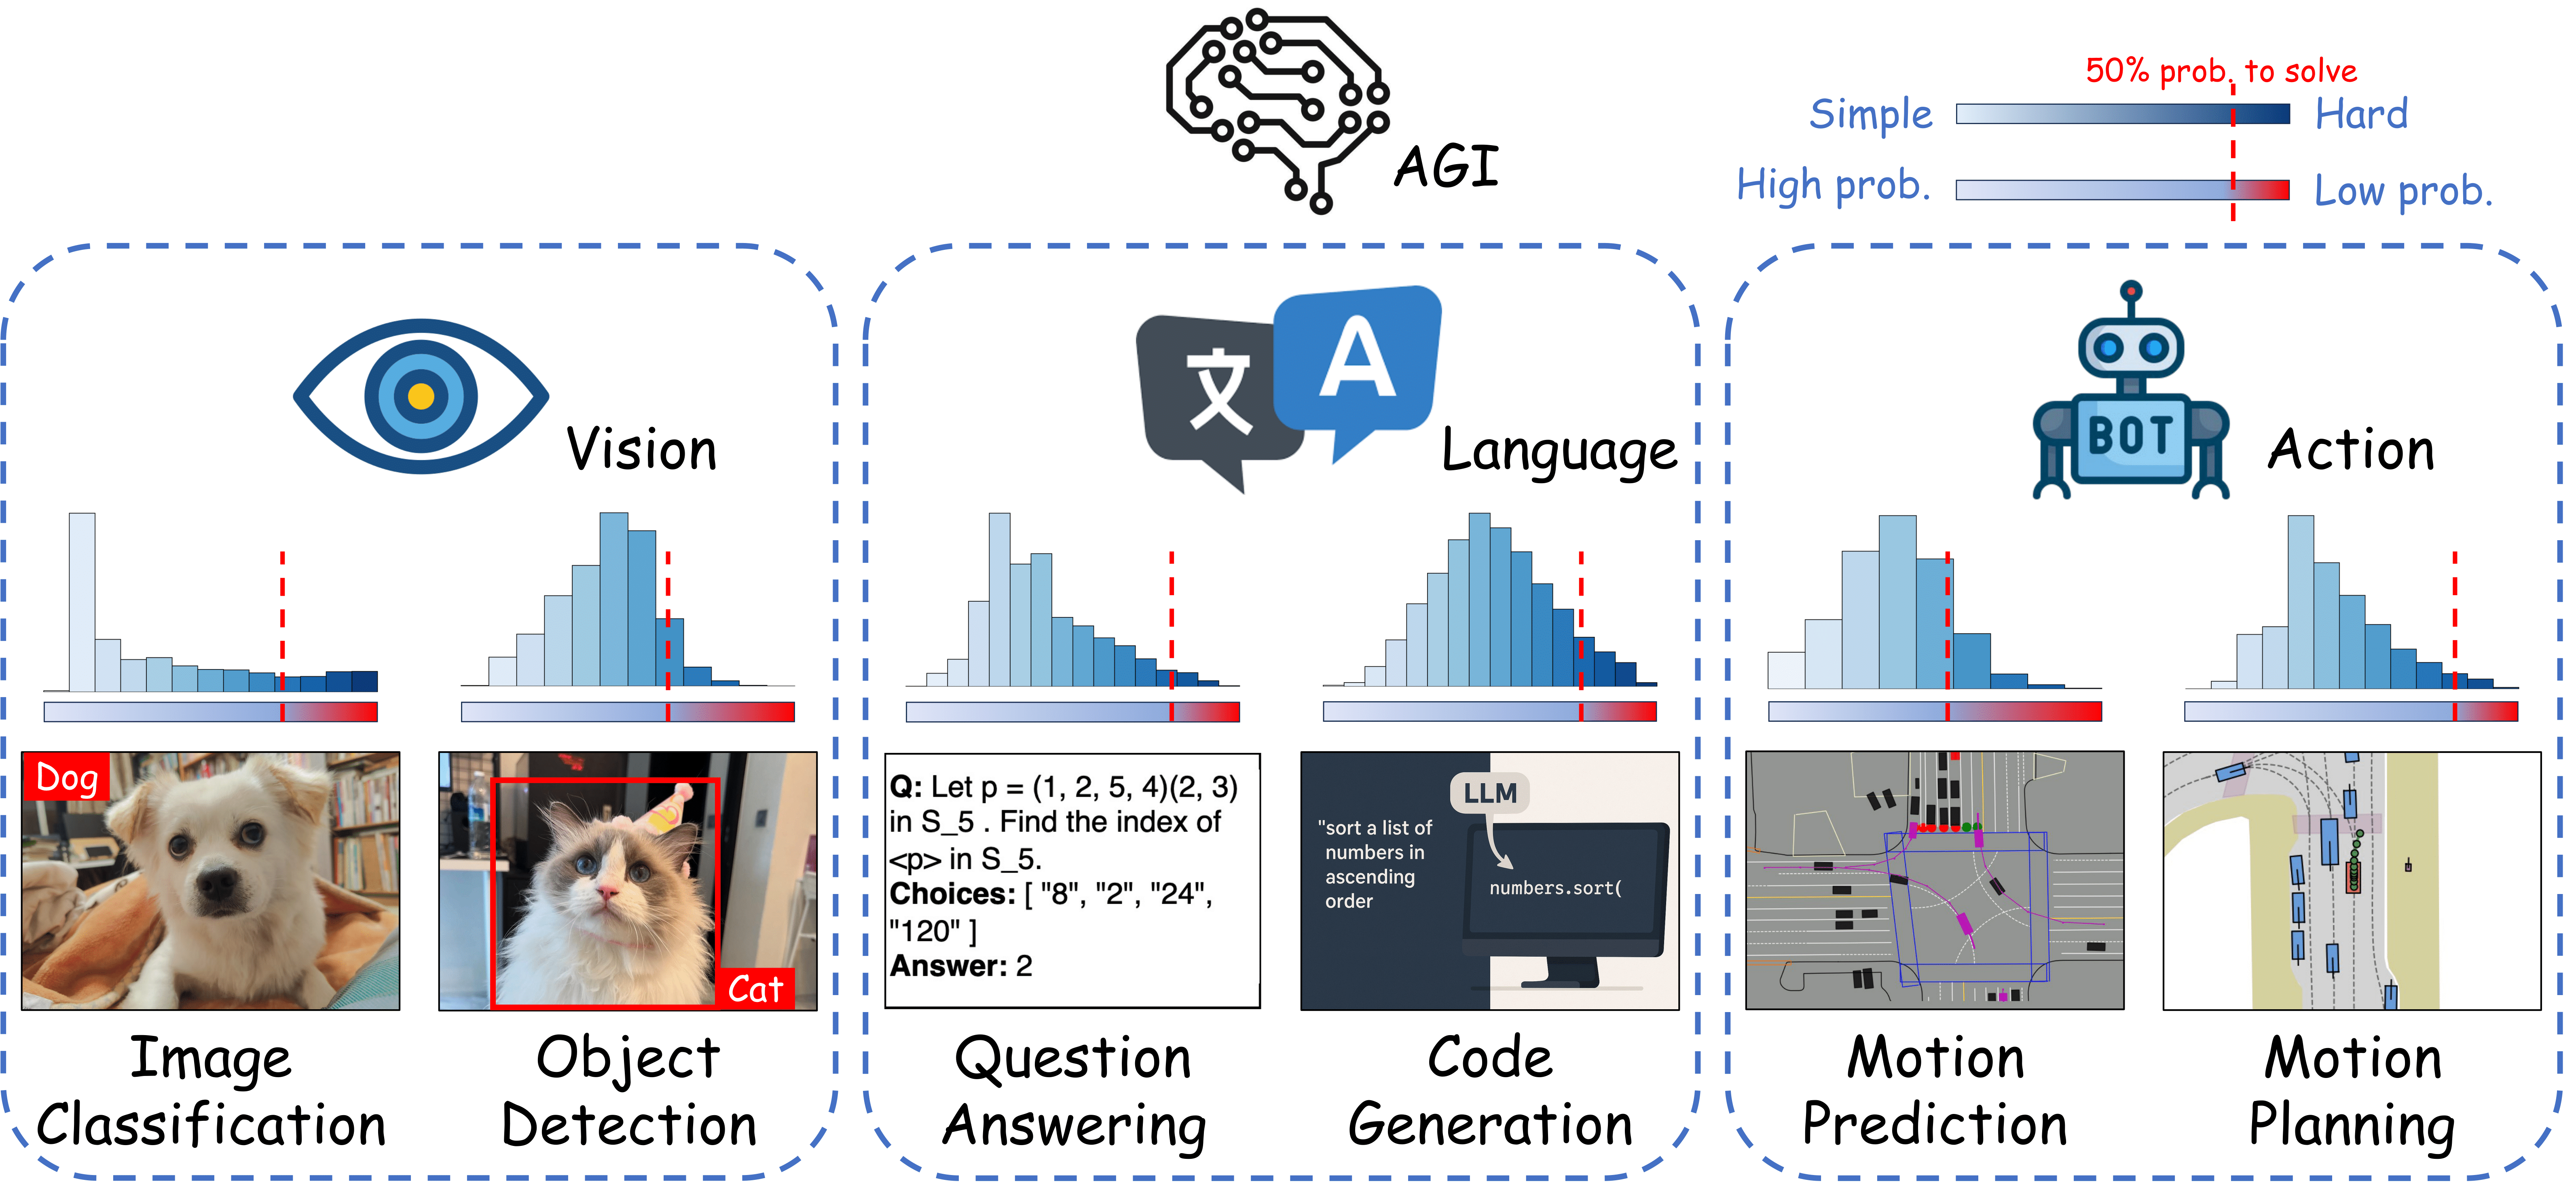
Universal Agent Evaluation Framework (UAEF) is a framework-agnostic evaluation system for AI agents. Invoke any agent and score it on multiple metrics spanning tool calling, response quality, safety, performance, and reasoning. Track experiments against baselines, catch regressions automatically, and get LLM-generated insights.

  • 184
  • Python
  • Apache-2.0
  • 5 d ago
awslabsTake it
AI on my own machineRepo

oh-my-knowledge

OMK helps people and agents build, maintain, and reuse valuable knowledge from real work and collaboration, with readable content, traceable sources, and revision history for future tasks.

  • 25
  • TypeScript
  • MIT
  • 11 h ago
lizhiyaoTake it
AI on my own machineRepo

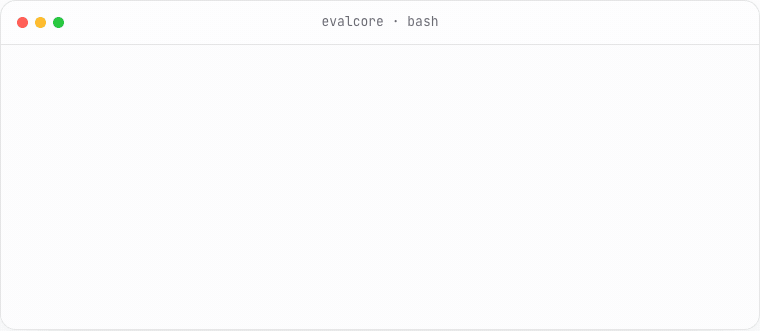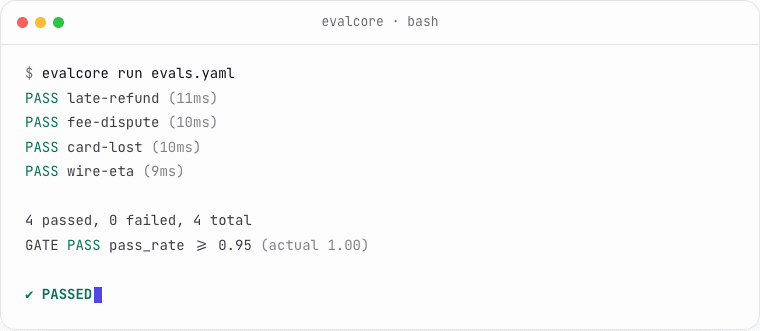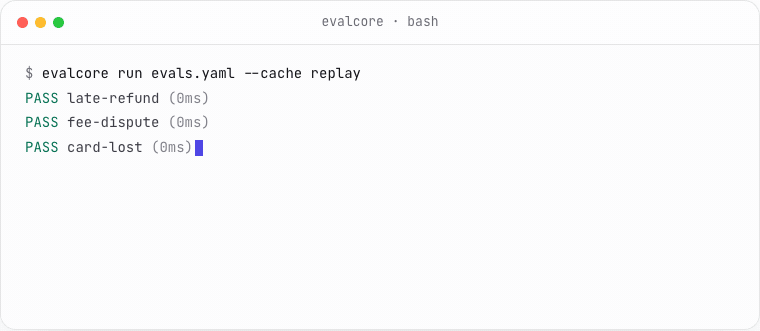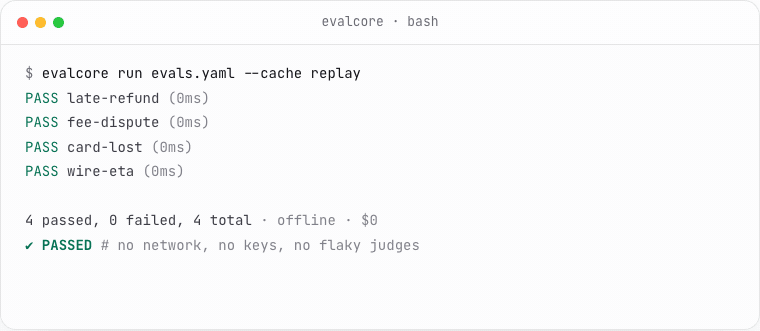
evalcore

Snapshot testing for LLM apps and agents, built to run locally and block regressions in CI.

  • 19
  • Rust
  • Apache-2.0
  • 4 mo ago
Eval-coreTake it
AI on my own machineRepo

LLM_InSight

This is my personal home rig for serious LLM experimentation. I built it to test models head-to-head, create custom evaluation rubrics, automatically improve prompts based on the previous run’s results, and generate high-quality synthetic training data. Everything runs locally first (Ollama by default), with optional cloud support. logged locally.

  • 5
  • Python
  • MIT
  • 5 mo ago
yuvhaim-gifTake it
Search GitHub and Hugging Face for evaluation-framework

Get , open it once and sign in. Then come back here and press the button again.