kyojin
Kyojin: open-source engine that runs 100 GB-class open models (GLM-5.3, Qwen3.8, DeepSeek V4.1) on one desktop machine. AMD Strix Halo, NVIDIA RTX and Apple Mac. OpenAI API, built on ExLlamaV3.
- 244
- Python
- MIT
- 2 d ago
Kyojin: open-source engine that runs 100 GB-class open models (GLM-5.3, Qwen3.8, DeepSeek V4.1) on one desktop machine. AMD Strix Halo, NVIDIA RTX and Apple Mac. OpenAI API, built on ExLlamaV3.
Image text to text model, used with transformers.
Gated access
TandemEngine: local inference that drafts and verifies its own tokens, behind an OpenAI-compatible API.
Run Qwen3.8-Flash-Next on one AMD Strix Halo (Ryzen AI Max+ 395, gfx1151). EXL3 4.05 and 3.05 bpw packs, own ROCm/HIP kernels, OpenAI-compatible server, 4 sessions of 262K context, setup guide included.
Image text to text model, used with exllamav3.
DeepSeek-V4.1-Flash on two NVIDIA DGX Sparks: EXL3 weights from the official checkpoint, upstream vLLM with our patches and decode kernels
DeepSeek-V4.1-Flash (1M context) and GLM-5.3-Flash on a BOSGAME M5 (Ryzen AI Max+ 395, Radeon 8060S, 128 GiB) with two RX 7900 XTX over OCuLink: pinned Ansible recipes and measured results. Also the M5-only Qwen and DeepSeek setups.
Qwen3.8-27B EXL3 (4.00 bpw) + DFlash2 speculative decoding for ExLlamaV3, validated at 262k context on a 24 GB RTX 3090
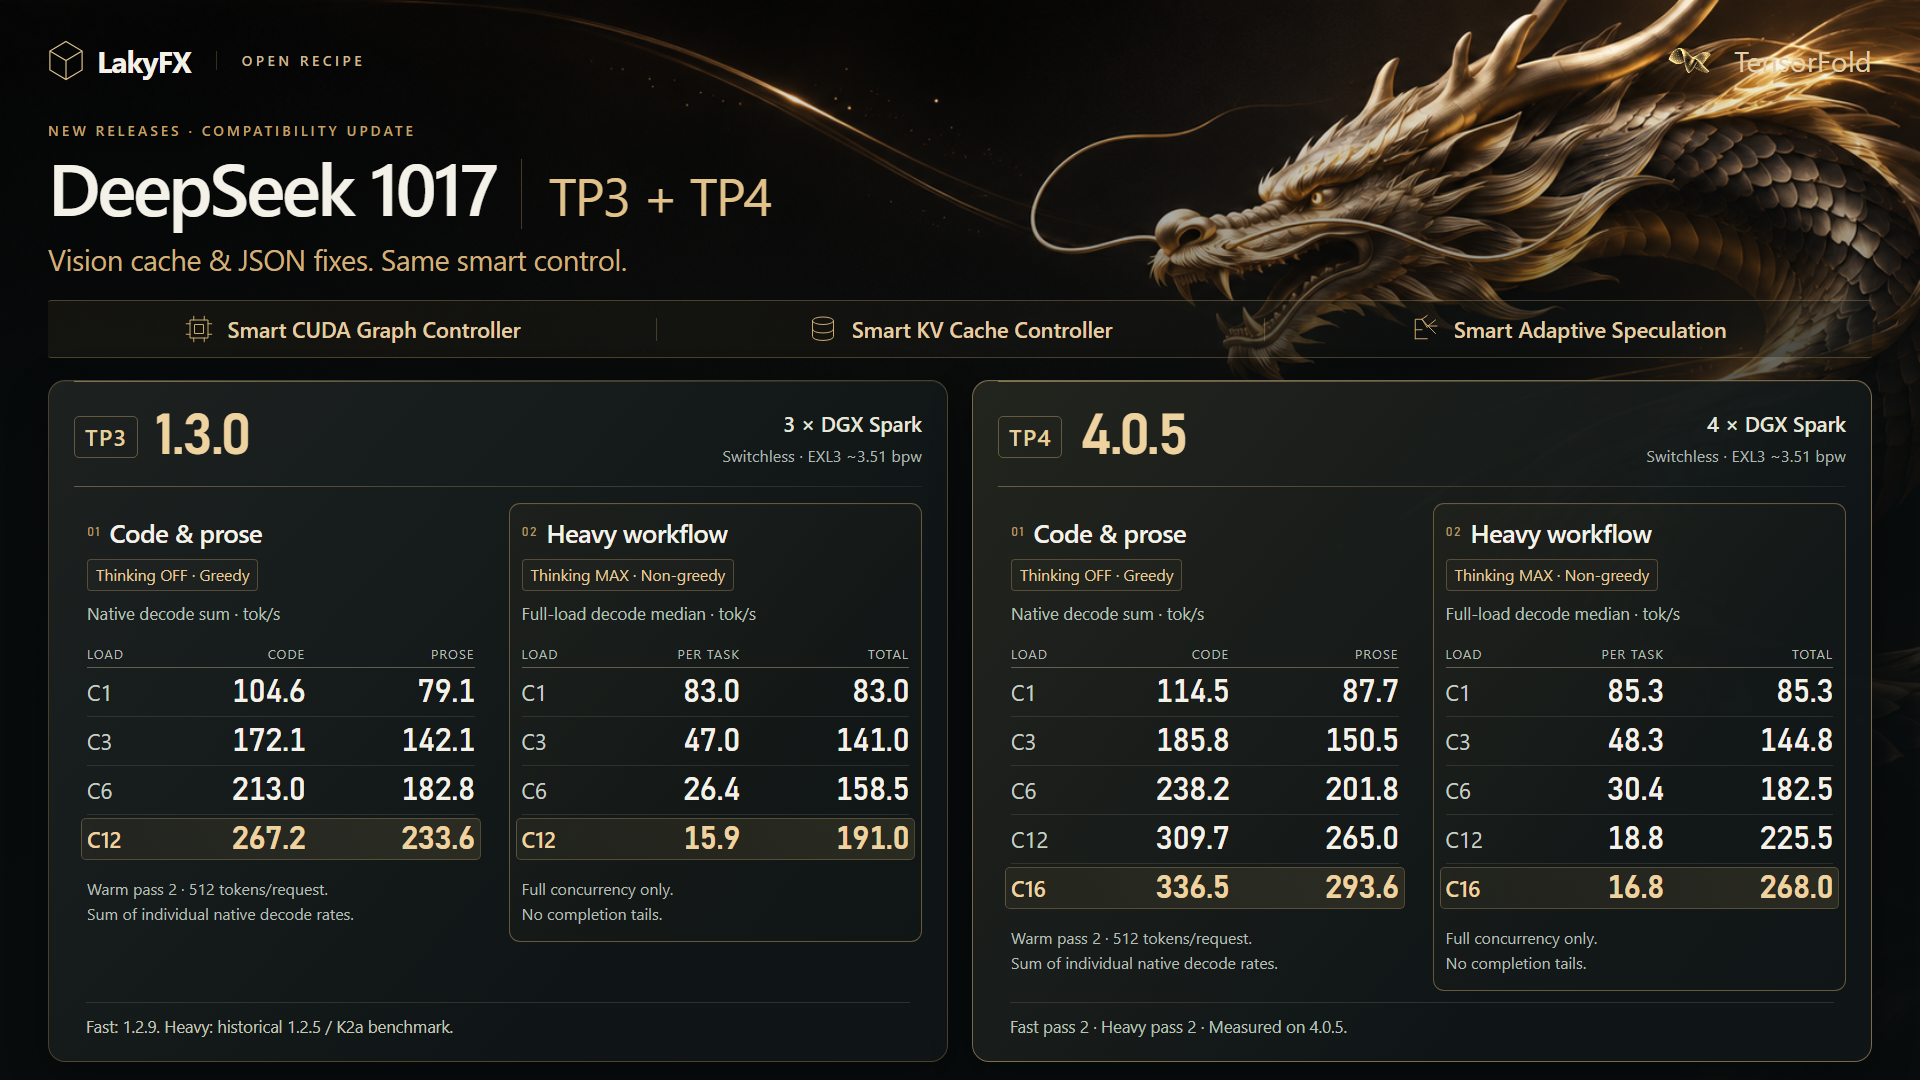
DeepSeek 1017 EXL3 on 3-4 DGX Sparks. TP4 4.0.4: 4,277 tok/s cold prefill; C16 code 331.7 / prose 287.5 native decode sum. Smart CUDA Graph, KV Cache and Adaptive Speculation controllers. C16/R48, 9M KV, 3.5 GiB checkpoints. TP3 1.2.8: up to +58% cold prefill. Exact recipes, source and benchmarks.
Reproducible 262K GLM-5.3 Flash Uncensored EXL3+DFlash2 deployment for 2x RTX PRO 6000 Blackwell
Abliterated DeepSeek-V4.1-Flash-1017, 3.84 bpw EXL3, on 3x NVIDIA DGX Spark with tensor parallelism (TP3). TensorFold engine, deploy scripts, OpenAI-compatible API, benchmarks. 3,816 tok/s prefill.
Expert pruning of two MoE models for one owner's traffic, so both fit on one DGX Spark: DeepSeek V4 Flash 95 to 70 GiB with no loss in review, and Qwen3.6-35B-A3B at 208 of 256 experts with vision, side by side. A finished record, with the negative results.
TensorFold v0.6.0 GLM-5.3-Flash engine generalized from 2 to 4 DGX Sparks (TP4) over a switchless RoCE fiber ring - uncensored EXL3 checkpoint, overlay + tooling. Upstreams: ashhart/TensorFold, MiaAI-Lab 2x-Spark stack, alexellis/switchless-nccl.
GLM-5.3-Flash on two DGX Sparks with TensorFold v0.6.7: the root-caused, bit-exact HC row-split fix, RoCE all-gathers for decode, per-step latency instrumentation, and a working 2-rank NCCL config over a direct CX7 link. Upstreams: ashhart/TensorFold, MiaAI-Lab 2x-Spark stack, alexellis/switchless-nccl.
vLLM EXL3 runtime for GLM-5.3-Flash on DGX Spark / GB10 (SM121): fused EXL3 MoE kernels, DFlash2 speculative decoding, measured receipts