vllm
A high-throughput and memory-efficient inference and serving engine for LLMs
- 97k
- Python
- Apache-2.0
- 5 h ago
A high-throughput and memory-efficient inference and serving engine for LLMs
SGLang is a high-performance serving framework for large language models and multimodal models.
TensorRT LLM provides users with an easy-to-use Python API to define Large Language Models (LLMs) and supports state-of-the-art optimizations to perform inference efficiently on NVIDIA GPUs. TensorRT LLM also contains components to create Python and C++ runtimes that orchestrate the inference execution in a performant way.
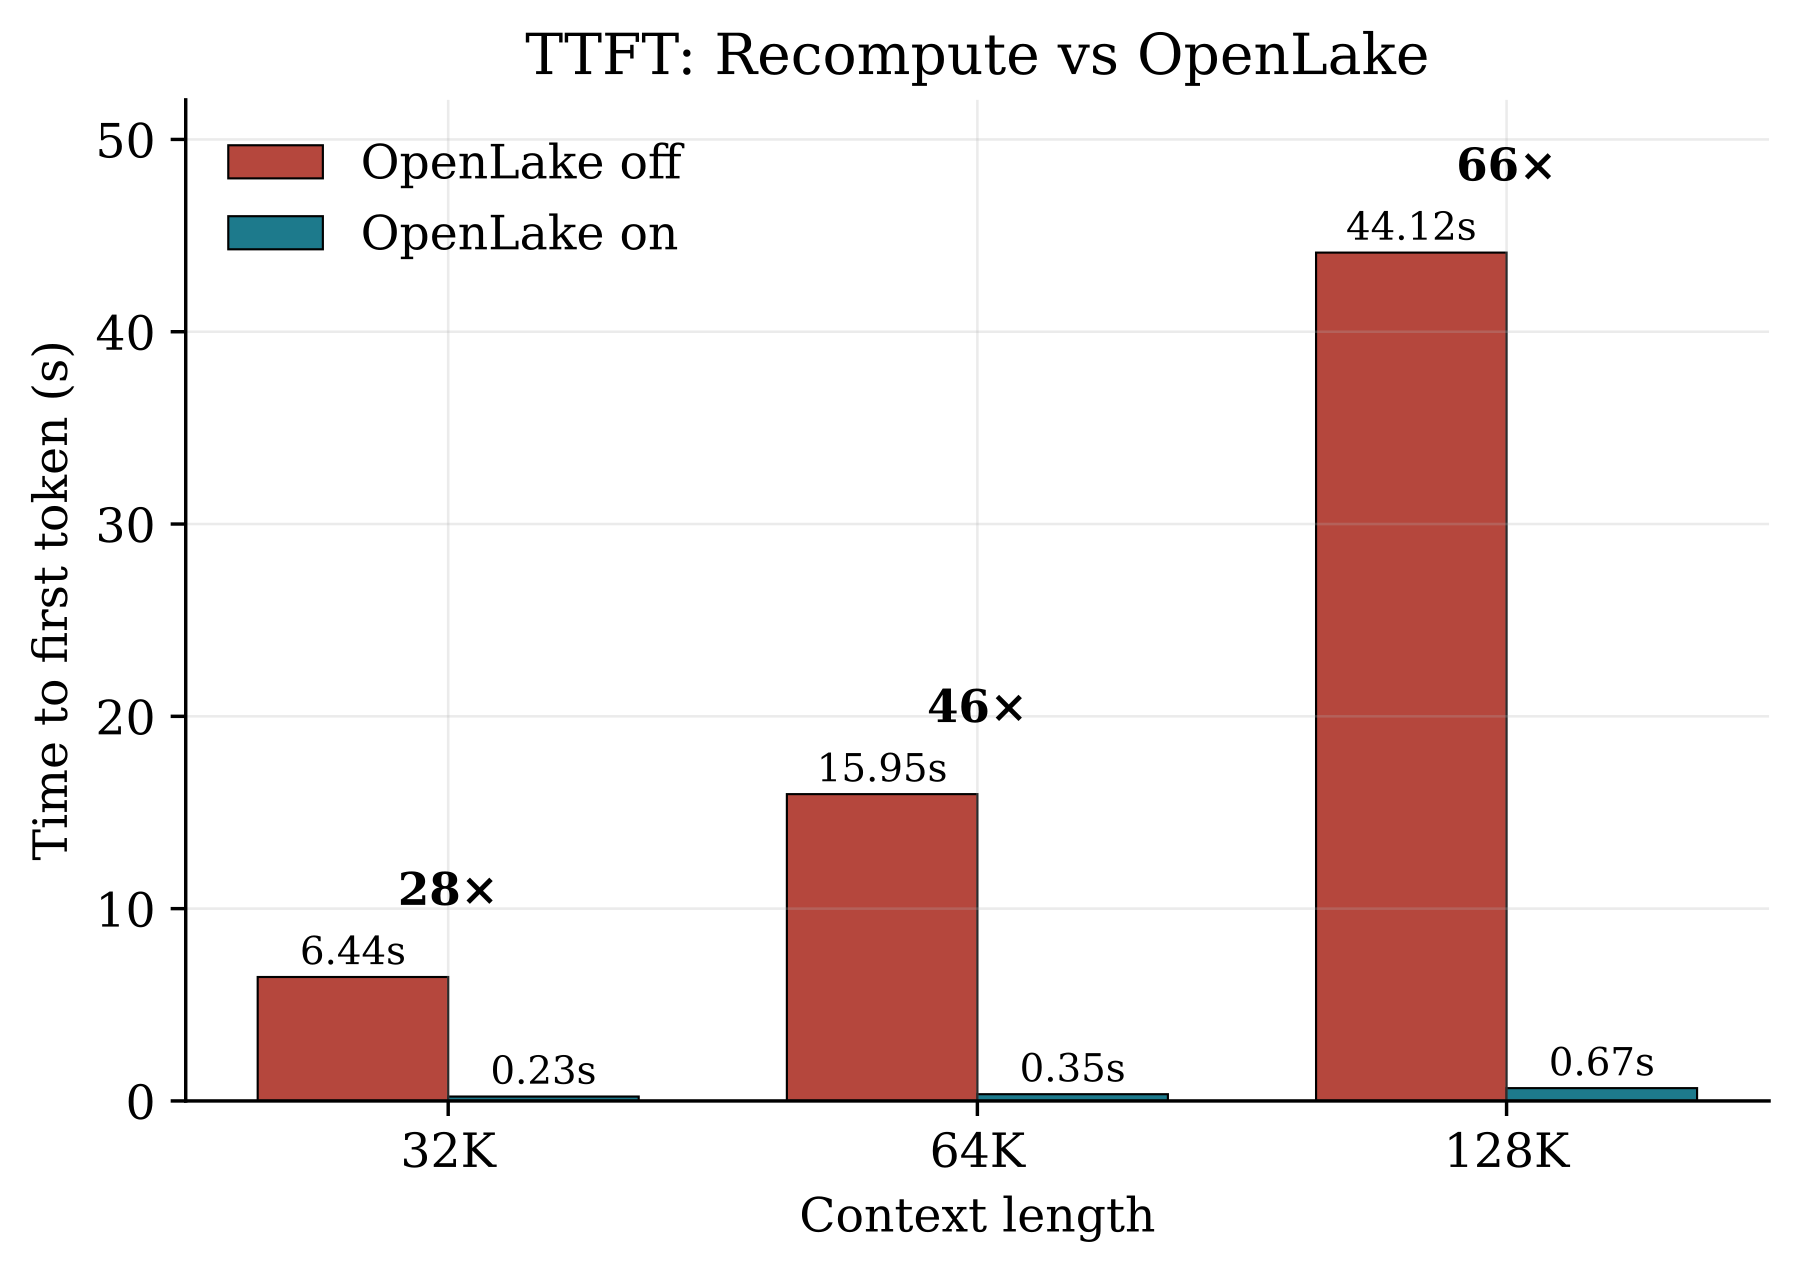
OpenLake is a high performance storage engine for efficient LLM inference and GPU Training
cuDNN Frontend is NVIDIA's modern, open-source entry point to the cuDNN library and a growing collection of high-performance open-source kernels.
Frontier MoE models on RTX PRO 6000 / RTX 5090 (sm_120): DeepSeek-V4.1-Flash on 4x RTX PRO 6000, as a GPU+CPU hybrid on 4x RTX 5090, and 2-bit experts on vLLM v0.24.0
Fully uncensored, capability-enhanced abliteration of Qwen3.6-27B. NVFP4 + z-lab DFlash speculative decoding (n=12) on the unified ghcr.io/aeon-7/aeon-vllm-ultimate:latest container, tuned for long-context draft acceptance on DGX Spark. 6 HF variants (BF16/NVFP4/MTP/MTP-XS), docker-compose, and QuickStart.
Strata fork: Qwen3.8-Flash-Next 125B MoE in NVFP4 on one RTX 20-50 card (12 GB+) and 64 GB of RAM or more. Setup installs our GPTQ quants (huihui abliterated, OrcaRouter) from Hugging Face. CPU experts on AVX-512 or AVX2 (+AVX-VNNI), all experts in RAM from 92 GB, a low-RAM mode below, vision, W4A8 prompts. Windows / CUDA 13.
Text generation model, used with transformers.
Optimized SGLang runtime for Qwen3.8-27B FP8 with DFlash2 and Qwen3.8 Flash-Next NVFP4 with FR-Spec on one NVIDIA RTX PRO 6000 Blackwell 96 GB GPU (SM120): 524K context, HiCache and NIXL.
Native Rust inference server for open models on NVIDIA and Apple Silicon. OpenAI- and Anthropic-compatible APIs, GGUF + safetensors + MLX, FP8/NVFP4/MXFP4/Q8/Q4, built-in Studio
NVIDIA Sol-Attn for ComfyUI / Triton kernel on SM89 - SM121, with zero-copy MiniMax H3 nodes: memory-efficient attention, scheduled tau with graph preview, and feed-forward chunking. Measured 1.14–1.44× vs SageAttention and −37% MLP peak VRAM on H3
GLM-5.2-NVFP4-REAP-469B serving on SM120 (4× RTX PRO 6000 Blackwell) — one-command vLLM launch recipe, 250K context, DeepSeek Sparse Attention + MTP speculative decode
Text generation model, used with transformers.
Bleeding-edge ComfyUI for NVIDIA DGX Spark (GB10/Blackwell/sm_121a). CUDA 13 + SageAttention v3 (sm_121a) + NVFP4 + 14 custom-node packs + Flux 2 Dev / LTX 2.3 22B / ACE-Step v1.5 XL Turbo pre-bundled with abliterated text-encoder paths.
Run large AI chat models privately on your own NVIDIA RTX 50 or RTX PRO graphics card. On one RTX 5090, Qwen3.8-27B writes about 70 words per second, 1.4x faster than vLLM. Even a model almost four times larger than the card's memory runs. Works with apps made for ChatGPT or Claude. Starts with one docker command.
Text generation model, used with llama.cpp.
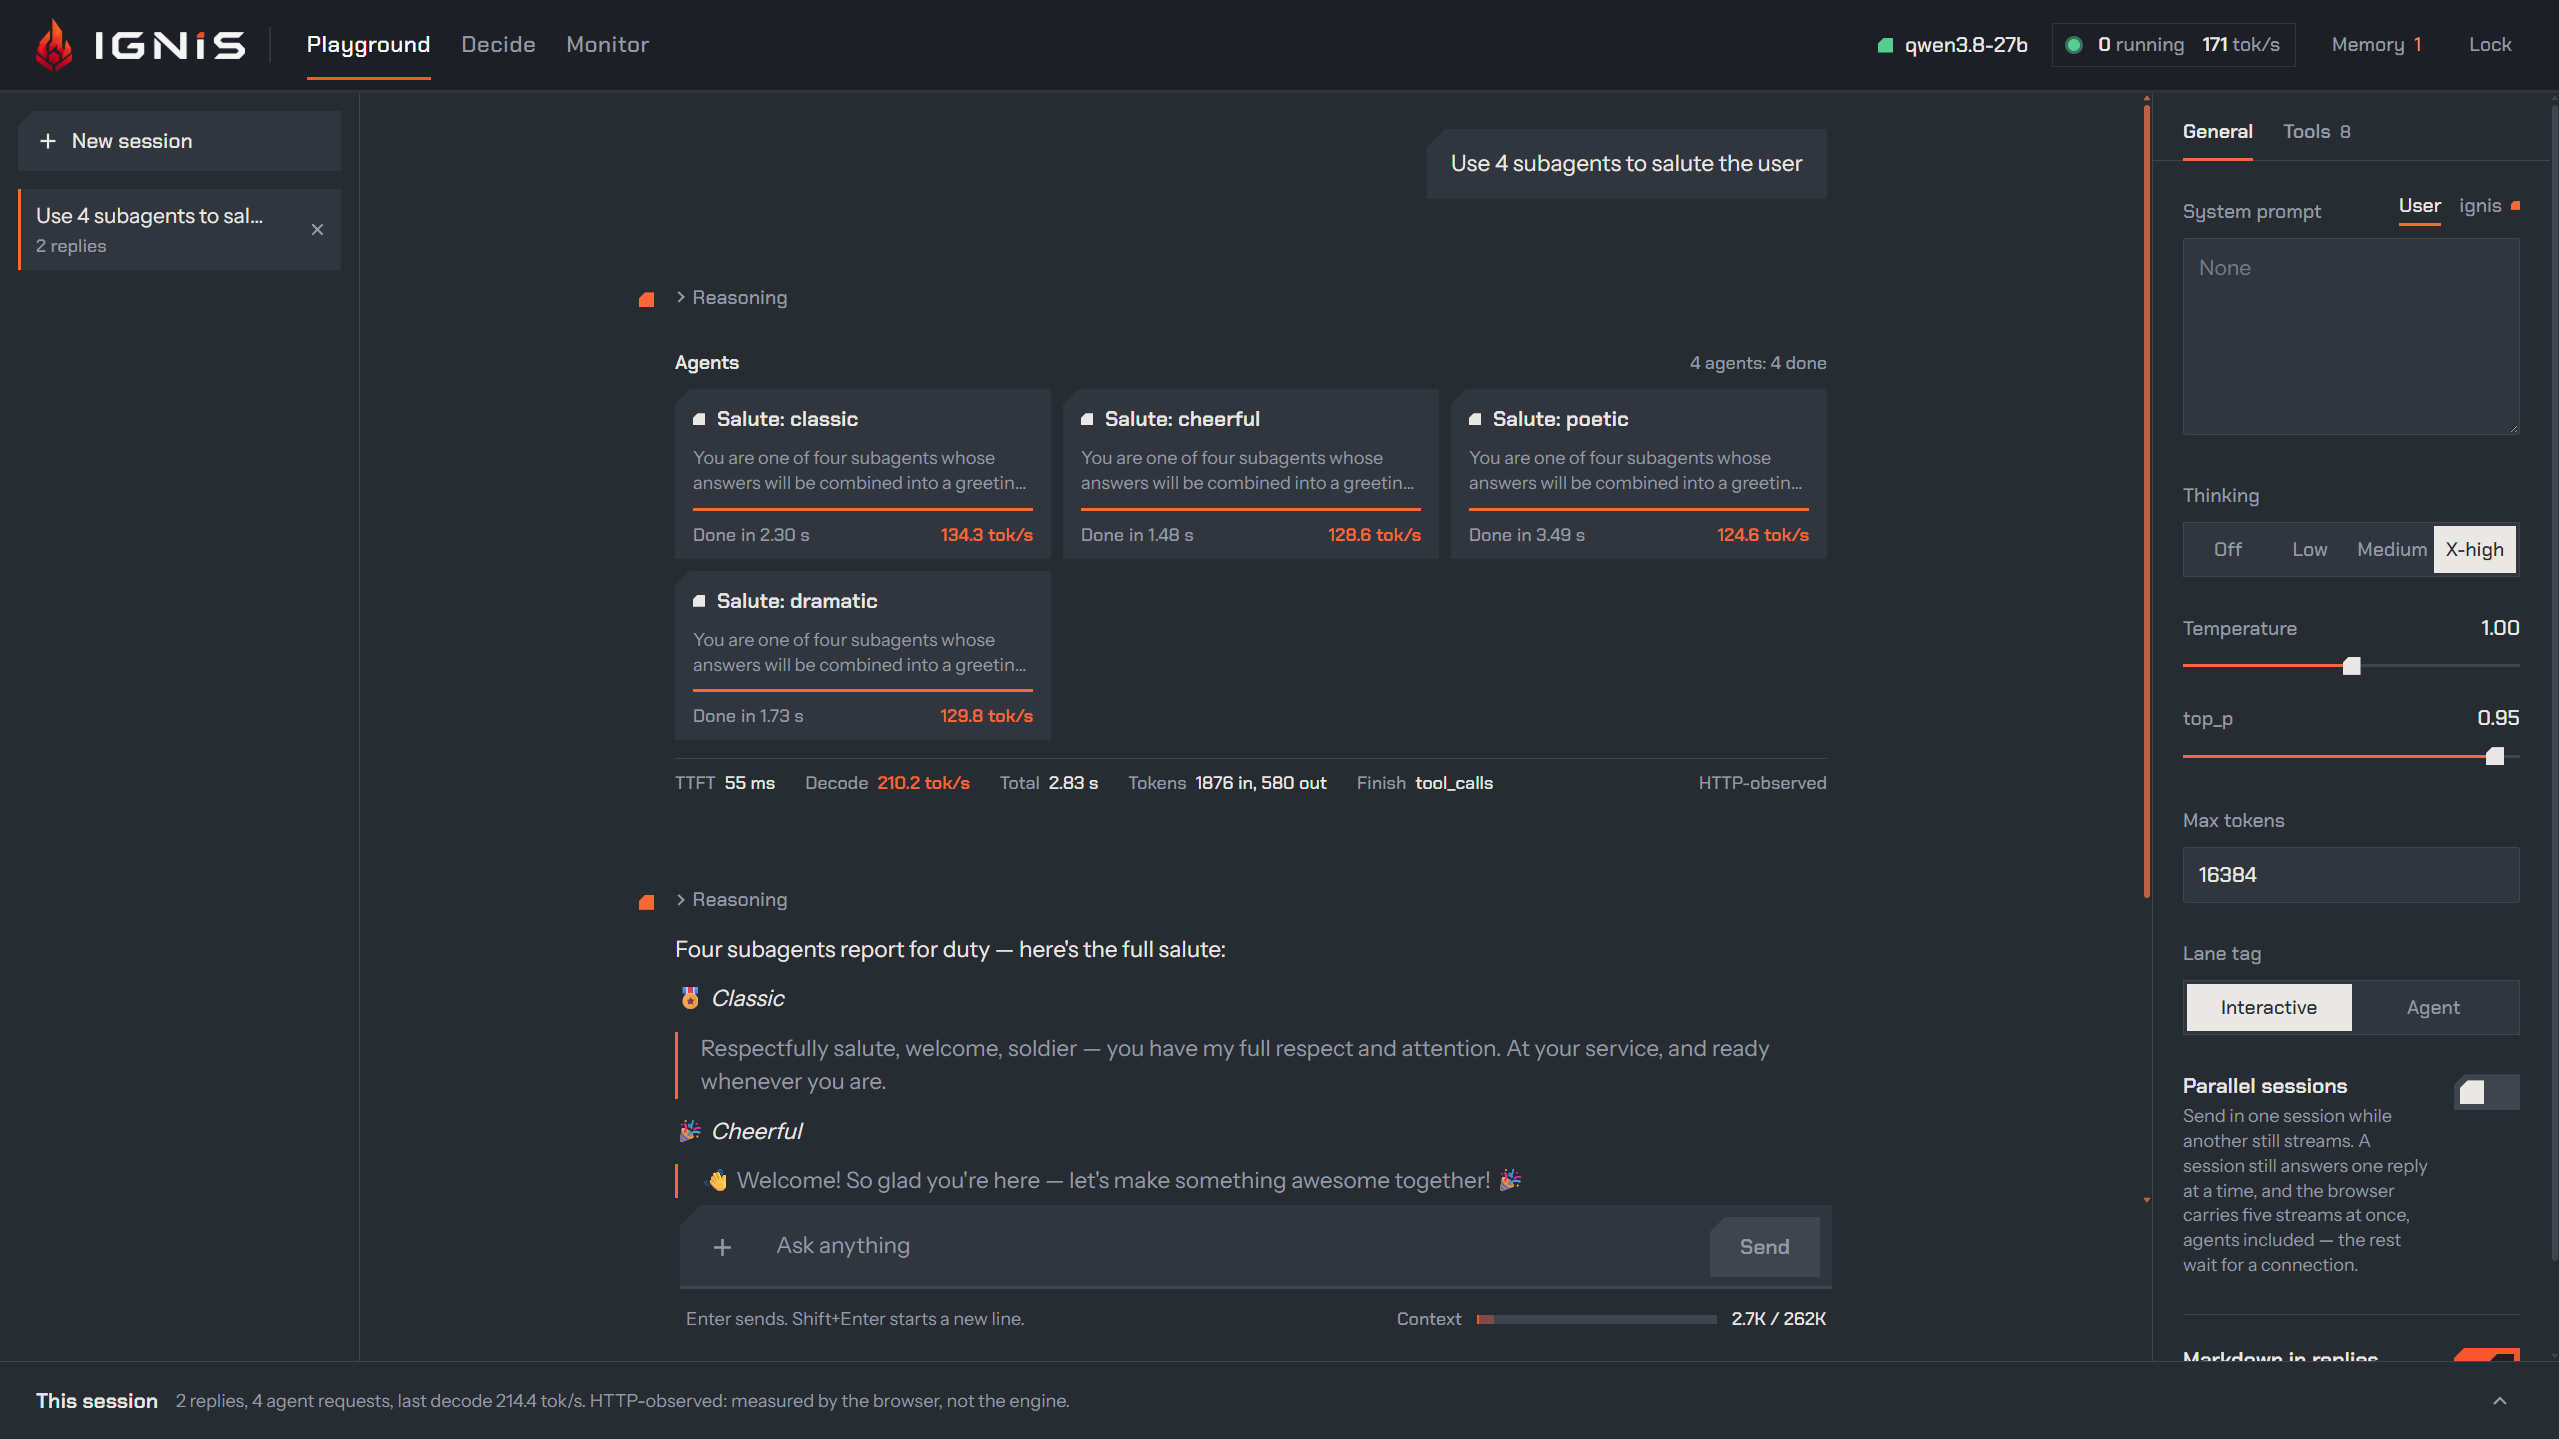
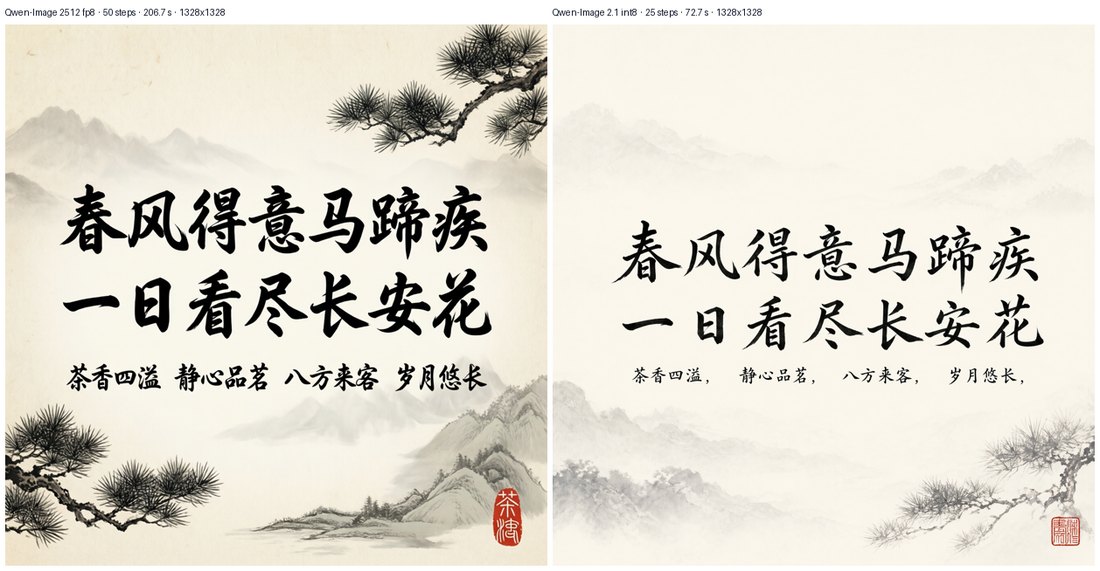
An inference engine for NVIDIA RTX card card family, built for a coding agent and its subagents, and a companion that listens, reads and draws: Qwen3.8 27B and 125B Flash-Next MoE, Qwen-Image-2.1, Qwen3-ASR on the CPU. OpenAI-compatible API and Playground in one binary.
Image text to text model, used with transformers.
Text generation model, used with vllm.
Abliterated DeepSeek-V4.1-Flash-1017 (FP8 dense, FP4 experts) on 4x RTX PRO 6000 with vLLM-Moet r21, DSpark + FLy verification and top_p 1.0: 463 tok/s single-stream agent decode at 30k-120k context, 1082 tok/s over 8 streams, 1M context, Flex-start GCE VM
DFlash vLLM for DGX Spark — Plug & Play Block-Diffusion Speculative Decoding
Cross-platform FlashAttention-2 Triton implementation for Turing+ GPUs with custom configuration mode
Lynn 原生 LLM 推理引擎 · W4A8/NVFP4 量化 · 自写 CUDA/Triton kernel · MoE · 投机解码 | Lynn-native LLM inference engine for NVIDIA Blackwell
RTX 5090 Laptop (24GB) + ComfyUI: 12 model lines / 21 measured configs — MiniMax H3, Wan 2.2, Qwen-Image 2512, HunyuanVideo 1.5, FLUX.2 Klein, Z-Image-Turbo, LTX-Video, ACE-Step 1.5, YuE2, Stable Audio 3, Hunyuan3D 2.1, ERNIE-Image. A controlled A/B proves NVFP4 beats INT8. Bilingual 中文/English, licence-verified.
Qwen3.8-27B on RTX 5090 Laptop 24GB — TWIN-TURBO NVFP4 (native llama.cpp) vs Coder390 Q3 LynnStyle (.ninfer + NInfer engine in WSL2/Docker): 86 tok/s decode, 262K context, C4 aggregate 228 tok/s. Every number a controlled measurement.
LLM fine-tuning with LoRA + NVFP4/MXFP8 on NVIDIA DGX Spark (Blackwell GB10)
One command spins up Qwen3.8-27B (abliterated, NVFP4) on a rented Blackwell GPU at ~150 tok/s and wires it into your local coding agent via a fixed local proxy URL.
Reproducible recipe: serve abliterated Gemma-4-12B (gemma4_unified) at 50-118 tok/s on no-NVLink Blackwell (SM120) via vLLM nightly + ModelOpt FP8/NVFP4 + MTP spec-decode.
Reproducible 262K GLM-5.3 Flash Uncensored EXL3+DFlash2 deployment for 2x RTX PRO 6000 Blackwell
Rust-native MoE inference runtime with custom CUDA kernels for Blackwell GPUs. Includes DFlash speculative decoding, multi-tier Engram memory, and entropy-adaptive routing. Targets Qwen3.5-35B-A3B on a single RTX 5060 Ti 16GB.
Lna-Lab production pipeline: GGUF -> modelopt-format NVFP4 + working MTP head for vLLM on RTX PRO 6000 Blackwell (SM120). Stages 2 (NVFP4) and 3 (MTP graft) are Lna-Lab originals; stage 1 (GGUF->bf16) reuses li-yifei/gguf-to-nvfp4.
Experimental DDTree-on-vLLM research track for Qwen3.6 AEON Ultimate on DGX Spark / GB10.
AEON vLLM Ultimate RTX — vLLM 0.27.1 from source for RTX 5090 / Blackwell sm_120 / NVFP4. NOT for DGX Spark / GB10 / sm_121a.
EAGLE E4B speculative decoding drafter for Gemma 4 31B DECKARD HERETIC Uncensored NVFP4 — optimized for NVIDIA DGX Spark
The only deployed sparse FP4 GEMM on SM120: beats CUTLASS 80b on every shape, wins end-to-end request latency in 81 of 112 serving regimes vs dense NVFP4.
Optimized SM121 vLLM container and benchmark report for nvidia/diffusiongemma-26B-A4B-it-NVFP4
Nemotron Puzzle 75B-A9B NVFP4 on 1× DGX Spark (GB10): MTP, prefix cache, 4 concurrent seqs — ~40 tok/s solo, ~75 tok/s aggregate ×4