Mage
- 1.8k
- Python
- MIT
- 3 wk ago
A Flow Matching-based Text-to-Speech Model with Emoji-driven Style Control
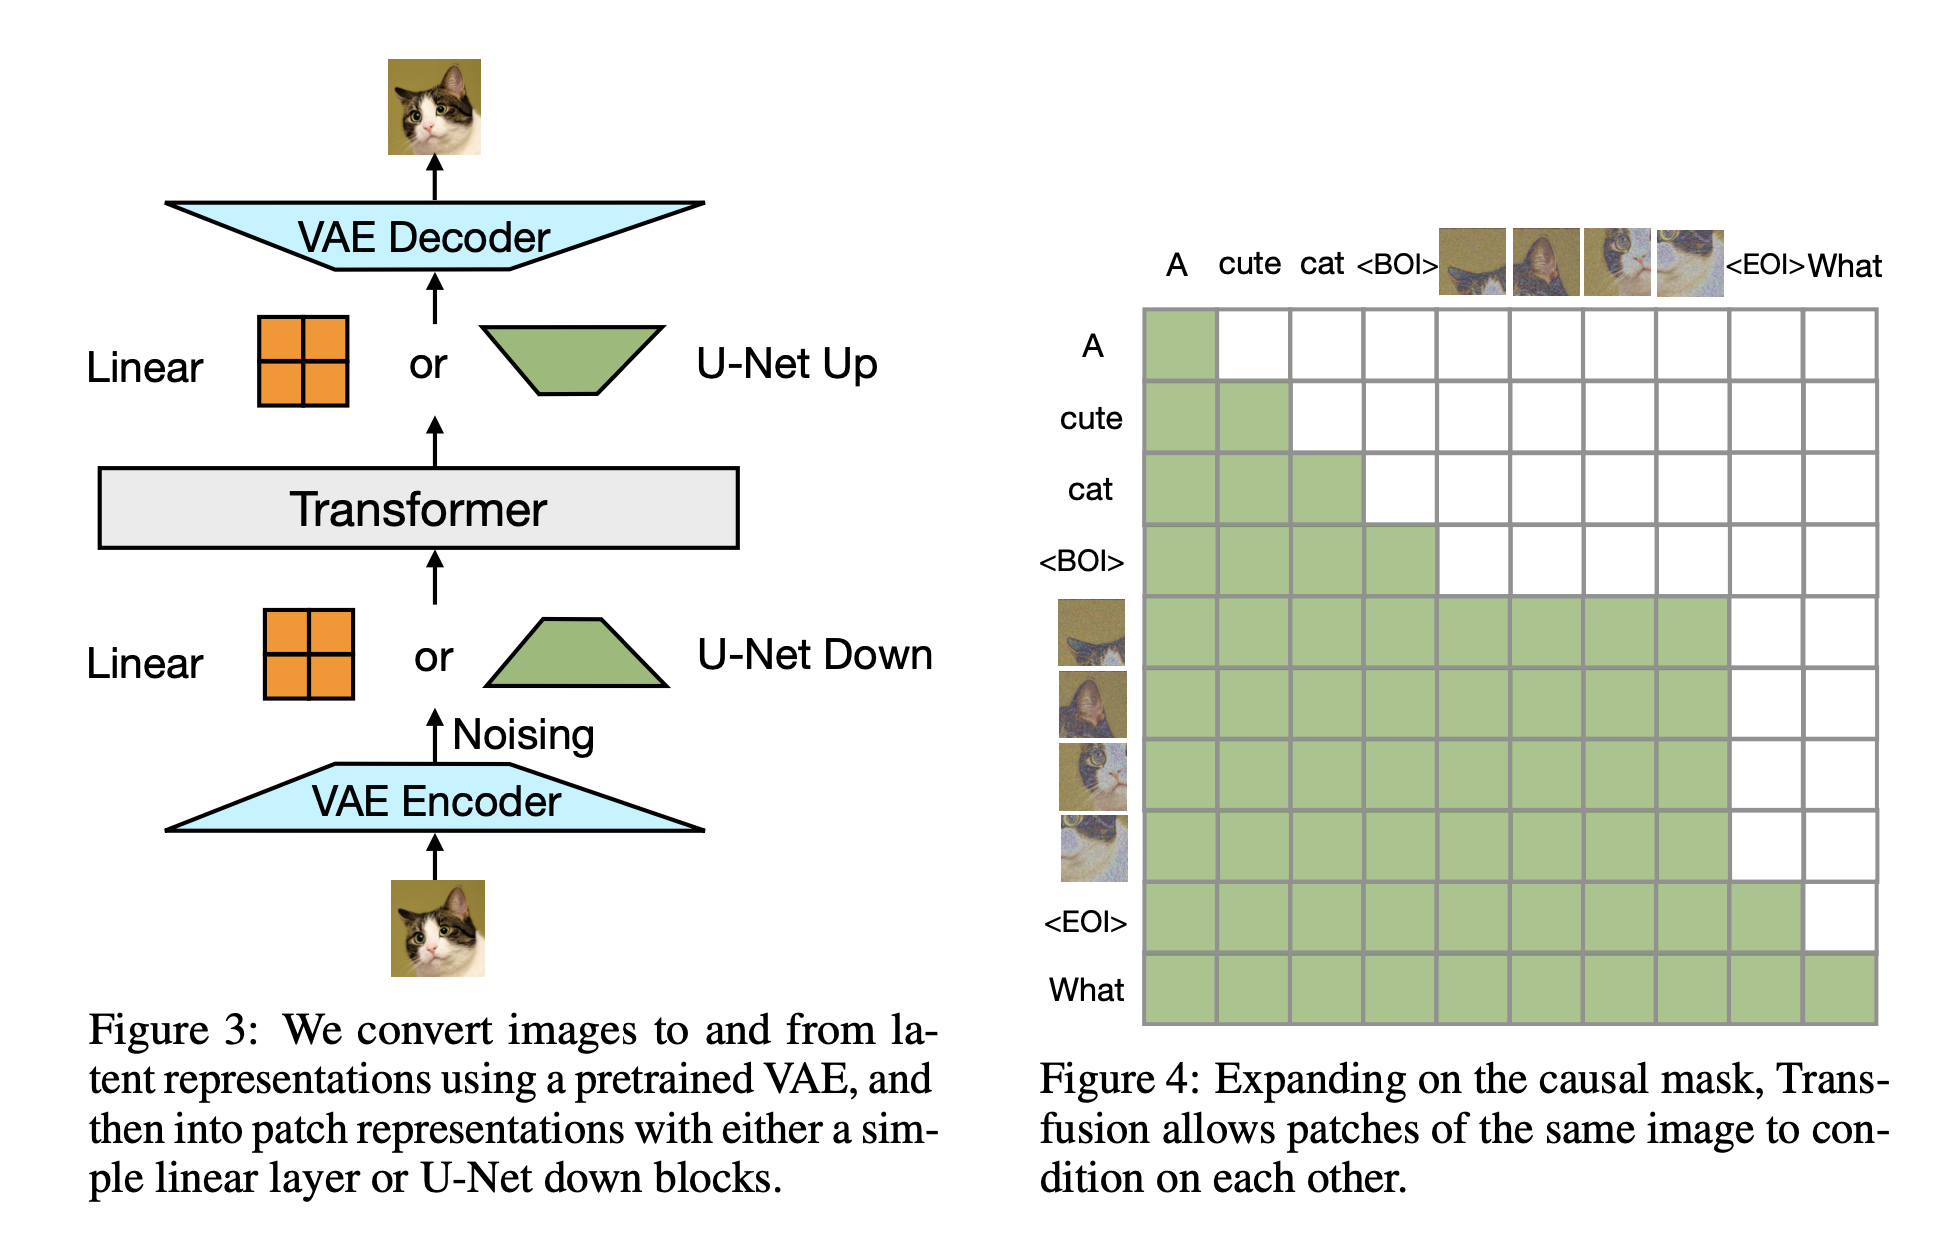
Pytorch implementation of Transfusion, "Predict the Next Token and Diffuse Images with One Multi-Modal Model", from MetaAI
[ICASSP 2024] 🍵 Matcha-TTS: A fast TTS architecture with conditional flow matching
[ICLR 2026] TangoFlux: Super Fast and Faithful Text to Audio Generation with Flow Matching
[AAAI 2025, Oral] DepthFM: Fast Monocular Depth Estimation with Flow Matching
A unified framework for easy fine-tuning in Flow-Matching models
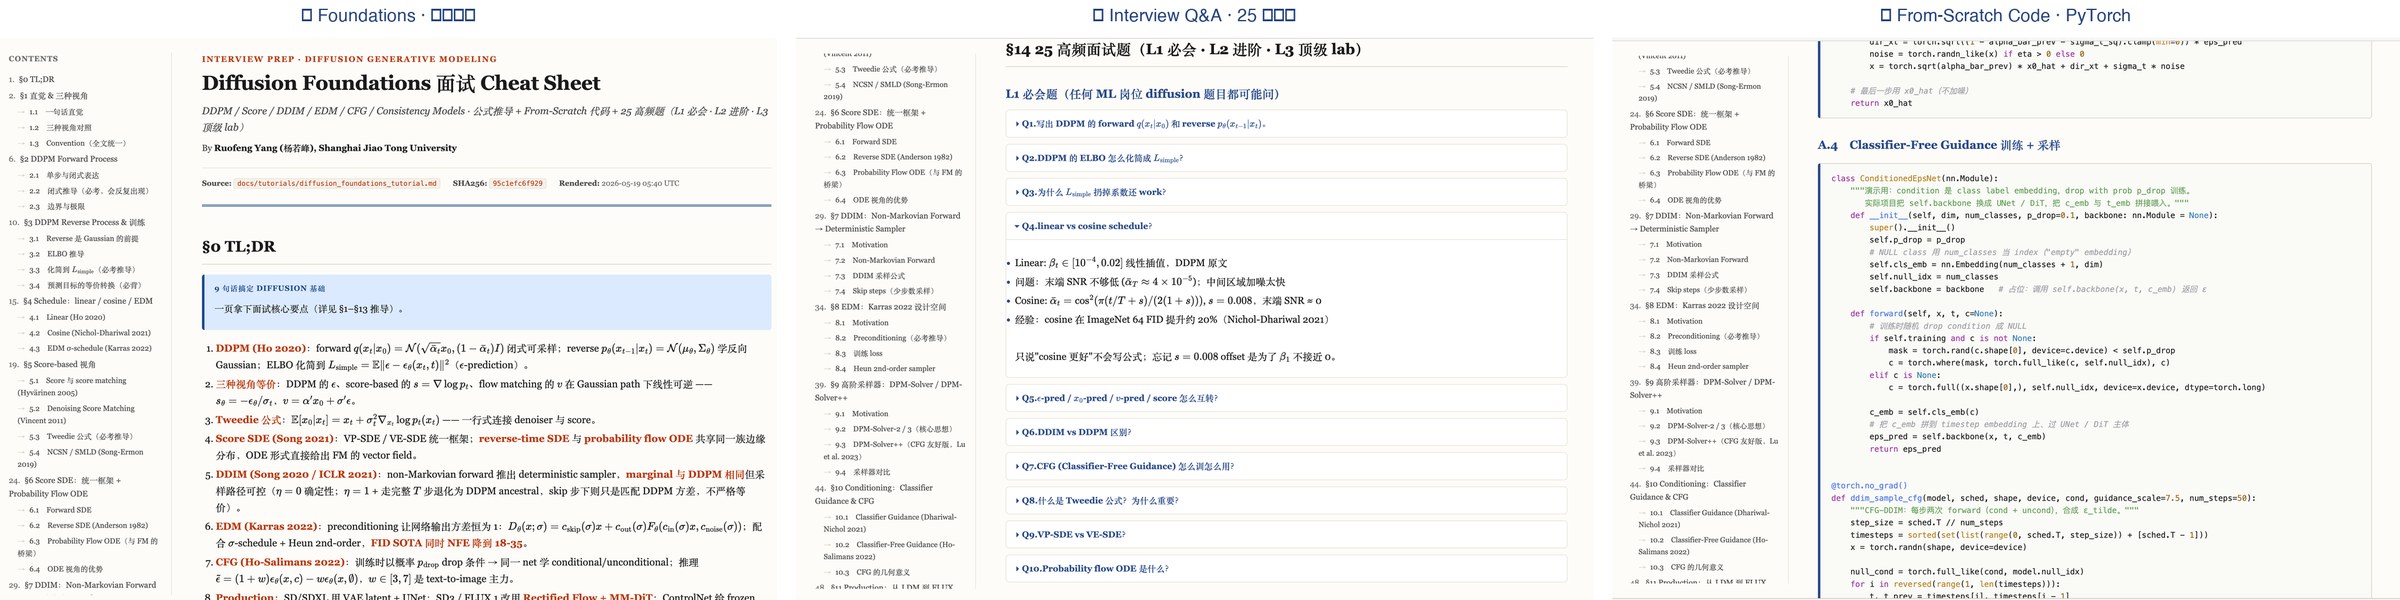
Bilingual (中文+EN) ML / LLM / diffusion / agent interview cheat sheets for AI 秋招 — generated by ARIS /interview-cheatsheet, rendered by /render-html into single-file HTML, reads anywhere — plus a CV→DBLP-fact-checked academic homepage generator and hand-authored long-form blogs 🌱
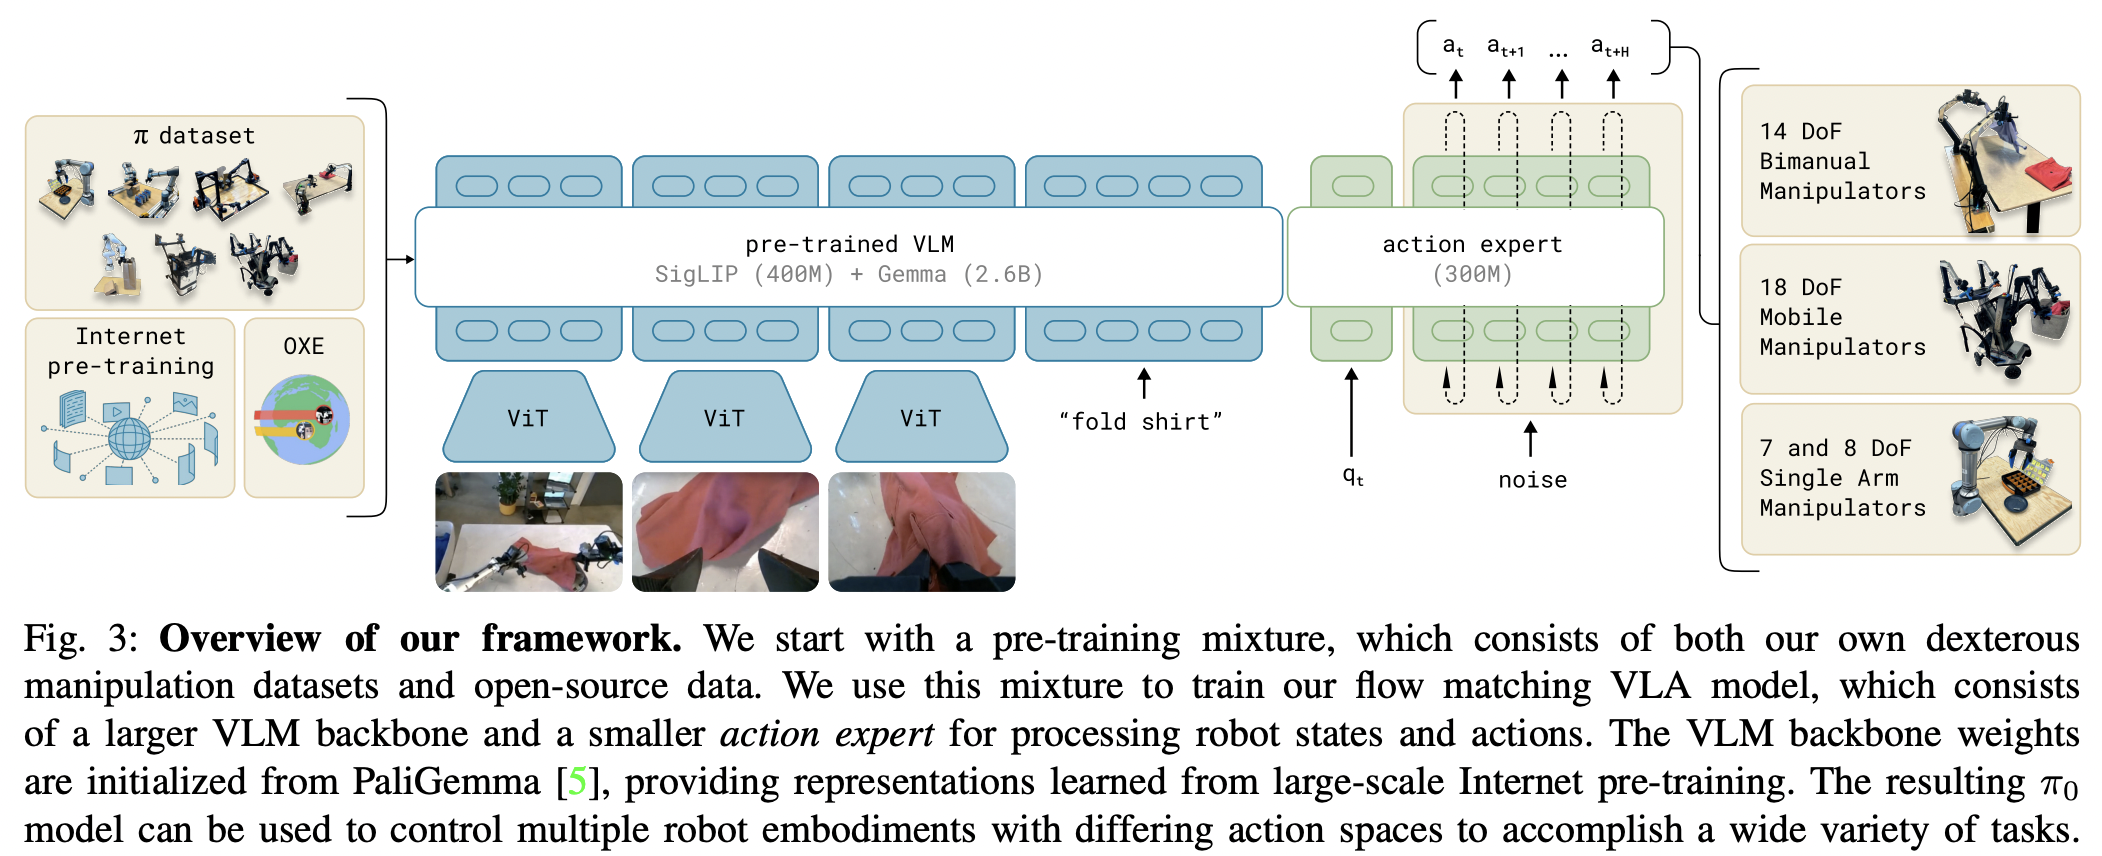
Implementation of π₀, the robotic foundation model architecture proposed by Physical Intelligence
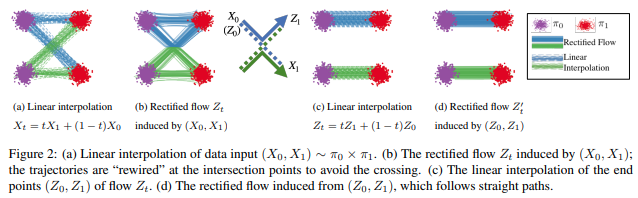
Implementation of rectified flow and some of its followup research / improvements in Pytorch
A PyTorch implementation of the paper "ZigMa: A DiT-Style Mamba-based Diffusion Model" (ECCV 2024)
[ECCV 2026] Official implementation of "HRDiT: Training-Free High-Resolution Image Generation with Off-the-Shelf Diffusion Transformer Models"
[ECCV 2024, Oral] FMBoost: Boosting Latent Diffusion with Flow Matching
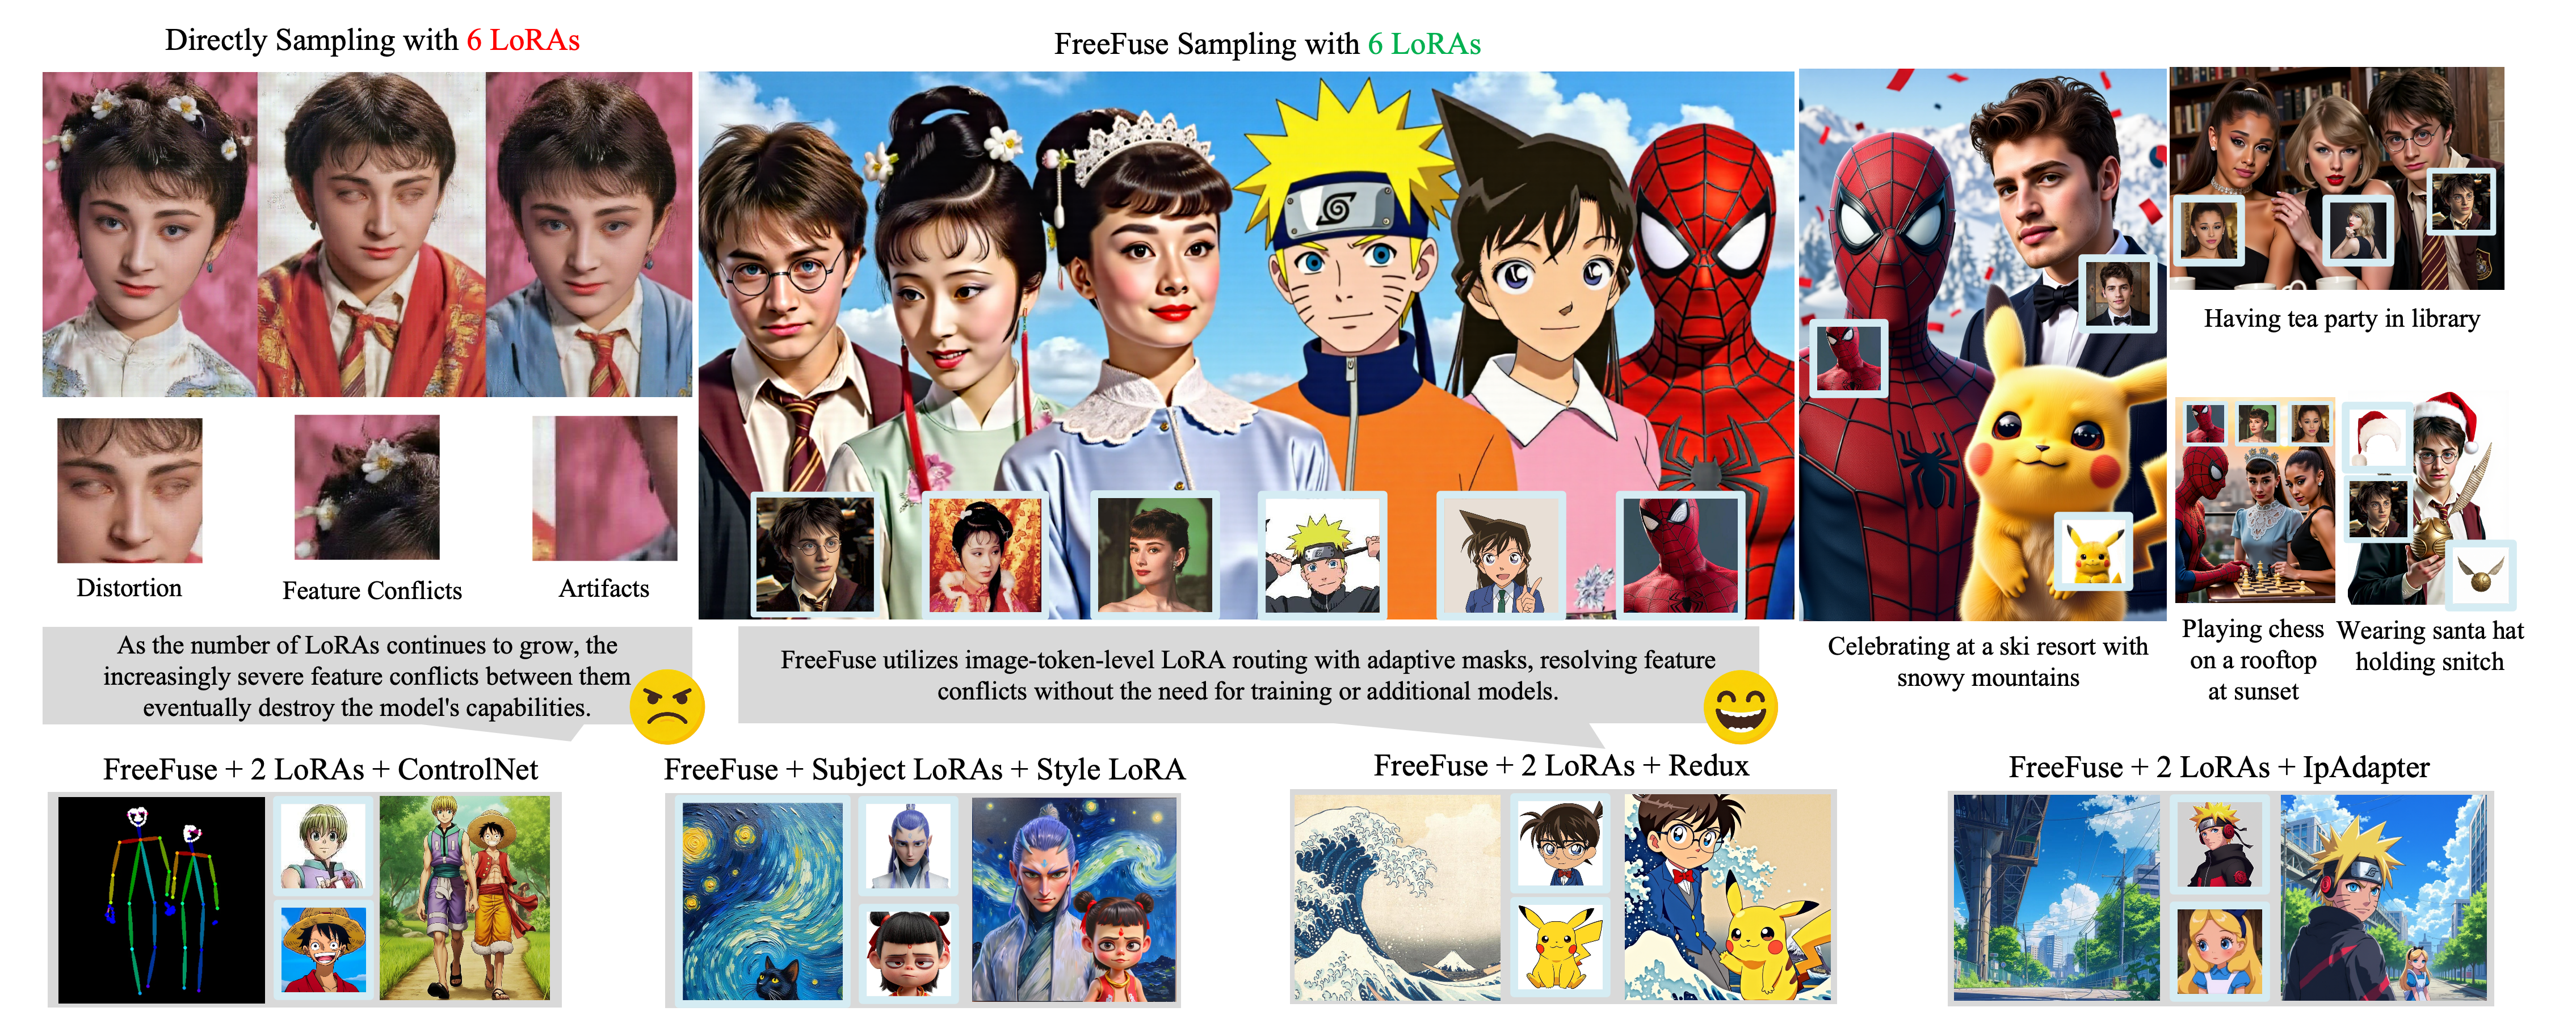
[TMLR26]FreeFuse: Multi-Subject LoRA Fusion via Adaptive Token-Level Routing at Test Time
A curated list of papers and code on efficient diffusion models for image, video, world modeling, and language generation. Covering acceleration, quantization, compression, caching, and distillation.
Generative models from scratch, progressively implemented in NumPy, C, and CUDA to uncover what ML frameworks hide.
Text-to-audio and video-to-audio using Sony AI's Woosh foundation model.
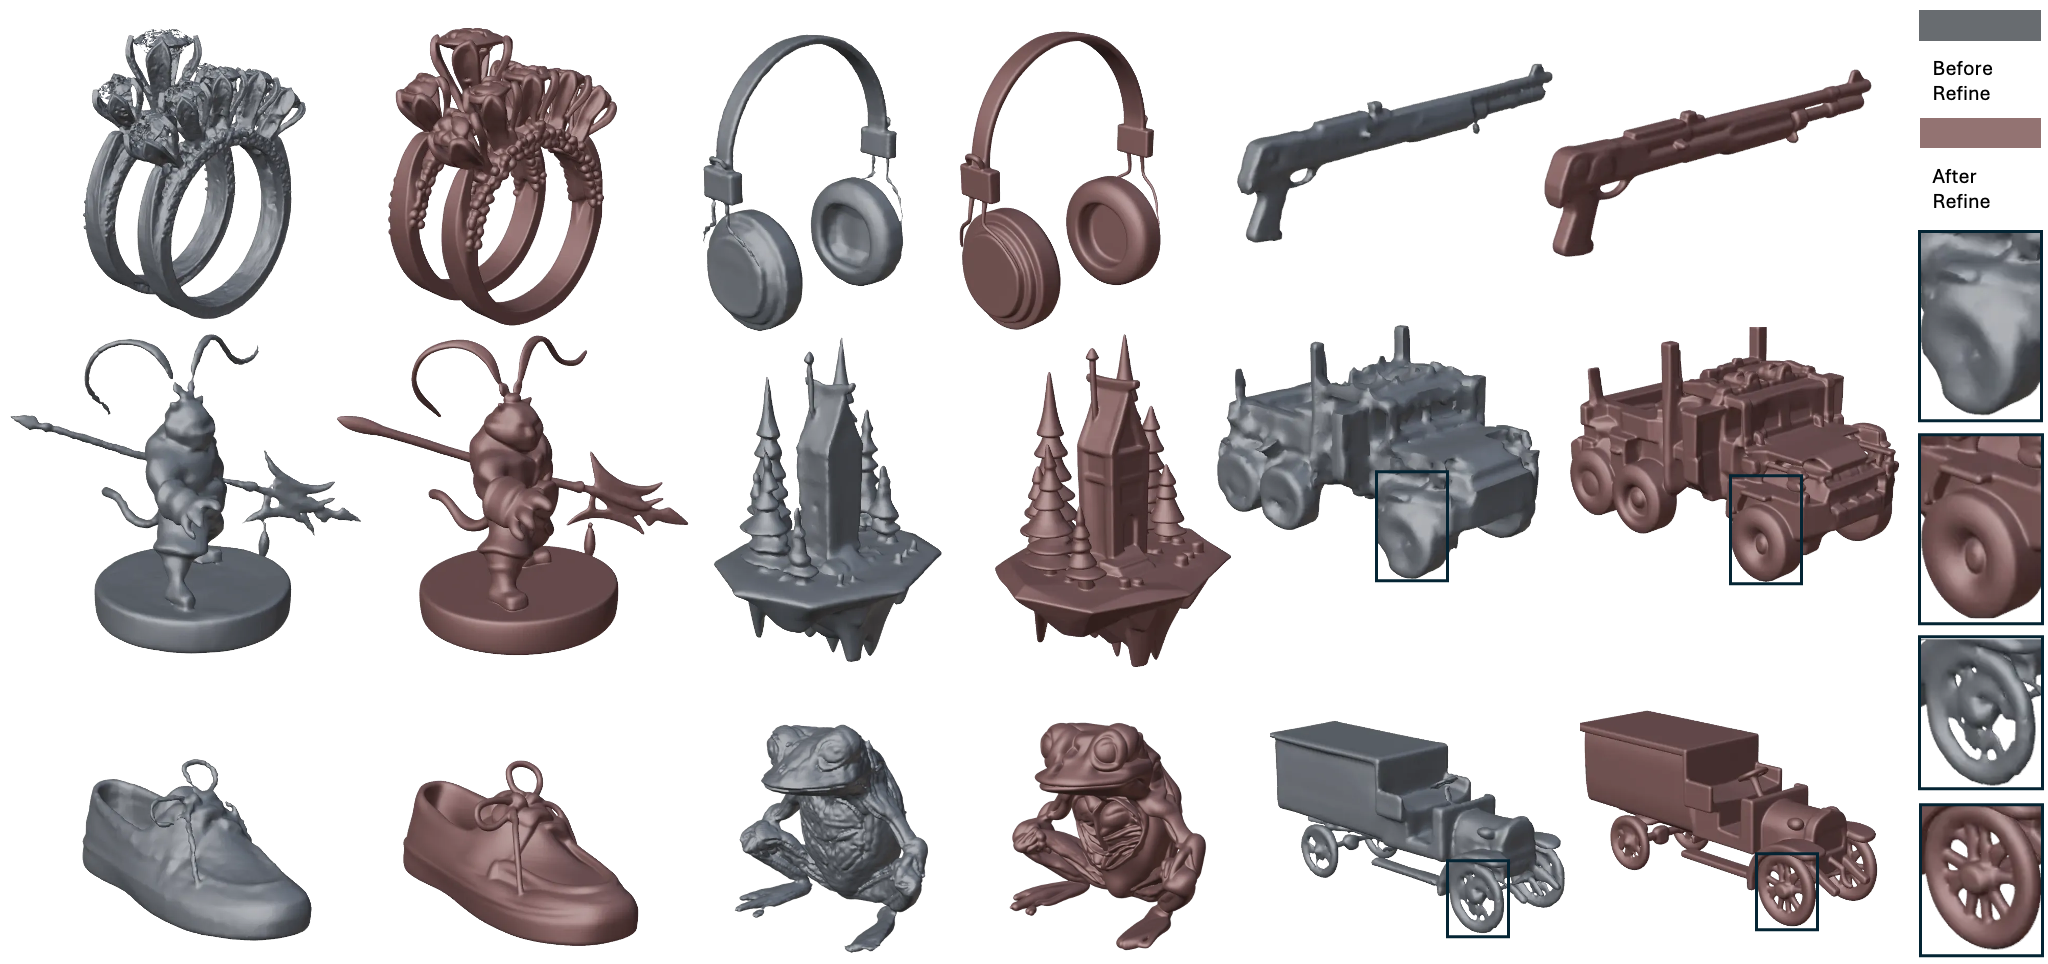
[3DV 2026] DetailGen3D: Generative 3D Geometry Enhancement via Data-Dependent Flow
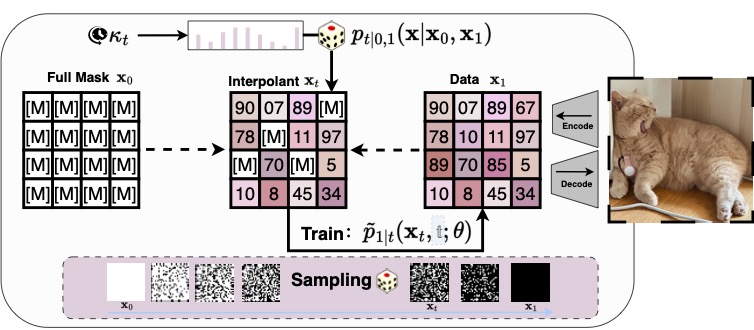
The official implementation of "[MASK] is All You Need"
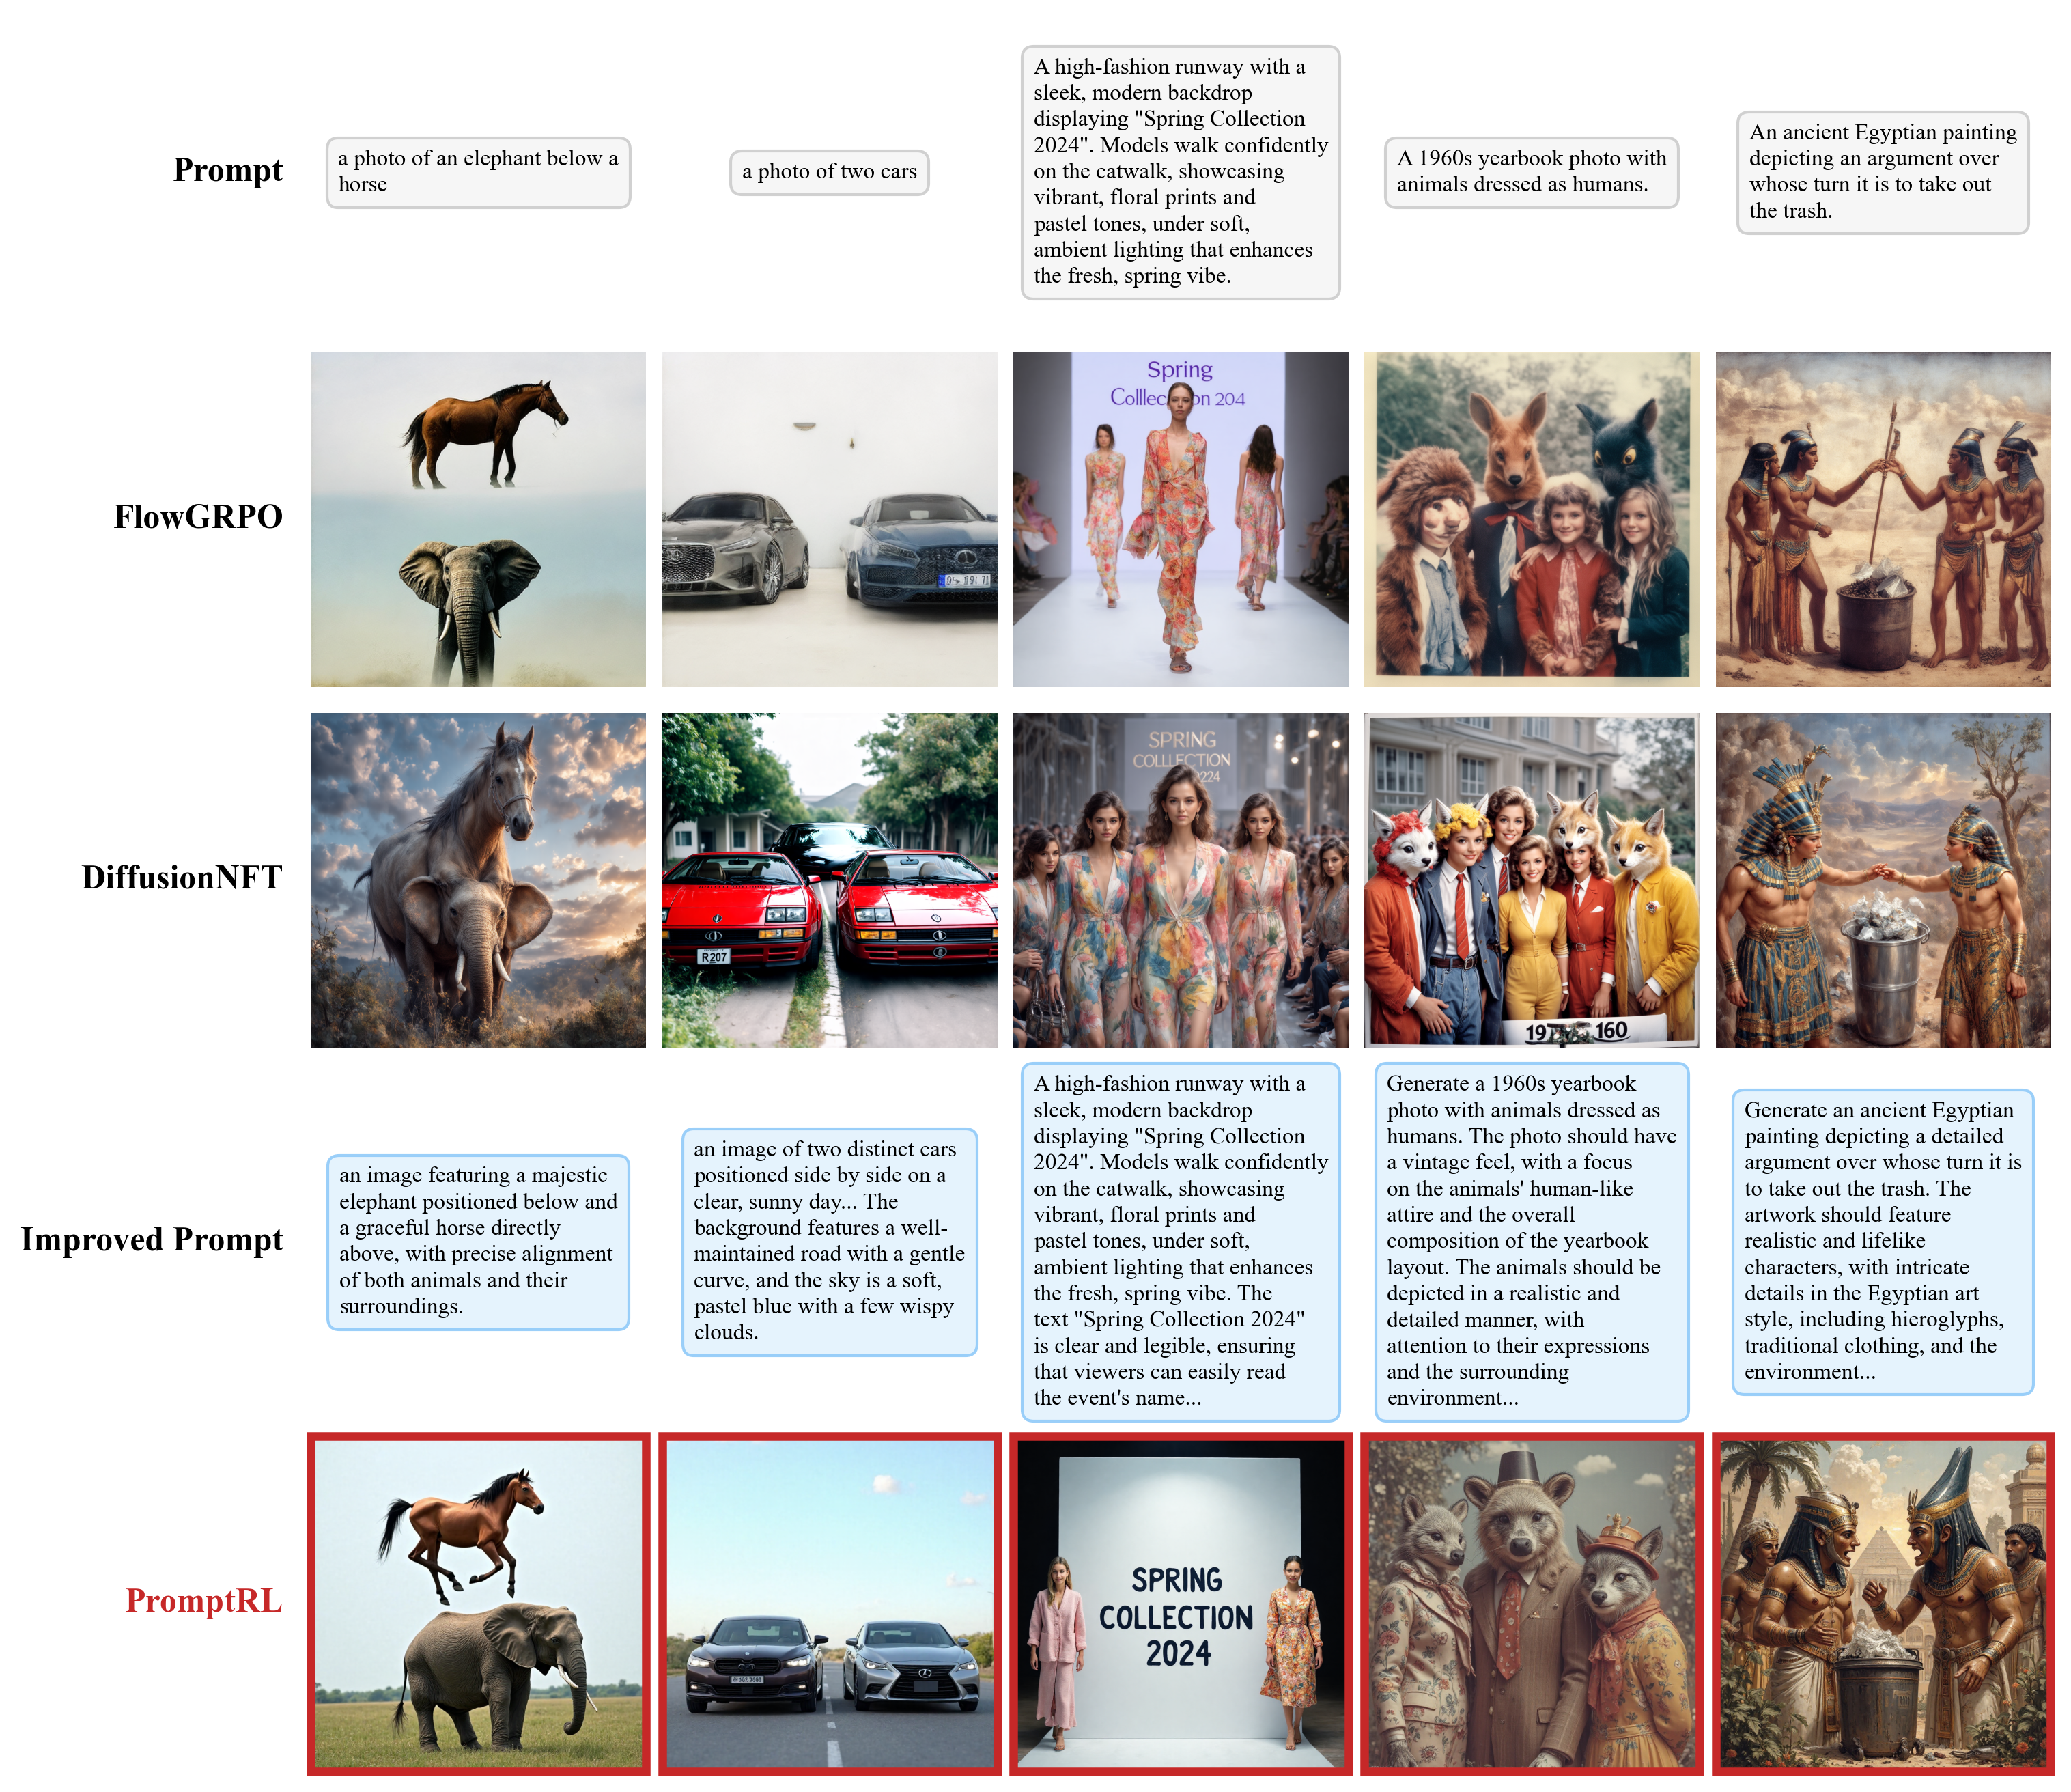
[ICML 2026] a unified reinforcement learning toolbox for joint RL on language models and diffusion models
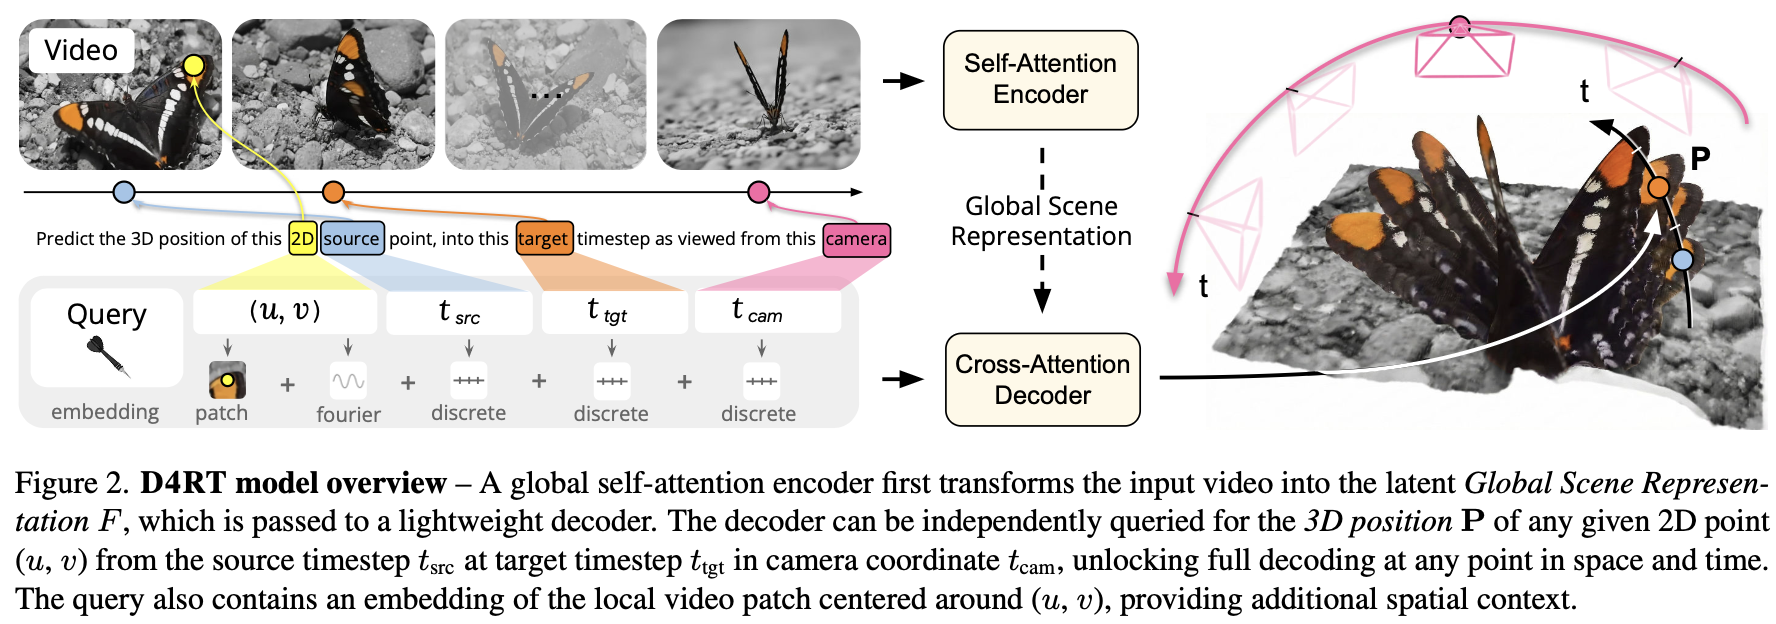
Implementation of D4RT, Efficiently Reconstructing Dynamic Scenes, from Deepmind
[CVPR 2026] STCDiT for Real-World Video Enhancement and AIGC Enhancement. It achieves temporally stable and structurally faithful restoration even under complex motions.
Official Code for GPIC: A Giant Permissive Image Corpus for Visual Generation
Efficient Stable Diffusion Fine-Tuning Framework 2026: Lightweight Config-Driven Pipeline
Zero-Config LoRA Fine-Tuning Studio for Diffusers 2026: The Ultimate Lightweight Trainer
Training-free reference-guided generation with FLUX.2-klein
Runs in the browser on Hugging Face
Zero-shot voice cloning text-to-speech (TTS) with explicit emotion class conditioning built on F5-TTS
[CVPR 2026 (Highlight)] Unofficial Implementation of "Image Diffusion Preview with Consistency Solver"
[ECCVW] How Far Can 5,500 Hours of Driving Take You? A Scaling Law Analysis of Video Diffusion Models
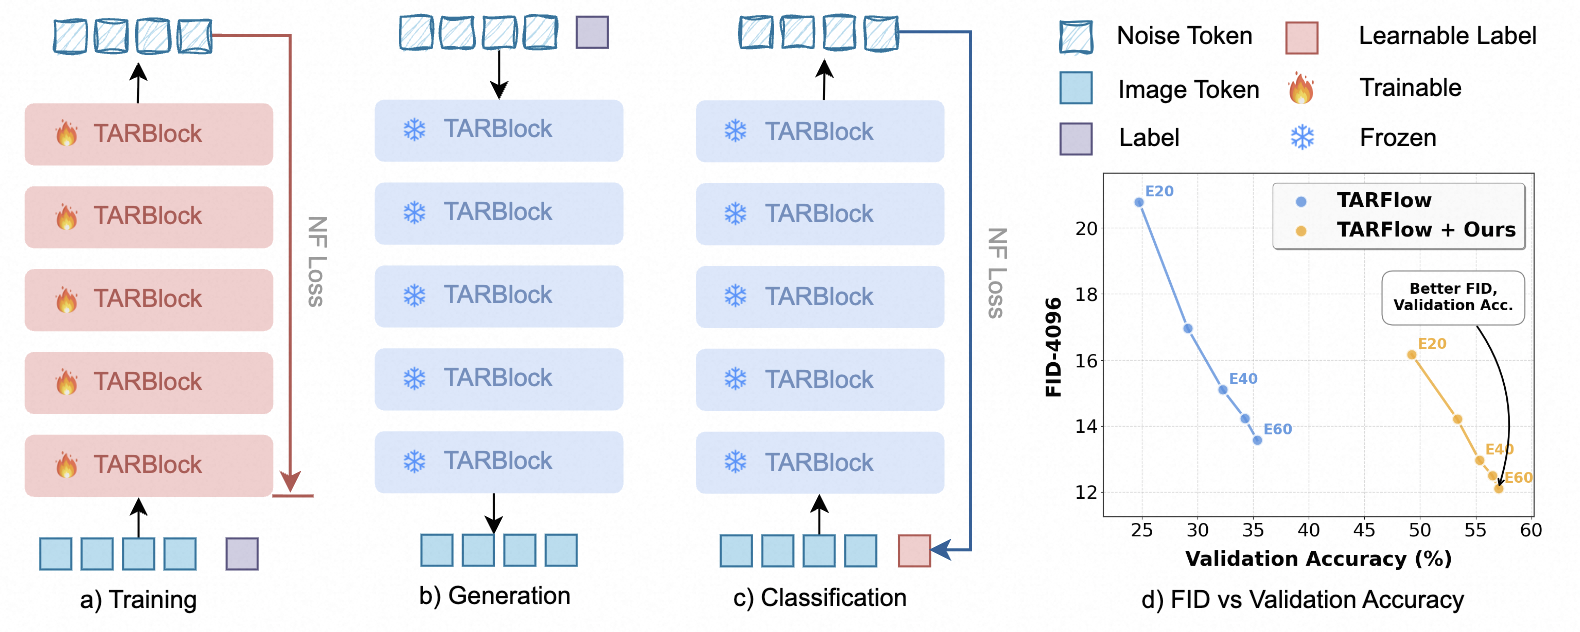
[AAAI 2026] Flowing Backwards: Improving Normalizing Flows via Reverse Representation Alignment
[ECCV 2026 oral] MIMFlow: Integrating Masked Image Modeling with Normalizing Flows for End-to-End Image Generation
Small exercises for robot learning, rustlings style: kinematics, dexterous hands, control, diffusion policy, flow matching. NumPy only.
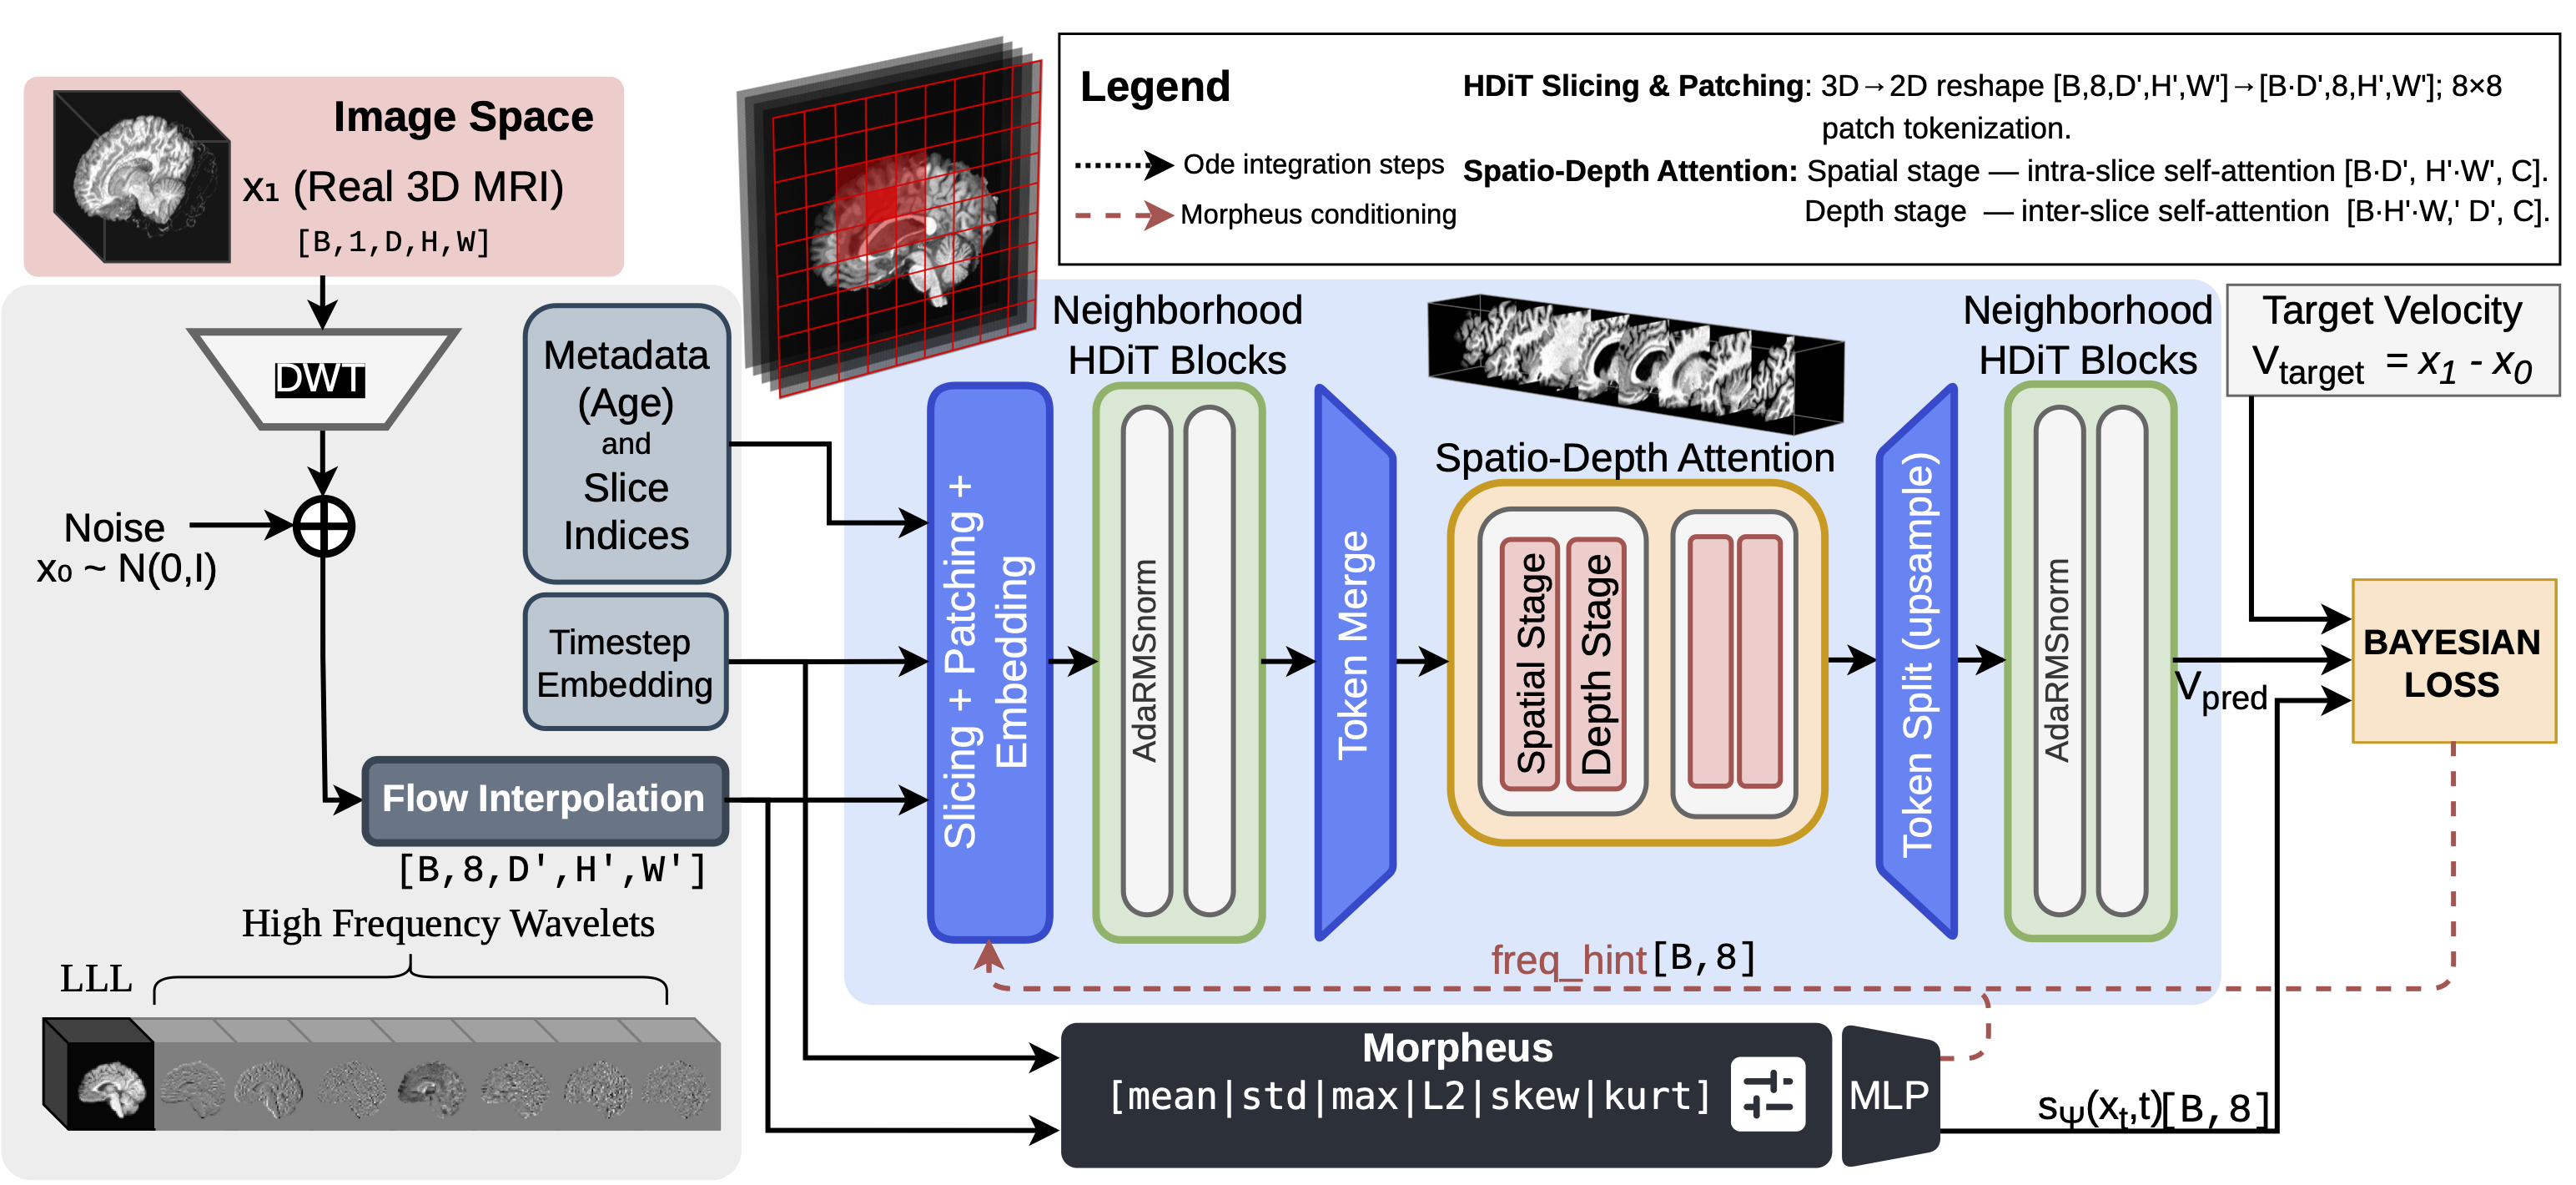
WaveDiT: Distribution-Aware Wavelet Flow Matching for Efficient 3D Brain MRI Synthesis - Accepted at MICCAI 2026
Generate music from text & lyrics with ACE-Step
Runs in the browser on Hugging Face
Runs in the browser on Hugging Face
Text-to-sound-effect diffusion demo (DiT + Flow Matching).
Runs in the browser on Hugging Face