Lance
A 3B-active-parameter native unified multimodal model for image and video understanding, generation, and editing.
- 1.4k
- Python
- Apache-2.0
- 4 mo ago
A 3B-active-parameter native unified multimodal model for image and video understanding, generation, and editing.
[CVPR 2024 Highlight🔥] Chat-UniVi: Unified Visual Representation Empowers Large Language Models with Image and Video Understanding
UniWorld: High-Resolution Semantic Encoders for Unified Visual Understanding and Generation
🎩 An Alfred 5 Workflow for using OpenAI Chat API to interact with GPT models 🤖💬 It also allows image generation/editing/understanding 🖼️, speech-to-text conversion 🎤, and text-to-speech synthesis 🔈
WACV 2024 Papers: Discover cutting-edge research from WACV 2024, the leading computer vision conference. Stay updated on the latest in computer vision and deep learning, with code included. ⭐ support visual intelligence development!
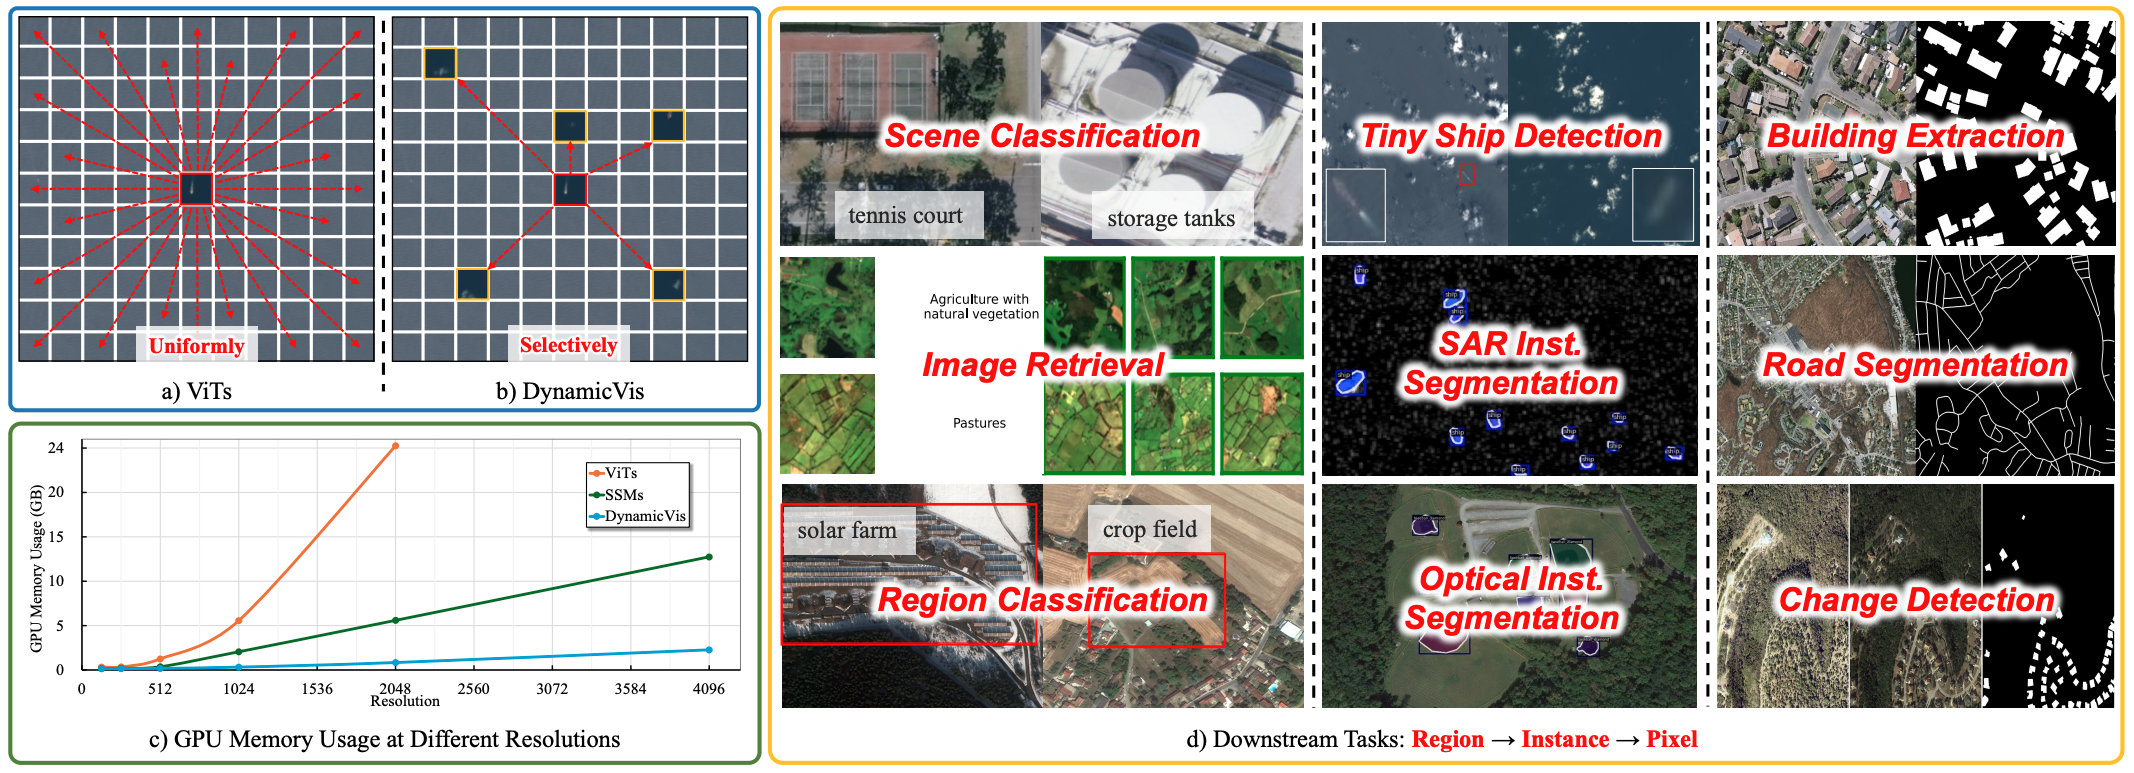
This is the implement of the paper "DynamicVis: An Efficient and General Visual Foundation Model for Remote Sensing Image Understanding"
Image text to text model.
📘 [Teaching] Class CVIU78101: Introduction to Computer Vision for Image Understanding Course
🖼️📄E2E Multi-modal Document Preprocessing with Azure Document Intelligence
PicQ: Demo for MiniCPM-o 4.5 to answer questions about images using natural language.
🐍 Miru — Multimodal reasoning tracer 👁️. Answers questions over images/docs 🖼️📄 while visualizing step-by-step attention and reasoning 🔍. Built for explainable vision-language AI 🤖✨
Unified MiniMax MCP server for multimodal generation, Token Plan search, and image understanding.
Fallback multimodal vision skill for AI coding agents. Calls any OpenAI-compatible vision API (doubao, OpenAI, OpenRouter, Azure, vLLM, etc.) when the primary model fails to interpret images.