GroundingDINO
[ECCV 2024] Official implementation of the paper "Grounding DINO: Marrying DINO with Grounded Pre-Training for Open-Set Object Detection"
- 11k
- Python
- Apache-2.0
- 2 y ago
[ECCV 2024] Official implementation of the paper "Grounding DINO: Marrying DINO with Grounded Pre-Training for Open-Set Object Detection"
Chinese version of CLIP which achieves Chinese cross-modal retrieval and representation generation.
Official repository of OFA (ICML 2022). Paper: OFA: Unifying Architectures, Tasks, and Modalities Through a Simple Sequence-to-Sequence Learning Framework
An open-source implementaion for fine-tuning Qwen-VL series by Alibaba Cloud.
A collection of original, innovative ideas and algorithms towards Advanced Literate Machinery. This project is maintained by the OCR Team in the Language Technology Lab, Tongyi Lab, Alibaba Group.
Image text to text model, used with gguf.
Gated access
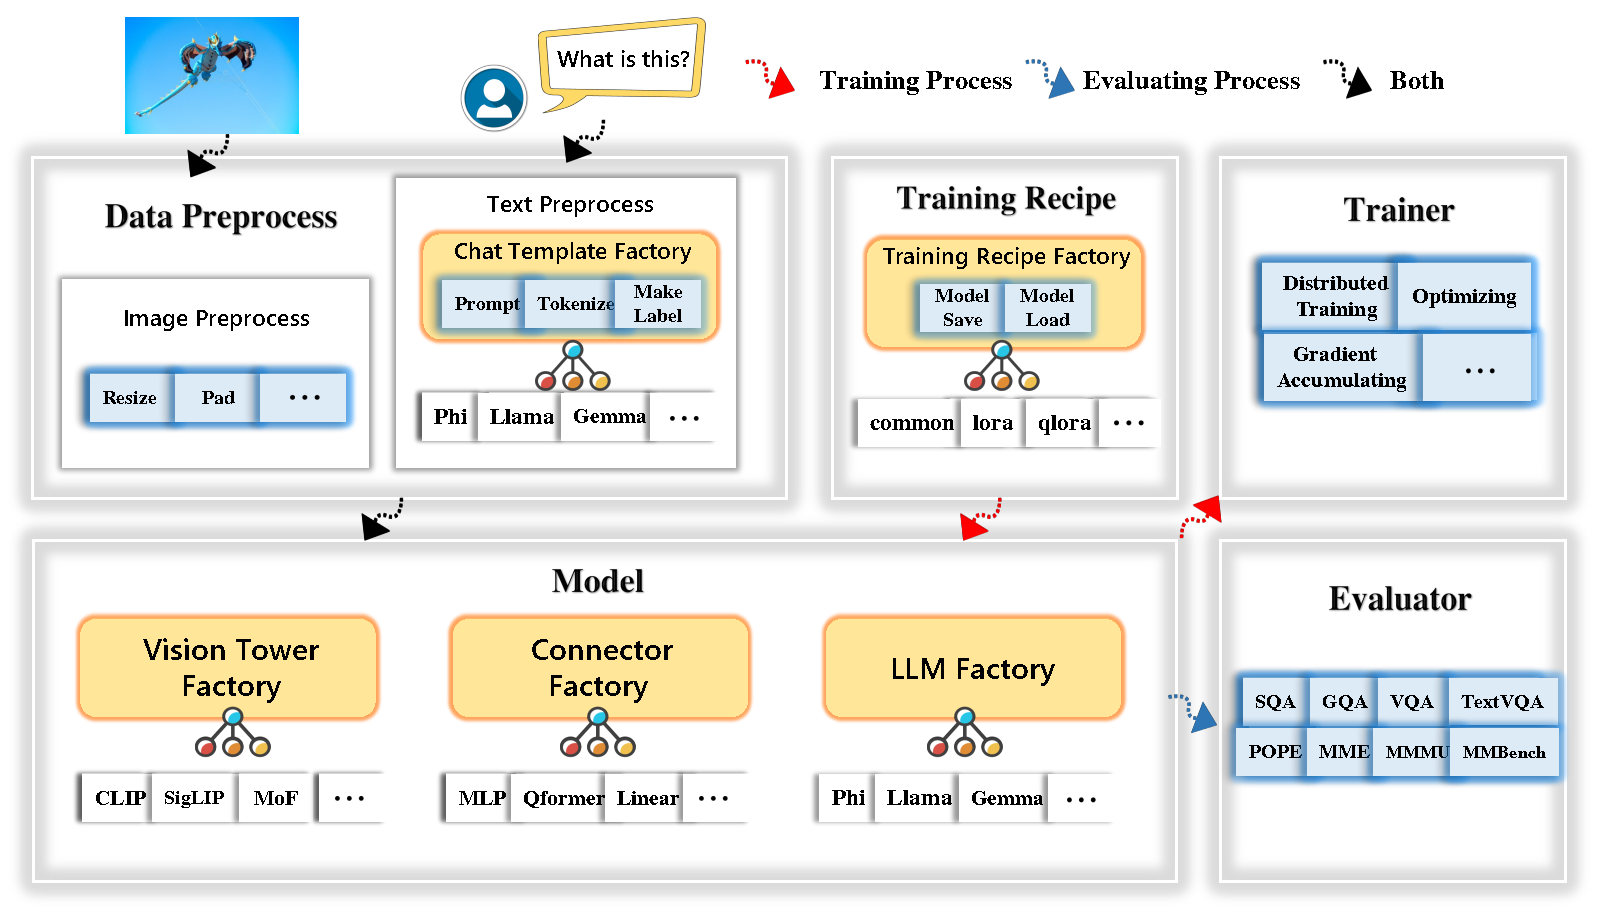
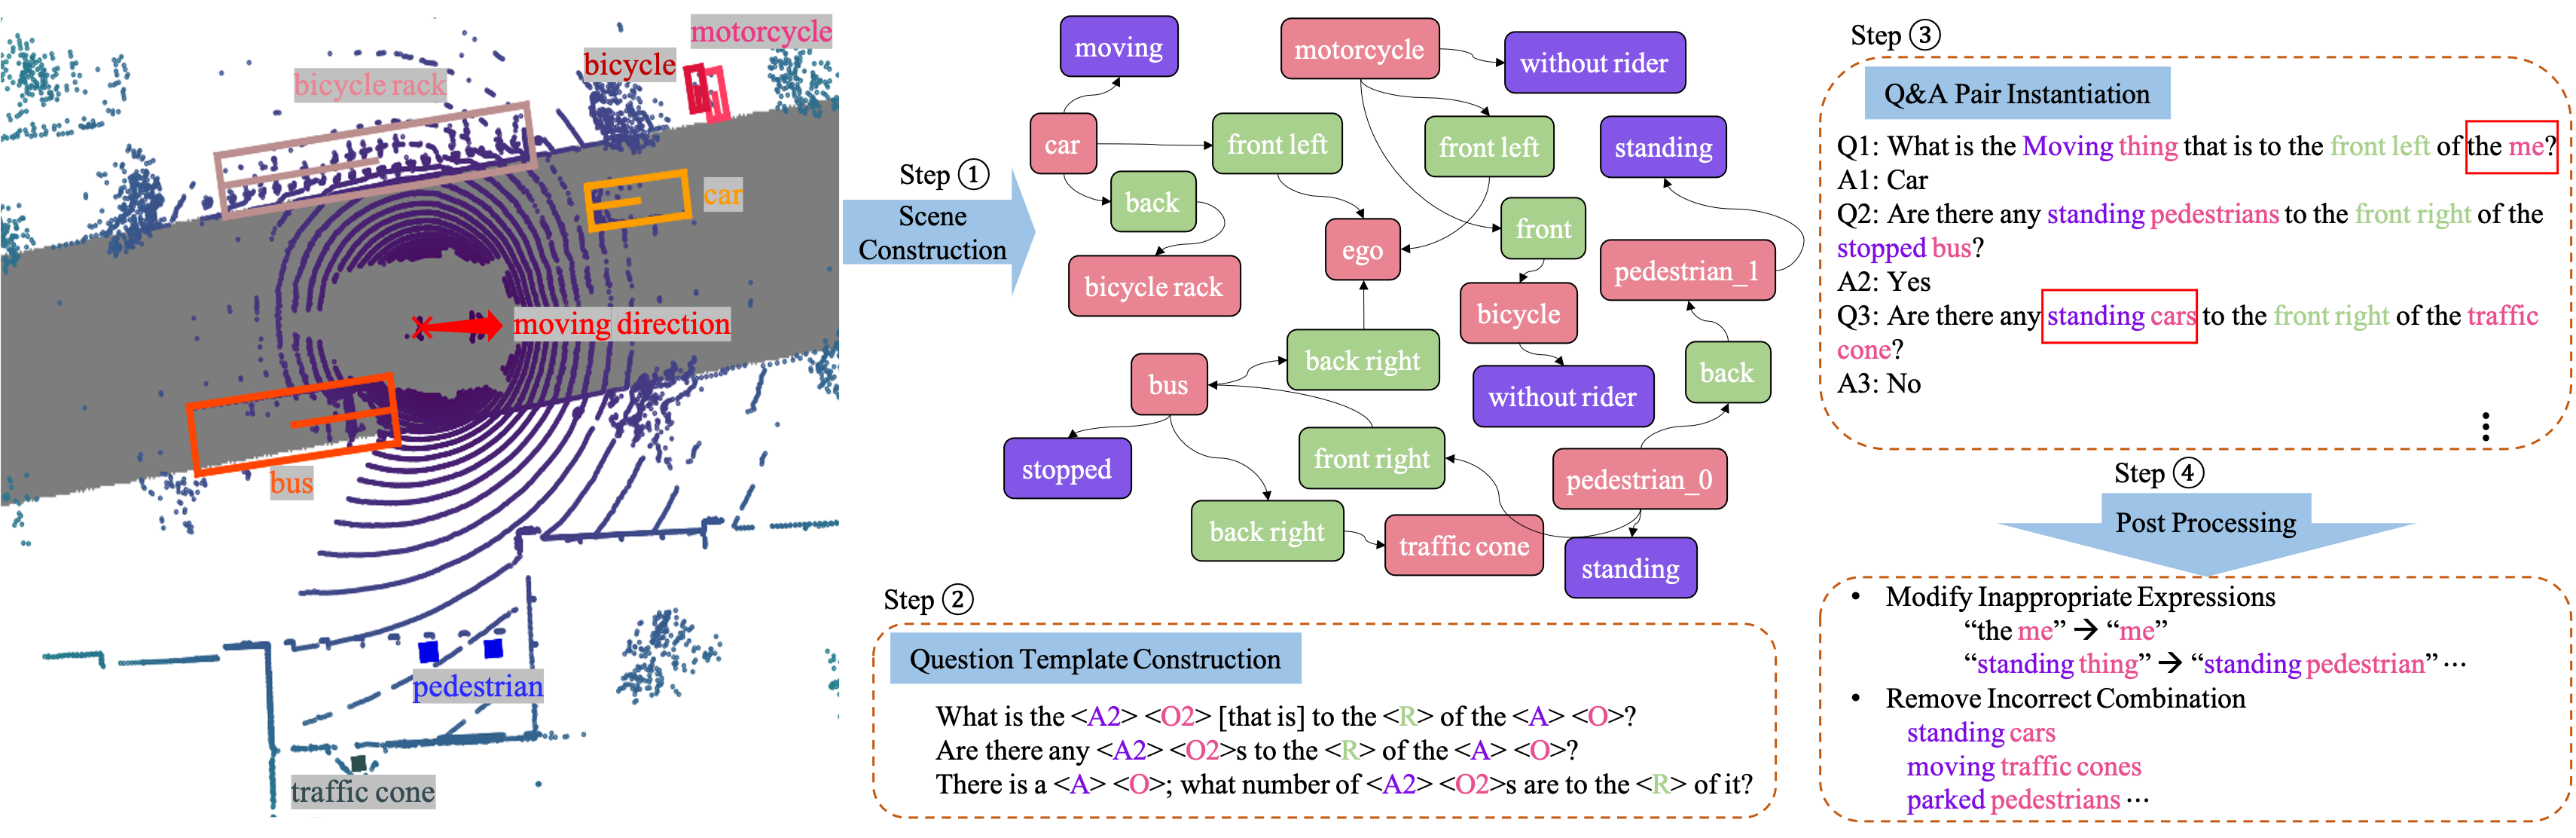
[ECCV 2024 Oral] DriveLM: Driving with Graph Visual Question Answering
This is the third party implementation of the paper Grounding DINO: Marrying DINO with Grounded Pre-Training for Open-Set Object Detection.
An open-weight 11B model series for long-form and real-time video understanding
Image text to text model, used with transformers.
Gated access
[IEEE TPAMI 2026] Simulating the Real World: Survey & Resources, which contains our survey "Simulating the Real World: A Unified Survey of Multimodal Generative Models" (IEEE TPAMI, 2026) and Awesome-Text2X-Resources. Watch this repository for the latest updates! 🔥
A minimal codebase for finetuning large multimodal models, supporting llava-1.5/1.6, llava-interleave, llava-next-video, llava-onevision, llama-3.2-vision, qwen-vl, qwen2-vl, phi3-v etc.
[AAAI 2024] NuScenes-QA: A Multi-modal Visual Question Answering Benchmark for Autonomous Driving Scenario.
Unofficial notebooks and resources for Microsoft's Florence-2 vision-language model: inference, auto-labelling and fine-tuning.
Catch claim errors before you submit — open model
Runs in the browser on Hugging Face
MLX Porting Toolkit — an agent-guided, evidence-gated pipeline (scaffold → convert → parity → benchmark) plus a portable skill for porting PyTorch/Hugging Face models to Apple MLX.
Unlimited-horizon parsing studio for baidu/Unlimited-OCR-2
Runs in the browser on Hugging Face
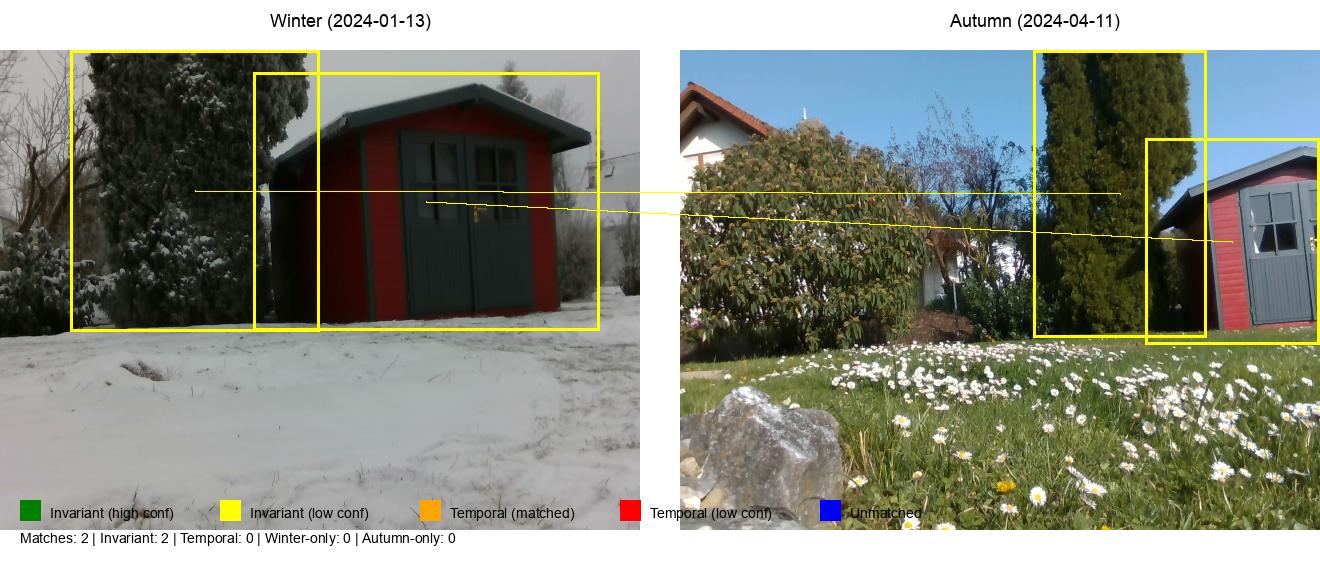
POLARIS: staged vision-language pipeline for cross-temporal landmark matching with OWL-ViT detection, FastVLM enrichment, and geometric verification
Live chat plus exact Apple-Silicon MLX setup
Runs in the browser on Hugging Face