compound
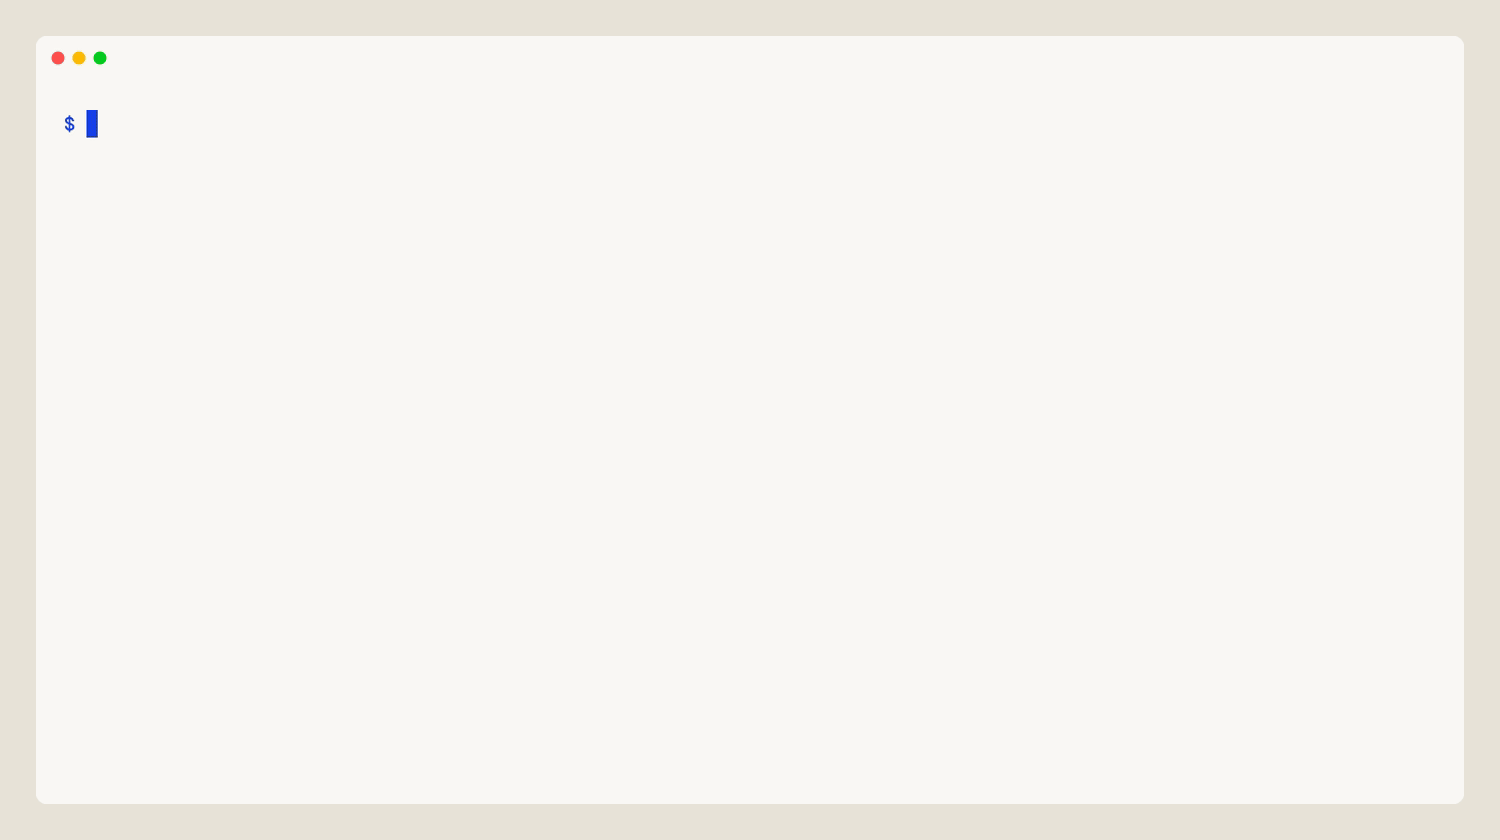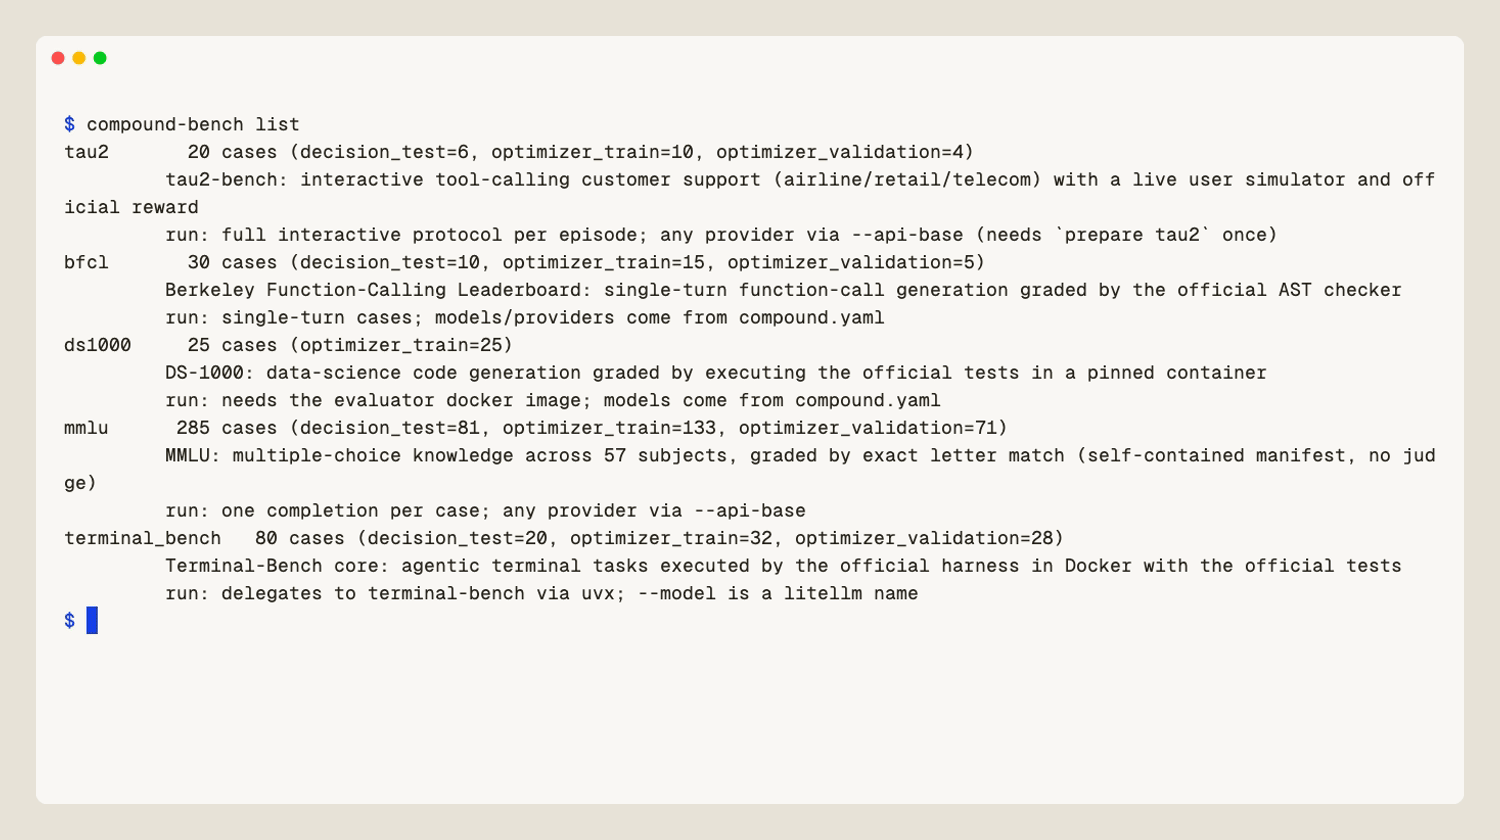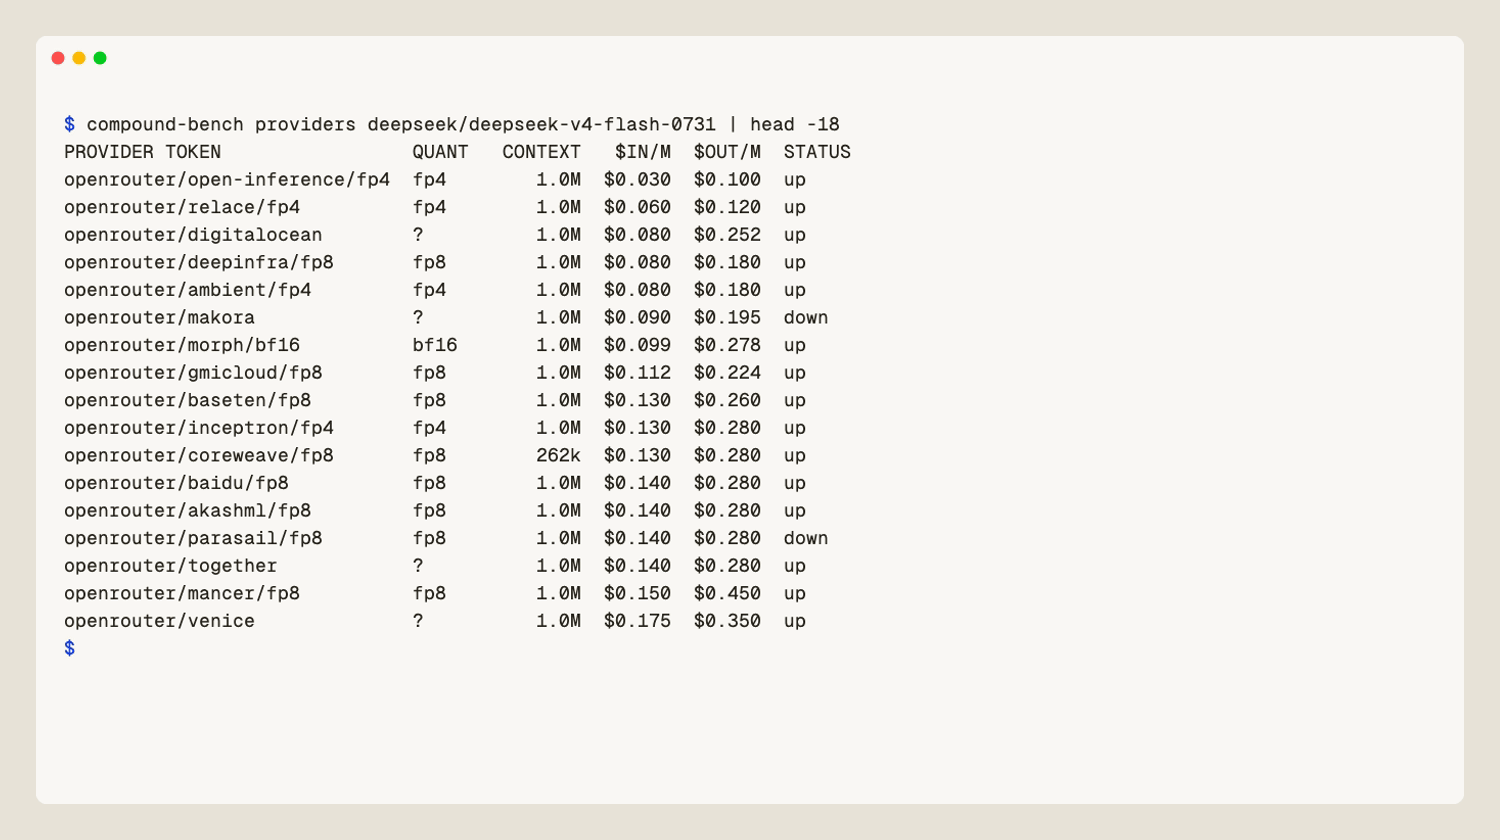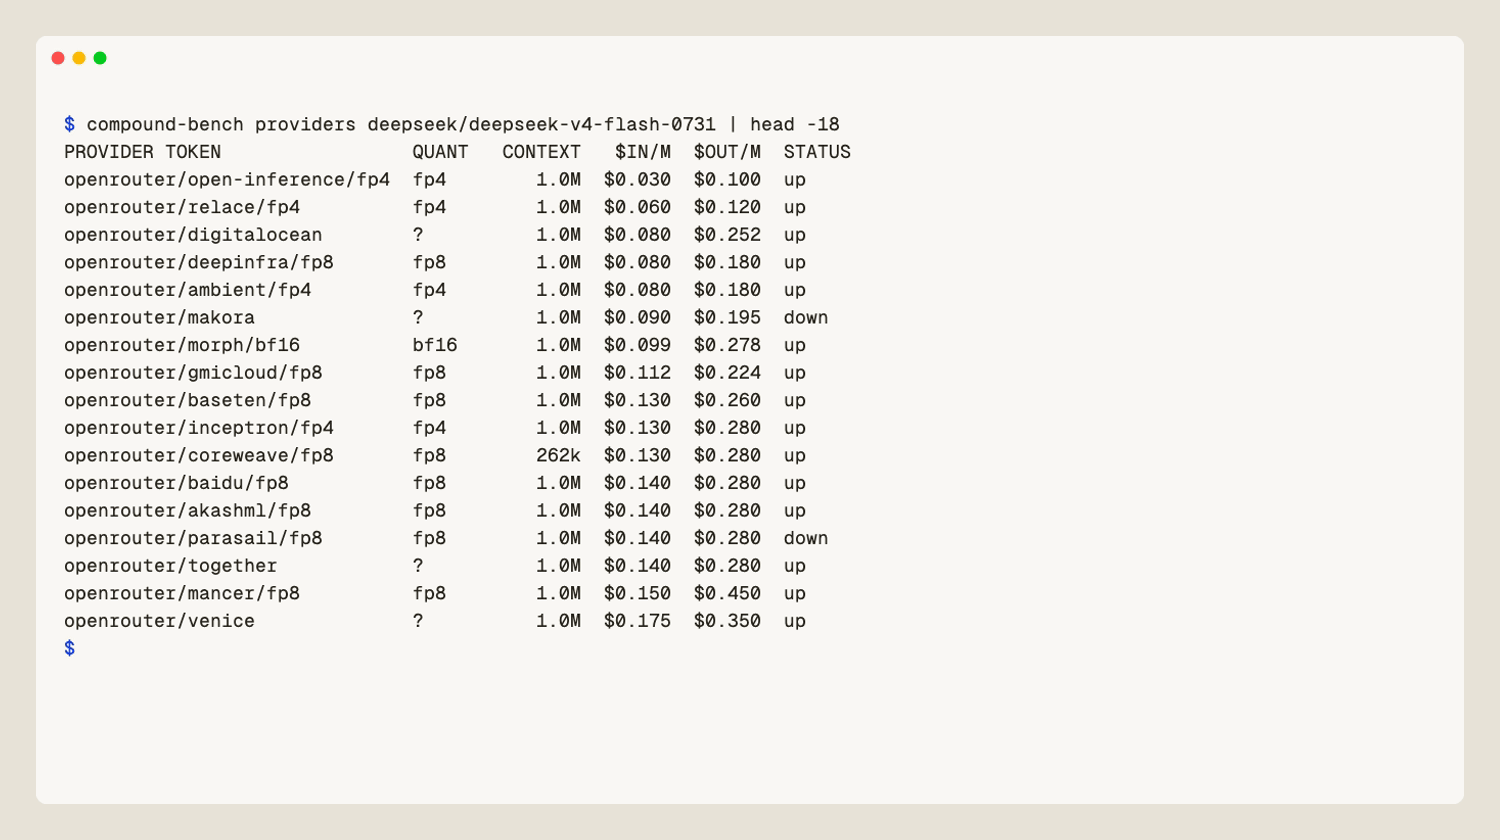
Which host should serve your open model? Run your workload across pinned, verified providers and get one table: success, cost, latency, cache hits.
- 8
- TypeScript
- Apache-2.0
- 3 wk ago
Which host should serve your open model? Run your workload across pinned, verified providers and get one table: success, cost, latency, cache hits.
An independent, evidence-graded read on how much you own the open models and inference providers you rely on.
A browser FPS built with Qwen3.8-27B via HF + Featherless.
Runs in the browser on Hugging Face
Private workspace for generative media with own key, domain, and storage.
Text to speech API, speech to text and LLM provider for Vercel AI SDK: official Telnyx package for voice AI apps.
Dashboard for comparing AI model pricing, capabilities, context windows, and token costs from European AI providers with automatic EUR/USD conversion.
Open-source text-to-video and image-to-video app. Static frontend for GitHub Pages, a local backend, and pluggable inference providers. No paid service required.
DeepSeek-V4-Pro-0813: 22 API providers, price per 1M tokens
Runs in the browser on Hugging Face
GLM-5.3: 31 API providers, price per 1M tokens
Runs in the browser on Hugging Face
Kimi-K3: 17 API providers, price per 1M tokens
Runs in the browser on Hugging Face
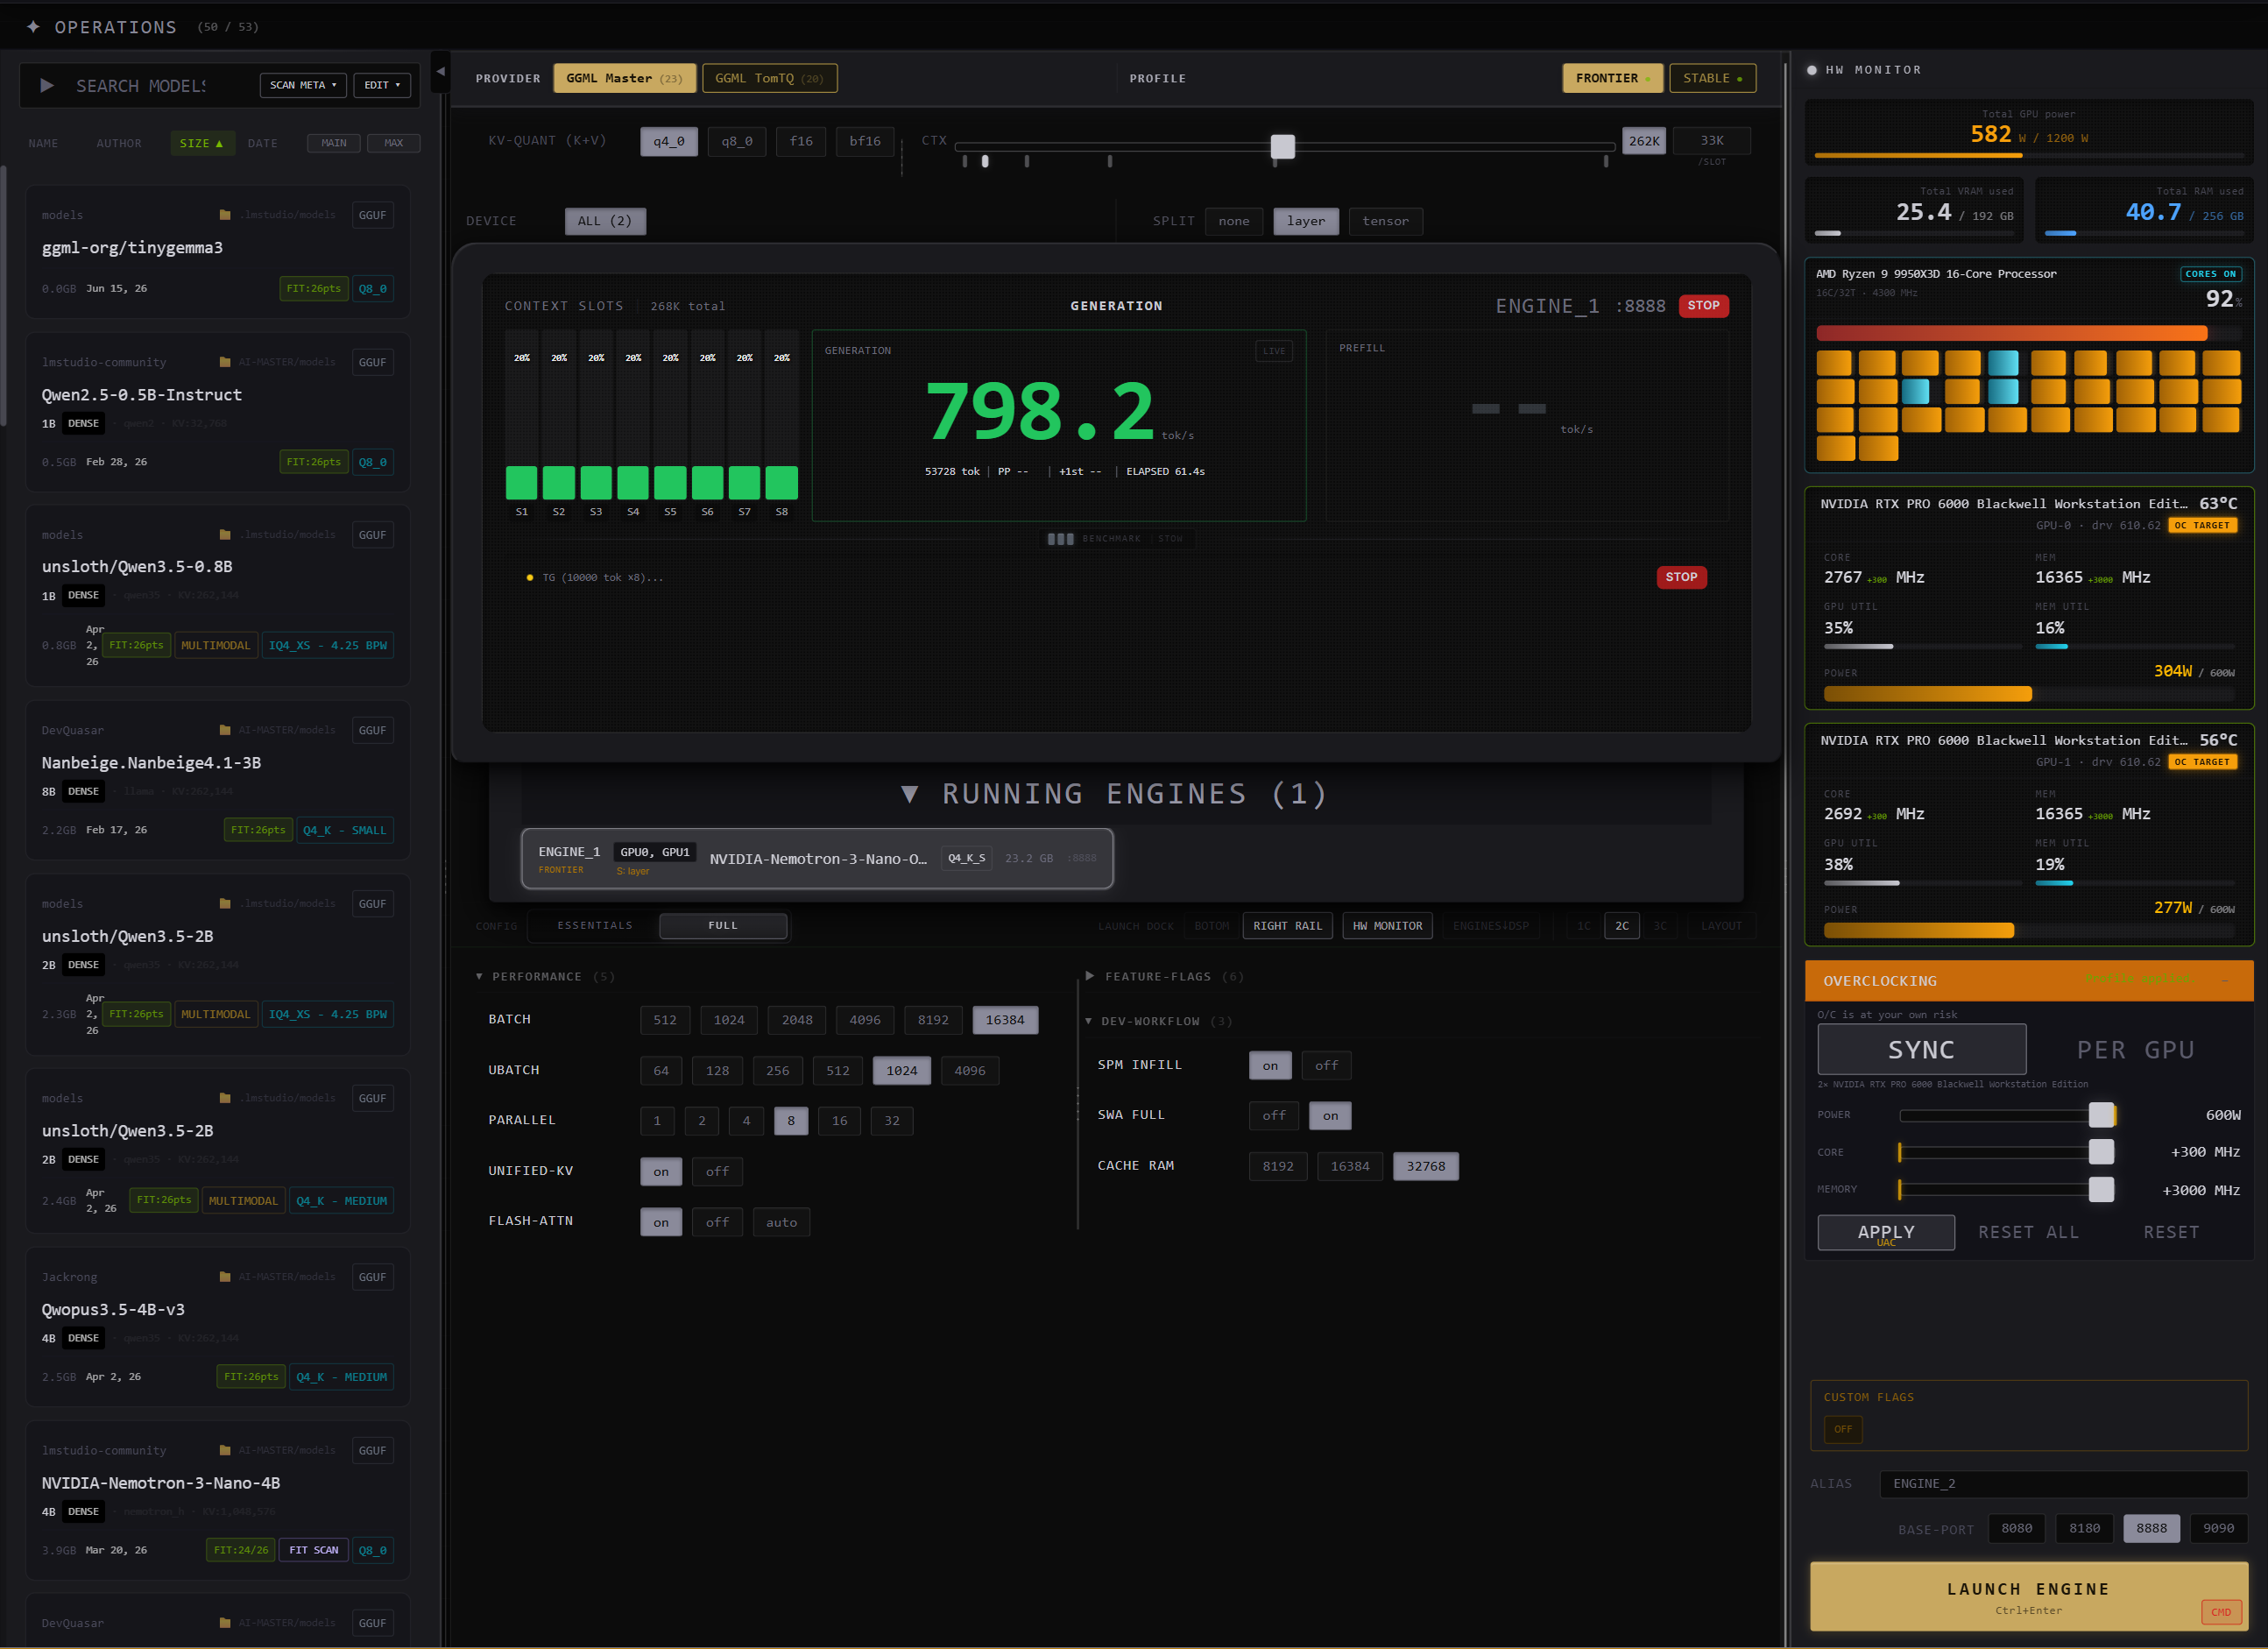
Hardware probe and best-of-N sampling harness in C. Ranks GGUF quantisations against measured VRAM and RAM, drives Ollama or llama.cpp over OpenAI-format HTTP on localhost, and gates every candidate behind a static check and a test run.
Private workspace for generative media with own key, domain, and storage.
GLM-5.3-Flash: 30 API providers, price per 1M tokens
Runs in the browser on Hugging Face
Private workspace for generative media with own key, domain, and storage.
Credit-based generative media app with auth, prepaid credits, and private storage.