SageAttention
[ICLR2025, ICML2025, NeurIPS2025 Spotlight] Quantized Attention achieves speedup of 2-5x compared to FlashAttention, without losing end-to-end metrics across language, image, and video models.
- 4k
- Cuda
- Apache-2.0
- 10 mo ago
[ICLR2025, ICML2025, NeurIPS2025 Spotlight] Quantized Attention achieves speedup of 2-5x compared to FlashAttention, without losing end-to-end metrics across language, image, and video models.
TurboDiffusion: 100–200× Acceleration for Video Diffusion Models
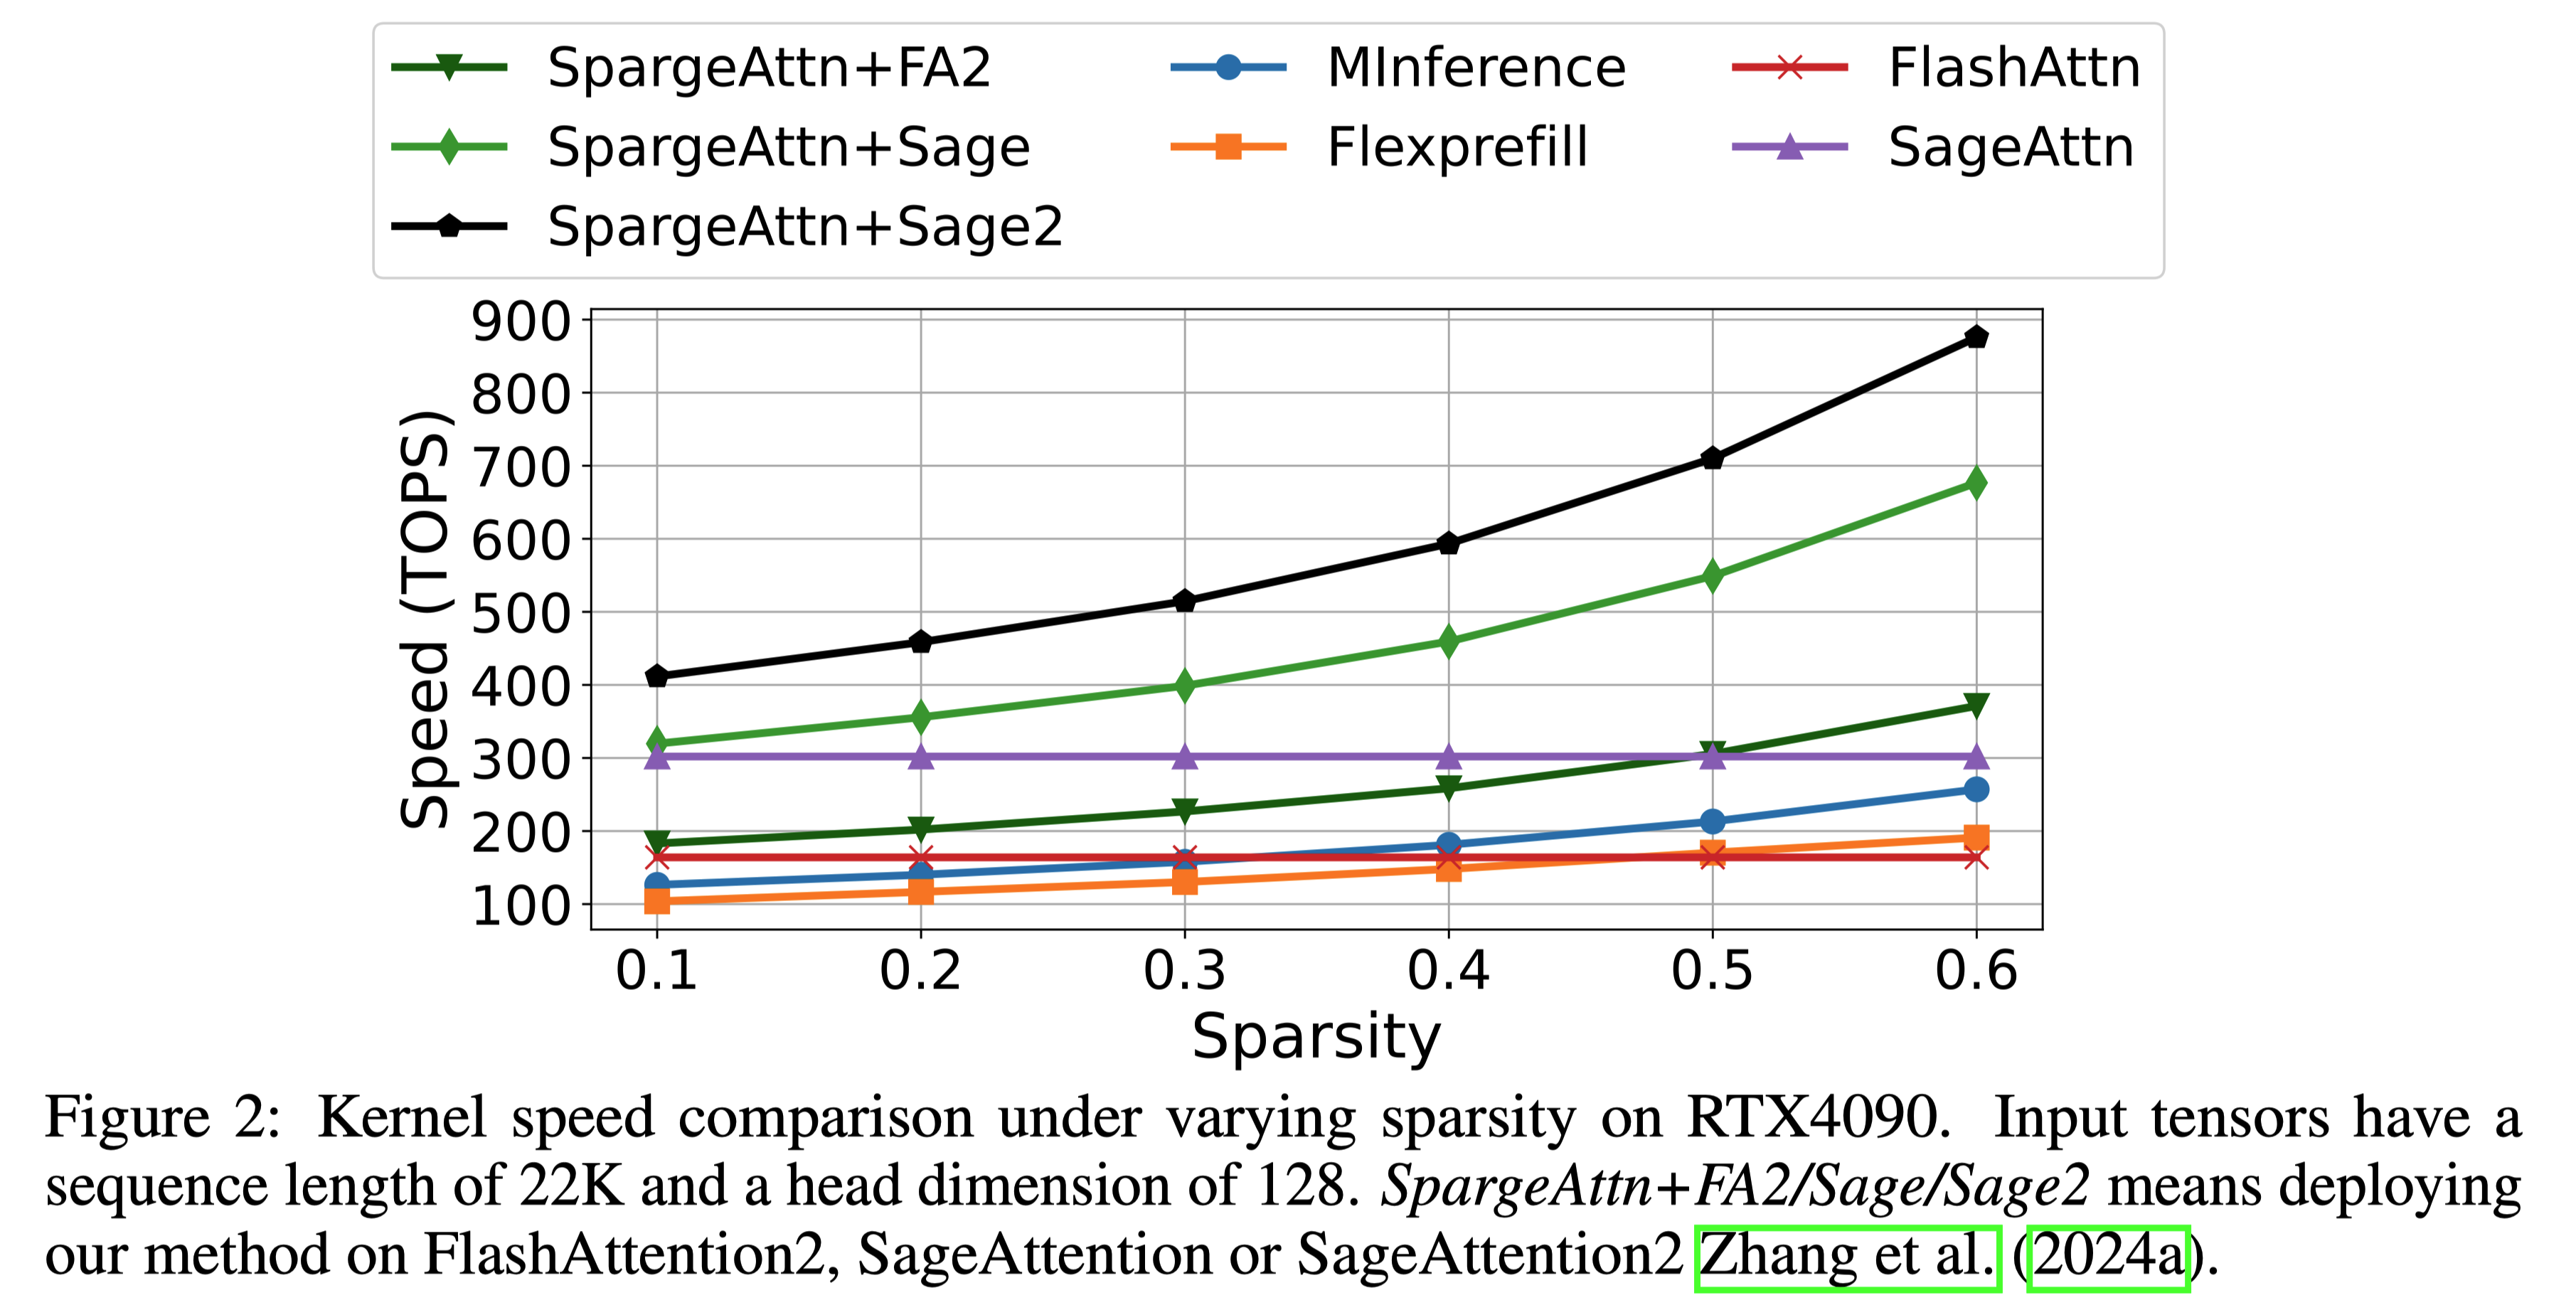
[ICML2025] SpargeAttention: A training-free sparse attention that accelerates any model inference.
SparkDiffusion: Accelerating DiT video generation by 265× via joint Sparsity, Distillation, Quantization, etc.
SLA: Beyond Sparsity in Diffusion Transformers via Fine-Tunable Sparse–Linear Attention
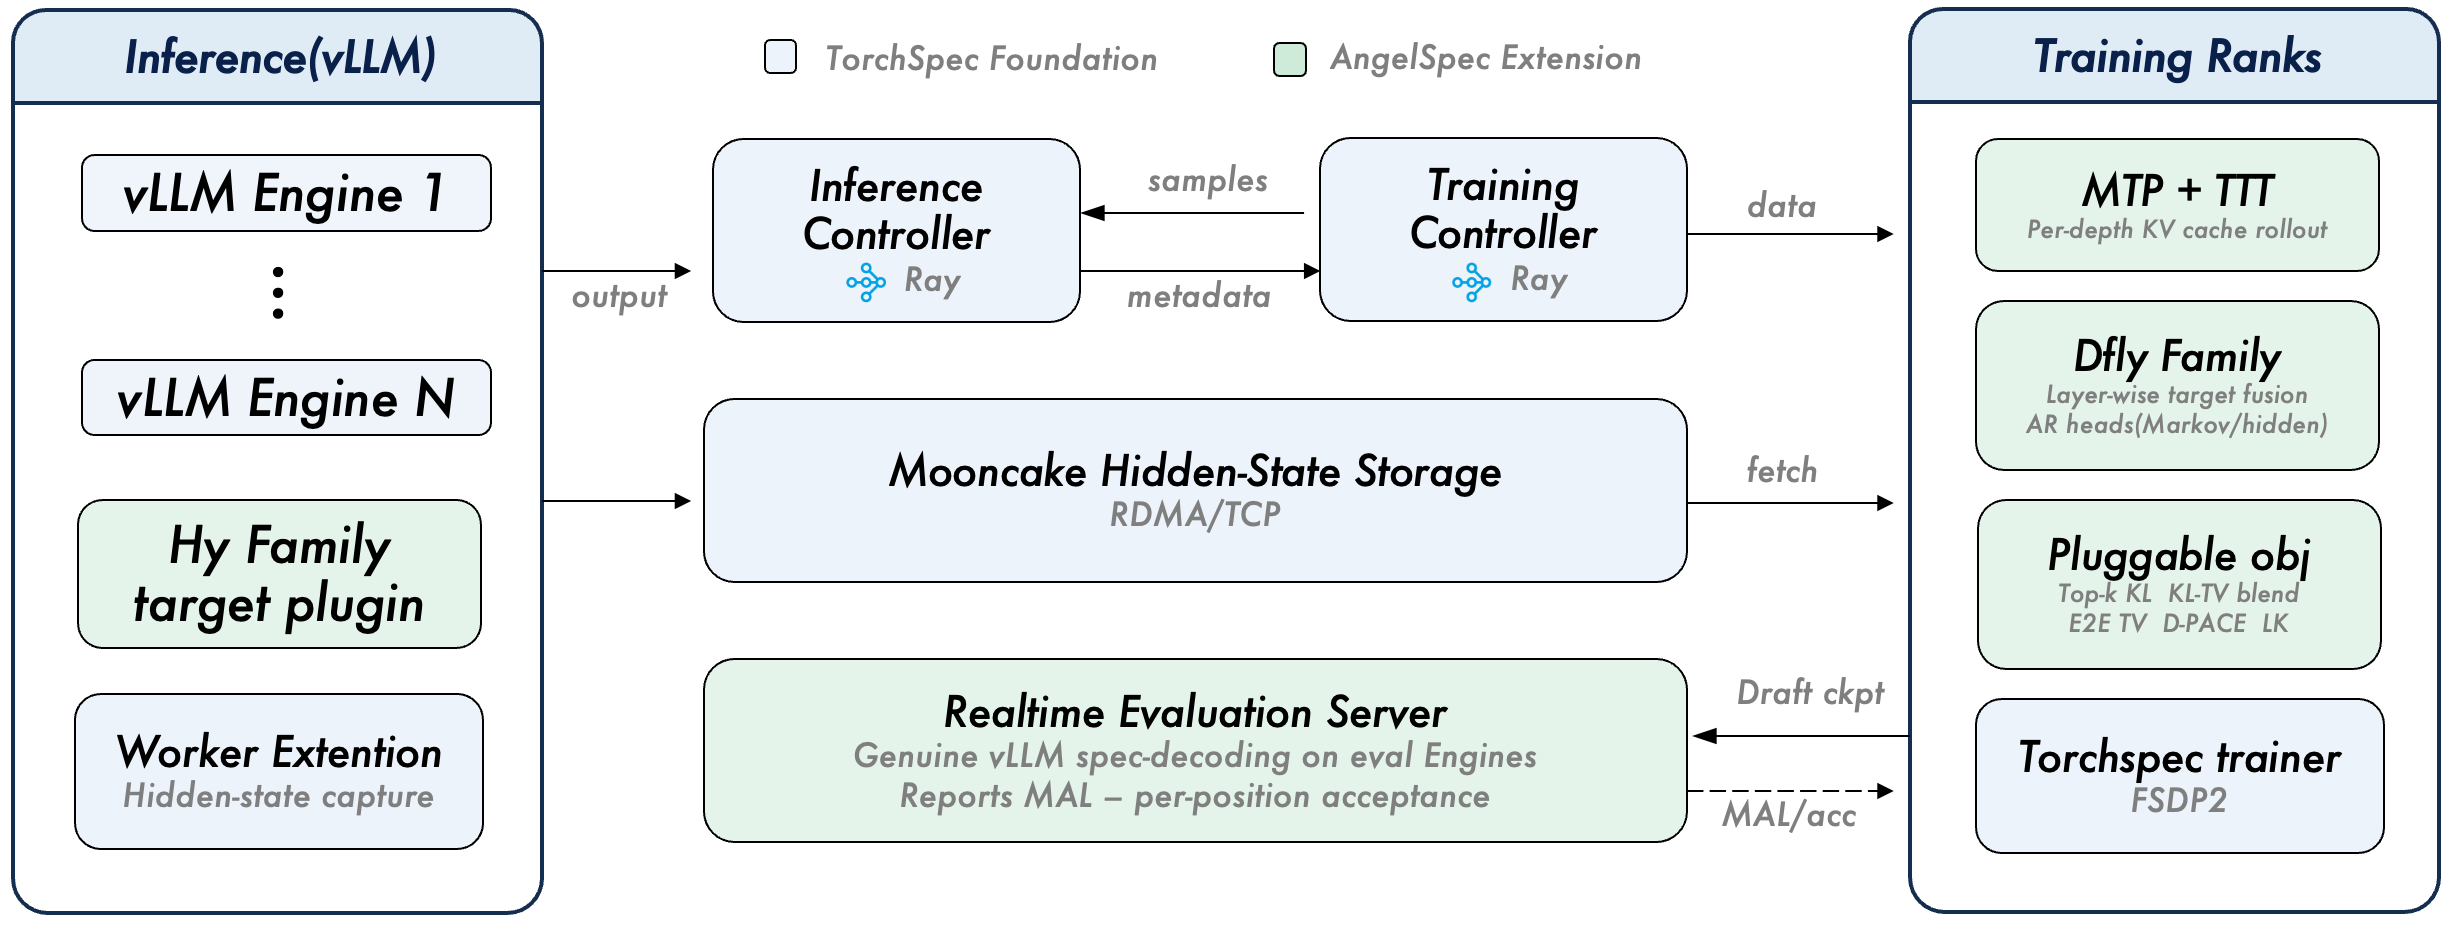
A unified, torch-native training framework for MTP and block-parallel speculative decoding.
[EMNLP 2026] 📚 A curated list of Awesome Efficient dLLMs Papers with Codes
Transport-neutral, vendor-agnostic virtual accelerator devices. First class cross-platform NPU backend support for Apple, Intel, AMD, Qualcomm devices, as well as Vulkan for cross-platform GPU support.
Code for paper "TLEE: Temporal-wise and Layer-wise Early Exiting Network for Efficient Video Recognition on Edge Devices"
Code for paper "Joint Adaptive Resolution Selection and Conditional Early Exiting for Efficient Video Recognition on Edge Devices"
Code for paper "Deep Reinforcement Learning based Multi-task Automated Channel Pruning for DNNs"
40x faster AI inference: ONNX to TensorRT optimization with FP16/INT8 quantization, multi-GPU support, and deployment
Code for paper "Automated Design for Hardware-aware Graph Neural Networks on Edge Devices"
Code for paper "Automated Spatial-Temporal Graph Neural Network Search for Skeleton-based Human Action Recognition on Edge Devices"
Comprehensive performance analysis of DeepSeek V3 quantization levels (FP16, Q8_0, Q4_0) on 16GB GPU environments.
GPT-OSS B20 Local Execution. Lightweight local environment for running it with Python 3.12 and CUDA acceleration. - Run GPT-OSS B20 entirely offline - Optimize text generation with GPU - Enable fast, secure inference on consumer hardware.
Hardware probe and best-of-N sampling harness in C. Ranks GGUF quantisations against measured VRAM and RAM, drives Ollama or llama.cpp over OpenAI-format HTTP on localhost, and gates every candidate behind a static check and a test run.
Text generation model, used with transformers.