orthrus
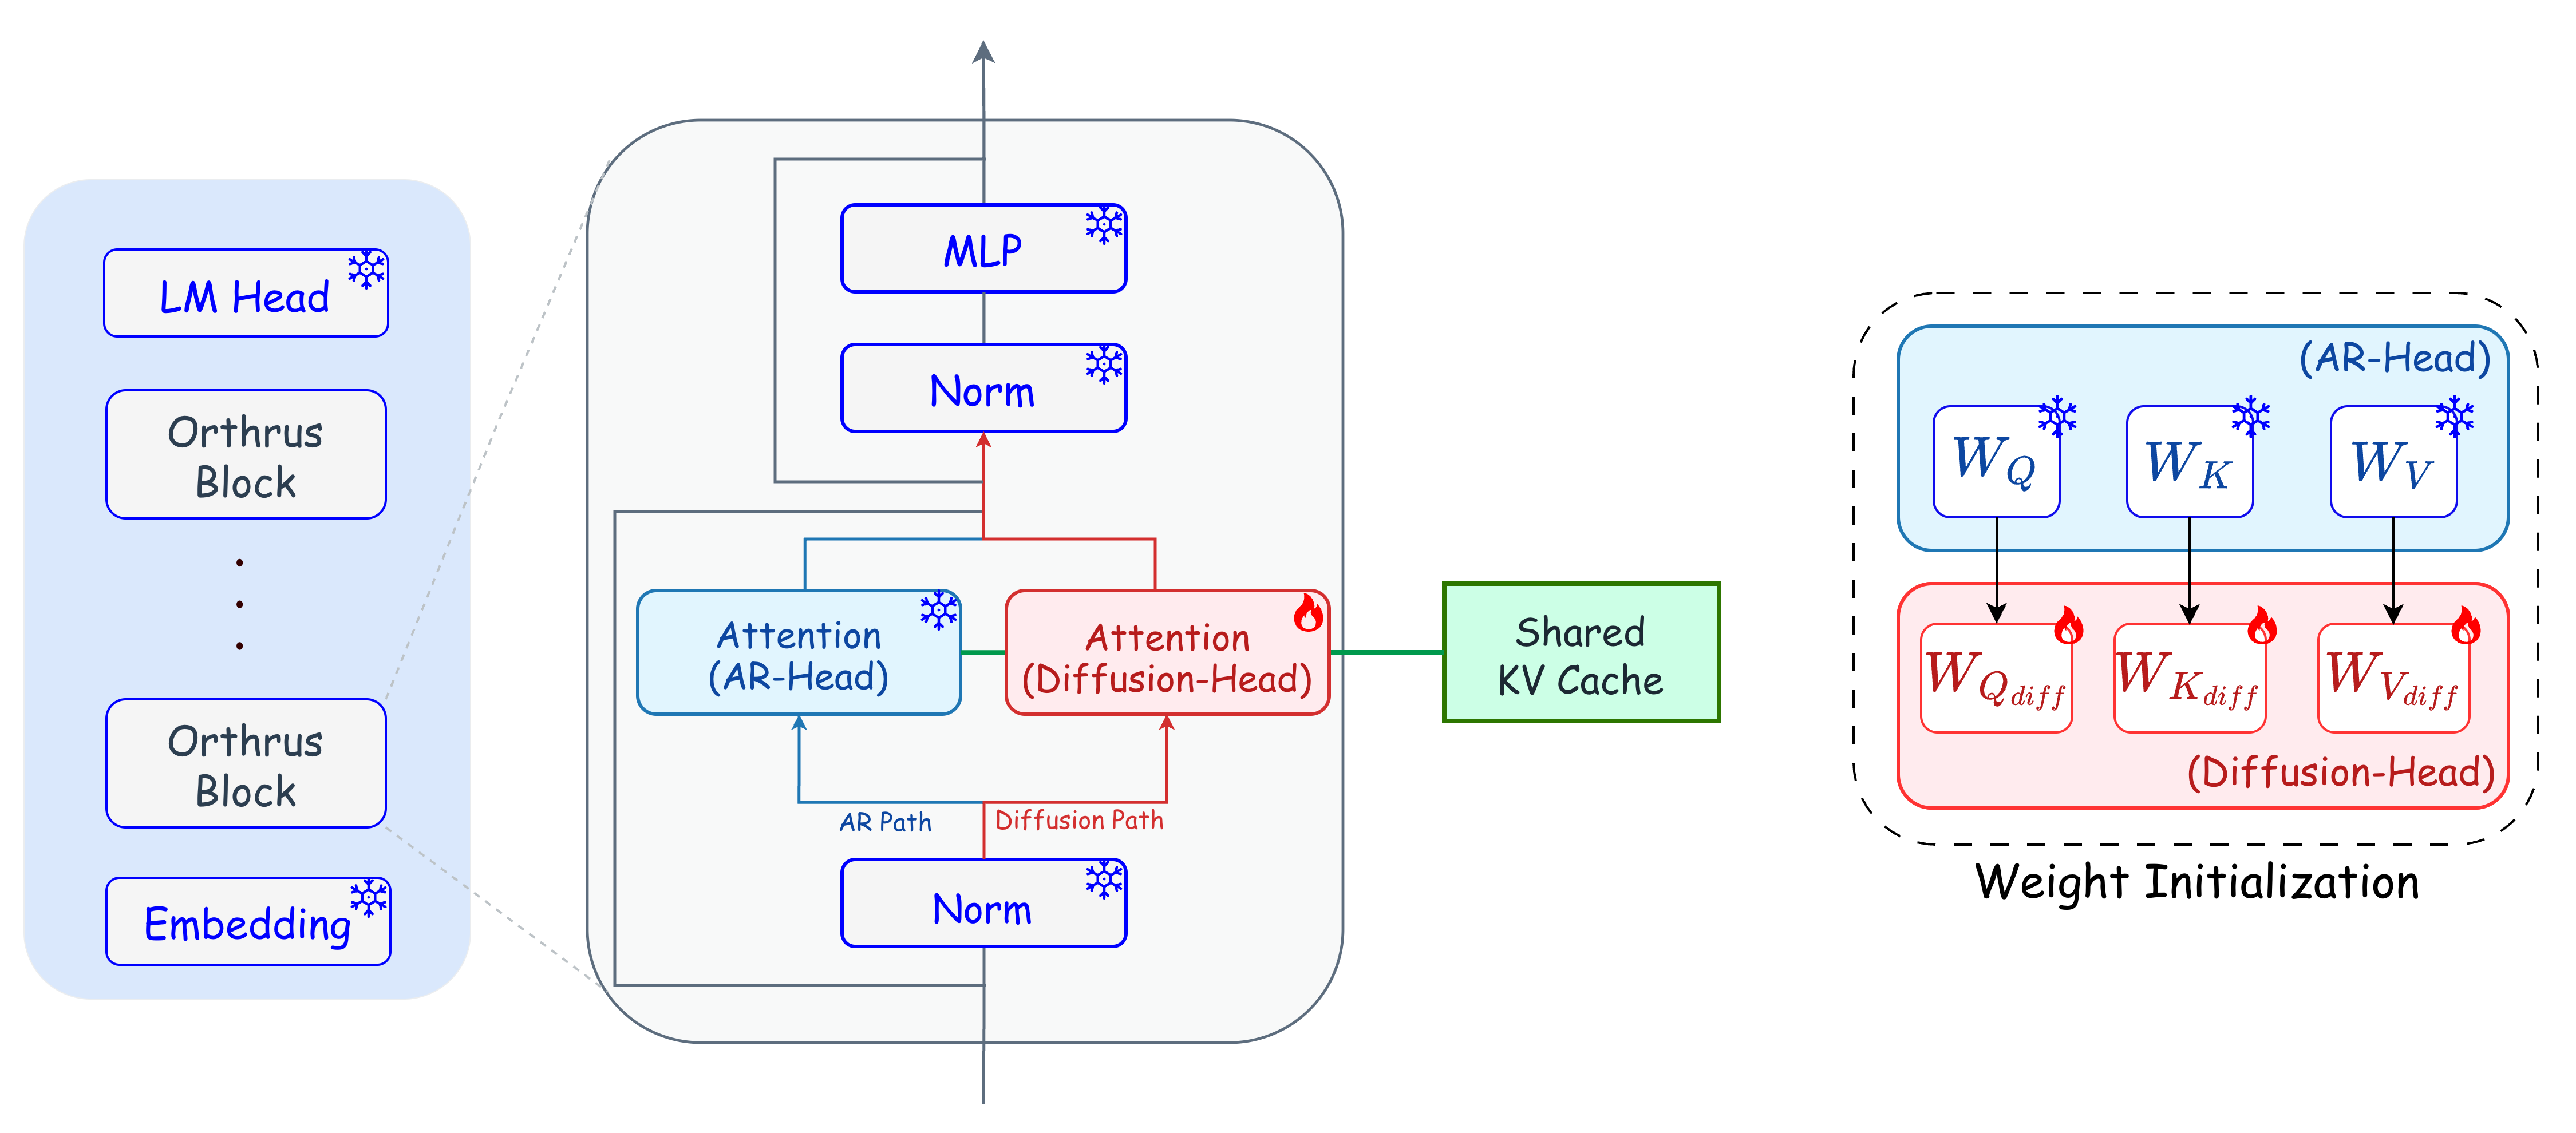
[NeurIPS 2026 Spotlight] Fast, lossless LLM inference via dual-view diffusion decoding.
- 483
- Python
- MIT
- 3 mo ago
[NeurIPS 2026 Spotlight] Fast, lossless LLM inference via dual-view diffusion decoding.
Official Implementation of "Gumiho: A Hybrid Architecture to Prioritize Early Tokens in Speculative Decoding" (ICML'25)
Biological code organization system with 1,029+ production-ready snippets - 95% token reduction for Claude/GPT with AI-powered discovery & offline packs
Dynamic Model Routing and Cascading for Efficient LLM Inference: A Survey


