local-inference


Mano-P
Mano-P: Open-source GUI-VLA agent for edge devices. #1 on OSWorld (specialized, 58.2%). Runs locally on Apple M4 Mac mini/MacBook — no data leaves your device.Mano-P 是一个开源 GUI-VLA 项目,支持在 Mac mini/MacBook 上或通过算力棒本地运行推理,实现纯视觉驱动的跨平台 GUI 自动化操作。数据完全本地处理,支持复杂多步骤任务规划与执行。
- 2.9k
- Apache-2.0
- 5 mo ago

ollaya
Jev-compatible API server for open decision models. Ollama for decision models: pull and serve 29 model families (Laya, pplx-decider, Clef, Winnow, coba...) locally or self-hosted behind /v1/systemone. The TypeSafe SDK works unchanged: set its base URL and pick an open model. CLI, desktop app, Docker, MCP server, public bench.
- 1.5k
- Rust
- Apache-2.0
- 1 d ago

kronk
Go With Your Own Intelligence! Use Go for hardware accelerated local inference with llama.cpp, whisper.cpp, and stable-diffusion.cpp directly integrated into your Go applications. Kronk provides a high-level API and production ready model server.
- 871
- Go
- Apache-2.0
- 23 h ago

tools
Tools, ComfyUI workflows and benchmark configs from a 4x RTX 3090 local-inference rig
- 702
- HTML
- MIT
- 8 wk ago

MACaQ
SOTA model-agnostic quantization for GGUF, local inference and beyond. Quantize and run text, image, video and audio models with llama.cpp, vLLM, Diffusers and PyTorch.
- 378
- C++
- Apache-2.0
- 3 d ago


Promethevs
PROMETHEVS: run the full DeepSeek-V4.1-Flash-1017 (510 GB) on a gaming PC with 64 GB RAM and a 12 GB GPU. PROMETHEVS engine (compress-then-correct), OpenAI-compatible local server, report and logs.
- 192
- CC-BY-4.0
- 11 d ago

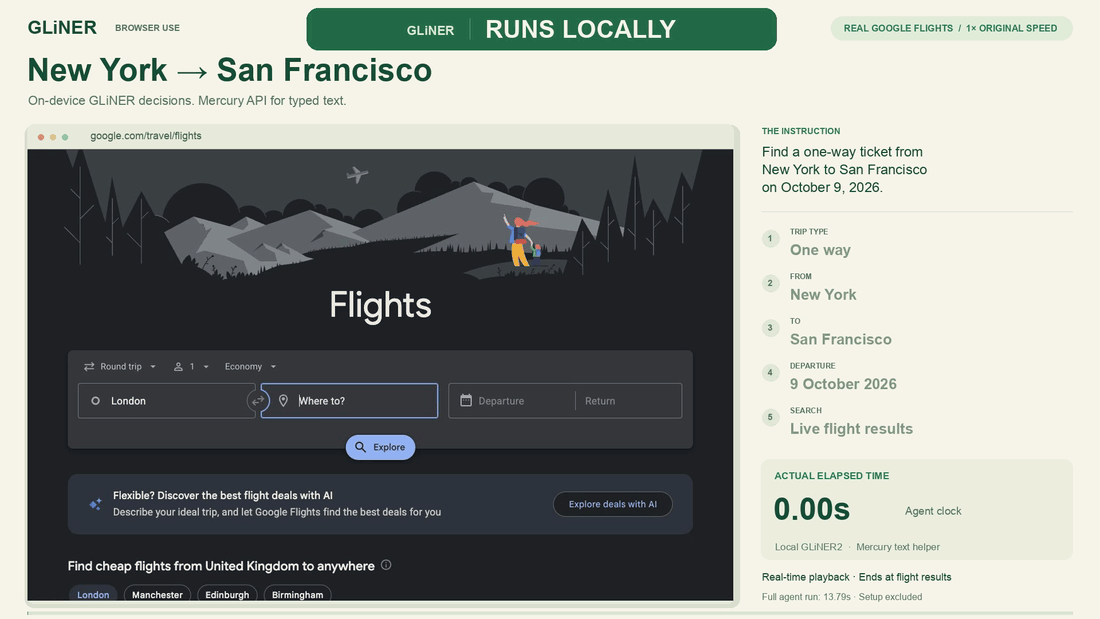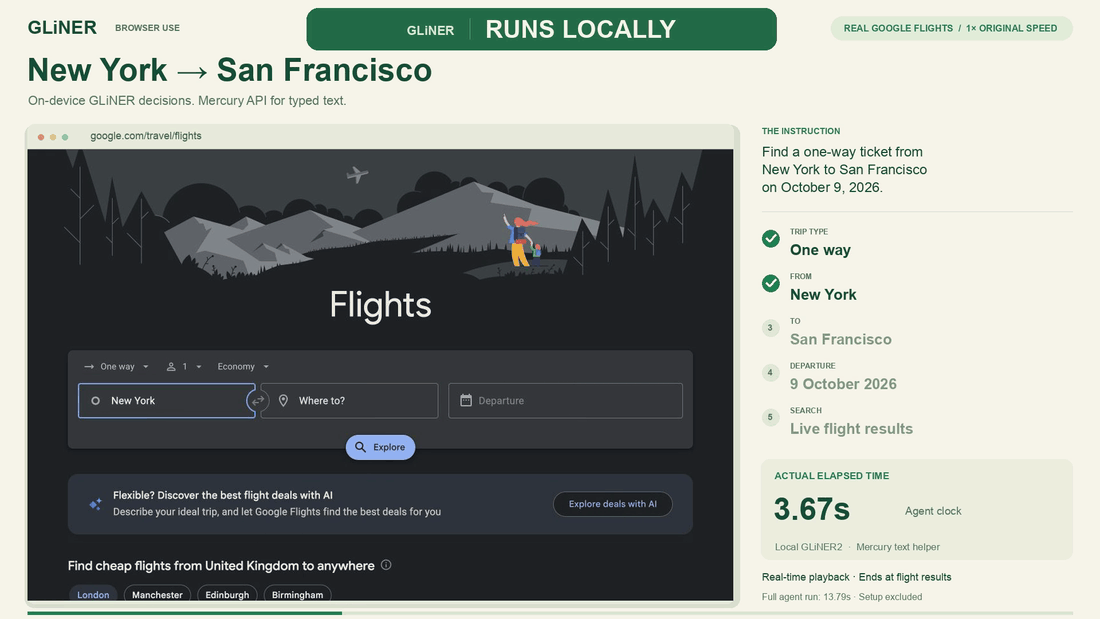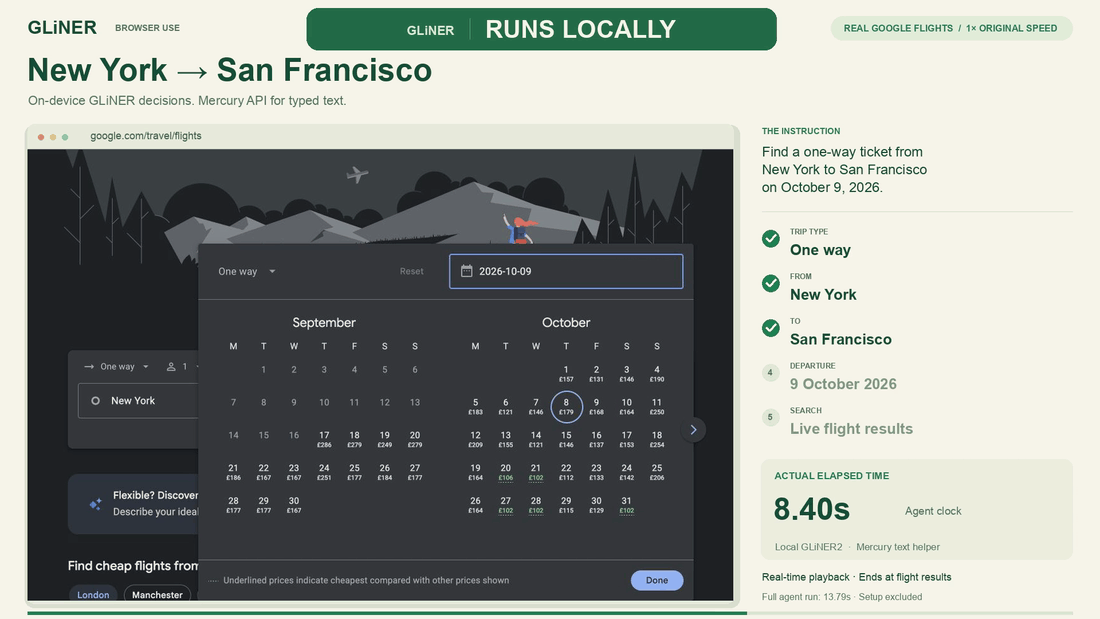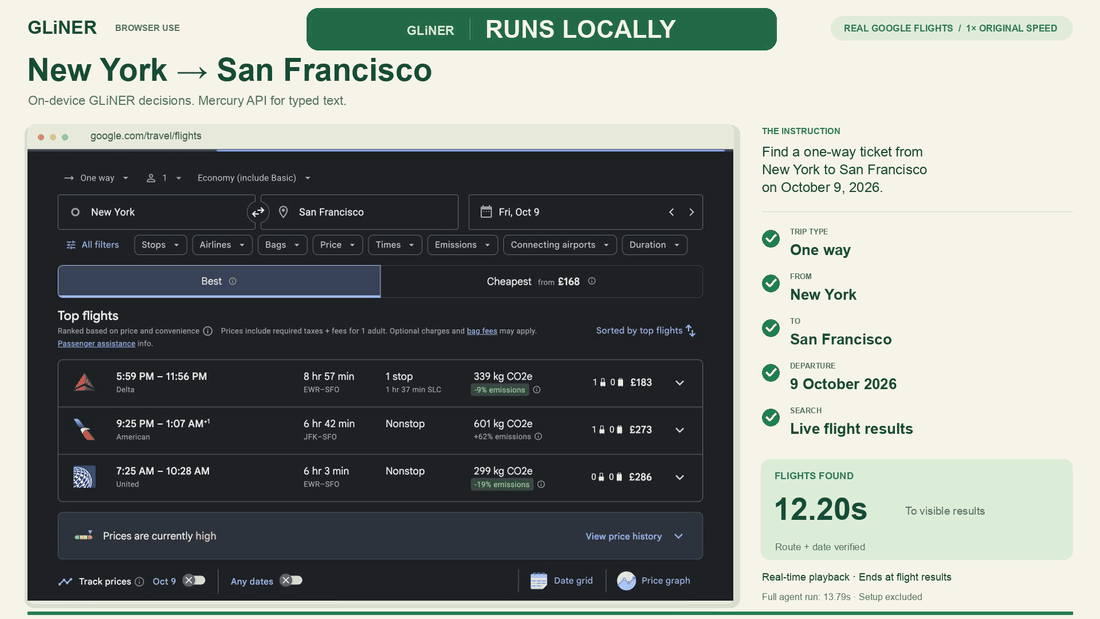
gliner2-ultrafast
Real browser automation with local GLiNER2 inference and open weights. Work in progress. Contributions welcome.
- 81
- Python
- MIT
- 4 wk ago

h3-image-mlx
Faster local MiniMax H3 Image generation and editing on Apple Silicon with MLX, with ultra-low ram
- 80
- Python
- Apache-2.0
- 18 h ago

localharness
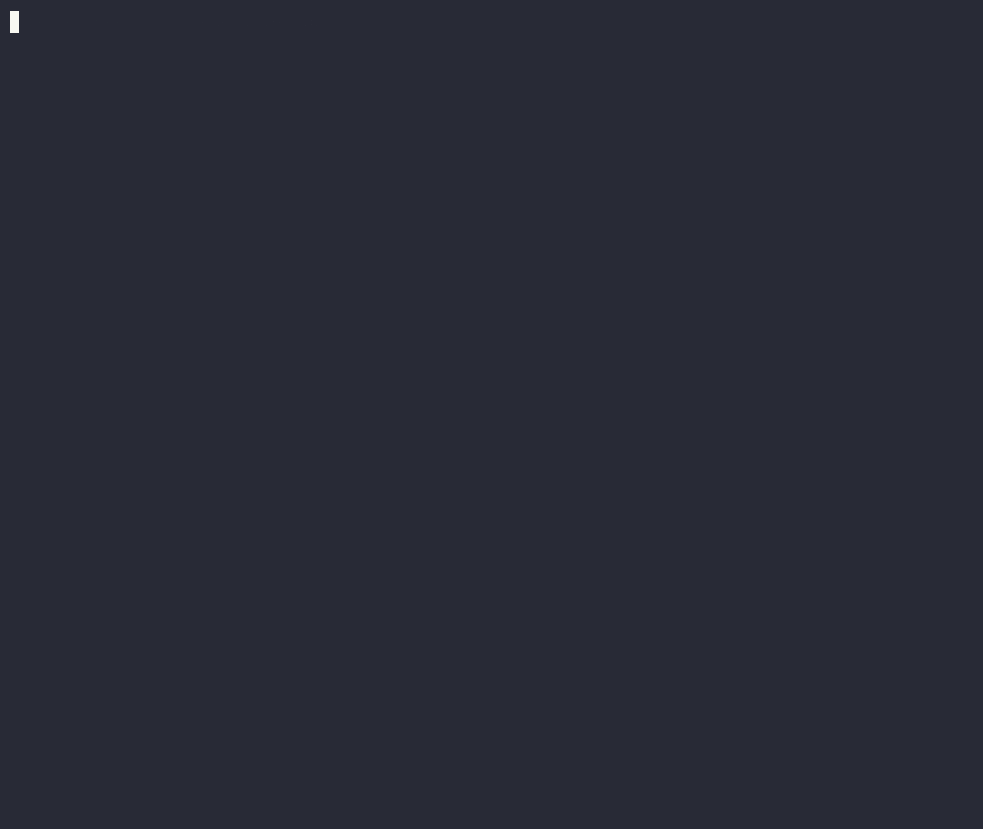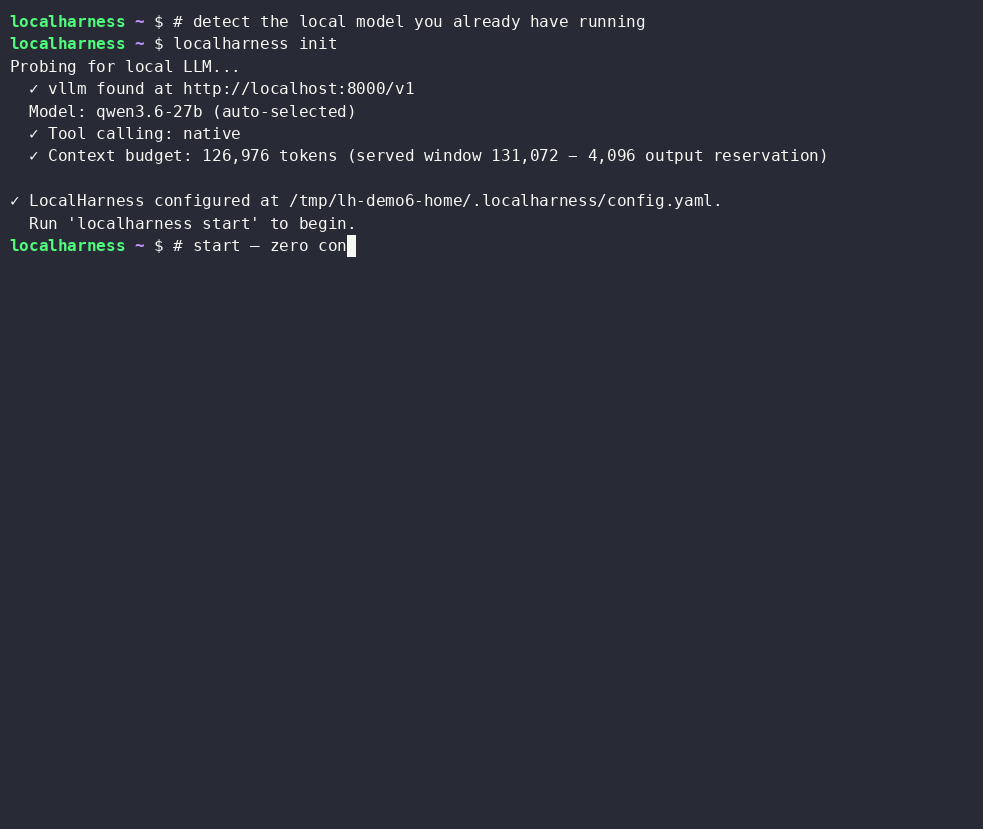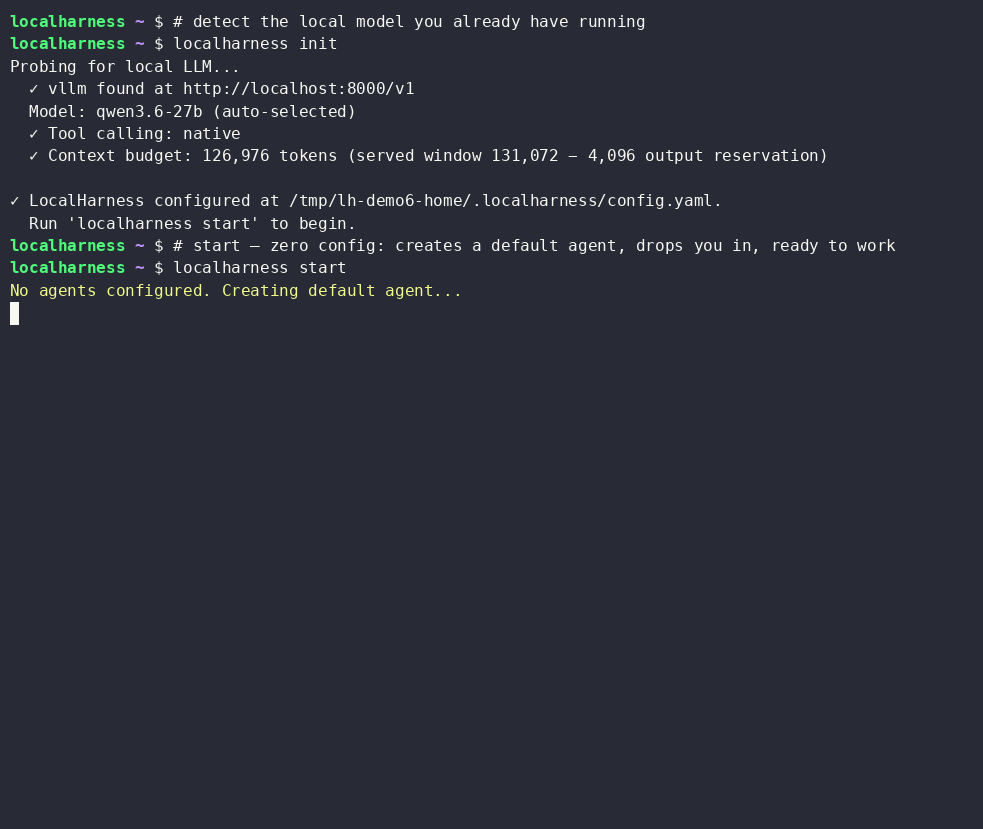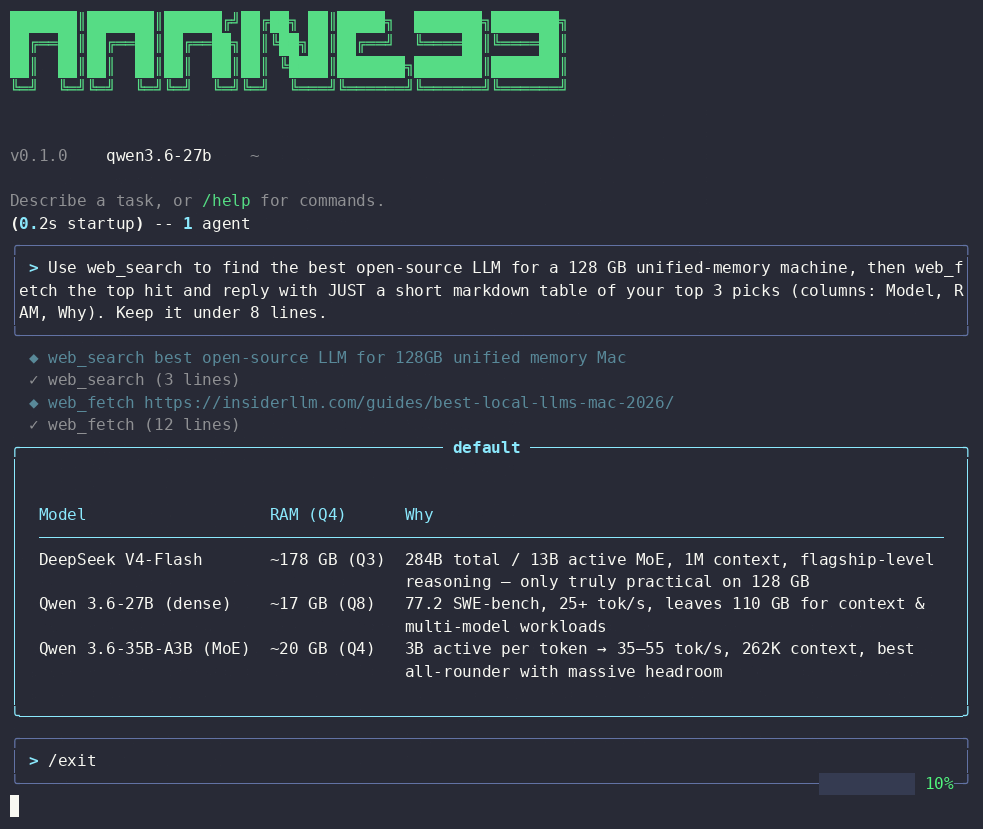
An open-source, coding agent harness designed specifically for local LLMs. Designed as everything a user needs to jumpstart their own harness (detailed event steams, logs, and performance data) or quickly replace closed source one (featuring out of the box plugins for web search, image gen, memory, auto research and more in dev).
- 75
- Python
- MIT
- 1 d ago

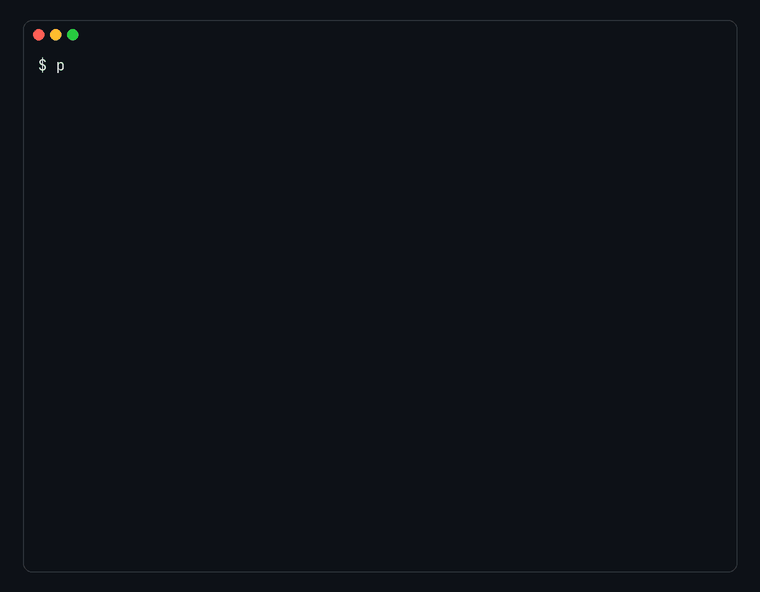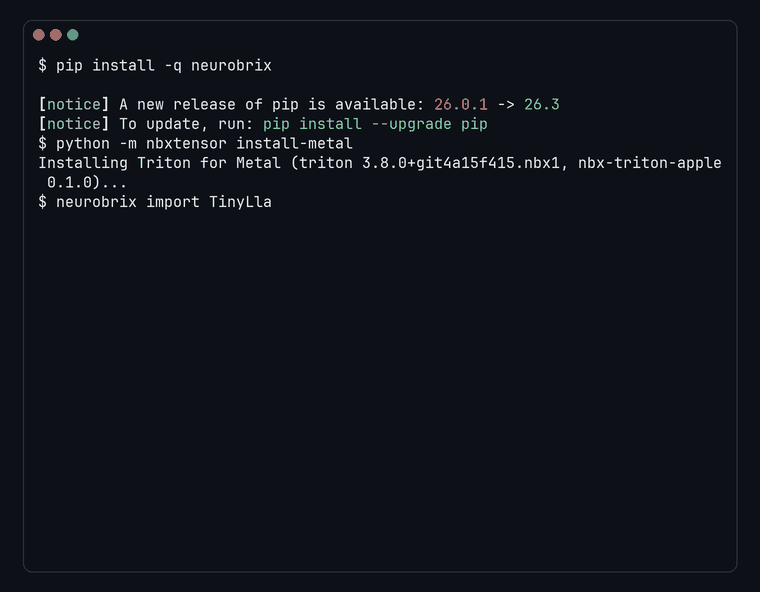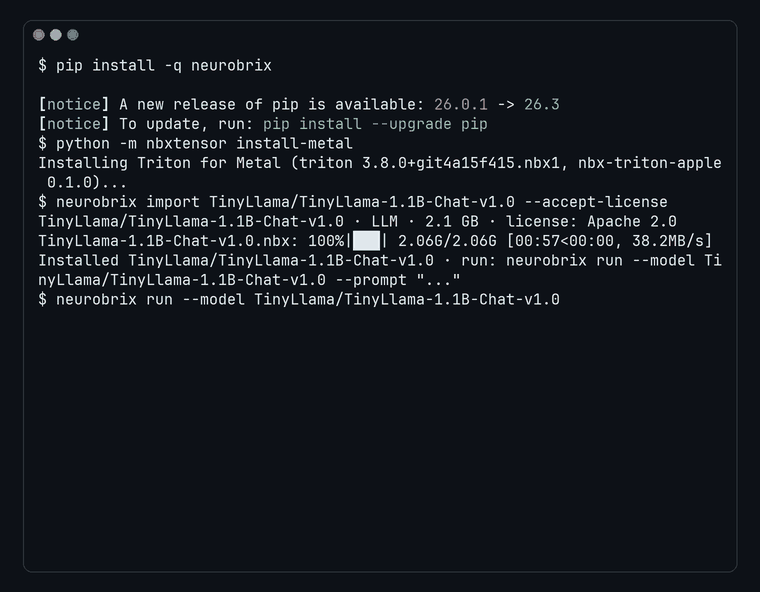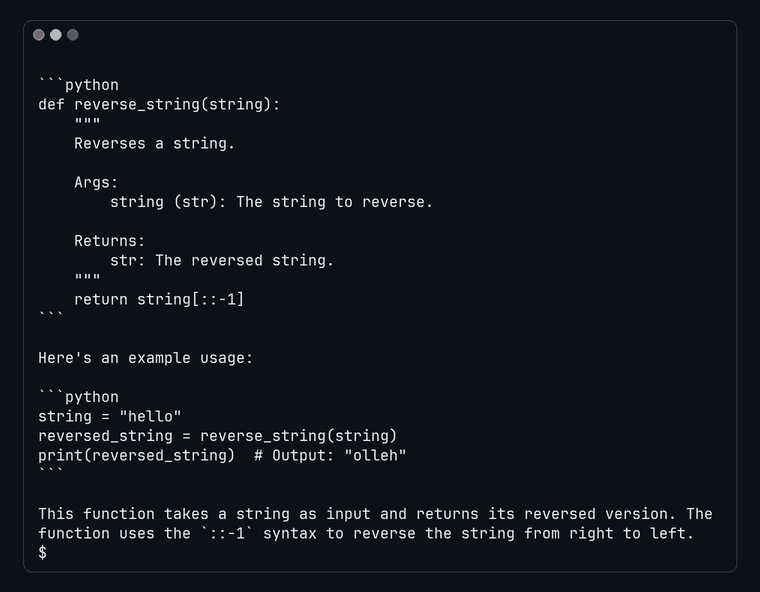
neurobrix
Run real AI models on the GPU you already own: language, speech, image and video models from one engine and one container format, with or without PyTorch. NVIDIA GPUs, Mac GPUs through Metal, CPU; other GPUs experimental. Apache 2.0.
- 65
- Python
- Apache-2.0
- 21 h ago


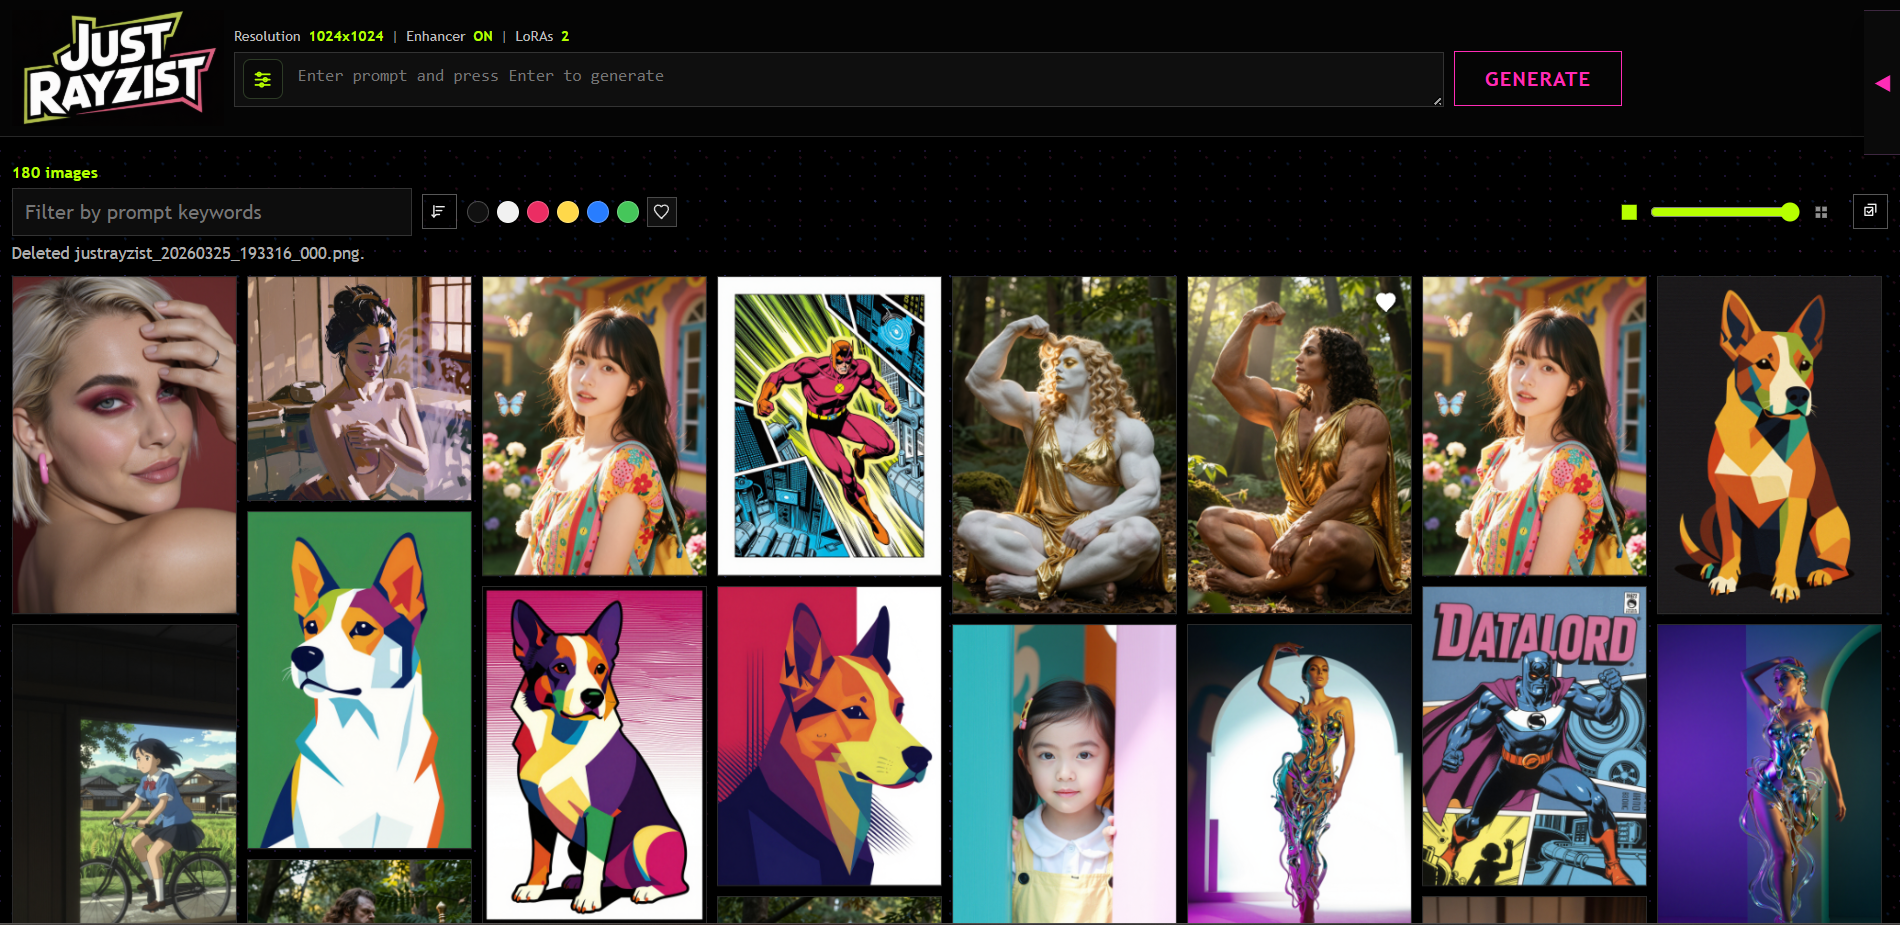
JustRayzist
A lightweight CUDA-based local inference platform built around Z-Image Turbo by Tongyi
- 27
- Python
- Apache-2.0
- 4 mo ago

flash-next-8gb
Run a 177B model (Qwen3.8-Flash-Next) on an 8 GB laptop GPU. Measured: 6.6 GiB VRAM, 47.8 GiB RAM, 34-35 tok/s. The n-gram table stays on disk; the experts run on CPU.
- 36
- Python
- MIT
- 3 mo ago

edgejev
离线可用的本地类型化决策:4 核 CPU 单题 15.6ms。Local & offline Jev / System One inference on CPU — ONNX + INT8, no torch at runtime. 支持 laya / kev / PlayJev
- 42
- Python
- 3 wk ago

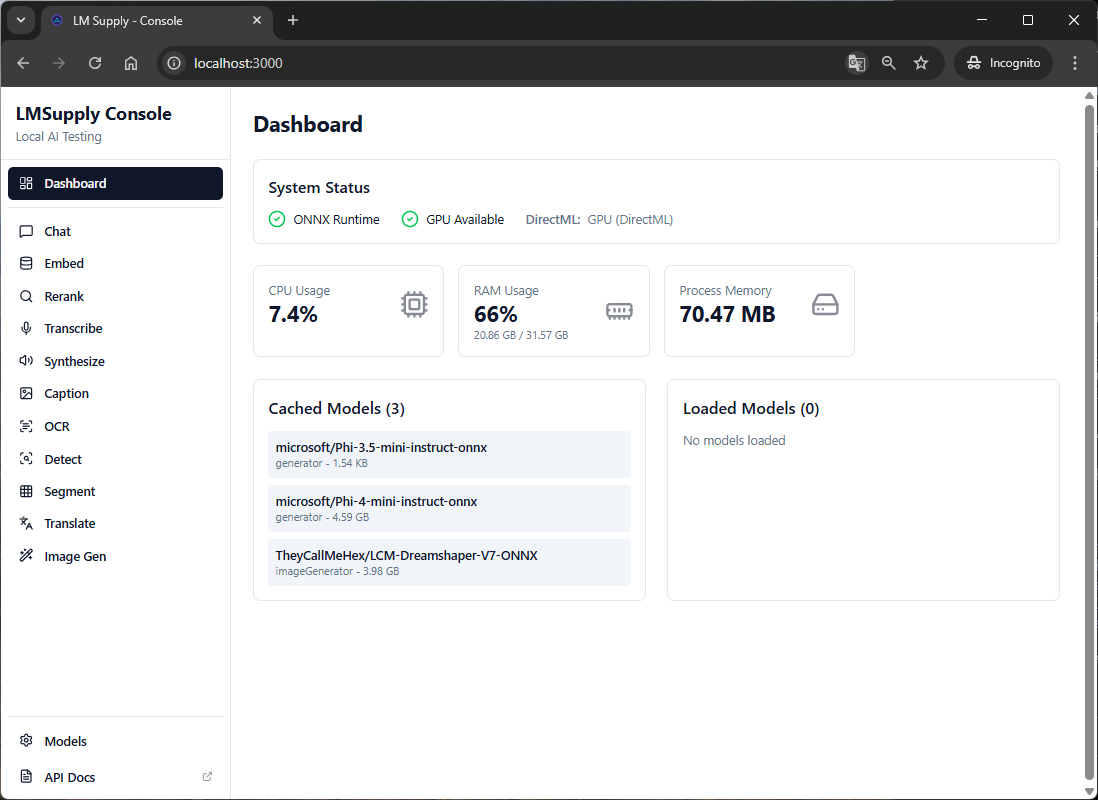
lm-supply
.NET library for on-demand local AI model inference — zero bundled models, lazy loading, hardware-aware GPU/CPU selection, 10 task types including embeddings, generation, vision, and audio.
- 13
- C#
- MIT
- 1 d ago

corriente-qwen38-flash-next
- 7
- 188
- apache-2.0
- 3 mo ago
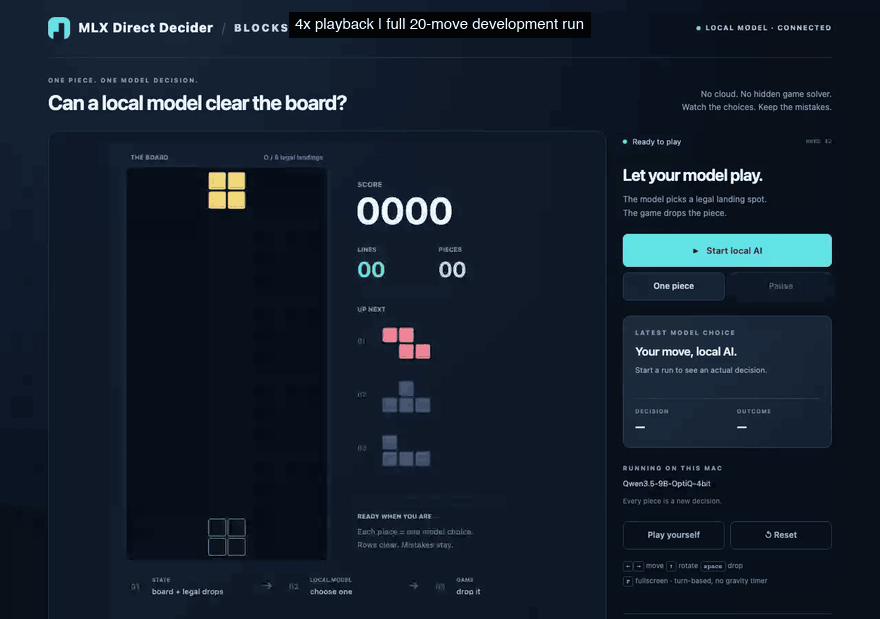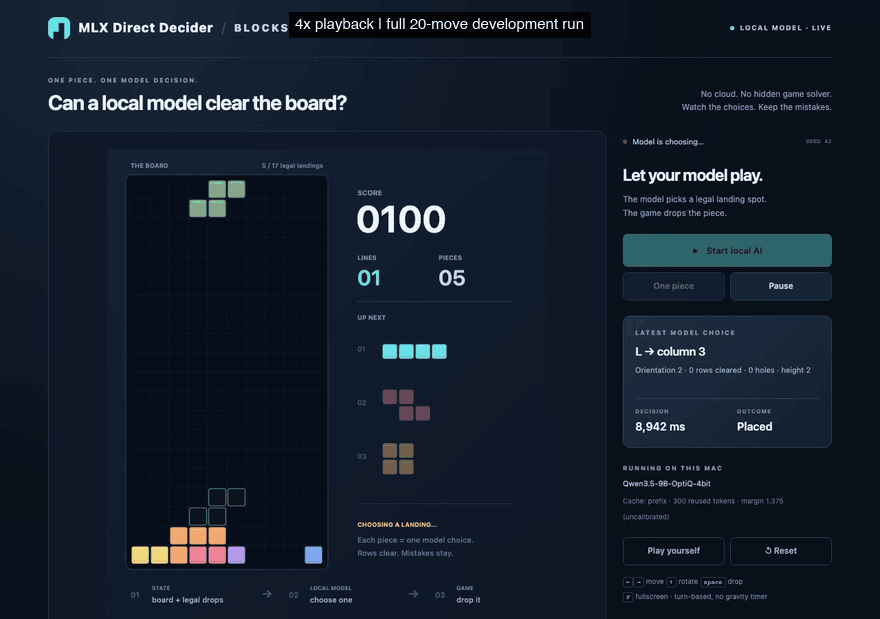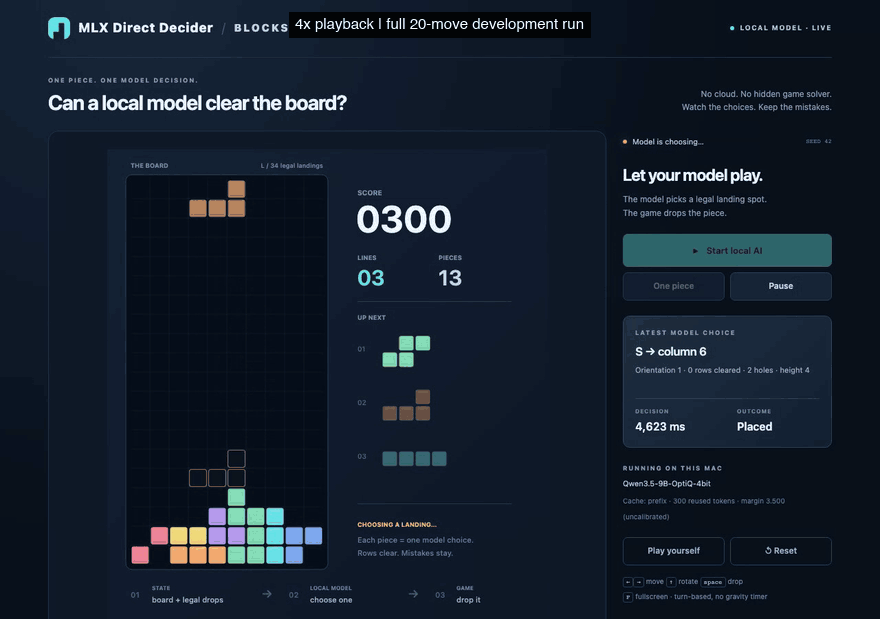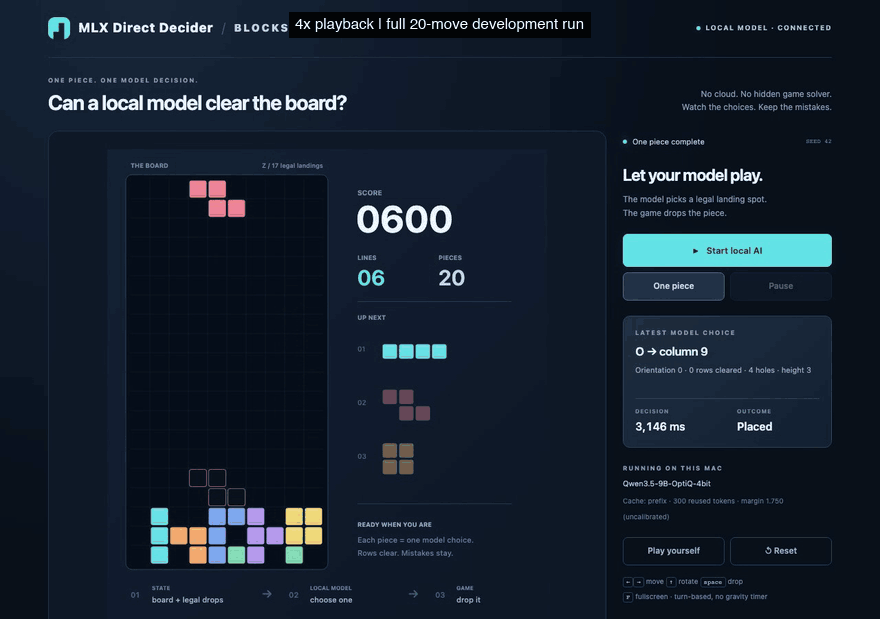
MLX-Direct-Decider
Training-free decision engine for existing MLX models on Apple Silicon. No fine-tuning or extra decision weights. MLX-LM + experimental MLX-VLM action selection and semantic routing. Related: AnyJev.
- 5
- Python
- MIT
- 6 d ago


rave-life-simulation-game
A 90s drug empire simulation powered by local LLM inference. 96 AI dealers, 8 drugs, 9 cities, 5 tiers, cops, cartels, prison, girlfriends, crew — all running on your GPU via llama.cpp.
- 3
- TypeScript
- MIT
- 7 mo ago

buccaneer-life-simulation-game
A full-scale Golden Age of Piracy AI agent simulation powered by local LLM inference via llama.cpp. 100+ autonomous AI agents, 15 agent types, 50+ trade goods, 25 sea zones, and rich narrative proprioception — all running on your GPU.
- 2
- TypeScript
- MIT
- 7 mo ago
quant-lab
Quantization pipelines for local inference: recipes, exact module coverage, and side-by-side evaluation (KLD / top-1 / PPL, decode + TTFT) against both full-precision and vendor checkpoints.
- 0
- Python
- Apache-2.0
- 4 wk ago

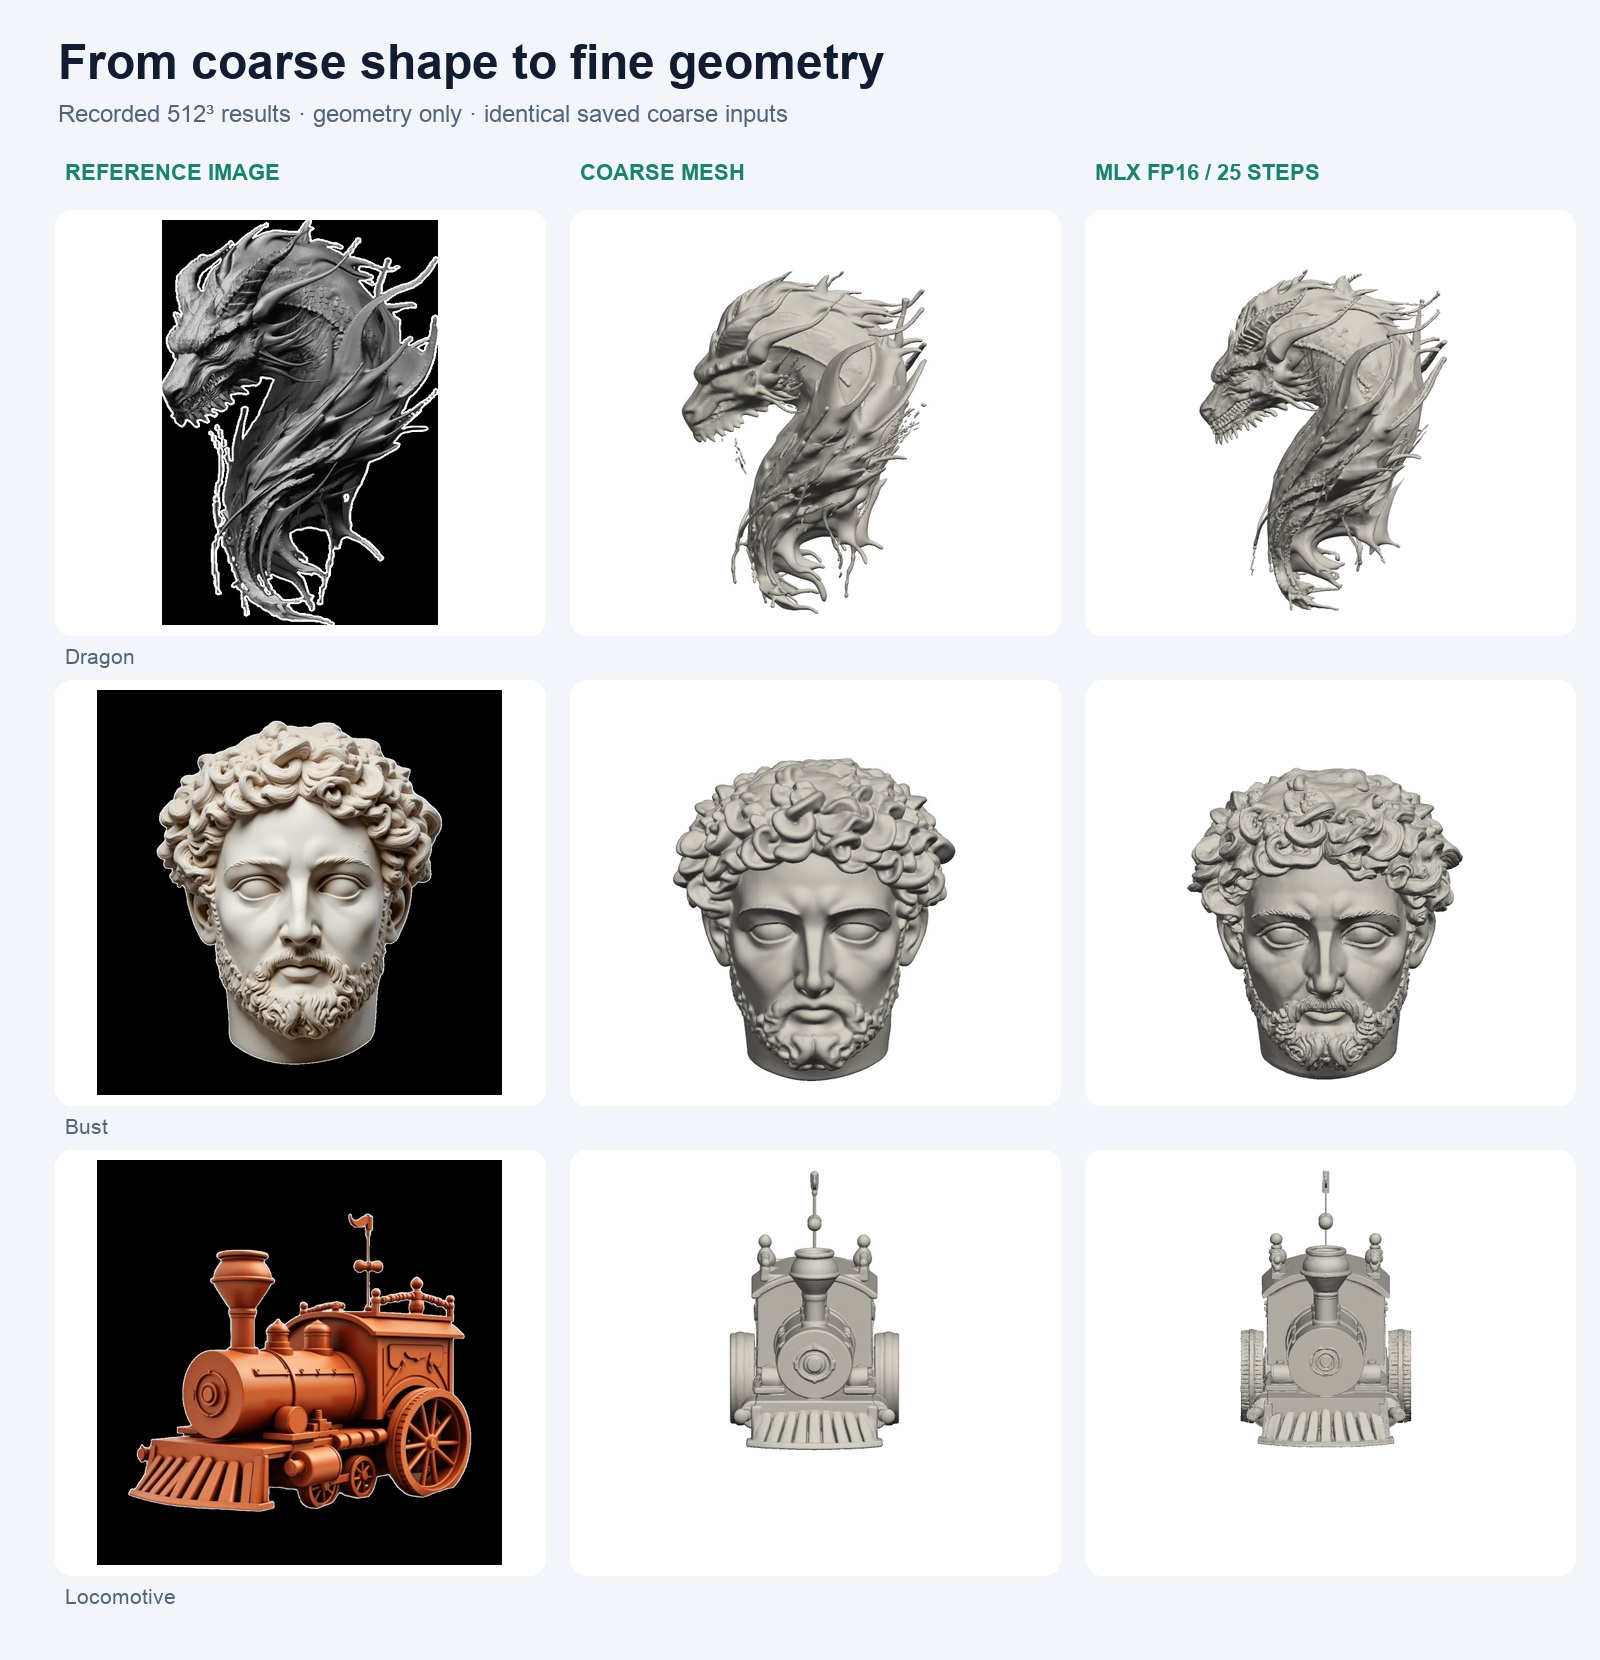
Hi3Dv1.0-mlx
Hi3D v1.0 inference on Apple silicon with MLX. Image + coarse mesh to detailed geometry, selective FP16/INT8/INT4/W8A8 downloads, and reproducible benchmarks.
- 0
- Python
- 4 wk ago

local-ai-workload
Docker-first, local-first AI workload toolkit for macOS Apple Silicon using Ollama, llama.cpp, LiteLLM, and Claude-compatible local endpoints.
- 0
- Shell
- MIT
- 8 mo ago

Which GGUF Quant Fits My Hardware
See which GGUF quant fits your RAM/VRAM.
Runs in the browser on Hugging Face
- 0
- apache-2.0
- 4 mo ago
humanitys-offline-brain
Offline AI + knowledge archive. Local LLM reasoning over humanity's essential texts. No internet required.
- 0
- MIT
- 8 mo ago
