kedro
Kedro is a toolbox for production-ready data science. It uses software engineering best practices to help you create data engineering and data science pipelines that are reproducible, maintainable, and modular.
- 11k
- Python
- 2 d ago
Kedro is a toolbox for production-ready data science. It uses software engineering best practices to help you create data engineering and data science pipelines that are reproducible, maintainable, and modular.
🤖 𝗟𝗲𝗮𝗿𝗻 for 𝗳𝗿𝗲𝗲 how to 𝗯𝘂𝗶𝗹𝗱 an end-to-end 𝗽𝗿𝗼𝗱𝘂𝗰𝘁𝗶𝗼𝗻-𝗿𝗲𝗮𝗱𝘆 𝗟𝗟𝗠 & 𝗥𝗔𝗚 𝘀𝘆𝘀𝘁𝗲𝗺 using 𝗟𝗟𝗠𝗢𝗽𝘀 best practices: ~ 𝘴𝘰𝘶𝘳𝘤𝘦 𝘤𝘰𝘥𝘦 + 12 𝘩𝘢𝘯𝘥𝘴-𝘰𝘯 𝘭𝘦𝘴𝘴𝘰𝘯𝘴
Notes for Machine Learning Engineering for Production (MLOps) Specialization course by DeepLearning.AI & Andrew Ng
Frouros: an open-source Python library for drift detection in machine learning systems.
💻 Decoding ML articles hub: Hands-on articles with code on production-grade ML
A comprehensive solution for monitoring your AI models in production
A robust (🐢) and fast (🐇) MLOps tool for managing data and pipelines in Rust (🦀)
An open-source platform for building, fine-tuning, evaluating, and deploying AI models.
Tutorials on how to engineer Machine Learning projects using Deep Neural Networks with PyTorch and Python
My repo for the Machine Learning Engineering bootcamp 2022 by DataTalks.Club
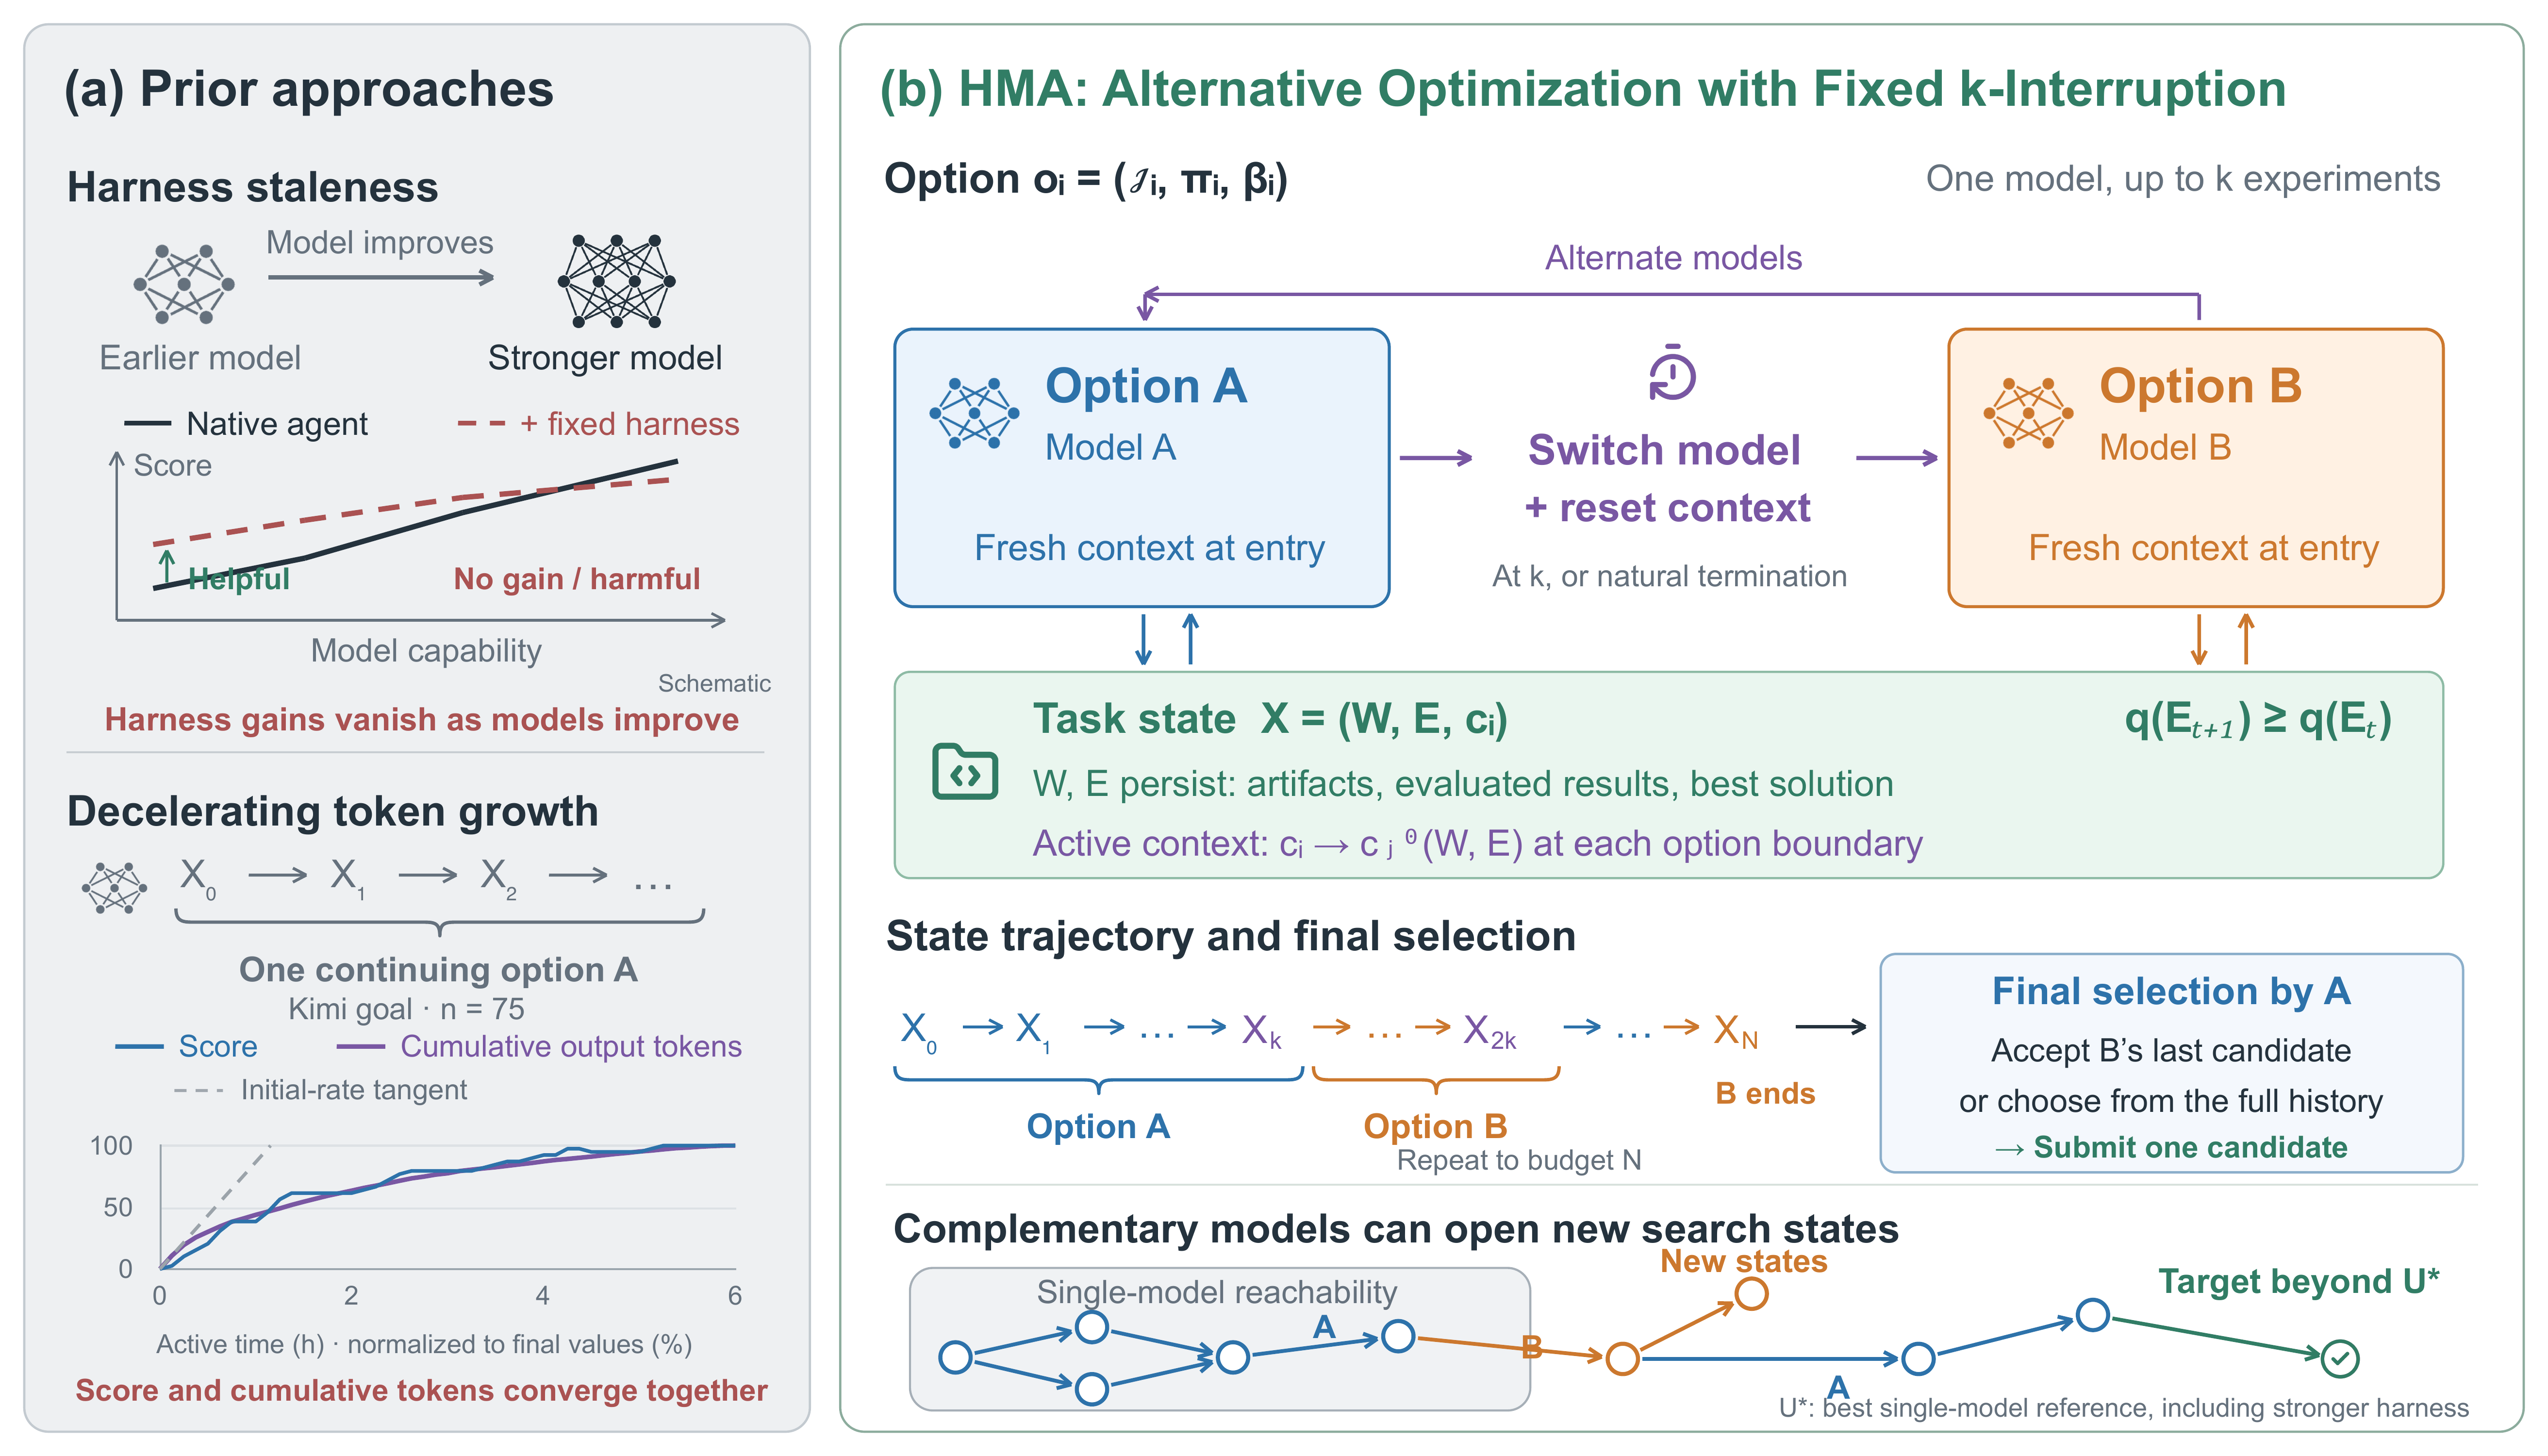
HMA (Humanize MLE Agents): alternating native coding agents over a shared workspace on MLE-bench — paper experiment code
agent-replay is a 100% local, SQLite-powered CLI tool for time-travel debugging AI agents that lets you replay execution traces, diff behavioral changes, fork runs to test fixes, and run AI-powered evaluations or safety guardrails to eliminate hallucinations and production failures.
A Helm chart containing Kubeflow Pipelines as a standalone service.
Practical Machine Learning repository focused on training, validating, and evaluating Classical ML models using Python and Scikit-learn. Covers regression, classification, model selection, cross-validation, hyperparameter tuning, performance metrics, and model optimization through hands-on implementations.
Data Version Control (DVC) learning repository for Machine Learning Engineering, covering dataset versioning, experiment tracking, pipeline management, reproducible ML workflows, remote storage integration, and collaborative model development.
Self-study course on designing production ML systems: 18 modules from data quality and feature pipelines to serving, monitoring and drift, plus lead-level interview quizzes and a runnable end-to-end churn project (PyTorch, Optuna, ONNX, FastAPI).