folkbench
AI API 中转站推荐与评测:中转站排行榜、中转站检测、Claude / GPT / Gemini 中转站对比 · AI API relay rankings · Folkbench Switch for Claude Code, Codex & Gemini CLI
- 4k
- TypeScript
- 21 h ago
AI API 中转站推荐与评测:中转站排行榜、中转站检测、Claude / GPT / Gemini 中转站对比 · AI API relay rankings · Folkbench Switch for Claude Code, Codex & Gemini CLI
Open-source, end-to-end platform for evaluating, observing, and improving LLM and AI agent applications. Tracing · Evals · Simulations · Datasets · Gateway · Guardrails. Self-hostable. Apache 2.0.
Awesome Jev: a source-backed field guide to TypeSafe's System One model, with SDKs, live demos, agent tools, and independent evaluations.
Machine Learning notebooks for refreshing concepts.
魔搭紫皮书|ModelScope Cookbook:面向开发者的开源模型应用实战指南,覆盖模型选型、推理、微调、评测、RAG、Agent 与 AIGC,从跑通第一个模型到构建实际应用。
GLM 5.3 abliterated or uncensored API access with RouterHub. Browse 35 jailbreak prompt links, compare GLM models, and find SDK examples, coding-tool setup, pricing, and evaluation guides.
Neural networks and weight-space programming in Rust, JavaScript and WebAssembly. Inspect activations, edit weights, evaluate candidates, train small models, and explicitly promote or roll back revisions.
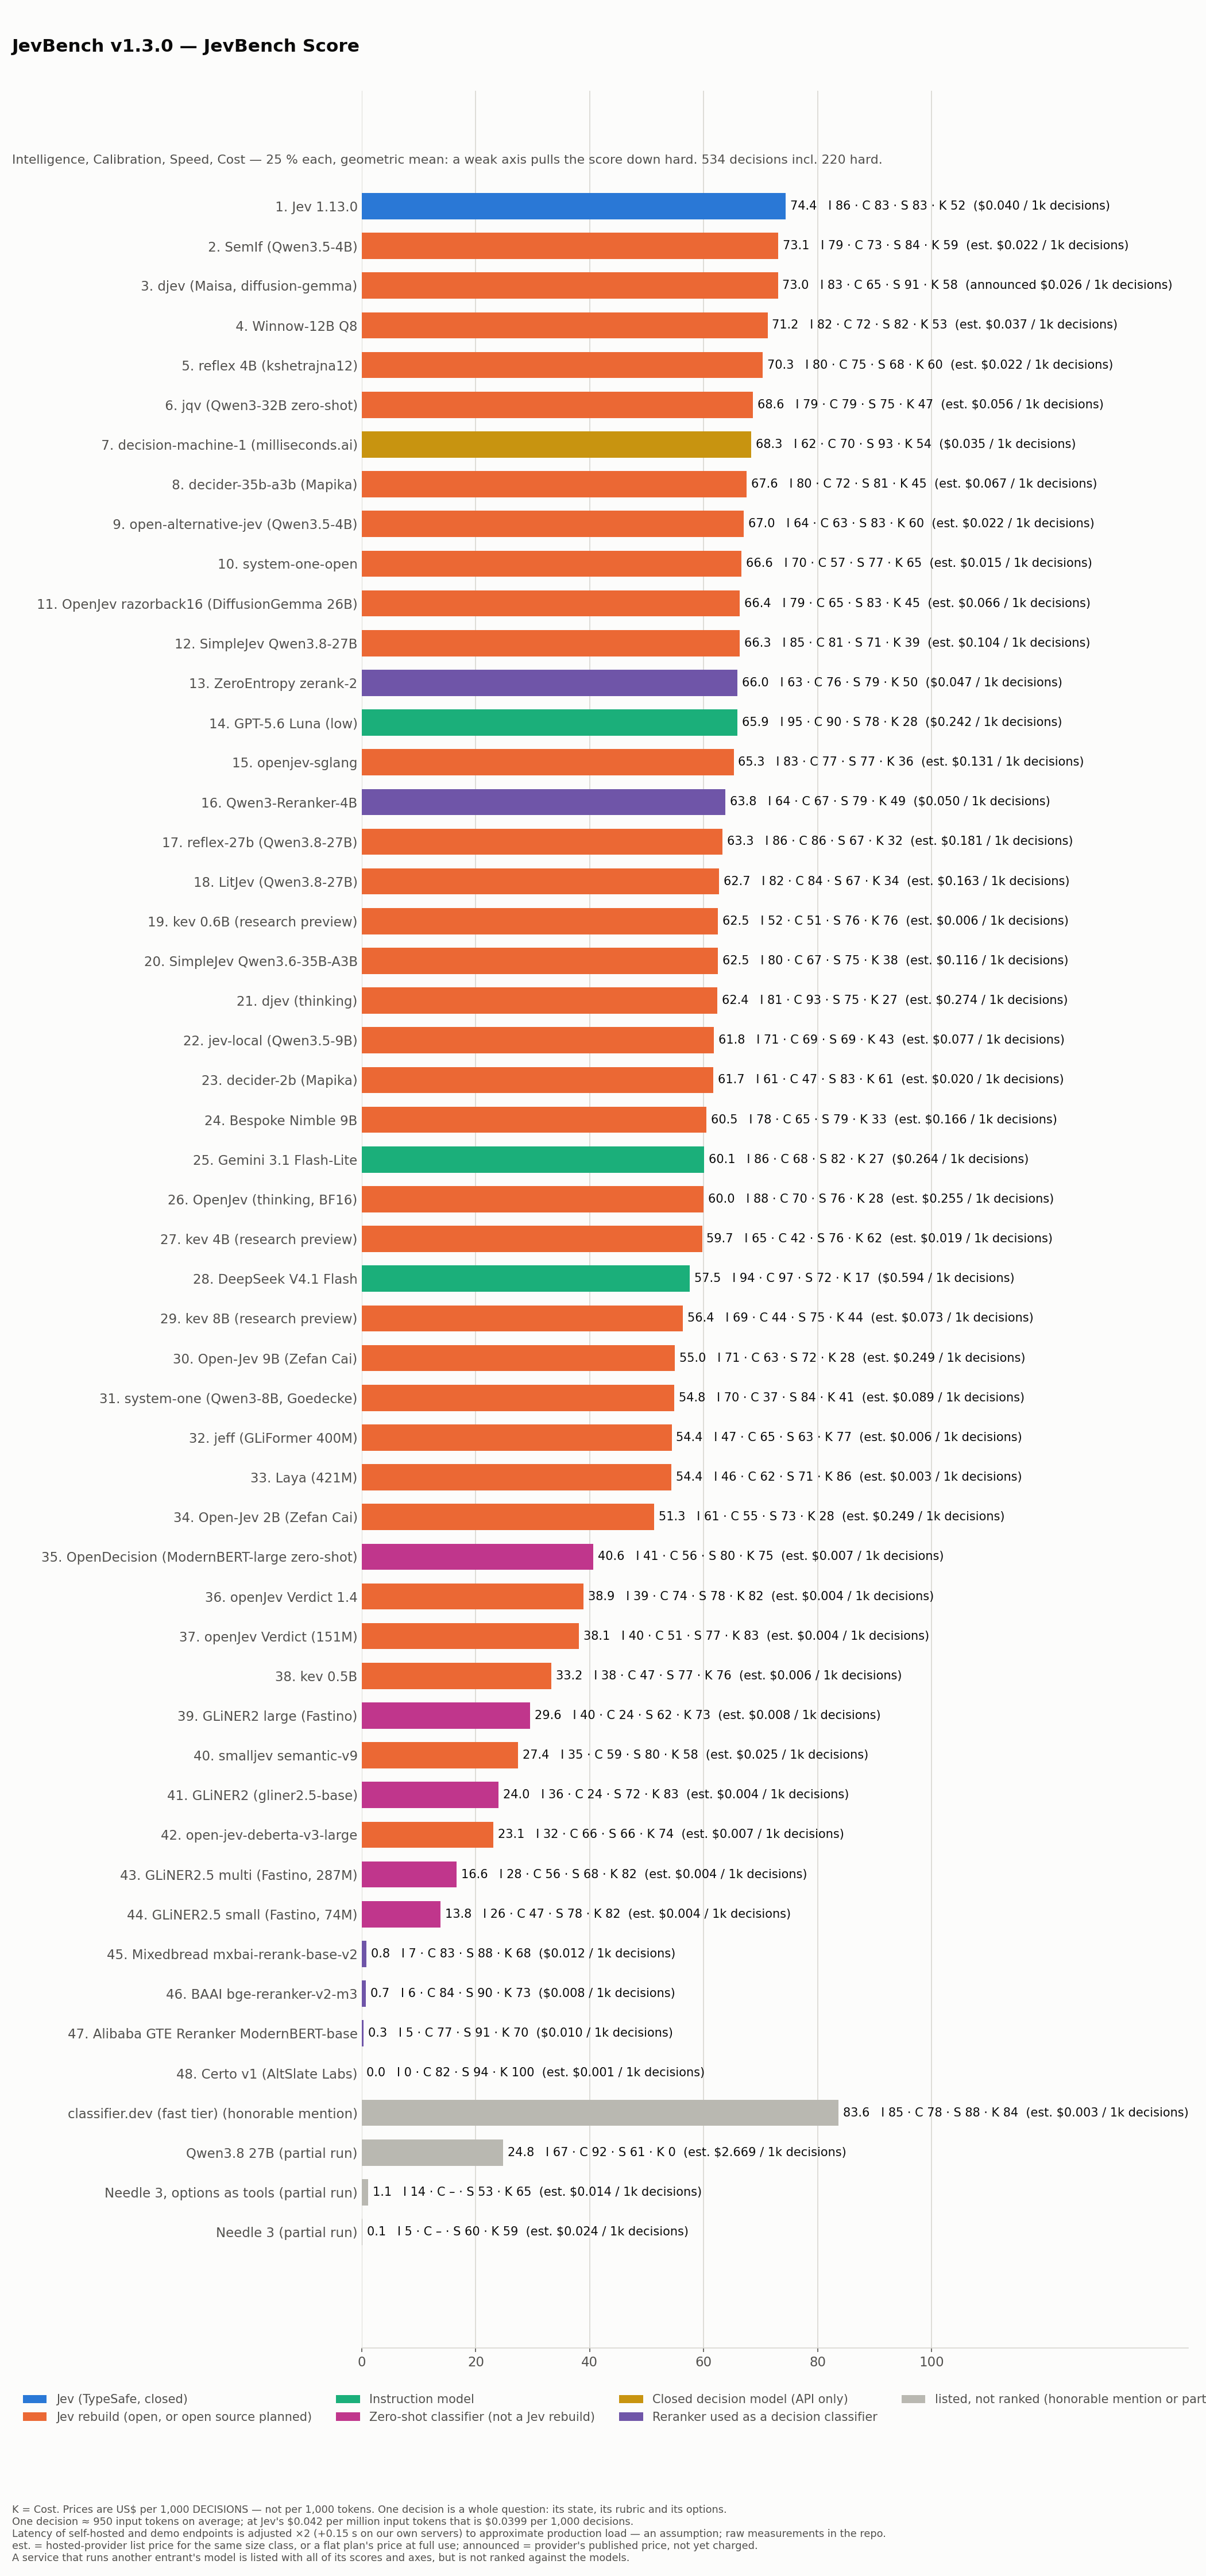
JevBench by Benchmark Heaven: benchmark and leaderboard for AI decision models, measuring typed decision accuracy, calibration, latency and cost.
🔍 Minimal examples of machine learning tests for implementation, behaviour, and performance.
A reproducible local LLM benchmarking platform with versioned datasets, deterministic scoring, and auditable reports.
Community registry of LLM serving-path traps that produce confidently wrong measurements: templates, tool parsers, reasoning fields, quant kernel paths, CUDA toolchains, KV allocation, eval harnesses, versioning. Symptom-first, with the check that catches each.
An in-depth analysis of audio classification on the RAVDESS dataset. Feature engineering, hyperparameter optimization, model evaluation, and cross-validation with a variety of ML techniques and MLP
AI-powered NBA game outcome predictor that uses advanced team stats and trend-based features to forecast winners and track model performance
This project analyzes and visualizes the Used Car Prices from the Automobile dataset in order to predict the most probable car price
An Interactive Approach to Understanding Deep Learning with Keras
GLM 5.3 Uncensored — 35 jailbreak prompt files, model guide and API access. One RouterHub key also covers GPT, Claude, DeepSeek, Qwen and Grok.
🟣 Model Evaluation interview questions and answers to help you prepare for your next machine learning and data science interview in 2026.
NVIDIA AlpaJudge is a human-calibrated evaluation and reward model for autonomous driving that scores causal driving explanations.
Sales Conversion Optimization MLOps: Boost revenue with AI-powered insights. Features H2O AutoML, ZenML pipelines, Neptune.ai tracking, data validation, drift analysis, CI/CD, Streamlit app, Docker, and GitHub Actions. Includes e-mail alerts, Discord/Slack integration, and SHAP interpretability. Streamline ML workflow and enhance sales performance.
Evidence-backed use cases, prompts, integrations, evaluations, and safety notes for OpenAI GPT-6 Astra.
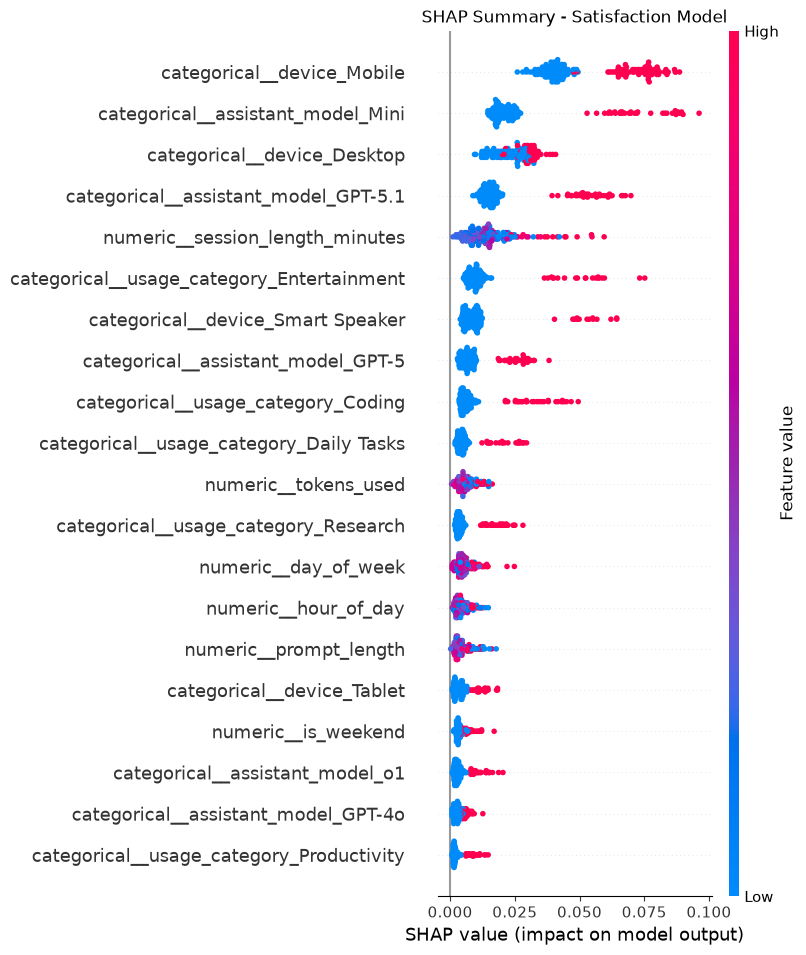
A complete machine-learning system that predicts AI assistant user satisfaction using behavioral signals such as device, usage category, time features, session metrics, and model metadata. Includes full ML pipeline, SHAP explainability, evaluation suite, and an interactive Streamlit analytics dashboard.
Curated Claude Fable 5.1 use cases, API migration notes, prompting patterns, integrations, demos, and benchmark evidence.
Muapi-hosted coding-model benchmark and setup guides for Codex, Claude Code, and OpenCode; compare coding quality and refusal behavior.
Solve complex real-life problems with the simplicity of Keras
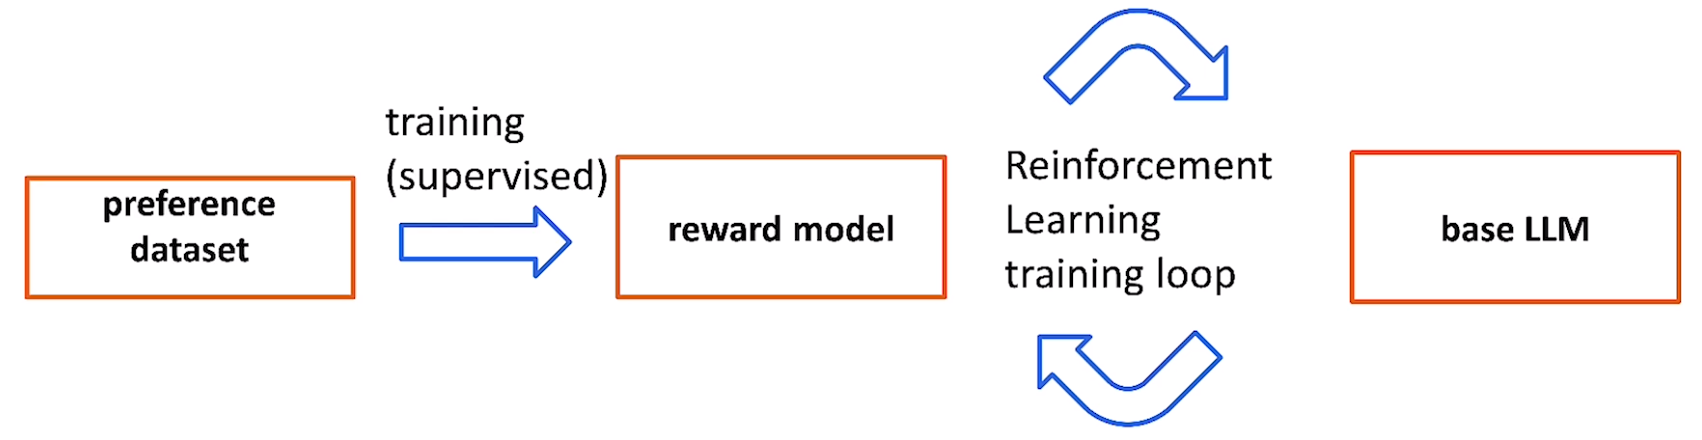
Embark on the "Reinforcement Learning from Human Feedback" course and align Large Language Models (LLMs) with human values.
Privacy-first local AI model comparison platform with blind evaluation, per-model hyperparameters, and multi-configuration testing. Compare 2-6 models side-by-side through Ollama with zero cloud dependencies.
When do biological reasoning models use their biological inputs? Strong benchmark performance can create a mirage of reliance on biological foundation model representations, even when those representations contribute little to task performance.
Static JevBench snapshot for AI decision models
Runs in the browser on Hugging Face
Fix the pass bar before the test runs. PRML is an open spec and CLI that hashes and timestamps evaluation criteria (SHA-256, RFC 3161) so anyone can check them later. Python, JS, Go, Rust.
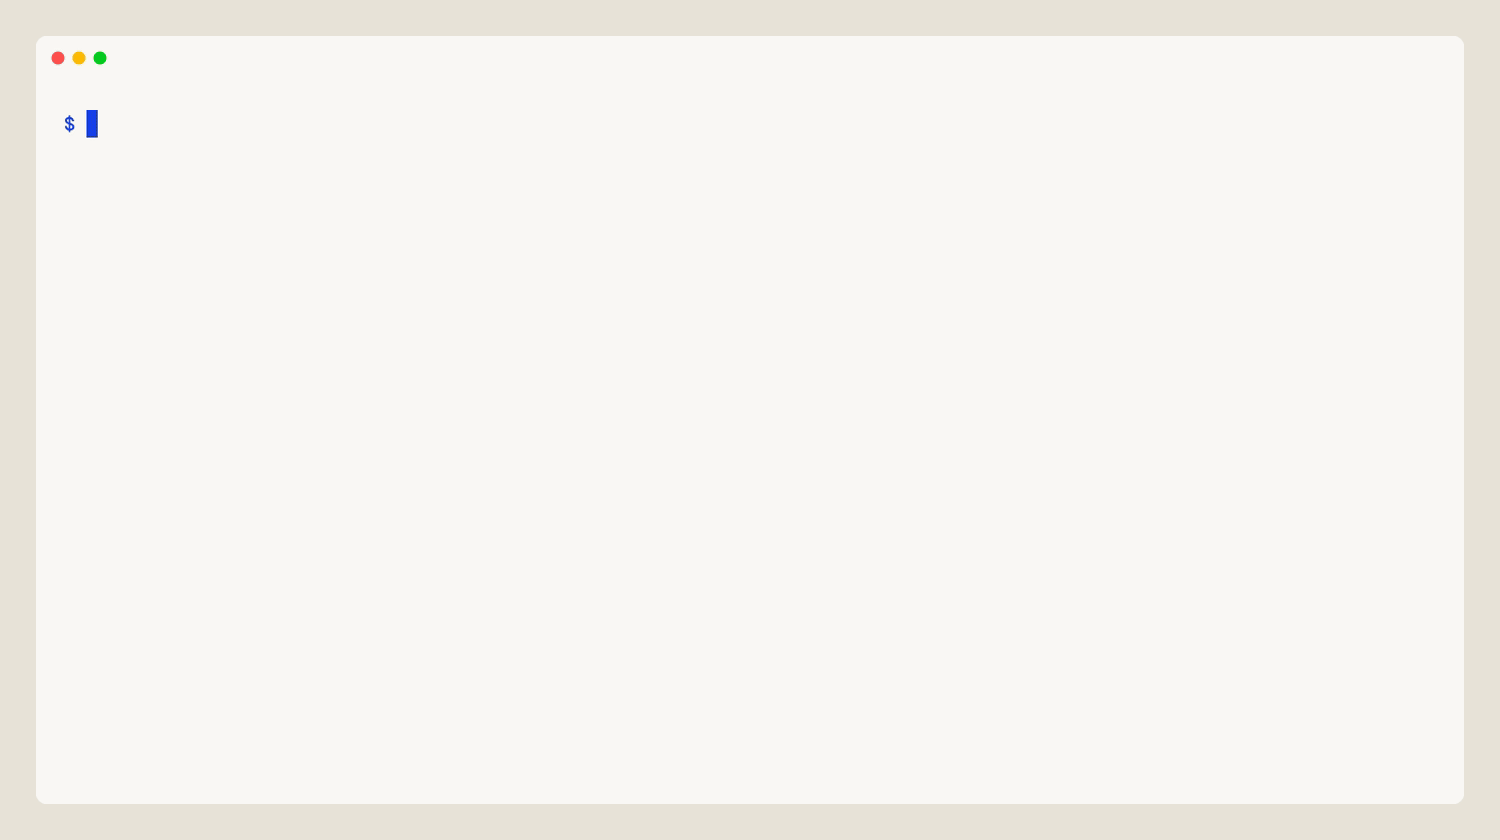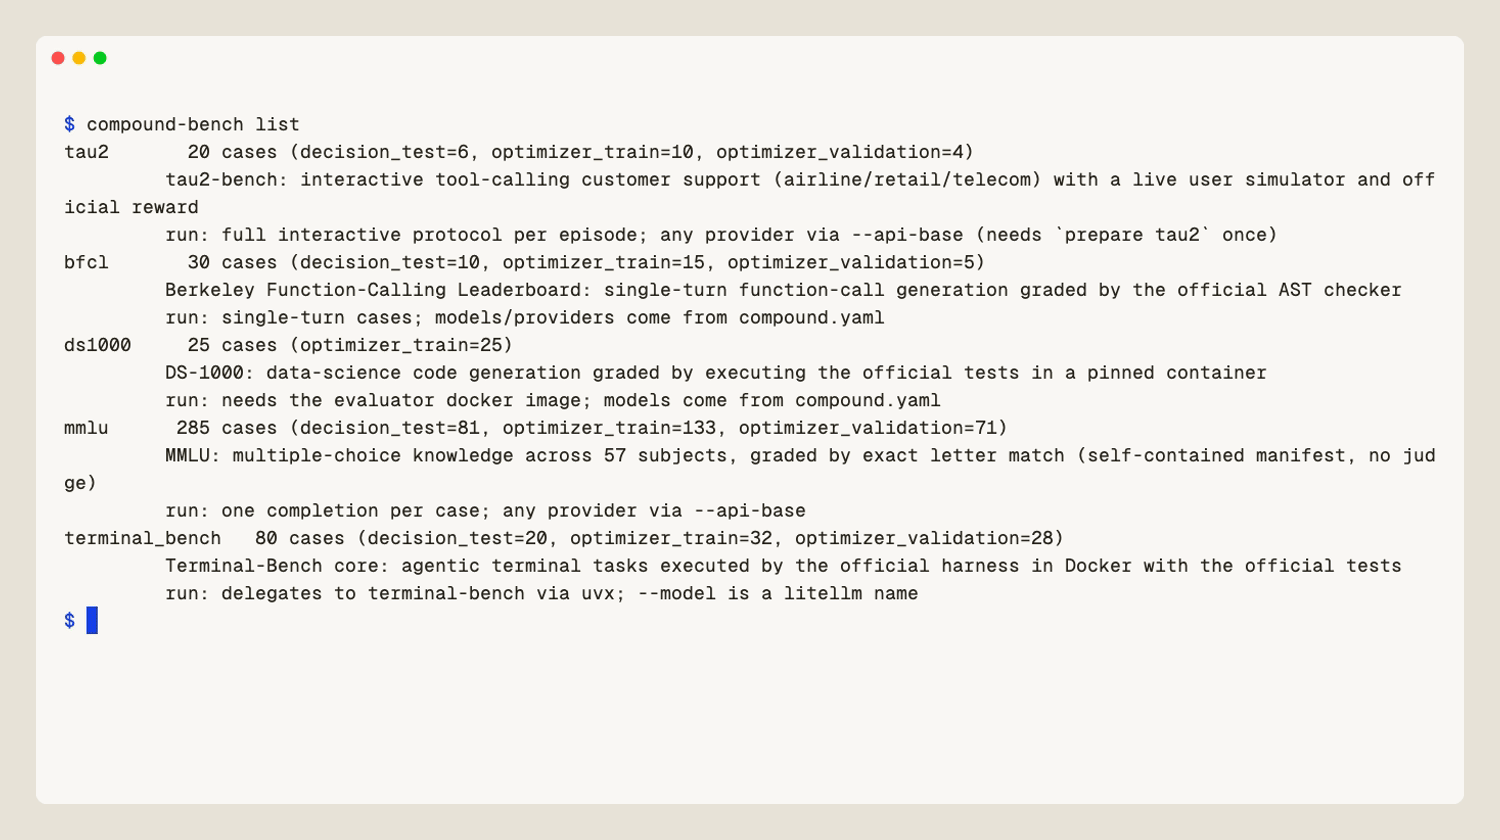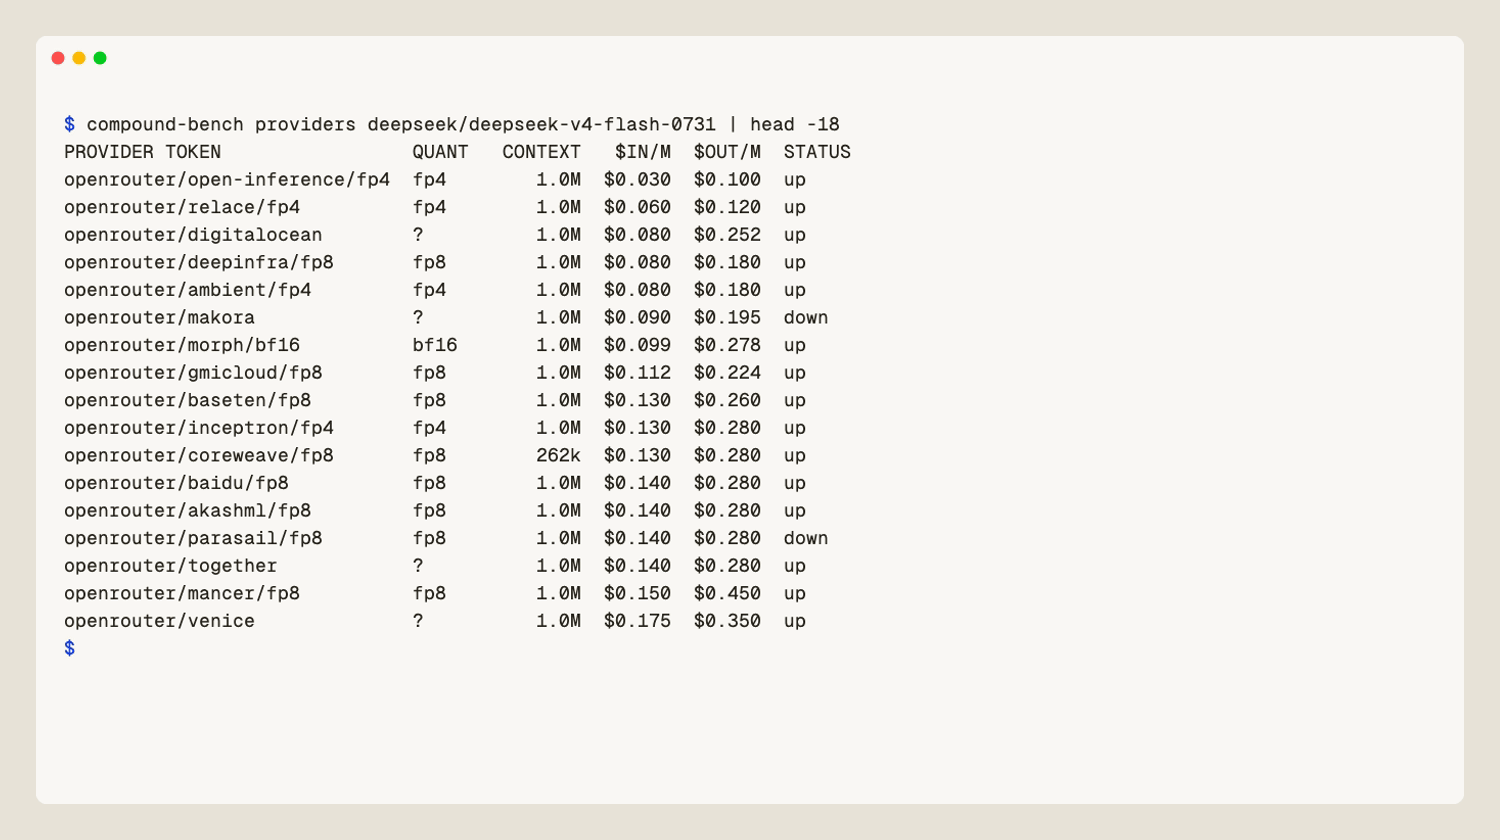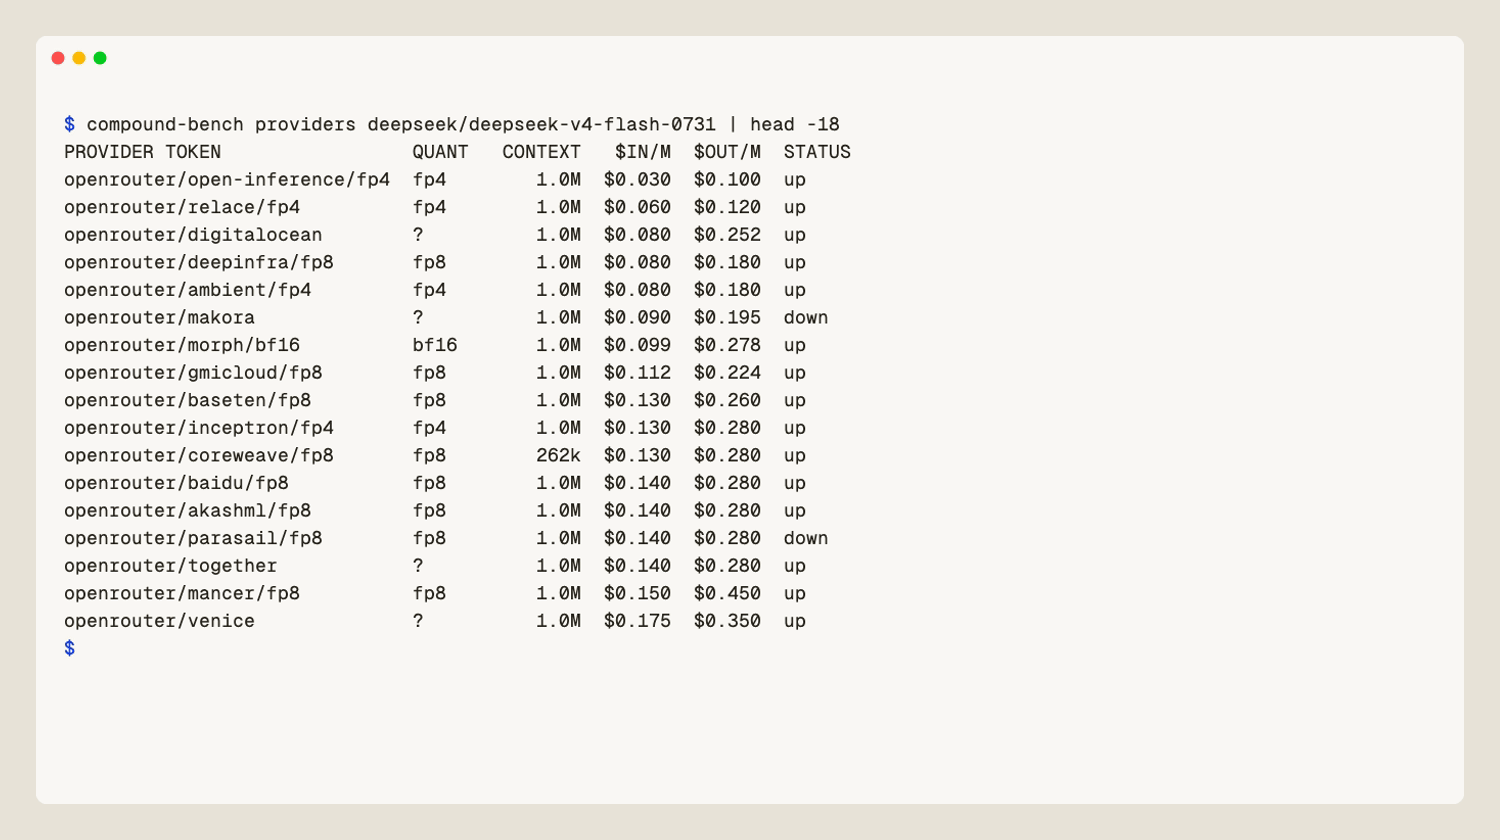
Which host should serve your open model? Run your workload across pinned, verified providers and get one table: success, cost, latency, cache hits.
Open-source red-team harness for LLMs. Jailbreaks, prompt injection, agentic tool-abuse and image attacks, scored with validated judges (Llama Guard 3, StrongREJECT).
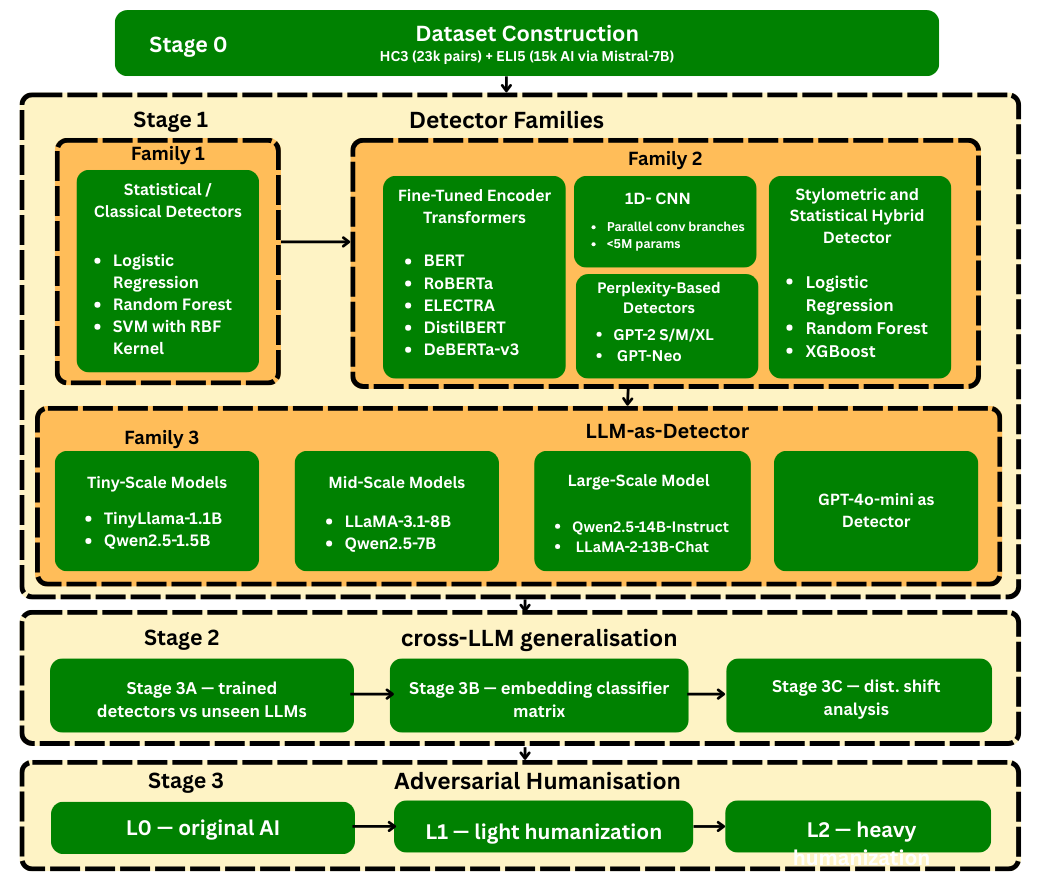
This project aims to address this gap by conducting a systematic, controlled study of human versus LLM-generated text detectability using paired question–answer datasets. Rather than proposing a novel detection architecture, the focus is on analyzing detection robustness, failure modes, and the impact of adversarial humanization strategies.
Kaggle Machine Learning Competition Project : In this project, we will create a classifier to classify fashion clothing into 10 categories learned from Fashion MNIST dataset of Zalando's article images
Curated Jev and System One papers, models, datasets, benchmarks and SDKs, with versioned sources and transparent verification levels. English / 中文.
Live index of LLM evaluation tools and benchmarks, refreshed every 15 minutes from GitHub
NLI benchmark leaderboard: accuracy, calibration, speed
Runs in the browser on Hugging Face